Perplexity SharePoint Integration: Enterprise Internal Search Setup
Connecting Perplexity Enterprise to Microsoft SharePoint enables unified search across internal documents and live web sources with inline citations. While native connectors query SharePoint through Microsoft Graph, large document libraries often hit indexing latency and stale session caches. Deploying an intermediate Fast.io workspace gives teams scheduled cloud sync, hybrid semantic retrieval, and remote MCP tooling for autonomous AI agents.

How the Perplexity SharePoint Integration Connects Enterprise Knowledge
Connecting an AI search platform like Perplexity Enterprise to corporate SharePoint document libraries exposes a fundamental divide between human-oriented file hierarchies and machine-driven semantic retrieval. Enterprise intranet repositories organize files into deep site collections, subsites, and inherited permission trees. Conversational search engines require low-latency passage indexing, continuous sync, and scoped citations.
The Perplexity SharePoint integration enables Perplexity Enterprise to index and search internal corporate documents, policies, and intranet libraries alongside live web search. When an employee asks a technical question about internal infrastructure or compliance policies, the model synthesizes answers from verified internal records rather than relying solely on public web crawls or training data.
Organizations connecting Perplexity Enterprise to Microsoft 365 typically choose between two architectural paths. The first is Perplexity's native Microsoft 365 connector, which interfaces with Microsoft Graph to surface files within the Perplexity web interface. The second is an intermediate workspace architecture using Fast.io, which synchronizes selected SharePoint libraries into an isolated workspace and exposes them to autonomous agents through the Model Context Protocol (MCP).
Understanding how these architectures handle authentication, indexing latency, and document synchronization determines whether an enterprise deployment operates smoothly or stalls during daily use.
Azure Entra ID Authentication and Setup Workflow
Deploying Perplexity Enterprise internal knowledge connectors represents a major shift in enterprise AI search adoption, moving organizations away from static intranet portals toward conversational knowledge discovery. Integrating Perplexity Enterprise with Microsoft SharePoint relies on a structured three-step technical sequence:
- Azure Active Directory Tenant Authentication: An enterprise administrator opens Perplexity Settings, selects My Connectors, and initiates the Microsoft 365 integration. This redirects the administrator to the Microsoft identity platform to authenticate via OAuth 2.0 and grant directory-level consent for Microsoft Graph application scopes.
- Document Library Synchronization: Once identity authentication completes, Perplexity establishes API connections to the organization's SharePoint sites and OneDrive libraries. Administrators or team members configure which document collections and folders participate in enterprise search.
- Indexed Citation Synthesis: When an employee runs a query with the internal files source enabled, Perplexity retrieves relevant text segments, synthesizes an answer, and attaches direct inline citations linking back to the original SharePoint document.
This sequence allows cross-functional teams in finance, legal, human resources, and engineering to query contracts, standard operating procedures, and product specifications without downloading files manually.
Standard Search vs. High-Precision Search Modes
Perplexity Enterprise provides two distinct operational modes for querying connected SharePoint files:
- Standard Search (API-Based): Queries Microsoft Graph endpoints directly at search time. In this mode, Perplexity does not persist file copies within its own storage layer. Each query triggers real-time Microsoft Graph calls to retrieve matching file excerpts, strictly adhering to live SharePoint user permissions.
- High-Precision Search (Indexing-Based): Involves synchronizing selected files or folders into dedicated enterprise storage for deeper semantic indexing and vector search. Perplexity parses document contents, extracts text chunks, and computes embeddings to support natural language queries across complex technical documents.
Standard Search minimizes data duplication by querying SharePoint on demand, but query speed depends on Microsoft Graph responsiveness. High-Precision Search speeds up retrieval by operating against pre-indexed text, though it introduces a requirement to manage synchronization intervals and storage boundaries.
Related guides
- ChatGPT SharePoint Connector: Enterprise Setup vs. Fast.io MCP WorkspacesConnecting ChatGPT to SharePoint document libraries gives conversational models access to enterprise knowledge. While...
- How to Connect Google Gemini to SharePoint for Enterprise Document SearchDeploying a Gemini SharePoint connector allows enterprise teams to query, retrieve, and summarize files stored across...
- LangChain SharePoint Integration: How to Query Enterprise DocumentsA LangChain SharePoint integration connects autonomous agents and retrieval chains to Microsoft SharePoint libraries,...
- Connecting AutoGen Multi-Agent Systems to SharePoint: Architecture and SetupAn AutoGen SharePoint connector enables Microsoft AutoGen agent teams to authenticate against Microsoft Graph and query...
- Azure AI Search SharePoint: How to Index SharePoint Files for Agentic RetrievalIndexing Microsoft SharePoint document libraries with Azure AI Search requires configuring Entra ID service principals,...
- Amazon Bedrock SharePoint Connector: Setup, Limitations, and AlternativesThe Amazon Bedrock SharePoint connector allows Amazon Bedrock Knowledge Bases to ingest and index documents stored in...
More on this subject: Agent File and Document Workflows (298 guides)
Why Native SharePoint Connectors Hit Latency and Synchronization Bottlenecks
While native connectors provide a straightforward setup flow inside the Perplexity web application, enterprise teams managing large intranet libraries encounter several technical constraints. Intranet file repositories are designed for asynchronous human document management, not the real-time request-response patterns required by large language models.
When an AI engine attempts to traverse an enterprise SharePoint tenant, it encounters three primary obstacles: document library scale, file synchronization latency, and API rate limits. Enterprise SharePoint collections often store hundreds of thousands of files across deeply nested subfolders. Querying these collections on demand requires significant compute and bandwidth, which can quickly saturate service quotas. Addressing these constraints requires evaluating how files move from SharePoint into the indexing pipeline and where bottlenecks arise during active inference.

Document Library Scale and Indexing Latency
Enterprise SharePoint deployments often house millions of files accumulated over years of project work. These include scanned PDF contracts, complex multi-tab financial spreadsheets, PowerPoint decks, and technical design documents.
For organizations operating large intranet portals, Microsoft recommends syncing no more than 300,000 files in a single OneDrive or team site library to maintain performance. When document counts exceed this threshold or folder hierarchies extend dozens of levels deep, file enumeration slows down noticeably.
Indexing latency across massive SharePoint document libraries creates operational friction. Initial file discovery and document parsing across multi-gigabyte collections can require several hours to complete. If an engineering or compliance team regularly adds hundreds of technical documents, background indexing queues fall behind, leaving users searching against outdated indexes.
Session Staleness and File Synchronization Gaps
A critical constraint of native file connectors is how updates propagate to existing conversational sessions. When an employee edits a file in SharePoint, the changes do not immediately update previous conversational threads.
According to Perplexity documentation on enterprise file connectors, if a user updates an original file in cloud storage, the version attached to a previous session will not automatically update. The user must re-attach or re-upload the file to ensure the AI accesses the latest information.
In fast-moving operational settings, this gap leads to subtle errors. If an engineering team revises an architectural specification or HR updates a health insurance policy in SharePoint, employees querying older conversational threads receive answers derived from obsolete file versions. Automated agent pipelines require active synchronization mechanisms to guarantee that language models read the current state of truth.
Microsoft Graph Throttling and HTTP 429 Failures
Native connectors query SharePoint through Microsoft Graph REST endpoints. To protect service availability across shared cloud infrastructure, Microsoft enforces strict request throttling per tenant and application.
When an automated system sends rapid batches of queries across extensive directory trees, Microsoft Graph returns HTTP status code 429 when client requests exceed service throttling thresholds.
When an HTTP 429 error occurs, the failed response includes a Retry-After header specifying the wait period before additional requests are accepted. For interactive users typing questions in a browser, throttling manifests as stalled answers or search timeouts. For autonomous agents executing batch research across multiple document libraries, throttling halts execution entirely until the backoff window passes.
The Intermediate Workspace Architecture: Fast.io with Remote MCP
To bypass the limitations of direct Graph queries and manual session re-uploads, engineering teams increasingly implement an intermediate workspace architecture. Rather than pointing conversational models directly at raw SharePoint site collections, organizations synchronize selected SharePoint folders into an isolated Fast.io workspace.
Fast.io provides dedicated workspace storage for agents that links directly to existing cloud storage providers. Through Cloud Sync, documents stored in SharePoint libraries synchronize to an intelligent Fast.io workspace through the OneDrive connector. Sync runs one-way or two-way, on a schedule or on demand, without requiring continuous background polling.
Once files land in the workspace, Fast.io's built-in Intelligence Mode parses documents and generates hybrid search indexes. Autonomous agents, coding assistants, and search workflows interact with the indexed workspace through Fast.io's remote Model Context Protocol (MCP) server over Streamable HTTP at https://mcp.fast.io/mcp/tools (or https://mcp.fast.io/mcp/code for coding agents).
Configuring Cloud Sync for SharePoint Document Libraries
Setting up an intermediate workspace preserves SharePoint as the authoritative human repository while creating a high-speed retrieval layer for AI tooling. The integration follows four discrete steps:
- Create an Isolated Workspace: In Fast.io, establish a dedicated workspace for the target project or department, such as
Engineering-SpecificationsorCorporate-Policies. - Connect SharePoint via Cloud Sync: Authorize Cloud Sync using the OneDrive connector to reach the relevant SharePoint document library. Select the exact folder subtrees required for the project.
- Set Sync Frequency: Choose between on-demand execution or scheduled synchronization intervals. This ensures document updates in SharePoint propagate into the workspace on a predictable timetable without saturating API quotas.
- Enable Workspace Intelligence: Turn on Intelligence Mode to generate full-text and semantic vector embeddings across all synchronized files automatically.
Because Fast.io processes files upon arrival, documents become queryable without manual chunking scripts or external vector database infrastructure.
Hybrid Retrieval vs. Raw File Ingestion
Language model context windows have expanded, but passing entire files into prompts remains inefficient and costly. When an agent attempts to answer questions by downloading full multi-megabyte PDF manuals or large spreadsheets, prompt token usage spikes and response latency climbs.
Fast.io replaces full-file ingestion with hybrid search, combining full-text keyword matching, semantic vector retrieval, and search-by-metadata-value. When an agent queries the workspace, the search engine returns concise, relevant passages accompanied by source metadata and file path citations.
In independent evaluations of agent storage retrieval, the connector comparison is published at fast.io/benchmarks/, where Fastio was measured the fastest and the lowest cost of the providers tested.
For teams needing structured data extraction from synchronized SharePoint documents, Fast.io provides Metadata Views. Metadata Views turn unstructured documents into typed databases without writing custom regular expressions or training bespoke extraction models. Users define fields in natural language, and the platform populates sortable schemas across PDFs, Word documents, and scanned records.
Connecting Autonomous Agents via Remote MCP
A primary drawback of native web connectors is their confinement to browser chat windows. Developers cannot easily hook native connectors into autonomous coding tools, command-line agents, or background automation scripts.
Fast.io solves this by exposing a consolidated MCP toolset over Streamable HTTP at https://mcp.fast.io/mcp/tools for general MCP clients and https://mcp.fast.io/mcp/code for coding agents, with setup instructions in the Fast.io documentation. Interactive clients sign in with OAuth in the browser and carry no API key, while headless runtimes connect to the indexed SharePoint workspace using a standard configuration block:
{
  "mcpServers": {
    "fastio-sharepoint": {
      "url": "https://mcp.fast.io/mcp/tools",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Through this single connection, autonomous agents search indexed documents, retrieve precise text chunks, check per-file version history, and write new synthesis notes directly into the workspace.


Connect Perplexity and Enterprise Agents to SharePoint with Fast.io
Synchronize SharePoint document libraries into isolated Fast.io workspaces, index files automatically, and query enterprise documents via remote MCP. Every organization starts with a 14-day free trial.
Enterprise Data Governance, Security, and Blast Radius
Security and IT compliance teams must evaluate the blast radius of connecting AI platforms to enterprise document repositories. When an enterprise search connector uses tenant-wide administrative consent, an employee prompt might inadvertently surface sensitive internal files from restricted executive sites.
Intranet knowledge repositories contain a wide spectrum of proprietary data, ranging from public sales collateral to confidential payroll records and merger planning documents. Granting conversational models broad tenant-level discovery rights introduces security risks that central governance teams must mitigate. Isolating AI access to specific workspaces enforces the principle of least privilege, preventing accidental data exposure while maintaining complete operational auditability across all automated sessions.
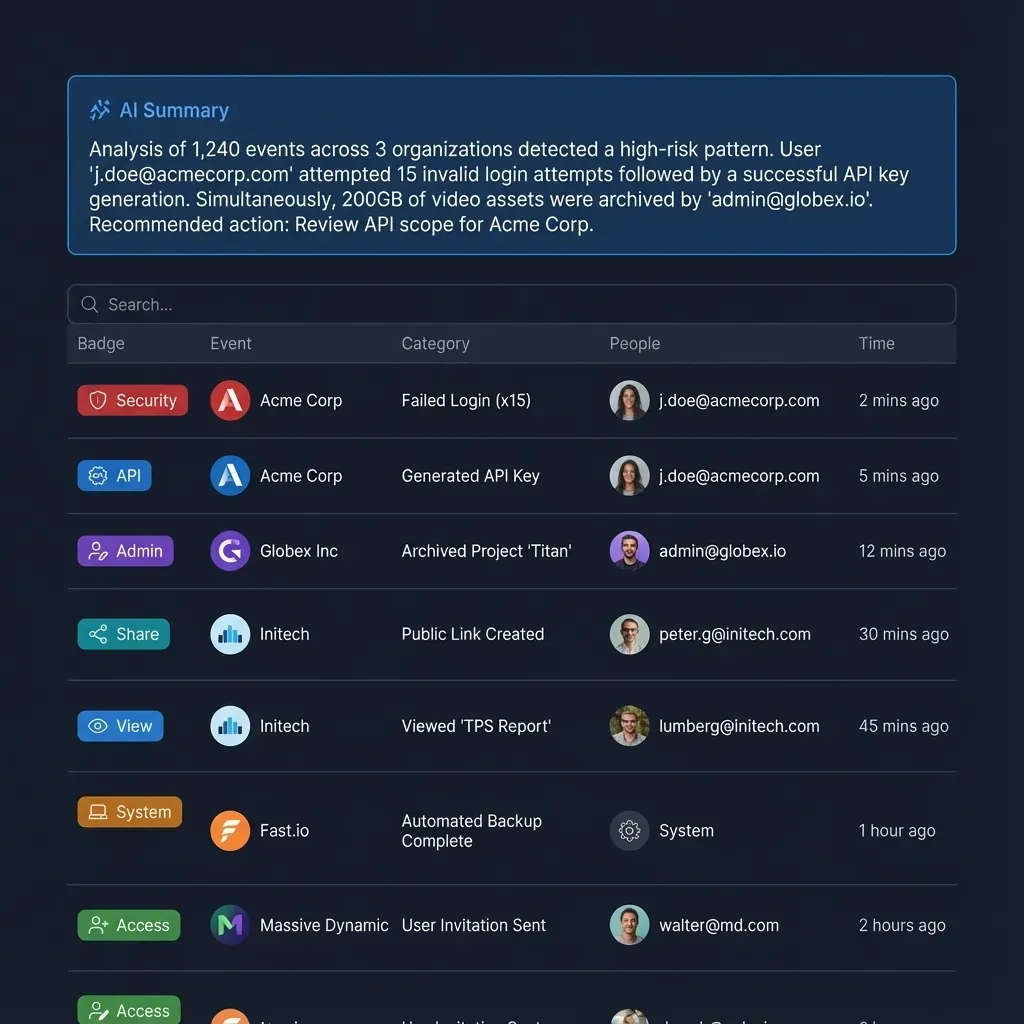
Containing Blast Radius with Scoped Workspaces
In a native connector setup, user queries often search across all SharePoint sites that the user has read permissions for in Microsoft Entra ID. If an employee belongs to broad security groups, a single search can return fragments from confidential budget projections, internal reorganization memos, or legal disclosures.
The intermediate workspace architecture constrains the agent's operating environment. By selectively synchronizing only approved document folders into a dedicated Fast.io workspace, administrators establish a strict perimeter. An AI agent deployed for customer support can query product documentation and release notes without having physical access to financial archives or personnel records.
Granular Access Controls and Audit Logging
Fast.io provides granular access control across organization, workspace, folder, and file levels. Team administrators assign explicit member roles to humans and agents, controlling who can view, edit, or manage workspace assets.
Every interaction within the workspace is recorded in an append-only audit log. The audit log tracks file additions, synchronization events, search queries, downloads, and permission modifications. Security teams can review the log to verify exactly which documents an agent retrieved during an automated workflow.
Fastio runs on cloud infrastructure partners, including Google Cloud Platform and Cloudflare, that are certified to industry-leading security standards. Files are protected with encryption in transit and encryption at rest, giving enterprises verifiable protection for proprietary intranet knowledge.
Advisory File Locks and Concurrent Agent Writes
When autonomous agents collaborate with human teams on documents synchronized from SharePoint, concurrent writes can cause accidental file overwrites. Fast.io addresses this through advisory file locks exposed directly through the MCP storage tool.
An agent acquires an advisory file lock before updating a document, heartbeats the lock during long-running analysis, and releases it upon completion. Because the lock is advisory, other collaborators in the workspace can see who holds the lease. If concurrent writes do occur, Fast.io's per-file version history preserves every version, allowing teams to review changes, compare diffs, and restore prior states at any time.
In collaborative deployments, an agent can create a complete workspace structure, populate it with research notes and summaries, and execute an ownership transfer to a human team member while retaining administrative oversight to support ongoing tasks.
Implementation Steps for Native Search and Agent Workspaces
Deploying an enterprise AI search pipeline requires methodical execution across identity configuration, storage synchronization, and agent testing. Following a structured implementation blueprint ensures that internal document retrieval remains accurate, secure, and compliant with enterprise standards.
IT administrators and software architects must balance end-user convenience in browser search with the rigorous isolation required by autonomous agent workflows. By systematically testing document library permissions, establishing scheduled synchronization intervals, and verifying citation accuracy, organizations can launch conversational search without compromising data integrity. The four-stage deployment blueprint below guides teams through setting up native Perplexity search alongside high-performance MCP agent workspaces for complete operational visibility and predictable query performance.
Step 1: Document Library Preparation and Audit
Before connecting any AI tool to SharePoint, audit the target document libraries:
- Remove Stale Archives: Archive outdated policy revisions, draft agreements, and temporary files so the search engine indexes only active institutional knowledge.
- Normalize Folder Structures: Consolidate fragmented project folders into coherent directory trees. Avoid deeply nested folder paths that slow down API crawling.
- Audit Access Permissions: Review SharePoint site membership and remove obsolete security groups. Ensure that sensitive executive documents reside in separate, non-synchronized site collections.
Step 2: Native Microsoft 365 Connector Activation in Perplexity
For teams using the Perplexity Enterprise web interface for daily search:
- Initiate Integration: An administrator with Microsoft Entra ID privileges logs into Perplexity, opens the Connectors section in account settings, and enables Microsoft 365.
- Grant Delegated Consent: Complete the Microsoft authentication modal, approving requested read permissions across SharePoint and OneDrive.
- Configure Internal File Scope: Instruct team members on toggling between Web and Org Files in the Perplexity query bar. Users seeking combined research should keep both sources active, while queries regarding proprietary policies should be restricted to Org Files.
Step 3: Deploying Fast.io Workspaces for Developer and Agent Workflows
For engineering teams building autonomous agents, coding pipelines, or automated document workflows:
- Provision Workspaces: Create targeted Fast.io workspaces corresponding to key business functions.
- Configure Cloud Sync: Connect SharePoint libraries via the OneDrive connector. Establish scheduled synchronization intervals to maintain freshness without hitting Microsoft Graph rate limits.
- Issue Scoped API Keys: Generate Fast.io API keys with restricted workspace permissions for your autonomous agents and development environments.
- Integrate MCP Tools: Add the Fast.io remote MCP server endpoint to your agent configuration files, enabling agents to execute semantic searches and document queries.
Step 4: Verification, Citations, and Operational Monitoring
Validate retrieval quality and operational health across both platforms:
- Verify Inline Citations: Test sample prompts across technical policies and verify that generated citations link directly to authoritative SharePoint source files.
- Monitor API Quotas: Track Microsoft Graph usage to ensure synchronization jobs remain well below the HTTP 429 throttling threshold.
- Review Audit Logs: Periodically inspect Fast.io's detailed activity log to verify that agent document reads align with authorized project boundaries.
Sources
References used to verify factual claims in this guide.
-
For organizations operating large intranet portals, Microsoft recommends syncing no more than 300,000 files in a single OneDrive or team site library to maintain performance.
-
When an automated system sends rapid batches of queries across extensive directory trees, Microsoft Graph returns HTTP status code 429 when client requests exceed service throttling thresholds.
Frequently Asked Questions
Can Perplexity search internal SharePoint documents?
Yes. Perplexity Enterprise Pro and Enterprise Max organizations can search internal SharePoint and OneDrive documents by enabling the native Microsoft 365 connector. Once authenticated via Microsoft Entra ID, users can toggle the Org Files source to search corporate files alongside public web sources with inline citations.
How do I connect Perplexity Enterprise to Microsoft 365?
To connect Perplexity Enterprise to Microsoft 365, open the My Connectors section under account settings in the Perplexity interface, locate Microsoft 365, and click Enable. Sign in with your corporate Microsoft account and complete the OAuth consent prompt to grant Perplexity read access to your authorized SharePoint and OneDrive files.
Is company data in SharePoint kept private when using Perplexity?
Yes. Perplexity maintains enterprise data protection standards for Enterprise Pro and Enterprise Max accounts. Company files retrieved through connectors are encrypted in transit and at rest, and enterprise customer data is never used to train or fine-tune Perplexity's AI models.
What is the difference between Perplexity Standard Search and High-Precision Search?
Standard Search queries SharePoint directly via Microsoft Graph APIs at query time without storing file copies, preserving live permissions but relying on real-time API latency. High-Precision Search synchronizes selected files into enterprise storage for local semantic indexing, enabling faster natural language retrieval across large technical documents.
How does an intermediate Fast.io workspace improve SharePoint search for AI agents?
An intermediate Fast.io workspace synchronizes SharePoint libraries through Cloud Sync and indexes documents automatically using Intelligence Mode. Instead of pulling full files or making slow Graph API calls, autonomous agents query concise, citation-backed text chunks via remote MCP through [Fast.io workspace storage for agents](/storage-for-agents/), minimizing token bloat and preventing API throttling.
Related Resources

Connect Perplexity and Enterprise Agents to SharePoint with Fast.io
Synchronize SharePoint document libraries into isolated Fast.io workspaces, index files automatically, and query enterprise documents via remote MCP. Every organization starts with a 14-day free trial.