Azure AI Search SharePoint: How to Index SharePoint Files for Agentic Retrieval
Indexing Microsoft SharePoint document libraries with Azure AI Search requires configuring Entra ID service principals, Graph API permissions, vector skillsets, and scheduled batch indexers. However, pipeline failure modes like Graph API throttling, folder rename indexing breaks, and ACL sync limits create friction. Syncing SharePoint folders into an intelligent workspace lets agents query indexed files directly via MCP without cloud search infrastructure.

Why SharePoint Ingestion Poses Architectural Challenges for AI Agents
When software teams connect autonomous AI agents to enterprise SharePoint document libraries, ingestion pipelines frequently break down under authentication handshakes, rate limits, and batch synchronization lag. An autonomous AI agent attempting to ground its reasoning in corporate policies, architectural specs, or vendor contracts cannot query SharePoint directly without either pulling entire document libraries into prompt context or orchestrating a brittle sequence of Entra ID app registrations, Graph API permissions, periodic batch indexers, and vector skillsets that lag behind live edits.
Azure AI Search SharePoint indexer is a cloud service connector that crawls Microsoft SharePoint document libraries to extract, chunk, and vectorize document content for enterprise search applications. Formerly known as Azure Cognitive Search before Microsoft unified its search branding in November 2023, the service provides an automated crawling mechanism designed to pull unstructured files from Microsoft 365 tenants into an Azure-hosted search index.
For enterprise teams deploying retrieval-augmented generation (RAG) architectures, connecting AI agents to SharePoint presents three distinct operational hurdles:
- Context window bloat and token cost: Document libraries contain thousands of files spanning spreadsheets, slide decks, PDFs, and rich text documents. An AI agent cannot pull full document trees into active conversation context without generating prohibitive token costs and degrading model reasoning quality through needle-in-a-haystack dilution.
- Microsoft Graph API latency and throttling: Querying the Microsoft Graph API on demand during agent tool execution introduces unpredictable latency. High-concurrency agent workflows quickly trigger HTTP 429 throttling errors from SharePoint endpoints, stalling agent reasoning loops mid-execution.
- Crawl freshness and pipeline drift: Enterprise documents change continuously. When an agent relies on periodic crawler schedules rather than event-driven indexing, the agent retrieves stale versions of documents, leading to incorrect citations and grounded hallucinations.
Engineering teams face a fundamental architectural choice when connecting AI agents to enterprise repositories: build and maintain a custom ingestion and vector pipeline on Azure AI Search, or connect agents through storage for agents using an intelligent workspace that handles synchronization, indexing, and Model Context Protocol (MCP) retrieval automatically.
Related guides
- How to Index SharePoint Documents in LlamaIndex for AI AgentsLlamaIndex SharePoint integration connects LlamaIndex readers to Microsoft SharePoint document libraries, extracting...
- How to Access SharePoint Files with Microsoft Graph API and AI AgentsThe Microsoft Graph API for SharePoint provides programmatic endpoints to access sites, lists, and document libraries...
- SharePoint Semantic Search: How to Enable AI Vector Search Across SharePointTraditional SharePoint search relies on lexical Keyword Query Language (KQL) matching, leaving relevant files hidden...
- Amazon Bedrock SharePoint Connector: Setup, Limitations, and AlternativesThe Amazon Bedrock SharePoint connector allows Amazon Bedrock Knowledge Bases to ingest and index documents stored in...
- How to Connect Dify AI to Microsoft SharePointConnecting Dify to SharePoint enables agentic workflows and LLM applications to retrieve, cite, and analyze enterprise...
- How to Integrate Flowise with Microsoft SharePointA Flowise SharePoint integration connects Flowise visual canvas nodes to SharePoint document libraries, enabling...
More on this subject: Agent File and Document Workflows (269 guides)
How to Configure the Azure AI Search SharePoint Indexer Pipeline
Deploying the Azure AI Search SharePoint indexer requires orchestrating four distinct cloud infrastructure layers: a Microsoft Entra ID application registration, Microsoft Graph read permissions, an Azure AI Search data source and indexer schedule, and a cognitive skillset for document chunking and vector embedding generation.
1. Microsoft Entra ID App Registration
Because indexers run as background services without interactive user logins, the search service authenticates to SharePoint via Microsoft Entra ID (formerly Azure Active Directory) using service principal credentials or managed identities.
In the Microsoft Entra admin center, register an application and configure the necessary API permissions:
- Application permissions: Add Microsoft Graph application permissions for
Files.Read.AllandSites.Read.All. These grant the indexer permission to crawl all site collections and document libraries across the tenant. - Admin consent: Grant tenant administrator consent for the configured application permissions.
- Client credentials: Generate a client secret or establish federated credentials linked to the Azure AI Search managed identity.
2. Azure AI Search Data Source Definition
The search data source instructs Azure AI Search how to connect to the SharePoint document library. The data source is created via the Azure AI Search REST API using the sharepoint data source type.
{
  "name": "sharepoint-datasource",
  "type": "sharepoint",
  "credentials": {
    "connectionString": "SharePointOnlineEndpoint=https://yourtenant.sharepoint.com/sites/Engineering;ApplicationId=00000000-0000-0000-0000-000000000000;ApplicationSecret=YOUR_CLIENT_SECRET;TenantId=00000000-0000-0000-0000-000000000000;"
  },
  "container": {
    "name": "defaultSiteLibrary",
    "query": "includeLibrary=Shared Documents"
  }
}
The container property defines the target library. You can target the default site document library or specify specific named document libraries within the site collection.
3. Vector Index Schema and Skillset Pipeline
To support semantic search and agent retrieval, raw text extracted from documents must be split into chunks and converted into vector embeddings. This requires defining a search index with vector fields and a cognitive skillset that chains text splitting with embedding generation.
The target search index requires vector fields (for example, a 1536-dimensional collection field corresponding to Azure OpenAI text-embedding-3-small or text-embedding-ada-002) alongside metadata fields for document titles, paths, and modification dates.
The skillset definition uses #Microsoft.Skills.Text.SplitSkill to recursively partition text into chunks and #Microsoft.Skills.Text.AzureOpenAIEmbeddingSkill to generate vector representations:
{
  "name": "sharepoint-vector-skillset",
  "skills": [
    {
      "@odata.type": "#Microsoft.Skills.Text.SplitSkill",
      "name": "chunking-skill",
      "description": "Split document text into chunks",
      "textSplitMode": "pages",
      "maximumPageLength": 2000,
      "pageOverlapLength": 500,
      "inputs": [
        { "name": "text", "source": "/document/content" }
      ],
      "outputs": [
        { "name": "textItems", "targetName": "pages" }
      ]
    },
    {
      "@odata.type": "#Microsoft.Skills.Text.AzureOpenAIEmbeddingSkill",
      "name": "vector-embedding-skill",
      "description": "Generate embeddings for each text chunk",
      "context": "/document/pages/*",
      "resourceUri": "https://your-openai-service.openai.azure.com",
      "apiKey": "YOUR_AZURE_OPENAI_KEY",
      "deploymentId": "text-embedding-3-small",
      "inputs": [
        { "name": "text", "source": "/document/pages/*" }
      ],
      "outputs": [
        { "name": "embedding", "targetName": "vector" }
      ]
    }
  ]
}
4. Indexer Scheduling and Field Mappings
The indexer binds the data source, skillset, and search index into an executable pipeline. The configuration defines the execution schedule, field mappings for system metadata, and output field mappings that map chunked embeddings into the index.
{
  "name": "sharepoint-indexer",
  "dataSourceName": "sharepoint-datasource",
  "targetIndexName": "sharepoint-vector-index",
  "skillsetName": "sharepoint-vector-skillset",
  "schedule": {
    "interval": "PT2H"
  },
  "parameters": {
    "configuration": {
      "indexedFileNameExtensions": ".pdf,.docx,.xlsx,.pptx,.txt,.html",
      "dataToExtract": "contentAndMetadata"
    }
  }
}
This configuration instructs Azure AI Search to poll the SharePoint library every 2 hours, parse matching file types, execute chunking and embedding skillsets, and populate the vector index.
Why Azure AI Search SharePoint Indexers Fail in Production
While the Azure AI Search SharePoint indexer provides an automated ingestion route, production deployments uncover recurring friction points that impact retrieval reliability and operational cost.
Microsoft Graph Throttling and Run Timeouts
The SharePoint indexer queries SharePoint libraries using the Microsoft Graph API. Microsoft Graph applies aggressive rate-limiting quotas per tenant and per application ID. During initial crawls or bulk document updates across large libraries, Graph endpoints respond with HTTP 429 status codes.
Although Azure AI Search contains built-in retry logic with exponential backoff, frequent throttling slows indexing throughput. Standard Azure AI Search indexer executions enforce a maximum duration limit of 2 hours per run. In document libraries containing tens of thousands of complex PDFs or slide presentations, the indexer frequently hits the run execution ceiling before completing document traversal, deferring remaining files to subsequent schedule windows.
Incremental Indexing Traps and Metadata Rescans
Incremental indexing relies on SharePoint change tracking to detect modified files. However, operational behaviors in Microsoft 365 can disrupt change detection:
- Folder renames reset indexing history: Microsoft Learn notes that renaming a SharePoint folder breaks incremental indexing and causes the folder contents to be treated as new content. When a team reorganizes folder hierarchies, the indexer reprocesses every document within the renamed directory tree, regenerating embeddings and consuming embedding model API tokens.
- Automated metadata updates: Automated Microsoft 365 processes, DLP scanners, or custom Power Automate flows that modify item properties touch file metadata timestamps. The indexer interprets these metadata updates as document revisions, triggering unnecessary ingestion passes across unmodified document bodies.
Identity and Access Control List Synchronization
Enterprise SharePoint libraries rely on complex access control lists (ACLs) to enforce departmental boundaries. Azure AI Search offers preview capabilities to index SharePoint ACLs, but significant constraints remain:
- Nested Entra ID groups: Azure AI Search indexer ACL synchronization does not expand Microsoft Entra security groups nested inside SharePoint groups. If access permissions are assigned through nested security groups, documents may be unintentionally omitted from authorized search queries.
- Conditional Access policy blocks: Tenants enforcing strict Microsoft Entra ID Conditional Access policies often block the indexer connection string or managed identity because the service principal cannot satisfy device-compliance or interactive multi-factor authentication requirements.
Infrastructure Complexity and Compounding Costs
Operating an Azure AI Search pipeline requires managing multiple billable components:
- Dedicated Azure AI Search service units (Basic, Standard S1, or Standard S2 tiers)
- Cognitive skills execution billing for document cracking and text partitioning
- Azure OpenAI embedding token consumption on initial crawls and metadata resets
- Azure Monitor diagnostic log retention for indexer run tracking
For engineering teams whose primary goal is enabling AI agents to search enterprise documents, managing this cloud infrastructure stack creates continuous administrative overhead.
How Remote MCP Workspace Connectors Simplify Agent Retrieval
Engineering teams building agentic workflows increasingly favor direct agent storage connectors over dedicated cloud search ETL pipelines. In an agent storage connector architecture, teams keep their existing enterprise storage repositories while synchronizing target folders into an intelligent workspace that natively exposes search tools to AI agents.
How the Workspace Connector Operates
In this architecture, your organization maintains SharePoint as the primary storage location for team collaboration. The SharePoint folder synchronizes into a Fast.io workspace. Synchronization can run on a schedule or on demand, operating as a one-way or two-way sync:
- Storage persistence: Documents live in their original SharePoint document libraries, preserving existing team workflows, editing habits, and internal sharing links.
- Automated workspace indexing: Once files sync into the Fast.io workspace, Intelligence Mode automatically indexes documents for retrieval-augmented generation. Full-text search, semantic search, and metadata value indexing occur on arrival without requiring manual skillset configuration, chunking definitions, or separate vector database hosting.
- Remote Model Context Protocol (MCP) access: Rather than writing custom retrieval code against Azure search endpoints, AI agents connect to the remote Fast.io MCP server. The agent executes targeted semantic searches across the workspace, retrieving precise excerpts and document citations directly into its reasoning loop.
This pattern eliminates the need to configure Microsoft Entra service principals, manage Azure search indexes, write JSON skillset definitions, or handle Graph API 429 backoff logic. The agent interacts with the workspace through standard MCP tool calls.
Architecture Comparison
On multi-document retrieval benchmarks published at Fast.io benchmark tests, Fastio was measured the fastest and the lowest cost of the providers tested. By indexing files upon arrival and serving search queries through an MCP endpoint, agents retrieve relevant context without pulling full documents into memory.


Connect AI Agents to Enterprise Files Without Azure Infrastructure
Sync your SharePoint documents into an intelligent workspace where files are automatically indexed for hybrid semantic search. Agents query through the remote Fast.io MCP server with full citations. Every organization starts with a 30-day free trial.
Steps to Connect AI Agents to Indexed Workspaces via MCP
Connecting AI agents to an indexed workspace relies on the Model Context Protocol (MCP), an open standard that allows Large Language Models to discover and invoke tools securely. Fast.io exposes an MCP endpoint over Streamable HTTP at https://mcp.fast.io/mcp/tools, providing a consolidated toolset for workspace search, file reading, and metadata extraction.
Configuring the Agent Client
Custom agent frameworks and headless runtimes connect to Fast.io by declaring the remote MCP endpoint in their configuration. Interactive clients sign in with OAuth in the browser as detailed in the setup documentation, while headless environments send an API key in the authorization header:
{
  "mcpServers": {
    "fastio": {
      "url": "https://mcp.fast.io/mcp/tools",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Agent Tool Invocation for Hybrid Search
The Fast.io MCP server exposes a consolidated storage tool driven by an action parameter. To query indexed SharePoint files, an agent calls the storage tool with the search action, passing a natural language query and optional workspace or folder scope filters:
{
  "tool": "storage",
  "arguments": {
    "action": "search",
    "query": "What are the termination notice requirements in the vendor master services agreement?",
    "workspace_id": "ws_enterprise_contracts"
  }
}
The search engine executes a hybrid query combining full-text search and semantic vector embeddings across the indexed files. The MCP server returns relevant text snippets accompanied by file citations, file paths, and version metadata. The agent ingests only the relevant text fragments, avoiding context window bloat and eliminating whole-file download latency.
Structured Extraction with Metadata Views
Enterprise SharePoint libraries often contain structured data embedded inside unstructured files, such as effective dates, invoice numbers, total contract values, or compliance ratings.
Beyond unstructured search, Fast.io provides Metadata Views to turn documents into live, queryable tables. Users define fields in natural language, and the system extracts typed schemas (Text, Integer, Decimal, Boolean, Date & Time, JSON) across PDFs, Word documents, and presentations without manual template or OCR configuration.
AI agents query Metadata Views via MCP to filter documents by structured attributes before executing detailed content searches, dramatically narrowing retrieval scope for multi-step agent investigations.
Multi-Agent Governance and Version History
When multiple agents interact with shared enterprise documents, governance and auditability are essential:
- Per-file version history: Every document modification preserves complete historical revisions. If an agent writes an updated document summary or proposal draft, prior versions remain intact and auditable.
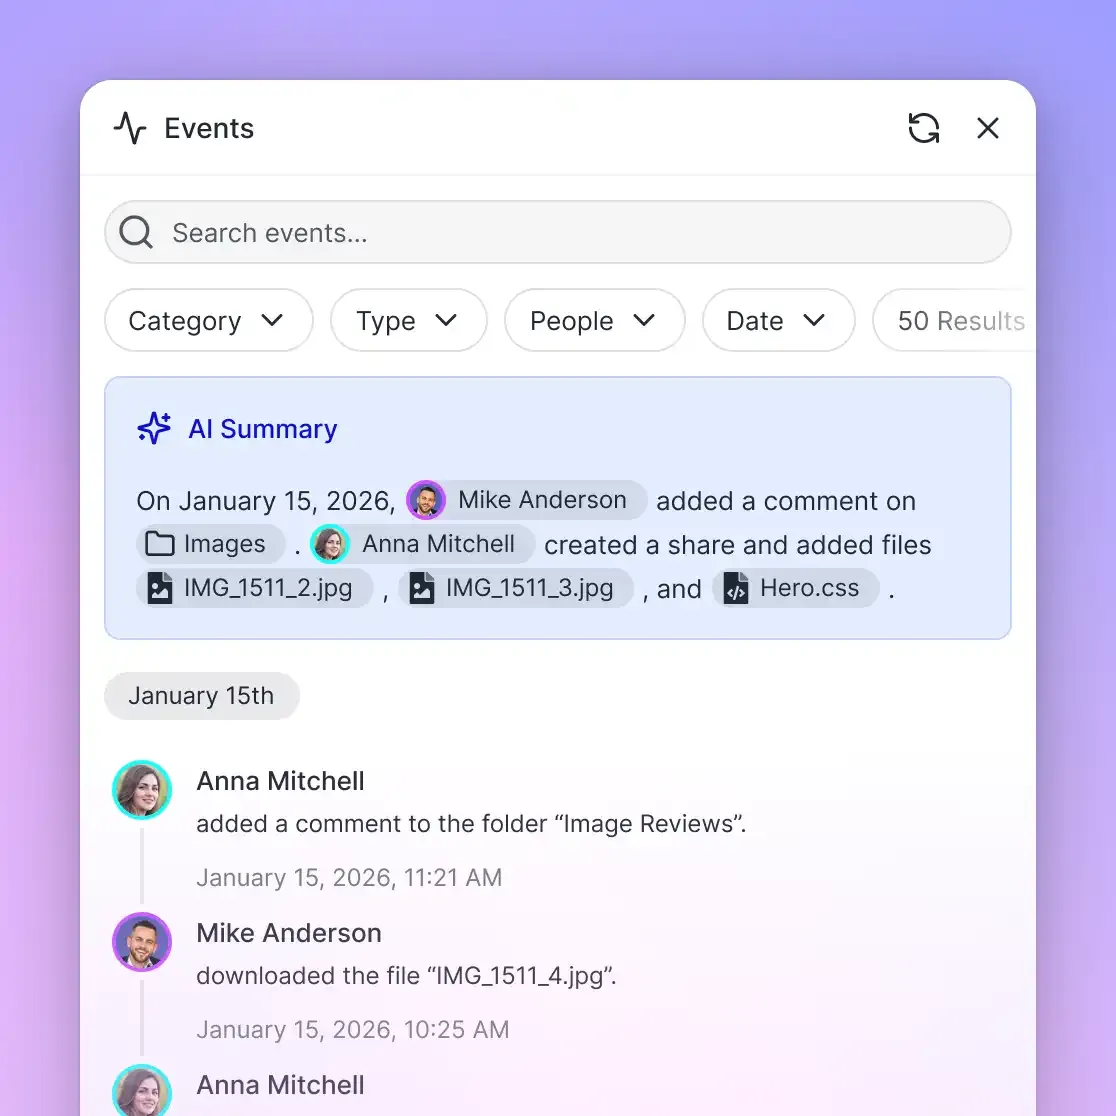
- Append-only audit log: Every file access, search query, and metadata extraction is recorded in an immutable audit trail, providing clear operational visibility for enterprise compliance teams.
- Agent-to-human handoff: Autonomous agents can initialize workspaces, organize imported SharePoint files, populate Metadata Views, and transfer organization ownership to human operators while retaining administrative access.
How to Choose the Right Retrieval Architecture for Your Organization
Deciding between Azure AI Search and an intelligent workspace connector depends on your organization's infrastructure footprint, security policies, and target agent tooling.
When to Choose Azure AI Search SharePoint Indexer
Azure AI Search is well-suited for organizations that meet specific enterprise conditions:
- Deep Azure ecosystem lock-in: Your team already hosts applications within Azure Virtual Networks, uses Azure OpenAI service deployments exclusively, and manages infrastructure through Azure Resource Manager or Terraform.
- Custom cognitive skill chains: Your retrieval pipeline requires complex cognitive skills, such as custom machine learning models hosted in Azure Machine Learning, multi-language speech-to-text extraction, or proprietary image analysis skillsets.
- Dedicated cloud operations staff: You have cloud infrastructure engineers available to manage Microsoft Entra ID permissions, monitor indexer execution logs in Azure Monitor, tune vector index HNSW parameters, and troubleshoot Graph API throttling.
When to Choose a Remote Workspace Connector
An intelligent workspace connector like Fast.io is the better choice when your primary objective is enabling AI agents with minimal infrastructure friction:
- Rapid deployment: You need AI agents querying SharePoint documents immediately without provisioning Azure search services, designing vector schemas, or handling REST API authentication handshakes.
- Multi-model agent flexibility: Your engineering team runs diverse LLMs (Claude Code, OpenAI GPT models, Google Gemini, or local open-weights models) that connect to storage via standard Model Context Protocol tooling.
- Operational simplicity: You want automatic chunking, hybrid vector search, and citation-backed retrieval without managing background crawl timers, debugging folder rename breaks, or absorbing unexpected embedding re-indexing costs. Review available pricing and plan options to size workspaces for your team.
Operational Next Steps
To connect your AI agents to enterprise SharePoint files using an intelligent workspace:
- Identify the target SharePoint document libraries or folders required for agent context.
- Create a shared workspace in Fast.io and enable Intelligence Mode for automatic document indexing.
- Synchronize the SharePoint folder into the workspace on your required operational cadence.
- Add the Fast.io remote MCP server endpoint (
https://mcp.fast.io/mcp/tools) to your agent client configuration. - Direct your agents to query the indexed workspace using the consolidated
storagetool with thesearchaction.
Sources
References used to verify factual claims in this guide.
-
Microsoft Learn notes that renaming a SharePoint folder breaks incremental indexing and causes the folder contents to be treated as new content.
Frequently Asked Questions
How do you connect Azure AI Search to SharePoint?
Connecting Azure AI Search to SharePoint requires registering an application in Microsoft Entra ID with Microsoft Graph application permissions (Files.Read.All and Sites.Read.All), granting admin consent, and creating an Azure AI Search data source using the sharepoint type. You then define a target search index, configure a cognitive skillset for document chunking and vector embeddings, and establish an indexer schedule to periodically crawl the document library.
What are the limitations of the Azure AI Search SharePoint indexer?
Key limitations include lack of support for OneNote notebooks, lack of direct support for tenants with strict Entra ID Conditional Access policies, and failure to expand nested Entra security groups within SharePoint groups during ACL sync. Renaming a SharePoint folder also breaks incremental indexing, causing all folder contents to be treated as new documents and triggering a full re-indexing cycle that consumes embedding API tokens.
Is there a simpler way for AI agents to query SharePoint files than Azure AI Search?
Yes. Instead of building and maintaining an Azure AI Search pipeline, teams can sync SharePoint folders into a Fast.io workspace. Fast.io automatically indexes documents on arrival using Intelligence Mode for hybrid full-text and semantic search. AI agents then query the indexed files directly through the remote Model Context Protocol (MCP) server, eliminating the need to manage Azure infrastructure or vector databases.
Does Azure AI Search support real-time indexing of SharePoint document changes?
No. The Azure AI Search SharePoint indexer operates on a polling schedule (such as hourly or every few hours). It does not provide real-time event-driven indexing. High-frequency polling can quickly trigger Microsoft Graph API rate-limiting errors (HTTP 429), creating a delay between document modifications in SharePoint and their availability in the search index.
What Microsoft Graph permissions does the SharePoint indexer require?
The SharePoint indexer requires application-level permissions for Files.Read.All and Sites.Read.All in Microsoft Graph to crawl document libraries across site collections without requiring user interactive sign-in. These permissions require global or application administrator consent in Microsoft Entra ID.
How does the Fast.io MCP server connect AI agents to indexed SharePoint documents?
The Fast.io MCP server runs remotely over Streamable HTTP at `https://mcp.fast.io/mcp/tools`. Teams configuring [storage for agents](/storage-for-agents/) declare the server in their client settings and invoke the consolidated storage tool using the search action. The server queries the workspace's hybrid neural index and returns relevant text snippets with source citations directly to the agent.
How does the SharePoint indexer handle document permissions and Access Control Lists?
Azure AI Search offers preview support for indexing SharePoint Access Control Lists (ACLs) to filter search results based on user identity. However, this feature does not expand Microsoft Entra groups nested inside SharePoint groups, which can result in users being unable to find documents they have permission to access unless security filtering is relaxed.
Related Resources

Connect AI Agents to Enterprise Files Without Azure Infrastructure
Sync your SharePoint documents into an intelligent workspace where files are automatically indexed for hybrid semantic search. Agents query through the remote Fast.io MCP server with full citations. Every organization starts with a 30-day free trial.