How to Connect Google Gemini to SharePoint for Enterprise Document Search
Deploying a Gemini SharePoint connector allows enterprise teams to query, retrieve, and summarize files stored across Microsoft 365 directly within Google Gemini agent workflows. While cross-cloud architectures separate documents in SharePoint from AI models in Google Cloud, connecting them requires balancing authentication and retrieval speed. This guide covers native data stores, federated search, and unified workspace retrieval via remote MCP.

Why Enterprise Teams Need a Gemini SharePoint Connector
Enterprise technology stacks rarely stay confined to a single cloud provider. While Microsoft 365 and SharePoint host corporate document libraries, policy handbooks, contracts, and project records, engineering and analytics teams increasingly deploy Google Gemini for generative AI tasks, multimodal analysis, and long-context processing. When developers attempt to point Gemini models at enterprise files, they encounter an immediate infrastructure barrier: SharePoint document libraries sit protected behind Microsoft Entra ID boundaries, while Gemini environments operate in Google Cloud.
A Gemini SharePoint connector is a data integration bridge that allows Google Gemini models to query, retrieve, and summarize files stored in Microsoft SharePoint document libraries. Without this integration layer, teams face painful compromises. Individual developers download local file batches, email attachments between teams, or write brittle ad hoc extraction scripts. These manual workarounds introduce severe governance gaps, violate document retention rules, and leave models answering questions from stale data.
Connecting Gemini to SharePoint solves three fundamental operational challenges:
- Centralized Knowledge Grounding: Rather than copying documents across departments, Gemini retrieves verified passages directly from authoritative SharePoint sites.
- Access Control Preservation: Corporate file libraries require distinct permissions across business units. A proper connector architecture respects document boundaries rather than dumping sensitive materials into unpartitioned repositories.
- Context Optimization: Raw document libraries contain thousands of PDFs, spreadsheets, and Word documents. A connector provides the retrieval pipeline needed to select relevant paragraphs, keeping prompt token overhead low while delivering accurate, citation-backed answers.
Building this cross-cloud bridge requires choosing between two primary architectures: configuring Google Cloud's native enterprise data store connectors, or syncing libraries into a unified intelligent workspace accessible through the Model Context Protocol (MCP). Each approach addresses specific technical requirements, administrative capabilities, and synchronization trade-offs.
Related guides
- ChatGPT SharePoint Connector: Enterprise Setup vs. Fast.io MCP WorkspacesConnecting ChatGPT to SharePoint document libraries gives conversational models access to enterprise knowledge. While...
- How to Connect Dify AI to Microsoft SharePointConnecting Dify to SharePoint enables agentic workflows and LLM applications to retrieve, cite, and analyze enterprise...
- SharePoint Agent: Connecting Autonomous AI Agents to SharePoint StorageConnecting autonomous AI agents to enterprise SharePoint storage gives tool-calling assistants access to company...
- How to Connect ChatGPT to SharePoint Document LibrariesConnecting ChatGPT to SharePoint allows conversational AI models to query enterprise document libraries through...
- How to Connect NotebookLM (Now Gemini Notebook) to SharePointA NotebookLM (now Gemini Notebook) SharePoint integration enables teams to ground AI research on corporate documents...
- Connecting AutoGen Multi-Agent Systems to SharePoint: Architecture and SetupAn AutoGen SharePoint connector enables Microsoft AutoGen agent teams to authenticate against Microsoft Graph and query...
More on this subject: Agent File and Document Workflows (269 guides)
How to Configure the Native Gemini SharePoint Connector in Google Cloud
Google Cloud supports SharePoint integration through Gemini Enterprise and Vertex AI Search (part of the Gemini Enterprise Agent Platform). This built-in path allows organizations to connect SharePoint Online libraries directly into Google Cloud data stores for grounding LLM prompts and generative search applications.
Setting up the native Google Gemini SharePoint connector requires coordinated administrative access across both Microsoft 365 and Google Cloud Platform.
1. Registering the Microsoft Entra ID Application
Before Google Cloud can access SharePoint Online, you must register a dedicated enterprise application in the Microsoft Entra admin center (formerly Azure Active Directory) to manage OAuth 2.0 authentication:
- Sign in to the Microsoft Entra admin center with tenant administrator privileges.
- Navigate to Identity > Applications > App registrations and select New registration.
- Name the application (for example,
Gemini-Enterprise-SharePoint-Connector). - Set the redirect URI to Google Cloud's OAuth handler:
https://vertexaisearch.cloud.google.com/oauth-redirect. - Under Certificates & secrets, generate a new client secret and record the value immediately.
- Under API permissions, select Microsoft Graph and add application permissions for SharePoint reading, such as
Sites.Read.AllorFiles.Read.All. Grant admin consent for your organization. - Note your Application (client) ID, Directory (tenant) ID, and Client Secret.
2. Creating the SharePoint Data Store in Google Cloud
With Microsoft Entra credentials generated, switch to the Google Cloud console to configure the data store:
- Ensure your user account holds the Discovery Engine Editor role (
roles/discoveryengine.editor) on the target Google Cloud project. - Navigate to the Gemini Enterprise or Vertex AI Search console and select Data stores.
- Click Create data store and select Microsoft SharePoint as your data source.
- Enter your Microsoft Entra details: Client ID, Client Secret, Tenant ID, and your organization's SharePoint site URL (such as
https://example.sharepoint.com/sites/KnowledgeBase). - Choose your connection mode: Data ingestion or Federated search.
Data Ingestion vs. Federated Search Trade-Offs
Google Cloud offers two connection mechanisms for SharePoint, each presenting distinct operational trade-offs:
- Data Ingestion (Batch Indexing): The connector crawls SharePoint document libraries, parses files, splits content into text chunks, and generates vector embeddings stored in a Google-managed vector database. This mode provides fast semantic search and deep content retrieval. However, it requires initial ingestion time, periodic sync schedules, and copies document data into Google Cloud storage. Incremental synchronizations must be monitored closely to prevent duplicate chunking.
- Federated Search (Live Retrieval): The connector does not copy or pre-index files in Google Cloud. Instead, incoming user queries are translated and passed in real time to the SharePoint Search API via Microsoft Graph. This guarantees document freshness and eliminates secondary storage. The downside is increased query latency, rigid keyword matching constraints, and vulnerability to Microsoft Graph API rate limits (HTTP 429 throttling) during traffic spikes.
For organizations that need rich semantic retrieval across complex documents without maintaining dedicated Entra ID daemon services, an intermediate workspace layer provides a cleaner alternative.
How to Bridge SharePoint and Gemini Through an Intelligent Workspace
A major friction point with native cross-cloud connectors is administrative overhead. Enterprise IT teams are frequently reluctant to grant broad tenant-level Microsoft Graph application permissions to third-party cloud consoles. Furthermore, native ingestion pipelines duplicate gigabytes of unstructured data into specialized vector stores that require separate maintenance and monitoring.
An alternative architectural approach preserves SharePoint as your team's authoritative file repository while syncing selected document libraries into a unified workspace.
+----------------------------+
| Microsoft SharePoint       |
| (Authoritative Storage)    |
+--------------+-------------+
               |
               | Cloud Sync (Scheduled or On-Demand)
               v
+----------------------------+
| Fast.io Workspace          |
| - Intelligence Mode (RAG)  |
| - Hybrid Search (Full-Text |
|   + Semantic Retrieval)    |
| - Metadata Views           |
+--------------+-------------+
               |
               | Remote MCP Transport (Streamable HTTP / SSE)
               v
+----------------------------+
| Google Gemini Agent        |
| (Vertex AI / Custom ADK)   |
+----------------------------+
In this architecture, your team keeps their existing storage exactly where it is. Using Fast.io Cloud Sync, designated SharePoint libraries sync into a dedicated workspace through the OneDrive connector. Cloud Sync runs one-way or two-way, on a recurring schedule or on demand. It is never continuous, live, or real-time. (Note that Google Drive currently supports file imports, with two-way sync coming soon; Dropbox, Box, and OneDrive libraries sync on schedule or on demand).
Automated Semantic Indexing with Intelligence Mode
When documents arrive in a workspace, Fast.io Intelligence Mode automatically indexes them for both full-text keyword matching and semantic retrieval. You do not need to configure an external vector database, provision chunking scripts, or manage embedding models.
The workspace search engine combines:
- Exact Full-Text Matching: Locates specific contract IDs, SKU numbers, product codes, and legal clause headings.
- Semantic Search: Understands conceptual meaning, retrieving relevant sections even when queries use synonyms or non-matching phrasing.
- Metadata Value Filtering: Filters documents based on structured metadata attributes, such as department, review status, or creation date.
In independent connector performance evaluations, Fast.io was measured the fastest and the lowest cost of the providers tested (see the complete methodology and data at the Fast.io connector benchmarks).
By handling indexing inside the workspace, cross-cloud token transfers are minimized. Instead of streaming entire multi-megabyte PDFs or raw document trees over network boundaries into Gemini's context window, the model receives only high-relevance text passages paired with page-level citations.


Connect SharePoint Document Libraries to Gemini Workspaces
Deploy an intelligent workspace with scheduled Cloud Sync, automated semantic search, and remote MCP endpoints for Google Gemini models. Start your 30-day free trial.
Steps to Query SharePoint Documents with Gemini via Remote MCP
Connecting Gemini to your synced SharePoint workspace does not require building custom REST middleware. Instead, developers can use the Model Context Protocol (MCP), an open standard that allows AI agents to interact with external tools and data stores through standardized interfaces.
Fast.io provides an official remote MCP server accessible over Streamable HTTP at https://mcp.fast.io/mcp/tools, with setup instructions available in the documentation. Because the server is hosted remotely, agents running in Google Cloud Run, Vertex AI, or local developer workstations connect directly over standard HTTPS without running local daemon bridges.
Configuring MCP for Gemini Agents
When building an agent using the Google Agent Development Kit (ADK), LangChain, or custom Python orchestration, you configure the remote MCP endpoint with a scoped API key.
Here is a standard client configuration connecting Gemini to the remote MCP server:
{
  "mcpServers": {
    "fastio-sharepoint": {
      "url": "https://mcp.fast.io/mcp/tools",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Retrieval Execution Workflow
Once connected, the Gemini model uses the consolidated MCP toolset to inspect workspaces, query indexed documents, and retrieve specific passages.
A typical retrieval flow proceeds through four distinct stages:
- User Inquiry: A team member asks Gemini, "What are the dispute resolution procedures specified in our active regional vendor agreements?"
- Targeted Tool Invocation: The Gemini agent identifies the appropriate workspace tool and calls
storage/searchwith the user query, scoping the search to the synchronized SharePoint folder. - Hybrid Search Execution: The workspace queries its search index, evaluating keyword relevance and semantic embeddings across documents. It identifies matching excerpts from agreement PDFs.
- Context Injection and Response Generation: The MCP server returns concise text passages with document titles, folder paths, and page numbers. Gemini synthesizes the answer, citing the exact source documents without loading irrelevant document pages.
Because the MCP server handles search remotely, developers avoid passing broad Graph API credentials to their LLM environment. The agent interacts solely with the workspace storage and search tools permitted by its API key.
How to Manage Governance, Metadata Extraction, and Multi-Agent Workflows
Deploying AI agents across enterprise documents requires disciplined operational governance. When AI models read and extract information from sensitive business files, IT leaders must maintain visibility into what data was accessed, track document revisions, and establish clear operational boundaries.
An intelligent workspace provides built-in governance layers that protect SharePoint assets while expanding agent capabilities.
Structured Extraction with Metadata Views
Many SharePoint libraries contain structured business records, such as vendor agreements, invoices, insurance policies, and compliance reports. Reading these files through plain chat prompts can be inefficient when teams need structured data across hundreds of documents.
Fast.io Metadata Views turn unstructured document collections into live, queryable databases. Rather than writing brittle regular expressions or manual OCR rules:
- Users describe the target fields in natural language (for example: "vendor name, agreement expiration date, governing law, annual contract value").
- AI inspects matching workspace documents and constructs a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time fields.
- The platform extracts structured data from PDFs, scanned documents, Word files, and spreadsheets, populating a sortable data grid.
- Agents can query Metadata Views directly through MCP, filtering files by extracted metadata values (such as querying agreements where contract value exceeds a specific threshold).
Coordinating Multi-Agent Access with Advisory File Locks
In multi-agent architectures, multiple specialized agents may interact with the same workspace concurrently. For example, a research agent queries SharePoint documents, a summarization agent drafts briefing notes, and a reporting agent compiles weekly summaries.
To coordinate concurrent writes and prevent race conditions, Fast.io provides advisory per-file locking through the MCP storage tool (lock-acquire, lock-status, and lock-release). An agent acquires a lease on a file before writing. Other agents and team members can inspect who holds the lock and pause operations. The lock expires automatically unless renewed by a heartbeat, and concurrent writes still preserve every version in the file's revision history.
Version History, Audit Trails, and Ownership Transfer
Enterprise storage systems must maintain accountability across automated and human operations:
- Per-File Version History: Every document modification preserves full version history. Prior versions can be inspected or restored at any time, ensuring agent modifications remain reversible.
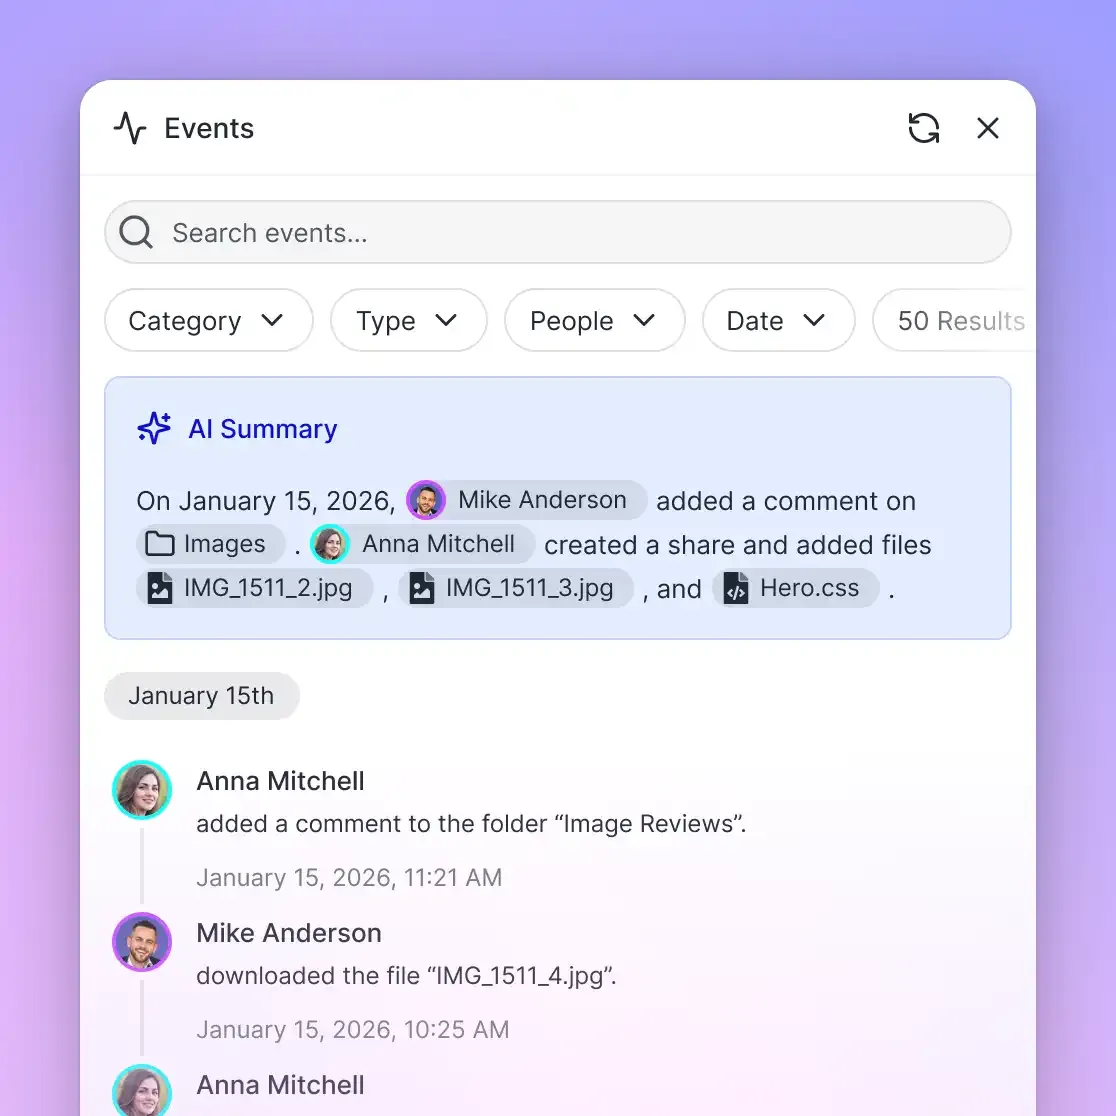
- Append-Only Audit Log: The workspace records an immutable log of file uploads, searches, permissions adjustments, downloads, and AI operations. This provides a verifiable chain of custody for enterprise compliance reviews.
- Agent-to-Human Ownership Transfer: An external systems integrator or automated setup script can configure the workspace, sync the SharePoint library, establish Metadata Views, and transfer workspace ownership to a corporate executive through a claim link, while preserving operational agent access.
Every organization starts with a 30-day free trial, which requires a credit card. Subscriptions are available on the Starter plan at $29/mo (5 seats, 1 TB storage, 300,000 credits a month), Business at $99/mo (20 seats, 10 TB storage, 1,200,000 credits a month), and Enterprise at $299/mo (50 seats with addable seats, 50 TB storage, 4,500,000 credits a month) detailed on Fast.io pricing. Annual billing options provide discounted rates. Credits meter AI operations. Storage, bandwidth, and member seats come with the plan.
Sources
References used to verify factual claims in this guide.
-
RAG Engine on Gemini Enterprise Agent Platform supports Retrieval-Augmented Generation to ground generative AI models on enterprise data sources.
-
The SharePoint API in Microsoft Graph exposes three major resource types for accessing sites, lists, and document libraries.
Frequently Asked Questions
Can Google Gemini connect to Microsoft SharePoint?
Yes. Google Gemini can connect to Microsoft SharePoint either natively through Google Cloud Gemini Enterprise data stores or via an intelligent workspace using the Model Context Protocol (MCP). The native integration uses Microsoft Entra ID authentication and Microsoft Graph APIs to index or federate SharePoint Online sites. The workspace approach syncs SharePoint libraries into a shared workspace that Gemini queries via remote MCP tools.
How do I query SharePoint documents with Gemini?
You can query SharePoint documents by configuring a SharePoint connector in Vertex AI Search or by connecting Gemini to an indexed Fast.io workspace using MCP. Once connected, Gemini performs semantic retrieval against the document index, extracting relevant paragraphs, tables, and page citations to generate answers grounded directly in your SharePoint files.
What is the best way to bridge SharePoint files into Google Vertex AI?
The recommended approach depends on your governance and infrastructure requirements. For organizations with deep Google Cloud Search integration and tenant-level Azure administrative consent, Google Cloud's native SharePoint data store offers managed batch ingestion. For teams seeking rapid setup, hybrid search, structured metadata extraction, and multi-agent coordination without broad tenant permissions, syncing SharePoint libraries into a Fast.io workspace with remote MCP querying provides lower operational friction.
What is the difference between federated search and data ingestion for SharePoint?
Data ingestion crawls SharePoint libraries, parses files, and stores vector embeddings in a managed database for rapid semantic retrieval. Federated search queries the live SharePoint Search API via Microsoft Graph in real time without duplicating file data. Ingestion delivers faster semantic answers but requires periodic syncs, while federated search offers live file freshness but is subject to Graph API rate limits and slower query response times.
How does remote MCP simplify connecting Gemini to enterprise document libraries?
The Model Context Protocol provides an open, vendor-neutral standard for connecting AI models to tools and storage. Instead of writing custom API integration code for Microsoft Graph or managing private vector databases, developers point Gemini at a remote MCP endpoint over Streamable HTTP. Gemini calls standardized search and retrieval tools, receiving only the necessary document passages.
Does connecting Gemini to SharePoint duplicate or alter original documents?
No. When using read-only connectors or one-way workspace synchronization, original SharePoint files remain unaltered in their primary Microsoft 365 environment. The connector indexes content for semantic retrieval, and any collaborative notes or structured extractions created during AI analysis are stored in the workspace without modifying source files.
Related Resources

Connect SharePoint Document Libraries to Gemini Workspaces
Deploy an intelligent workspace with scheduled Cloud Sync, automated semantic search, and remote MCP endpoints for Google Gemini models. Start your 30-day free trial.