Git LFS Limits: File Caps, Bandwidth Quotas, and Storage Workarounds
Git LFS limits on GitHub restrict single large file pointers to 2 GB on Free and Pro accounts, 4 GB on Team accounts, and 5 GB on Enterprise Cloud, while capping monthly storage and download bandwidth. Exceeding monthly bandwidth without a payment method blocks repository downloads and breaks automated pipelines. Understanding these thresholds prevents deployment failures and reveals when external workspace storage offers a more reliable architecture for large assets.

What Git LFS Limits Apply Across GitHub Plans
GitHub blocks any standard Git commit containing a file larger than 100 MiB and enforces a maximum Git LFS file cap of 2 GB on Free and Pro plans, extending to 4 GB on Team and 5 GB on Enterprise Cloud.
Git was designed to track differences in lines of plain text, not multi-gigabyte binary assets. When developers commit machine learning models, database snapshots, or high-resolution media directly to a standard Git repository, performance degrades quickly. Git compresses every revision into local history objects, forcing every collaborator and continuous integration runner to download the entire cumulative history on clone.
Git Large File Storage (Git LFS) addresses this architecture by replacing large binaries in your repository with tiny text pointers. The actual binary data transfers to a dedicated storage backend, while your Git tree tracks only a lightweight pointer file that records an object identifier (OID) and the file size in bytes:
version https://git-lfs.github.com/spec/v1
oid sha256:4cac19622fc3ada9c0fdeadb33f88f367b541f38b89102a3f1261ac81fd5bcb5
size 84977953
GitHub enforces distinct boundaries between standard Git operations, web interface uploads, and Git LFS tracking. Files uploaded through the GitHub web browser interface cannot exceed 25 MiB. Command-line Git pushes trigger a warning when any individual file exceeds 50 MiB, and GitHub blocks pushes completely if any untracked file exceeds 100 MiB. Additionally, GitHub documentation recommends keeping repositories compact, advising that smaller repositories clone faster and maintain better reliability.
When files exceed 100 MiB, Git LFS becomes mandatory. GitHub governs Git LFS through per-file size caps alongside monthly storage and bandwidth quotas that scale according to your account subscription.
Files that exceed your tier single-file cap fail during git push with an explicit error message rejecting the upload. Any file that exceeds GitHub Enterprise Cloud 5 GB ceiling is rejected immediately by Git LFS.
Historically, GitHub allotted 1 GB of storage and 1 GB of bandwidth to free accounts, requiring teams to purchase pre-paid $5 data packs for additional increments. GitHub replaced data packs with metered billing. Under this model, Free and Pro accounts receive 10 GiB of storage and 10 GiB of bandwidth per month, while Team and Enterprise Cloud organizations receive 250 GiB of each. Additional storage and download bandwidth accrue through metered billing rather than pre-paid data packs.
Related guides
- ChatGPT Message Limits: Quotas, Cooldowns, and Large File WorkaroundsText chat in ChatGPT is unlimited; uploads, images, and voice are capped within rolling windows. When conducting...
- Vertex AI Token Limits: Model Context Windows, Output Caps & Storage WorkaroundsVertex AI token limits define the maximum input context window, capped at 2,097,152 tokens for Gemini 1.5 Pro, and...
- gRPC Message Size Limit: 4MB Default Cap & RESOURCE_EXHAUSTED FixesThe default gRPC message size limit is 4 MB (4,194,304 bytes) for inbound messages, throwing a...
- AWS Bedrock Token Limits: Model Output Caps, Converse API Parameters, and QuotasAn AWS Bedrock token limit refers to the parameter-enforced boundaries on input prompt length and maximum generated...
- ChatGPT Canvas Limits: File Sizes, Document Length, and WorkaroundsChatGPT Canvas limits documents to practical thresholds of roughly 4,000 lines of code or 25,000 words, running in an...
- ChatGPT Token Limits: Input, Output, and Large File WorkaroundsThe ChatGPT token limit defines the maximum volume of text an OpenAI model can process in its prompt and generate in...
More on this subject: AI Agents: General Guides (172 guides)
Why the Bandwidth Quota Trap Causes Pipeline Failures
The primary operational risk with Git LFS is not storage capacity, but the asymmetric billing model governing download bandwidth. Pushing files to Git LFS consumes storage, but zero bandwidth. Bandwidth meters exclusively on outbound downloads, including local clones, branch checkouts, release archive downloads, and automated CI/CD test runs.
This asymmetry creates a common failure pattern for engineering teams. A developer tracks a heavy model weight or archive file using git lfs track "*.bin" and pushes it to a repository. That initial push consumes storage quota, while outbound bandwidth remains at zero.
Bandwidth consumption accelerates as soon as other systems interact with that commit:
- Multiple team members pull the branch to review changes, consuming download bandwidth on each local workstation.
- Continuous integration workflows trigger on every push and pull request, pulling repository assets repeatedly across ephemeral runner virtual machines.
- Within days, repeated downloads of large assets rapidly exhaust the included monthly download bandwidth allowance on standard accounts.
When an account reaches its bandwidth limit without a payment method on file, or with a spending budget set to zero, GitHub disables Git LFS downloads on the entire account until the first day of the next calendar month.
The operational consequences of disabled Git LFS are immediate and disruptive:
Downloading models/checkpoint.bin (Smudge error)
Client error: https://github-cloud.githubusercontent.com/...
Status: 402 Payment Required
error: external filter git-lfs filter-process failed
fatal: models/checkpoint.bin: smudge filter lfs failed
When this occurs, automated deployment pipelines halt. Developers who clone the repository receive only the lightweight text pointer files rather than real binaries. Applications, compilers, or test suites expecting valid binary files crash with parse errors or missing dependency flags.
Repository forks introduce another subtle trap. All bandwidth and storage consumed by a repository counts against the root repository owner, not the account that initiated the fork or download. If an open-source project or shared team template incorporates large LFS assets, forks created by external contributors continue drawing down the parent repository owner allowance. A spike in community forks can exhaust an organization monthly quota without any internal team activity.
How to Monitor and Reduce Git LFS Quotas
Preventing bandwidth lockouts and controlling storage expenses requires active monitoring of LFS objects, caching within automated pipelines, and pruning unneeded historical pointers.
Start by inspecting which files in your working directory consume LFS capacity. Run git lfs ls-files with the size flag to list every tracked file and its size:
git lfs ls-files --size
To audit repository health across Git history, use the open-source git-sizer utility. It calculates the total count of LFS pointers, maximum object size, and the percentage of your repository composed of binary data.
Local workstations accumulate cached LFS objects from past checkouts. Free disk space on development machines by executing a prune operation:
git lfs prune --dry-run
git lfs prune
To protect monthly download bandwidth in CI/CD environments, avoid downloading LFS assets on every build. Configure Git to skip the smudge filter during initial clone, then fetch only the specific files required for the test job:
GIT_LFS_SKIP_SMUDGE=1 git clone git@github.com:org/repo.git
cd repo
git lfs pull --include="models/production-weights.bin"
In GitHub Actions, use actions/cache to preserve downloaded LFS objects between workflow runs. Key the cache against the hash of .gitattributes and your LFS pointer files so that runners fetch assets from internal runner storage rather than drawing down your account metered Git LFS bandwidth.
- name: Cache Git LFS Objects
  uses: actions/cache@v4
  with:
    path: .git/lfs/objects
    key: ${{ runner.os }}-lfs-${{ hashFiles('.gitattributes') }}
    restore-keys: |
      ${{ runner.os }}-lfs-

- name: Pull LFS Assets
  run: git lfs pull
When someone accidentally commits a large binary to Git LFS, deleting the file in a new commit does not reduce storage usage for that billing cycle. GitHub Docs note that storage usage for the current calendar month is not recalculated when objects are removed partway through the month; the total resets on the first of the following month.
To excise accidental binaries completely from history, rewrite the commits using git filter-repo:
git filter-repo --invert-paths --path path/to/accidental-data.zip


Bypass Git LFS Limits with Dedicated Workspace Storage
Move large datasets, model weights, and media files beyond Git LFS limits into intelligent workspaces with per-file version history and native MCP access. Every organization starts with a 14-day free trial, which requires a credit card.
Architectural Workarounds for Datasets, Binaries, and AI Models
While Git LFS solves the problem of keeping large binaries out of standard Git tree diffs, it remains an awkward fit for modern AI workflows, machine learning datasets, raw media catalogs, and agent workspaces.
The core limitation lies in versioning mechanics. Git LFS does not support binary diffing. If a developer or automated agent makes a small modification to a large database file or embedding checkpoint, Git LFS treats the entire revision as a separate binary object. Pushing that update uploads a complete new file rather than a differential patch. Iterating on a model checkpoint across several training runs quickly multiplies total storage consumption, even when nearly all underlying bytes remain identical.
Engineering teams bypass these limitations using two primary architectural alternatives.
Option 1: Cloud Object Storage (Amazon S3, Google Cloud Storage, Cloudflare R2)
The standard infrastructure approach moves binaries out of Git entirely and hosts them in object storage buckets. Code repositories store a lightweight manifest file containing object keys, hashes, and download scripts.
Object storage provides high durability, unmetered ingress, and flexible storage classes. However, it introduces operational overhead. Engineering teams must build custom authorization wrappers, maintain sync scripts, configure CORS headers, and manage lifecycle rules.
Object storage buckets also lack an accessible collaborative interface for non-technical stakeholders and provide no native semantic understanding of document contents. If an autonomous agent needs to inspect a document inside a raw bucket, it must download the entire object, run local parsing, and extract the needed text.
Option 2: Intelligent Cloud Workspaces (Fast.io)
For teams coordinating autonomous agents, engineers, and clients around shared data, intelligent cloud workspaces provide a collaborative storage layer that operates alongside code repositories. Explore Fast.io workspaces to see how team collaboration and versioned storage function together.
Fast.io decouples multi-gigabyte assets from Git repositories while keeping them accessible to both humans and automated agents. Rather than pushing heavy files through Git LFS, assets reside in shared, organization-owned workspaces equipped with per-file version history, granular access permissions (organization, workspace, folder, and file level), and an append-only audit log. For teams building autonomous AI workflows, storage for agents provides dedicated persistence for agent reads and writes.
Key advantages for data-intensive and agentic workflows include:
- Native MCP Connectivity: Autonomous agents built on Claude Code, Cursor, Codex, or custom frameworks connect to Fast.io workspaces via the Model Context Protocol (MCP). The remote MCP server operates over Streamable HTTP: coding agents such as Claude Code and Cursor connect at
https://mcp.fast.io/mcp/code, Codex connects through the Fastio plugin or its custom MCP server athttps://mcp.fast.io/mcp/operations, and custom frameworks connect athttps://mcp.fast.io/mcp/tools. Interactive clients sign in with OAuth in the browser, while headless code sends anAuthorization: Bearer <api key>header on the connection. Agents read, write, and organize files directly without consuming Git bandwidth. Detailed tool interfaces are documented in the Fast.io documentation. - Built-in Intelligence and Hybrid Search: When Intelligence Mode is enabled on a workspace, files are indexed automatically upon arrival. Agents query documents using hybrid search (full-text, semantic similarity, and metadata values) and retrieve answers backed by citations, eliminating the need to maintain an external vector database.
- Document Data Extraction: Fast.io Metadata Views turn unstructured documents into typed databases (supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date schemas) across PDFs, images, and spreadsheets without manual OCR templates.
- Frictionless Collaboration: External stakeholders and clients can access deliverables through branded share links (Send, Receive, and Exchange) that include expiry controls and download restrictions. External guests open shares without consuming team seats.
Fast.io plans include a fixed storage allowance, and bandwidth is billed by use. Review the current Fast.io pricing options for organization tiers:
Every organization starts with a 14-day free trial, which requires a credit card. Credits meter AI operations, and accounts can add additional credit blocks whenever automated workflows scale up.
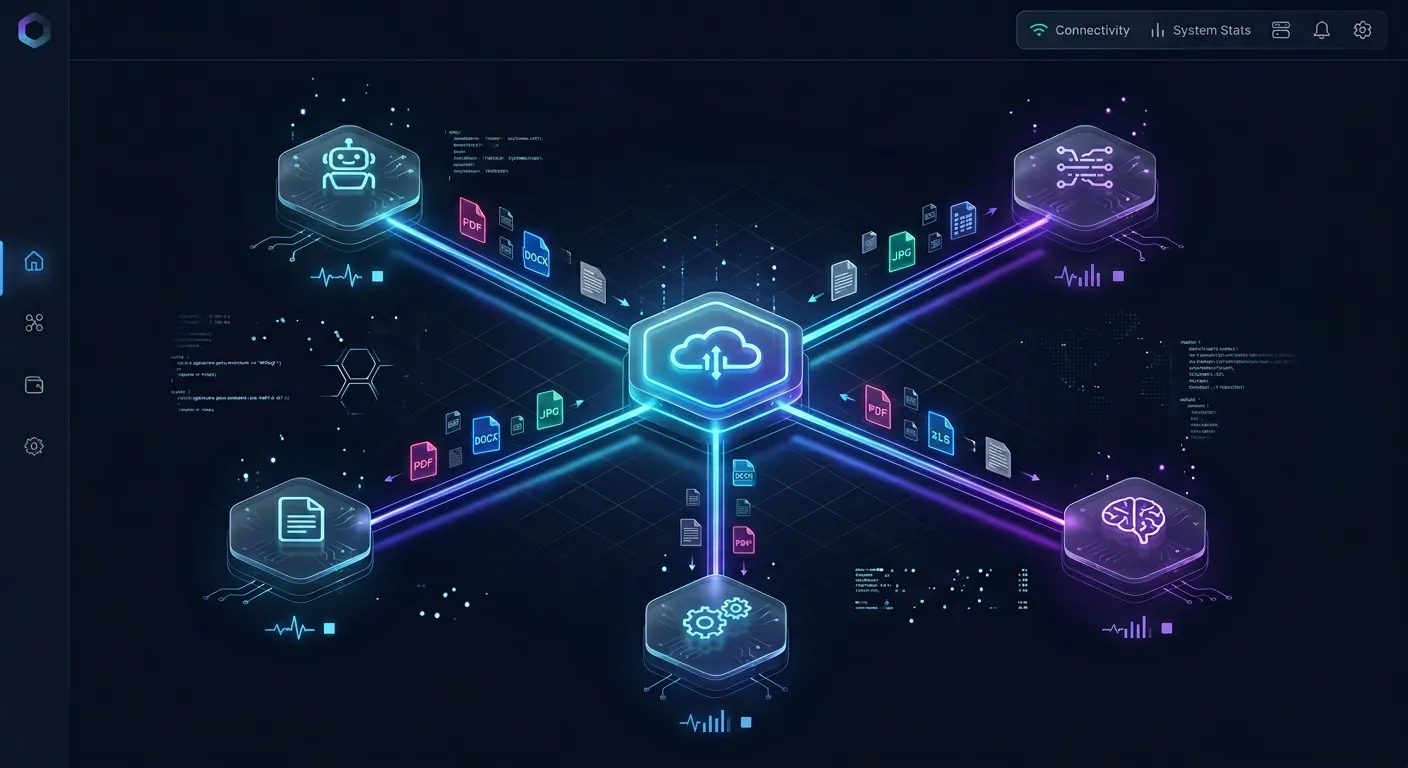
When to Decouple Code Repositories from Asset Storage
Decoupling software source code from binary assets improves developer velocity and isolates infrastructure from unexpected bandwidth overages.
To implement a clean separation of concerns, establish explicit rules for what belongs in Git versus dedicated workspace storage:
- Keep in Git: Source code, test scripts, infrastructure-as-code manifests, schema definitions, documentation, and configuration files.
- Move to Workspace Storage: Machine learning checkpoints, audio and video production files, training datasets, database dumps, PDF document archives, and compiled application binaries.
Implement this pattern in practice by referencing external assets within your code through deterministic configuration files. For example, store a lightweight JSON manifest in your Git repository specifying file hashes, version tags, and retrieval endpoints:
{
  "model_version": "v2.4.1",
  "assets": [
    {
      "name": "classifier_weights.bin",
      "sha256": "4cac19622fc3ada9c0fdeadb33f88f367b541f38b89102a3f1261ac81fd5bcb5",
      "workspace_path": "models/production/classifier_weights.bin"
    }
  ]
}
When an automated agent or CI pipeline requires the binary, it requests the file programmatically through the Fast.io API or MCP storage tools:
{
  "jsonrpc": "2.0",
  "method": "tools/call",
  "params": {
    "name": "storage",
    "arguments": {
      "action": "read",
      "path": "models/production/classifier_weights.bin"
    }
  },
  "id": 1
}
This separation produces tangible operational benefits:
- Sub-second Clones: New engineers and automated CI runners clone the code repository in seconds rather than waiting for gigabytes of Git LFS assets to transfer over the network.
- Predictable CI Costs: Automated test suites running hundreds of pull requests per week never risk disabling account-wide Git access due to exhausted LFS download bandwidth.
- Independent Asset Lifecycles: Large datasets and models can be revised, rolled back via per-file version history, and inspected by AI agents without generating commits that bloat the Git tree.
- Granular Access Control: Team members who need access to source code can work freely without requiring access to sensitive production training data, and vice versa.
Sources
References used to verify factual claims in this guide.
-
GitHub limits individual Git LFS files to 2 GB on Free and Pro accounts, 4 GB on Team, and 5 GB on Enterprise Cloud.
-
Exceeding monthly Git LFS download bandwidth without a payment method on file disables Git LFS support on the account until the next billing cycle.
Frequently Asked Questions
What is the file size limit for Git LFS on GitHub?
The maximum file size for Git LFS on GitHub depends on your plan: 2 GB for GitHub Free and Pro, 4 GB for GitHub Team, and 5 GB for GitHub Enterprise Cloud. Files exceeding the 5 GB ceiling for GitHub Enterprise Cloud cannot be tracked with Git LFS and will be rejected during push.
How much bandwidth do you get with Git LFS?
GitHub Free, GitHub Pro, and GitHub Free for Organizations include 10 GiB of monthly download bandwidth. GitHub Team and GitHub Enterprise Cloud include 250 GiB of monthly bandwidth. Bandwidth meters exclusively on downloads such as clones, pulls, and archive exports; uploading files does not consume bandwidth.
What happens when you exceed Git LFS bandwidth quotas?
If an account exhausts its monthly Git LFS bandwidth quota without a billing payment method on file, GitHub disables Git LFS downloads across the account until the next calendar month. CI/CD runs fail with smudge filter errors, and developers can only pull pointer files instead of actual binaries.
Why does pulling from a repository fork count against the parent repository?
GitHub attributes all Git LFS storage and download bandwidth to the root repository owner. When an external collaborator forks a repository and clones or pulls LFS assets from that fork, the bandwidth used is deducted from the parent repository owner allowance.
How can developers prevent CI/CD workflows from exhausting Git LFS bandwidth?
Developers can prevent bandwidth exhaustion by cloning with GIT_LFS_SKIP_SMUDGE=1 to skip automatic binary downloads, pulling only required files on demand, and using actions/cache in GitHub Actions to cache downloaded LFS objects between workflow runs.
Related Resources

Bypass Git LFS Limits with Dedicated Workspace Storage
Move large datasets, model weights, and media files beyond Git LFS limits into intelligent workspaces with per-file version history and native MCP access. Every organization starts with a 14-day free trial, which requires a credit card.