How to Connect Dify AI to Microsoft SharePoint
Connecting Dify to SharePoint enables agentic workflows and LLM applications to retrieve, cite, and analyze enterprise documents stored across Microsoft 365 libraries. Direct Microsoft Graph ingestion triggers API rate limits, complex Entra ID permissions, and memory pressure during recursive folder crawls. Synchronizing SharePoint libraries into an intelligent Fast.io workspace allows Dify agents to execute hybrid search over pre-indexed files via remote Model Context Protocol (MCP) tools.

How Dify AI Workflows Retrieve Enterprise Knowledge from SharePoint
Pointing an autonomous AI workflow directly at an unindexed enterprise SharePoint document library turns what should be an immediate factual retrieval into a fragile sequence of directory crawls and API throttling. When Dify agents and Chatflows query raw Microsoft 365 storage, they cannot search across document contents in a single step; they must recursively resolve site identifiers, enumerate drive items, download raw file binaries across the network, and exhaust context tokens on boilerplate text.
Dify is an open-source development platform for building LLM applications, offering visual workflow composition, multi-agent orchestration, prompt engineering, and integrated retrieval-augmented generation (RAG). Enterprise teams use Dify to deploy customer-facing support bots, internal research assistants, compliance audit workflows, and automated document analysis pipelines. In these corporate environments, Microsoft SharePoint functions as the central knowledge archive, storing vendor contracts, technical architecture reviews, standard operating procedures, executive briefings, and financial records.
Connecting Dify to SharePoint enables agentic workflows and LLM applications to retrieve, cite, and analyze enterprise documents stored across Microsoft 365 libraries. However, bridging unstructured SharePoint document libraries with Dify LLM context windows presents an architectural challenge. When developers need to connect Dify to SharePoint, they typically encounter two distinct integration paths: direct ingestion via Microsoft Graph API plugins and custom ETL scripts, or synchronized workspace retrieval via Fast.io and remote Model Context Protocol (MCP) tooling.
The conventional direct integration path involves installing Dify marketplace plugins such as the langgenius/sharepoint_datasource plugin or 4cos90/sharepointtool, or writing custom Microsoft Graph API ingestion scripts. In this model, developers register an Azure Entra ID application, request delegated or application permissions, discover tenant and site GUIDs, and schedule periodic ingestion runs that download files into Dify datasets. Once loaded into Dify, the platform chunks document text, generates vector embeddings, and stores records in an internal vector database.
While this direct architecture functions for small folders containing a handful of plain text documents, enterprise document libraries containing hundreds of multi-page PDFs, spreadsheets, and scanned records quickly trigger rate limits, memory spikes, and ingestion failures. Developers seeking a resilient storage substrate can explore Fast.io storage for agents to examine how intelligent workspaces support autonomous pipelines without unindexed crawling.
Related guides
- How to Connect Langflow AI Agents to Microsoft SharePointA Langflow SharePoint integration connects visual AI agents to Microsoft SharePoint document libraries, enabling...
- How to Connect ChatGPT to SharePoint Document LibrariesConnecting ChatGPT to SharePoint allows conversational AI models to query enterprise document libraries through...
- How to Integrate Flowise with Microsoft SharePointA Flowise SharePoint integration connects Flowise visual canvas nodes to SharePoint document libraries, enabling...
- How to Connect n8n Workflow Agents to SharePoint FilesAn n8n SharePoint integration links workflow automation pipelines and AI agent nodes with Microsoft SharePoint document...
- Connecting AutoGen Multi-Agent Systems to SharePoint: Architecture and SetupAn AutoGen SharePoint connector enables Microsoft AutoGen agent teams to authenticate against Microsoft Graph and query...
- LangChain SharePoint Integration: How to Query Enterprise DocumentsA LangChain SharePoint integration connects autonomous agents and retrieval chains to Microsoft SharePoint libraries,...
More on this subject: Agent File and Document Workflows (218 guides)
Why Direct Microsoft Graph Traversal Triggers Throttling and Ingestion Bottlenecks
Deploying direct SharePoint connectors into production Dify pipelines reveals immediate infrastructure constraints. When automated agents or scheduled RAG dataset jobs query Microsoft Graph directly, they encounter rate throttling, network transfer latency, and file extraction failures.
Microsoft Graph API Throttling and HTTP 429 Responses
SharePoint Online enforces strict request boundaries to protect multi-tenant cloud infrastructure. According to official documentation from Microsoft Learn on SharePoint Online throttling, the service will throttle delegated user requests that exceed 10 requests per second per user. Application-level background processes share tenant-level resource pools that throttle traffic when concurrent queries surge across corporate departments.
When an application exceeds rate thresholds, Microsoft Graph endpoints return an HTTP 429 Too Many Requests response with a Retry-After header specifying the mandatory backoff delay in seconds. In a Dify pipeline attempting to ingest or update a document dataset, recursive directory polling and parallel file downloads rapidly cross these boundaries. Without complex distributed backoff logic, automated ingestion jobs fail mid-run. Even with retries, backoff delays stretch sync jobs from minutes into hours, leaving Dify knowledge bases stale. Competitor tutorials require writing custom Microsoft Graph API ETL scripts or manual file uploads into Dify datasets rather than maintaining a scheduled workspace sync connection.
Recursive Directory Enumeration and Memory Overhead
Microsoft Graph models SharePoint libraries as drive item hierarchies identified by complex GUIDs rather than static filesystem paths. Querying /sites/{site-id}/drives/{drive-id}/root/children returns only immediate child items. If an enterprise repository nests project folders three or four levels deep, an ingestion script or plugin must execute recursive HTTP calls: discovering subfolder IDs, requesting children for each subfolder, and repeating down the tree. In a repository containing hundreds of files distributed across dozens of subfolders, directory discovery alone consumes repetitive round trips before a single byte of file content is downloaded.
Furthermore, standard loaders download full file binaries over HTTP to the host machine before performing text extraction. When Dify runs inside containerized environments like Docker or Kubernetes pods, buffering multiple large PDFs or dense spreadsheets concurrently causes out-of-memory container crashes. Network overhead also introduces substantial latency, slowing down scheduled indexing jobs.
Scanned Records and Silent Extraction Failures
Enterprise SharePoint repositories regularly contain scanned PDF contracts, signed agreements, paper invoices, and presentation decks lacking embedded digital text layers. Standard PDF parsing engines extract only digital character streams. When encountering an image-only scanned document, these parsers extract empty strings without raising an error. The document loader silently ingests blank records into the Dify dataset. When users ask questions about those files, the agent finds zero matches and either hallucinates or falsely claims the document does not exist, unless engineers maintain a separate OCR infrastructure.
Permission Scope Governance in Enterprise Tenants
Configuring direct Graph API access requires administrative intervention in Microsoft Entra ID. Security teams routinely reject requests for broad scopes like Files.Read.All or Sites.Read.All, which expose every file and document library across the entire corporate tenant to the AI application. Scoping access via Sites.Selected restricts permissions but requires administrators to run PowerShell scripts or custom Graph API calls, introducing weeks of administrative friction. Additionally, enterprise client secrets routinely expire on scheduled security rotations; an unrotated secret immediately breaks all downstream Dify agents.
The operational differences between direct Microsoft Graph traversal and indexed workspace search explain why native connectors struggle during enterprise operations:
Retrieval Model: Direct connectors download full file binaries on demand, whereas indexed workspaces return exact semantic passages matching the query.
Tool Call Volume: Traversing raw directories requires recursive calls to enumerate folders and download files, while indexed search resolves queries in a single retrieval operation.
Token Consumption: Unindexed file downloads inject entire document bodies into prompt context, whereas chunked semantic retrieval injects only relevant paragraphs and page citations.
Rate Limit Immunity: Frequent directory polling triggers Microsoft Graph throttling, whereas querying an indexed workspace bypasses repetitive calls to the underlying storage provider.
Direct Storage Traversal Compared With Fast.io Indexed Workspaces
To eliminate the latency, throttling, and administrative overhead of direct Graph API polling, enterprise teams decouple document storage from AI retrieval. Rather than migrating away from SharePoint or forcing corporate users into a new system, the organization keeps SharePoint as its primary corporate document repository. Selected SharePoint document libraries synchronize into an intelligent Fast.io workspace through the OneDrive connector, which is how Fast.io reaches SharePoint libraries.
Fast.io provides folder synchronization for Box, Dropbox, and OneDrive, while Google Drive supports one-time cloud import today with folder sync coming soon on the product roadmap; synchronization is never real-time, operating on predictable background schedules. Synchronization runs one-way or two-way, on a recurring schedule or on demand. For Dify agent workflows, engineering teams configure a scheduled one-way read-only sync from SharePoint to Fast.io. This setup guarantees that agents can read and analyze enterprise files without modifying or deleting original corporate records.
Once files land in the workspace, Fast.io's Intelligence Mode automatically parses and indexes content. Universal document parsing extracts text from PDFs, Word files, spreadsheets, presentations, and scanned pages with automated OCR, ensuring complete retrieval coverage. Hybrid search combines exact keyword matching with semantic vector retrieval.
For structured documents such as vendor invoices, master service agreements, and statements of work, teams configure Metadata Views. Metadata Views turn unstructured document repositories into a live, queryable database. Users describe target extraction fields in plain language, such as contract counterparty, effective date, renewal term, or payment amount. Fast.io designs a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time formats. AI extracts matching values automatically without manual templates or OCR rules. Dify agents can filter Metadata Views over MCP before retrieving specific document passages.
The performance difference between direct cloud storage polling and indexed workspace search is measurable rather than theoretical. Fast.io publishes a head to head benchmark of agent file work that runs one agent through the same multi-document audit over an identical corpus held in Fast.io and in each of the major cloud storage providers, recording completion time, tool calls, token consumption and cost per task. Fast.io completed the audit fastest and at the lowest cost of the storage layers tested. SharePoint is not a separate entry in that comparison, since its document libraries are reached through the OneDrive connector.
Syncing SharePoint to Fast.io workspaces provides indexed search without manual Graph API chunking or heavy batch ingestion. When documents land in a Fast.io workspace, Intelligence Mode automatically indexes their contents using hybrid search. Hybrid search combines exact full-text keyword matching, semantic vector retrieval, and structured metadata value filters. Instead of downloading whole files sequentially to locate terms, Dify agents query the workspace index through a remote Model Context Protocol (MCP) server. Fast.io returns exact text chunks with page-level citations, allowing the model to answer accurately with lower token overhead and reduced storage query latency.



Connect SharePoint to Dify with Pre-Indexed Workspaces
Synchronize enterprise SharePoint libraries to an intelligent workspace, query indexed documents through Fast.io MCP, and eliminate Graph API throttling. Every organization starts with a 14-day free trial, which requires a credit card.
Connecting SharePoint to Dify via Fast.io MCP in Four Steps
Connecting SharePoint document libraries to Dify workflows and autonomous agents through Fast.io follows four configuration steps:
- Isolate the target SharePoint document library
- Sync SharePoint folders into a Fast.io workspace
- Configure Intelligence Mode and Metadata Views
- Connect the remote Fast.io MCP server to Dify
1. Isolate the Target SharePoint Document Library
Begin by identifying the specific SharePoint document library containing the records your Dify workflow needs to access. Rather than exposing your entire Microsoft 365 tenant, define a clear perimeter, such as a client matter directory, policy repository, or technical documentation library. Restricting the agent to a designated folder enforces corporate data governance and prevents unrelated personal or financial records from entering the retrieval scope.
Organizing target documents into a dedicated library simplifies permission management in SharePoint. Team members can continue modifying and adding files to that library in their normal day-to-day workflow, knowing that designated business documents will synchronize to the agent workspace.
2. Sync SharePoint Folders into a Fast.io Workspace
Log into your Fast.io account and create a dedicated workspace for your project. From the workspace dashboard, establish folder synchronization with SharePoint:
Choose Microsoft OneDrive and SharePoint as the source provider, then authenticate your Microsoft 365 account through the standard OAuth prompt.
Select the target SharePoint site collection and designated document library.
Configure synchronization frequency and direction. For agent query workloads, select scheduled one-way synchronization from SharePoint to Fast.io.
Folders from Box, Dropbox, and OneDrive can be synchronized with an intelligent workspace. Synchronization runs one-way or two-way, on a recurring schedule or on demand. Google Drive files can be imported today, with sync coming soon on the product roadmap. Synchronization is never real-time, operating on predictable background schedules. Server-to-server synchronization transfers data directly between cloud infrastructures without consuming local bandwidth or requiring local disk storage.
3. Configure Intelligence Mode and Metadata Views
After documents arrive in the workspace, verify that Intelligence Mode is active. Intelligence Mode automatically parses PDFs, presentations, spreadsheets, Word files, and scanned documents, generating vector embeddings and keyword indexes for hybrid search.
For teams managing structured documents like vendor invoices, service agreements, or purchase orders, configure Metadata Views. Metadata Views turn unstructured document collections into a live, queryable database. Users describe target fields in plain English, such as contract effective dates, renewal terms, governing law, or payment milestones. Fast.io designs a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time formats. AI automatically extracts matching values from PDFs, images, and spreadsheets without rigid templates or manual OCR rules.
Dify agents can query structured Metadata Views directly through MCP tools, enabling an agent to filter for contracts expiring within upcoming quarters before retrieving full text passages.
4. Connect the Remote Fast.io MCP Server to Dify
Dify provides native support for external Model Context Protocol (MCP) servers operating over HTTP transports. Fast.io hosts a remote MCP server over Streamable HTTP at https://mcp.fast.io/mcp and https://mcp.fast.io/mcp/key when authenticating via an API key header, alongside a legacy SSE transport at https://mcp.fast.io/sse. You can review integration architecture on the storage for agents page.
To connect Fast.io to Dify:
Navigate to your Dify workspace and open the Tools section.
Select MCP from the tools menu and click Add MCP Server (HTTP).
Enter a descriptive server name, such as
Fastio SharePoint Connector.Set the server URL to
https://mcp.fast.io/mcp/key.Under headers, add an
Authorizationheader containing your Fast.io API key:
{
  "mcpServers": {
    "fastio": {
      "url": "https://mcp.fast.io/mcp/key",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Generate your API key within the Fast.io console under Developer Settings. Keys inherit granular workspace permissions, guaranteeing that Dify agents can access only the specific workspaces assigned to that credential.
Once connected, Dify automatically discovers Fast.io's consolidated MCP toolset. You can add Fast.io tool nodes directly into your Dify visual workflows and agent nodes, allowing agents to execute hybrid searches, retrieve citations, read files, and write outputs back to the workspace.
In a Dify Chatflow or Workflow canvas, developers can route user queries through an LLM node that decides when to call Fast.io search tools. The tool node passes the query to Fast.io and receives relevant passages with exact document names and page numbers. The agent then formats citations into its final output, providing transparent source attribution to the end user.
Developers managing environments from the command line can use the official command-line package @vividengine/fastio-cli. If your agent pipeline interacts directly with REST endpoints, the base path is https://api.fast.io/current/. To execute searches programmatically, agents query GET /current/workspace/{workspace_id}/storage/search/. To monitor file additions and team updates, agents query the realtime activity feed via GET /current/activity/poll/{entity_id} or connect to the WebSocket events stream, providing reactive coordination without repetitive storage polling.
Enterprise Governance, Access Control, and Multi-Agent Coordination
Deploying autonomous Dify agents over corporate document repositories requires reliable operational governance. Uncontrolled agents can misinterpret outdated contract drafts, overwrite active project files, or read sensitive employee records. Fast.io provides enterprise governance controls designed specifically for human-agent collaboration over synced SharePoint content.
Immutable Audit Logging for Agent Operations
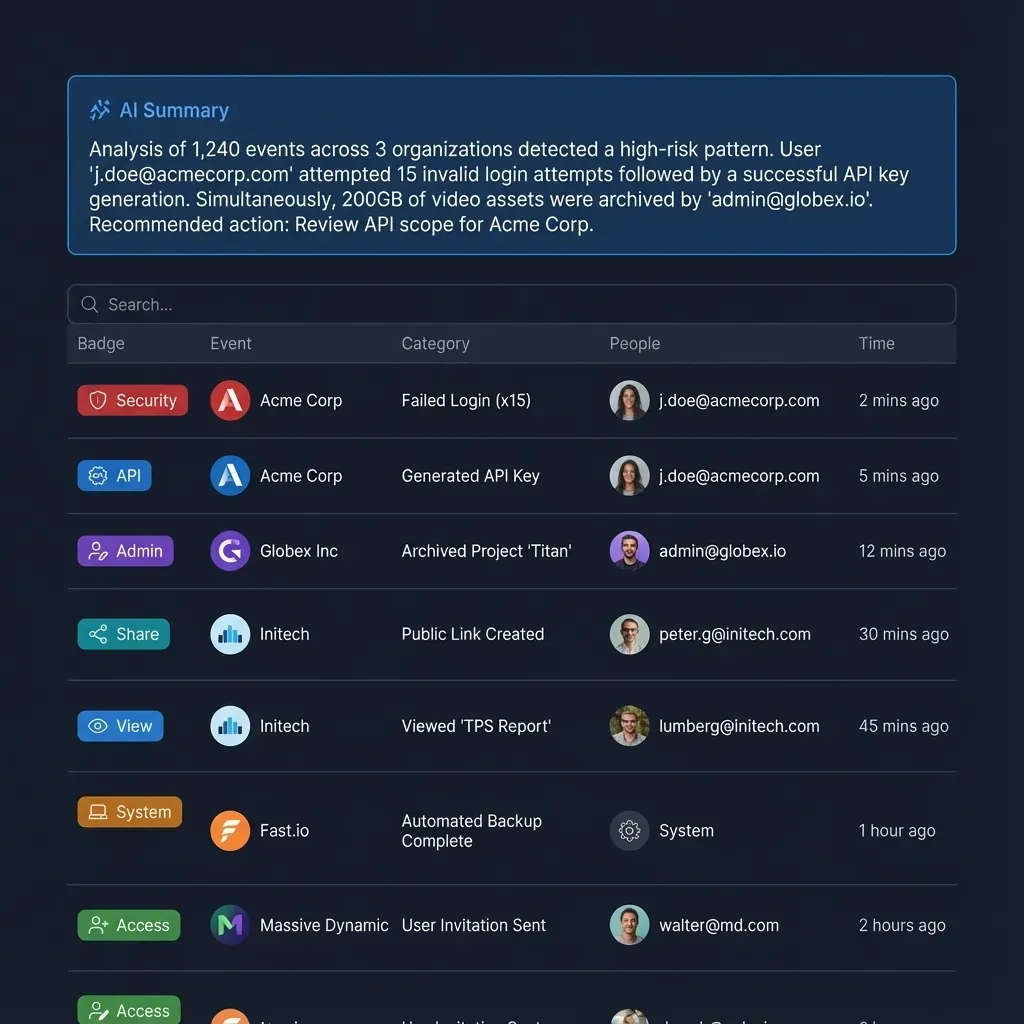
Every workspace interaction is recorded in an append-only audit log. When a Dify agent searches an indexed SharePoint folder, queries a contract term, or reads an invoice table, Fast.io logs the actor identity, action type, and exact timestamp. This immutable log gives engineering leads and operations managers complete visibility into which models accessed specific customer records, satisfying internal oversight requirements.
Granular Permissions and Scoped Access
Fast.io enforces multi-tier access permissions across organizations, workspaces, folders, and individual files. You can grant a Dify agent API credential read-only access to a synced SharePoint customer archive while allowing human colleagues full editing rights. Scoped permissions guarantee that models cannot wander outside their designated project folder or leak sensitive records across teams.
If multiple agents participate in a single workflow, each agent can operate under distinct credentials. For example, a research agent in Dify can hold read-only access to the synced SharePoint repository, while a reporting agent holds write access restricted to a separate outputs directory.
Per-File Version History and Accidental Overwrite Protection
When autonomous agents and human editors collaborate within the same workspace, concurrent edits risk overwriting valuable information. Fast.io maintains complete per-file version history for every document. If an agent modifies a shared document or outputs an inaccurate analytical summary, team members can review previous versions and restore prior content with a single click. Collaborative Notes provide a shared environment where humans and agents co-edit content simultaneously with full attribution.
Transferring Workspace Ownership to Human Stakeholders
Fast.io supports ownership transfer from agents to human administrators. An autonomous agent can programmatically set up an organization, create dedicated workspaces, sync SharePoint folders, and generate structured Metadata Views. Once the initial workspace configuration is complete, the agent transfers organization ownership to a human team member via a secure claim link. The human assumes administrative and billing ownership, while the agent retains operational access to perform scheduled queries and data extraction.
Transparent Pricing and Subscription Tiers
Getting started with Fast.io is straightforward. Creating an account is free; doing real work requires an organization on a paid subscription. Plans are structured into clear tiers: Starter at $9.99/mo, Business at $49.99/mo, and Enterprise at $199.99/mo. Every organization starts with a 14-day free trial, which requires a credit card.
Workspace subscriptions include team seats and storage capacity, along with a monthly credit allowance that meters AI operations. Learn more about deployment architecture on the storage for agents page and examine plan details on the pricing page. By combining SharePoint's familiar storage ecosystem with Fast.io's indexed workspaces, teams give their Dify AI agents fast, accurate, and governed access to corporate documents.
Sources
References used to verify factual claims in this guide.
-
SharePoint Online throttles delegated user requests that exceed 10 requests per second per user.
Frequently Asked Questions
How do I connect Dify to Microsoft SharePoint?
You can connect Dify to SharePoint by synchronizing SharePoint document libraries into a Fast.io workspace and attaching Fast.io's remote Model Context Protocol (MCP) server to Dify. In Dify's Tools section, add an HTTP MCP server pointing to `https://mcp.fast.io/mcp/key` with your Fast.io API key in the Authorization header. Dify agents can then query indexed SharePoint files via hybrid search in a single tool call.
Can Dify query SharePoint document libraries directly?
Dify can query SharePoint libraries directly using marketplace plugins such as `langgenius/sharepoint_datasource` or custom Microsoft Graph API scripts. However, direct Graph traversal requires complex Microsoft Entra ID permissions, triggers HTTP 429 throttling during directory crawls, and downloads full file binaries into memory. Decoupling storage by syncing SharePoint to an indexed Fast.io workspace eliminates these operational bottlenecks.
How do I keep Dify knowledge bases in sync with SharePoint files?
You can keep Dify in sync by scheduling background folder synchronization from SharePoint to a Fast.io workspace. Fast.io syncs folders on a recurring schedule or on demand without continuous API polling. When files update in SharePoint, Fast.io automatically indexes the new versions, making them immediately searchable to Dify agents via remote MCP without re-embedding entire datasets.
What are Microsoft SharePoint's API throttling thresholds?
SharePoint Online throttles delegated user requests that exceed 10 requests per second per user to protect multi-tenant infrastructure. Exceeding this limit returns an HTTP 429 Too Many Requests response with a `Retry-After` header. In automated AI pipelines, traversing nested directories and downloading file streams quickly triggers throttling delays that disrupt execution.
Does Fast.io sync SharePoint document libraries in real time?
No, synchronization is never real-time. Fast.io synchronizes folders from Box, Dropbox, and OneDrive on a recurring background schedule or on demand, while Google Drive supports one-time cloud import today with folder sync coming soon on the product roadmap. Background synchronization ensures predictable system performance without continuous API polling.
Can Dify workflows search scanned PDF documents stored in SharePoint?
Yes, when connected through an indexed Fast.io workspace. While direct document loaders often fail to extract text from scanned PDFs lacking embedded text layers, Fast.io's Intelligence Mode automatically runs optical character recognition (OCR) during ingestion. This ensures scanned agreements, signed PDFs, and image records are fully indexed and searchable by Dify agents.
Related Resources

Connect SharePoint to Dify with Pre-Indexed Workspaces
Synchronize enterprise SharePoint libraries to an intelligent workspace, query indexed documents through Fast.io MCP, and eliminate Graph API throttling. Every organization starts with a 14-day free trial, which requires a credit card.