Dropbox Search API Guide: How to Search Files Programmatically
The Dropbox Search API v2 allows developers to search files programmatically using scoped queries, extension filters, and continuation cursors. Querying files through raw REST endpoints introduces rate limit and pagination challenges, especially for autonomous agents. This guide covers search_v2 implementation, filtering techniques, error recovery, and modern workspace indexing workflows.

How the Dropbox Search API Architecture Operates
A background script polling a file repository can trigger an HTTP 429 Too Many Requests response before completing its first full sweep, stalling downstream automation. The failure stems from treating interactive cloud storage endpoints like a local filesystem or a dedicated database index, ignoring request throttling and pagination mechanics.
The Dropbox Search API is a v2 REST endpoint that allows applications to execute scoped keyword queries, file extension filtering, and metadata lookups across Dropbox accounts and team spaces. Unlike basic directory listing routes that return every item sequentially, the search endpoint inspects file names and, for team accounts with content indexing enabled, the text inside common document formats.
The primary endpoint for search operations is https://api.dropboxapi.com/2/files/search_v2. This is an RPC-style POST route where request parameters pass inside a JSON body rather than URL query parameters. Calls require an OAuth 2 bearer token passed in the standard Authorization header, and your Dropbox application must have the files.metadata.read permission scope granted.
Dropbox previously supported a v1 search route (/2/files/search), which has been superseded by files/search_v2. The v2 endpoint unifies filename matching, file extension constraints, directory boundaries, and status filters into a single structured options object, while returning modern pagination cursors that handle large result sets reliably.
curl -X POST https://api.dropboxapi.com/2/files/search_v2 \
  -H "Authorization: Bearer <your_dropbox_access_token>" \
  -H "Content-Type: application/json" \
  -d '{
    "query": "quarterly financial review",
    "options": {
      "path": "/Finance/2026",
      "max_results": 20,
      "file_status": "active",
      "filename_only": false
    },
    "match_field_options": {
      "include_highlights": false
    }
  }'
The request payload relies on three core blocks:
query: The string to match. The query parameter accepts keywords, phrases, or partial search terms without requiring special operators.options: A structured configuration object that narrows the search scope. Passing"path": "/Finance/2026"restricts the query to that specific directory tree. Omitting the path causes Dropbox to search the entire connected account. Setting"filename_only": trueskips document body parsing, speeding up execution when you only need to match file labels.match_field_options: Controls whether Dropbox returns highlighted snippets showing where the query matched within metadata or body text.
The response returns a SearchV2Result object. The SearchV2Result object contains a matches list, a has_more boolean flag, and a continuation cursor string. Each entry in matches wraps a metadata payload containing the file ID, path display name, modification timestamps, and file size.
Related guides
- Google Drive Search API: Query Syntax, Limits, and Agent PipelinesThe Google Drive Search API allows applications to query file metadata and document text through the files.list...
- How to Create Folders with Dropbox API: Endpoints, Conflicts & Agent StorageCreating a folder via the Dropbox API is performed using the /files/create_folder_v2 endpoint, which accepts a...
- How to Connect Python to Dropbox: SDK Guide vs Intelligent Agent WorkspacesThe Dropbox Python API enables programmatic file manipulation using the dropbox package, but requires developers to...
- OneDrive Search API: Microsoft Graph File Search GuideThe OneDrive Search API, exposed through Microsoft Graph, enables programmatic text searching, filename matching, and...
- API Gateway Payload Limits: 10MB REST Cap, 128KB WebSocket Limit, and WorkaroundsThe Amazon API Gateway payload limit is a hard cap of 10 MB for REST and HTTP APIs and 128 KB for WebSocket APIs,...
- Can Gemini Access Google Drive? Extension Limits, Permissions, and MCP SearchGoogle Gemini connects to Google Drive through the Google Workspace extension (@Google Drive) for conversational...
More on this subject: Agent Integrations and APIs (171 guides)
How to Filter Results by Path, Extension, and Category
Searching an entire corporate Dropbox account on every query creates significant latency and consumes rate limit budget. Precise scoping ensures requests return only the files relevant to the active task.
The options object in files/search_v2 accepts several parameters designed to restrict matches:
path: Scopes the search to a specific directory path or namespace ID. Setting this to a project folder isolates queries from irrelevant archives.file_extensions: An array of file extensions without leading dots (such as["pdf", "docx", "xlsx"]). This filter functions during active file searches and eliminates the need to inspect file endings manually in application memory.file_categories: Categorical groupings defined by Dropbox, includingdocument,image,video,audio, andspreadsheet. This allows broader matching when exact file formats vary across contributors.file_status: Acceptsactiveordeleted. Active files represent current workspace assets, while searching deleted files helps audit or recovery routines locate purged versions.order_by: Controls result ranking. By default, Dropbox orders matches by relevance. Setting the order union tolast_modified_timereturns the most recently updated files first, which is critical when synchronizing changes into external pipelines.
When working with the official Python SDK (dropbox), configuring these options uses typed objects:
import dropbox
from dropbox.files import SearchOptions, SearchOrderBy, FileStatus

dbx = dropbox.Dropbox("<your_dropbox_access_token>")
search_options = SearchOptions(
    path="/Operations/Contracts",
    max_results=50,
    file_extensions=["pdf", "docx"],
    file_status=FileStatus.active,
    filename_only=False,
    order_by=SearchOrderBy.last_modified_time
)
response = dbx.files_search_v2(
    query="indemnification clause",
    options=search_options
)
for match in response.matches:
    meta = match.metadata.get_metadata()
    print(f"File: {meta.name} | Path: {meta.path_display} | Modified: {meta.server_modified}")
Content searching introduces an important platform distinction. While searching by filename works across all Dropbox account types, full-text content searching across file bodies requires a Dropbox Business or Team subscription. Furthermore, newly uploaded or modified documents do not appear in content search results instantaneously. Dropbox processes files through an asynchronous extraction pipeline, meaning a brief indexing window exists between upload completion and search discoverability. For teams exploring alternatives or complementary storage architectures, reviewing modern solutions in our /alternatives/dropbox/ guide highlights key differences in file access patterns.
Why Pagination Cursors and Rate Limits Require Defensive Retries
Large file trees frequently return more matches than fit inside a single HTTP payload. The max_results parameter caps individual responses, defaulting to 100 matches per request. When additional records exist, the API sets has_more to true and supplies a pagination cursor.
Fetching the next batch requires sending the cursor to https://api.dropboxapi.com/2/files/search/continue_v2. Unlike the initial request, search/continue_v2 does not take the query or options dictionary again; it only accepts the cursor string.
The complete search v2 pipeline (combining initial calls and continuation requests) enforces a hard limit of 10,000 total matches per query. Applications attempting to page beyond 10,000 records must partition their queries into narrower subfolders or date ranges.
import time
import dropbox
from dropbox.exceptions import ApiError, RateLimitError

def collect_all_search_matches(dbx, query_str, folder_path=None):
    matches = []
    options = dropbox.files.SearchOptions(
        path=folder_path,
        max_results=100,
        file_status=dropbox.files.FileStatus.active
    )
    cursor = None
    has_more = True
    while has_more:
        try:
            if cursor is None:
                result = dbx.files_search_v2(query=query_str, options=options)
            else:
                result = dbx.files_search_continue_v2(cursor=cursor)
            for match in result.matches:
                meta = match.metadata.get_metadata()
                matches.append({
                    "id": meta.id,
                    "name": meta.name,
                    "path": meta.path_display,
                    "size": meta.size
                })
            has_more = result.has_more
            cursor = result.cursor
        except RateLimitError as rate_err:
            backoff_seconds = getattr(rate_err, "backoff", 10)
            print(f"Rate limited by Dropbox. Waiting {backoff_seconds} seconds.")
            time.sleep(backoff_seconds)
        except ApiError as api_err:
            print(f"Dropbox API error: {api_err}")
            break
    return matches
Production systems must anticipate request throttling. Dropbox does not publish static numeric rate limits because quotas adjust dynamically based on aggregate platform load and endpoint type. Search is computationally heavier than directory listing, making it prone to throttling under high concurrency.
When rate limits are exceeded, Dropbox responds with HTTP 429 Too Many Requests or HTTP 503 Service Unavailable. The response header Retry-After specifies the exact number of seconds the client must pause before retrying. Production code should inspect this header directly. If Retry-After is omitted, the application should fall back to exponential backoff with randomized jitter to prevent thundering herd spikes against the server.


Search Dropbox Archives Directly from Agent Workspaces
Connect existing Dropbox folders into workspaces that index files automatically, providing remote MCP search without burning API rate limits. Monthly plans start with a 14-day free trial.
When to Bridge Dropbox Storage into AI Agent Workspaces
Modern software development increasingly pairs storage backends with autonomous AI agents running in tools like Claude Code, Cursor, OpenClaw, or custom LangGraph workflows. Direct integration between AI agents and the native Dropbox Search API reveals structural friction.
An autonomous agent attempting to discover files through raw API calls spends substantial context window space parsing verbose JSON payloads. When search returns tens of matches, the agent must inspect metadata, request file download links, retrieve raw text, and manage rate-limiting pauses inside its execution loop. Furthermore, the Dropbox search endpoint relies on lexical keywords; it does not perform semantic vector retrieval or natural-language concept matching across document collections.
A cleaner architecture preserves Dropbox as the team's system of record while connecting active project folders into an intelligent workspace designed for AI agents. Fast.io provides Cloud Sync for Google Drive, Dropbox, Box, and OneDrive. Cloud Sync operates one-way or two-way, running on a schedule or on demand (never continuous, live, or real-time).
When files sync from Dropbox into a Fast.io workspace, Intelligence Mode indexes the content automatically. Instead of forcing an LLM to query raw REST endpoints and paginate through metadata structures, agents connect via the Model Context Protocol (MCP). Fast.io hosts a remote MCP server accessible over Streamable HTTP at https://mcp.fast.io/mcp/tools (setup steps are detailed in the documentation), with headless code authenticating via a bearer token on the connection. Explore our /product/ai/ capabilities to see how native agent intelligence functions across persistent workspaces.
{
  "mcpServers": {
    "fastio": {
      "url": "https://mcp.fast.io/mcp/tools",
      "headers": {
        "Authorization": "Bearer <your-fastio-api-key>"
      }
    }
  }
}
Through MCP, the agent calls consolidated workspace tools. It executes hybrid search (combining full-text lexical search, semantic vector retrieval, and metadata filters) against the synced files directly:
{
  "jsonrpc": "2.0",
  "id": 1,
  "method": "tools/call",
  "params": {
    "name": "storage",
    "arguments": {
      "action": "search",
      "workspace_id": "ws_enterprise_contracts",
      "query": "confidentiality obligations upon contract termination"
    }
  }
}
The search returns concise, relevant passages with source citations. The agent retrieves the exact answer it needs without downloading entire folders or exhausting its context budget on pagination tokens. In published connector benchmarks comparing storage integrations in agent runtimes, Fastio was measured the fastest and the lowest cost of the providers tested (detailed methodology and results are published at https://fast.io/benchmarks/).
For workflows requiring structured record extraction from synced PDFs, invoices, or agreements, Metadata Views (/product/document-data-extraction/) turn files into queryable spreadsheets with typed schemas without writing custom OCR parsers. Teams managing multi-agent access can also organize projects into isolated environments via /product/workspaces/.
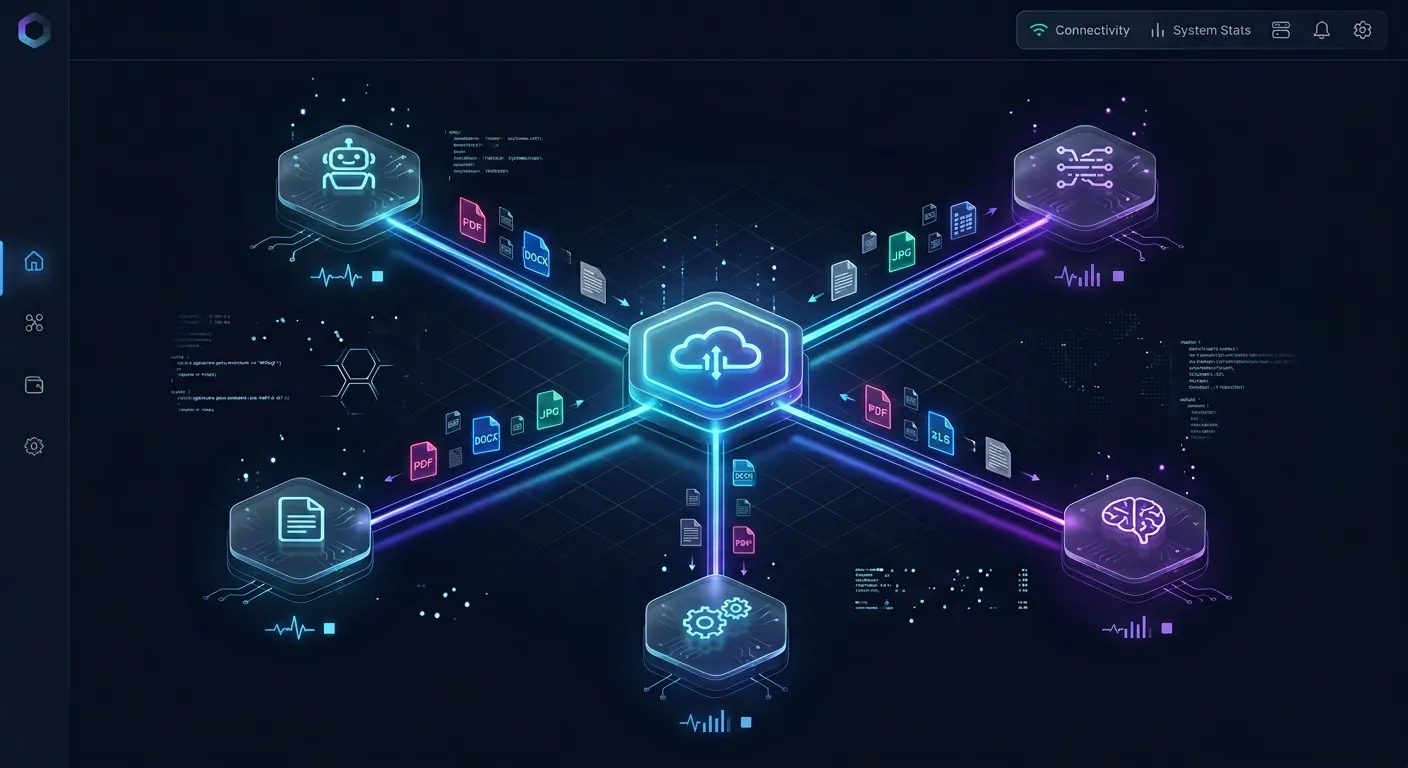
Steps for Building Resilient File Retrieval Pipelines
Connecting storage repositories to automated services requires operational rigor around security, concurrency, and change notifications. A brittle integration leads to failed runs, race conditions, or expired access tokens.
Token Lifecycle and Scoping
Avoid generating long-lived static developer tokens for production services. Implement an OAuth 2 refresh token rotation pattern. When configuring the Dropbox application in the developer console, scope permissions strictly to the minimum required: files.metadata.read for discovery or files.content.read for document retrieval. Scoping an integration to a single App Folder limits exposure compared to granting Full Dropbox account access.
Handling Concurrency and Team Collisions
When multiple agents or automated services operate on the same file collections, write collisions become a risk. While Dropbox maintains version history for overwritten files, concurrent writes can produce conflicted copies (Filename (Case Conflict).ext). In Fast.io workspaces, agents use advisory file leases through the MCP storage tool (lock-acquire, lock-status, and lock-release). An advisory lock publishes who currently holds the lease and expires unless heartbeated. It does not block concurrent writes, while version history preserves every revision so no human or agent work is lost.
Tracking Updates Without Constant Polling
Polling files/search_v2 repeatedly on a timer consumes rate limit allowances and generates wasted compute when files have not changed. When monitoring for changes, use an events feed. Within Fast.io, applications subscribe to workspace activity using WebSocket feeds or long-polling via GET /current/activity/poll/{entity_id}?wait=95&lastactivity={timestamp}. When a synced Dropbox file lands in the workspace, the activity feed alerts listening worker agents to process the new artifact immediately.
Human-Agent Collaboration
Automated file pipelines should never run in total isolation. Once an agent discovers, indexes, and analyzes documents, it can document its findings in Collaborative Notes or prepare deliverables inside shared workspaces. If an agent constructs a new client workspace or data repository, ownership transfer allows the agent to hand administrative control back to human project leads while retaining execution access.
Monthly plans start with a 14-day free trial, which requires a credit card.
Sources
References used to verify factual claims in this guide.
-
The Dropbox Search API returns a has_more boolean flag indicating whether additional pages of matches must be retrieved using a continuation cursor.
Frequently Asked Questions
How do I search for files in Dropbox using the API?
You search for files in Dropbox by sending an HTTP POST request to the `/2/files/search_v2` endpoint with an OAuth 2 bearer token in the `Authorization` header. The request body requires a JSON payload containing the `query` string and an optional `options` object to filter by path, file extension, or file status. The response returns matching file metadata along with pagination cursors when more results exist.
What is the difference between Dropbox search and search_v2 endpoints?
The original `/2/files/search` endpoint was the legacy v1 search method, which has been superseded by `/2/files/search_v2`. The search_v2 endpoint introduces structured filtering through the `SearchOptions` schema, supports continuation cursors via `/2/files/search/continue_v2`, and provides unified matching across filenames and document bodies with improved consistency.
Can the Dropbox Search API filter by file type and date modified?
Yes. In `files/search_v2`, you can filter by file extensions by passing an array of extensions (such as `["pdf", "docx"]`) in the `file_extensions` parameter within the `options` block for active files. You can also specify `file_categories` such as document or image. To sort by modification date, set the `order_by` property to `last_modified_time`.
How does pagination work when a query returns more than one page of results?
When a search query yields more matches than the `max_results` threshold, the `SearchV2Result` response contains `has_more: true` and a `cursor` string. To retrieve subsequent pages, post the cursor to `/2/files/search/continue_v2`. This process repeats until `has_more` returns `false`. Across all pages, search_v2 limits combined results to 10,000 matches.
What rate limits apply to the Dropbox Search API?
Dropbox does not publish static numeric request caps for API endpoints. Limits are applied per app and per user based on platform load. When an application sends too many requests, Dropbox responds with HTTP 429 Too Many Requests or HTTP 503 Service Unavailable, accompanied by a `Retry-After` header indicating the required wait duration in seconds.
Related Resources

Search Dropbox Archives Directly from Agent Workspaces
Connect existing Dropbox folders into workspaces that index files automatically, providing remote MCP search without burning API rate limits. Monthly plans start with a 14-day free trial.