How to Connect Dify AI Agents to Dropbox Cloud Storage
A Dify Dropbox integration connects Dropbox cloud storage directories to Dify knowledge bases and agent workflows, allowing autonomous systems to ground model reasoning on team files. While native Dify plugins handle static file imports, querying raw Dropbox directories over HTTP triggers API rate limits and token bloat. Synchronizing Dropbox folders into an indexed Fast.io workspace lets Dify agents query documents through remote MCP search in a single step.

How Dify AI Agents Query Cloud Storage in Production
Directly querying an unindexed Dropbox directory from an autonomous Dify agent turns an immediate factual lookup into an exhaustive chain of HTTP requests across nested folder trees. When Dify workflows or autonomous agent nodes query raw cloud storage, they cannot search across document contents in a single step. Instead, they must recursively list folder paths, guess relevance from file names, download entire file binaries over HTTP, and exhaust context tokens on irrelevant pages.
Dify is an open-source platform for developing applications powered by large language models. It combines visual workflow orchestration, prompt engineering interfaces, agent execution runtimes, and retrieval-augmented generation (RAG) pipelines. Development teams build diverse applications in Dify, including customer support assistants, autonomous market research agents, procurement analysis pipelines, and compliance verification bots.
For engineering teams building on Dify, Dropbox serves as a primary repository for team files and operational knowledge. These shared directories house master service agreements, vendor contracts, technical architecture specifications, policy handbooks, and financial spreadsheets.
A Dify Dropbox integration connects Dropbox cloud storage directories to Dify knowledge bases for automated document indexing, vectorization, and RAG retrieval.
In standard deployments, developers encounter two native pathways for connecting Dropbox to Dify: the Dropbox Tool plugin (langgenius/dropbox) available in the Dify Marketplace, and manual batch file uploads into Dify Knowledge datasets.
When building autonomous agents using ReAct or Function Calling modes in Dify, developers can attach the Dropbox Tool plugin. Maintained by langgenius, this plugin equips agent nodes with tools to list files and folders, search file names, download file contents, create folders, and upload new documents. For authentication, developers create an application in the Dropbox App Console, generate an OAuth 2.0 access token with appropriate read and write permissions, and configure the credentials in Dify.
For retrieval-augmented generation pipelines, teams often start by manually downloading files from Dropbox and uploading them into Dify Knowledge datasets. Dify parses incoming documents, extracts raw text, generates semantic chunks, and stores vector embeddings in its internal database.
Manual file uploads in Dify create stale datasets that drift out of sync with active team Dropbox folders. When colleagues update contracts, add product briefs, or reorganize folders in Dropbox, Dify's internal dataset remains unchanged. As a result, agents generate answers based on outdated information unless engineers repeat the manual export, chunking, and upload cycle.
Related guides
- How to Connect ChatGPT to Dropbox: Integration & Storage SetupConnecting ChatGPT to Dropbox allows OpenAI models to read, summarize, and organize cloud documents without manual...
- How to Connect ChatGPT to Dropbox: Integration GuideA ChatGPT Dropbox integration connects OpenAI models to cloud file directories, enabling users and agents to query,...
- How to Connect Dify AI Agents to Google DriveConnecting Dify to Google Drive allows agentic workflows and LLM apps to query Google Drive files as a persistent...
- Building an AI Agent for Dropbox: Setup and Storage PatternsBuilding an AI agent for Dropbox requires balancing file retrieval against LLM context boundaries. While direct API...
- LangGraph Dropbox Connector: Persistent Storage for Agent WorkflowsA LangGraph Dropbox connector links stateful graph agents to external cloud folders without bloating graph...
- How to Connect LlamaIndex to Dropbox Documents for Production RAGLlamaIndex Dropbox integration connects data readers and query engines to cloud storage files for semantic retrieval....
More on this subject: Agent Integrations and APIs (191 guides)
Why Direct Dropbox Traversal Stalls Multi-Document Workflows
Autonomous AI agents interact with file storage differently than human operators. A human team member opens Dropbox in a web browser, browses to a familiar project folder, scans file titles, and opens a specific PDF. In contrast, an autonomous Dify agent relies on programmatic tool calls to discover, inspect, and evaluate documents in unfamiliar directory trees. When an agent queries raw Dropbox repositories directly, technical bottlenecks quickly disrupt execution.
Recursive Directory Traversal and Chained Latency
Dropbox organizes files within hierarchical paths. When an agent needs to discover documents across multi-tiered directory structures, it must call folder listing endpoints repeatedly. When a team repository contains hundreds of documents distributed across dozens of subfolders, locating relevant files requires sequential API calls: inspecting the root, identifying child folders, issuing queries for each directory, and parsing results.
Every directory listing incurs a distinct network round trip over the public internet. These sequential requests add minutes of latency to agent execution. In interactive Dify chat applications or automated workflow nodes, chained API round trips cause client connections to exceed HTTP gateway timeouts.
Dropbox API Rate Limits and Lock Contention
The Dropbox API enforces dynamic rate limits across endpoints to maintain infrastructure stability. When an application issues rapid API calls during directory indexing or batch retrieval, the API returns an HTTP 429 status code with the reason too_many_requests. Rate limited responses from the Dropbox API include a Retry-After header indicating how long an application must wait before retrying.
In addition to explicit request rate limits, Dropbox enforces concurrency controls on shared namespaces. When parallel workflow threads attempt to read or modify files within the same folder space simultaneously, Dropbox can return an HTTP 429 error with the reason too_many_write_operations due to lock contention. Existing guides often suggest writing custom webhooks or cron scripts to poll Dropbox for file updates. However, these custom scripts break under rate limits during batch agent analysis: concurrent file modification events trigger sudden request bursts that exhaust Dropbox API limits, stalling Dify pipelines mid-run.
Context Window Bloat and Token Overhead
Direct storage connectors transfer complete file binaries rather than targeted text passages. When a Dify agent tool downloads a multi-page master service agreement, a technical whitepaper, or a large spreadsheet from Dropbox, the entire text content is injected into the LLM prompt context.
Injecting entire document bodies into prompt windows consumes tens of thousands of input tokens on legal disclaimers, boilerplate formatting, and irrelevant sections. This token bloat inflates per-query inference costs, slows model generation, and degrades retrieval precision by burying critical facts in peripheral text.
Storage Traversal Architecture Comparison
Evaluating direct API traversal against pre-indexed workspace retrieval demonstrates clear structural differences:
Benchmarking Direct Dropbox Traversal Against Fast.io Workspaces
To eliminate the latency, token bloat, and rate limits of direct API queries, engineering teams deploy an intelligent two-tier storage layer. Teams keep Dropbox as their operational source of truth where human colleagues create, organize, and edit files. They then link their designated Dropbox folders to a Fast.io workspace using Cloud Sync.
Fast.io Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders to a workspace. SharePoint libraries connect through the OneDrive connector. Synchronization runs one-way or two-way, on a schedule or on demand; never continuous, live, or real-time. Fast.io Cloud Sync provides scheduled background updates to keep agent-accessible document indices fresh without webhooks. This setup keeps team workflows grounded in Dropbox while Dify agents query an optimized search surface.
The performance difference between direct storage traversal and indexed workspace retrieval has been measured head to head. Fast.io publishes the connector comparison at Fast.io Benchmarks: one agent runs the same multi-document customer relationship audit against an identical corpus held in Fast.io and in each of the major cloud storage providers, and each run is scored on completion time, storage tool calls, input tokens, and task cost. Fastio was measured the fastest and the lowest cost of the providers tested. Every measured row represents that provider's native connector in Claude Cowork; no row is a local stdio server, a Files-On-Demand stub or SharePoint, and SharePoint was not measured at all.
This performance gain stems from Fast.io Intelligence Mode. When documents sync into a Fast.io workspace, Intelligence Mode indexes their contents using hybrid search: combining full-text keyword matching, dense semantic embeddings, and metadata values. Dify agents query the index through a remote Model Context Protocol (MCP) server, receiving precise text excerpts and document citations in a single tool call without traversing directory trees.


Connect Dify agents to enterprise Dropbox files
Synchronize team Dropbox folders into persistent Fast.io workspaces with automated indexing and remote MCP retrieval. Monthly plans start with a 14-day free trial, which requires a credit card.
Implementing a Dify Dropbox Integration via Fast.io MCP in Four Steps
Connecting Dropbox storage to Dify AI agents through Fast.io follows a four-step implementation:
- Scope the target Dropbox folder
- Sync Dropbox into a Fast.io workspace
- Index the workspace with Intelligence Mode and Metadata Views
- Connect Dify to Fast.io using the remote MCP server
1. Scope the Target Dropbox Folder
Begin by identifying the specific Dropbox directory containing the documents your Dify agents need to access. Rather than connecting an entire organizational root drive, scope the integration to a designated folder, such as a vendor contracts archive, client documentation folder, or technical knowledge base. Scoping folder boundaries prevents unnecessary indexing overhead, protects sensitive internal files, and keeps agent retrieval focused on relevant documentation.
2. Sync Dropbox into a Fast.io Workspace
Log into your Fast.io account and create a dedicated workspace for your project. From the workspace dashboard, configure Cloud Sync to connect to Dropbox:
Authenticate your Dropbox account through the standard OAuth prompt.
Select the designated Dropbox folder scoped in Step 1.
Configure sync direction: select one-way sync from Dropbox to Fast.io for read-only agent retrieval, or two-way sync if agents write reports or briefs back to Dropbox.
Define the synchronization schedule, choosing hourly or daily intervals, or manual on-demand execution. Synchronization runs on background schedules and is never real-time.
Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders to a workspace directly between cloud infrastructures without consuming local network bandwidth or local disk space.
3. Index the Workspace with Intelligence Mode and Metadata Views
Verify that Intelligence Mode is active on your workspace. Intelligence Mode parses incoming PDFs, Word files, Excel spreadsheets, presentation decks, and text documents, creating hybrid search indexes across full-text keywords and semantic embeddings.
For collections of structured business files, such as invoices, service contracts, or compliance questionnaires, configure Metadata Views. Metadata Views turn unstructured documents into a live, queryable database. Users describe target extraction fields using natural language, such as contract effective dates, counterparty names, renewal terms, or payment amounts. Fast.io creates a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time formats. Values are extracted across documents without rigid templates or manual OCR rules. Dify agents can query Metadata Views via MCP to filter files by structured attributes before retrieving matching text passages.
4. Connect Dify to Fast.io Using the Remote MCP Server
Dify includes native support for the Model Context Protocol (MCP), allowing visual workflows and agent execution nodes to connect to external tool servers over Streamable HTTP.
Fast.io hosts a remote MCP server accessible over Streamable HTTP at https://mcp.fast.io/mcp/tools. For server-to-server connections like Dify, the server accepts a scoped API key in the Authorization header. You can review integration details and architecture on the storage for agents page and the Fast.io MCP setup guide. Teams connecting other enterprise repositories to Dify can apply the same remote MCP pattern, such as connecting Microsoft OneDrive to Dify for Microsoft 365 files.
To configure Fast.io in Dify Studio:
In your Dify console, open Tools > MCP.
Click Add MCP Server and select Streamable HTTP as the transport type.
Enter the server endpoint URL:
https://mcp.fast.io/mcp/tools.In the Headers configuration, add your Fast.io API key:
{
  "Authorization": "Bearer YOUR_FASTIO_API_KEY"
}
- Save the configuration. Dify validates the connection and registers the consolidated MCP tools in your tool catalog.
To instruct an autonomous Dify agent to query the synchronized workspace, attach the Fast.io MCP tools to your agent node and provide retrieval instructions:
You have access to the Fast.io MCP toolset connected to the team Dropbox repository.
When answering questions regarding company contracts, specifications, or policies:
1. Call the storage tool to search with the user query.
2. Review returned text excerpts and citations.
3. Ground your response strictly on the retrieved passages, citing the document name and section.
4. Do not attempt manual file downloads or recursive folder crawling.
When the Dify agent executes, it calls the Fast.io storage tool once. Fast.io returns relevant text excerpts with source citations, enabling the agent to synthesize accurate answers without recursive API calls or token bloat.
Operational Best Practices for Production Dify Deployments
Operating autonomous Dify agents against synchronized cloud storage requires attention to governance, multi-agent coordination, and workspace lifecycle management. Applying structured operational patterns keeps enterprise knowledge secure, reliable, and auditable.
Multi-Agent Coordination and Per-File Version History
Complex Dify architectures often deploy multiple specialized agents in sequence: an intake agent indexes incoming files, an analysis agent extracts key metrics, and a reporting agent drafts client summaries.
To prevent agents from overwriting shared documents or losing historical context, Fast.io maintains complete per-file version history. When an agent updates an analysis or writes a new draft back to the workspace, Fast.io records the revision without destroying prior versions. Team members can inspect earlier revisions, compare diffs, and restore previous versions whenever needed.
Collaborative Notes for Human-Agent Handoff
When an agent completes a document synthesis or research task, delivering results only to a transient chat interface leaves valuable context isolated. Fast.io provides Collaborative Notes: persistent documents kept beside workspace files for people and agents. Collaborative Notes use version-checked saves rather than real-time co-editing.
An agent writes its synthesized findings, executive summaries, and action items directly into a Note. Human colleagues can review the document, leave comments, and refine recommendations, turning raw agent outputs into durable team assets.
Workspace and Share Access Governance
Enterprise deployments require clear boundaries around document access. In Fast.io, permissions are configured per organization, workspace, and share through member roles. When connecting Dify agents to a workspace, issue API keys scoped strictly to the required project workspace. Restricting agent credentials prevents automated workflows from accessing unrelated organizational workspaces.
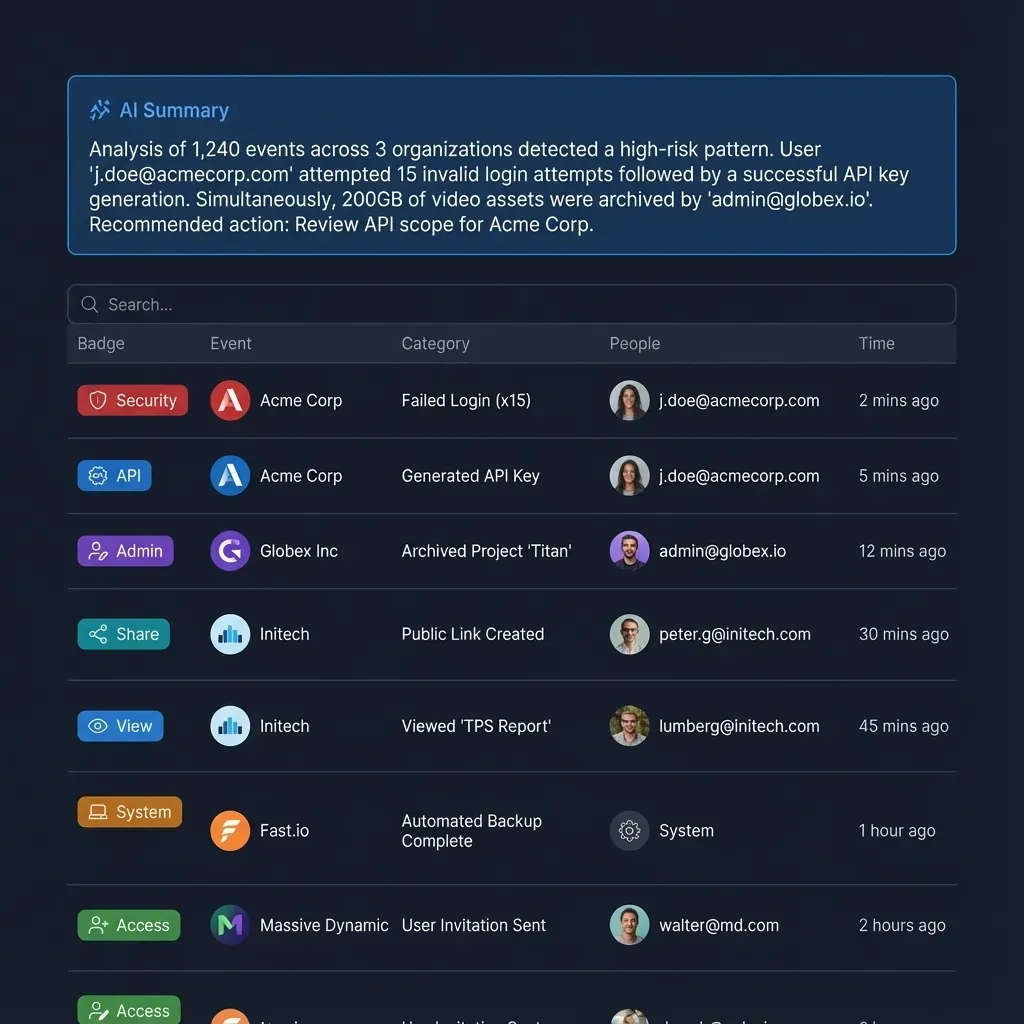
Every document creation, modification, move, and deletion is recorded in a detailed activity log. The activity log tracks changes made by team members and autonomous agents alike, giving security and compliance teams complete visibility into workspace modifications.
Agent-to-Human Ownership Transfer
In consulting, implementation agencies, and client delivery workflows, developers frequently use Dify agents to build dedicated client portals or compliance archives. An agent can establish the initial workspace structure, sync designated Dropbox folders, configure Metadata Views, and index files.
Once configuration is complete, Fast.io supports ownership transfer: an agent can build an organization and hand it to a person with a claim link while retaining administrative access. This capability allows agencies to deliver turn-key agentic workspaces to clients without ongoing operational friction.
Subscription Plans and 14-Day Free Trial
Setting up production workspaces on Fast.io is straightforward. Creating a user account is free; doing real work requires an organization on a paid subscription. Monthly plans start with a 14-day free trial, which requires a credit card. Annual plans start paid, with no trial. Development teams can review active tiers on the Fast.io pricing page and evaluate synchronized Dropbox workflows during the trial period:
Sources
References used to verify factual claims in this guide.
-
Rate limited responses from the Dropbox API include a Retry-After header indicating how long an application must wait before retrying.
Frequently Asked Questions
How do I sync Dropbox files to a Dify dataset?
You can sync Dropbox files to Dify using two approaches. For static datasets, you can manually export files from Dropbox and upload them into a Dify Knowledge dataset, where Dify parses and vectorizes the text. For automated synchronization, connect your Dropbox folder to a Fast.io workspace using Cloud Sync. Fast.io automatically indexes documents with hybrid search, allowing Dify agent nodes to query the latest files directly through Fast.io's remote MCP server.
Does Dify support automated Dropbox folder synchronization?
Dify does not provide native background folder synchronization for Dropbox. The Dify Marketplace Dropbox plugin (langgenius/dropbox) operates as an agent tool for interactive listing and downloading rather than background dataset synchronization. To keep datasets fresh automatically without custom webhooks, sync Dropbox folders to a Fast.io workspace on a background schedule and connect Dify to Fast.io via MCP.
How can Dify agents query documents stored in Dropbox?
Dify agents can query Dropbox documents either by using the Dropbox Tool plugin to download entire files dynamically, or by querying an indexed Fast.io workspace via MCP. Using Fast.io's remote MCP server at `https://mcp.fast.io/mcp/tools`, the agent issues a search query and receives concise text passages with document citations in a single tool call, avoiding rate limits and token bloat.
What happens when an application exceeds Dropbox API rate limits?
When an application exceeds Dropbox API rate limits, the API returns an HTTP 429 status code with the reason too_many_requests. Responses include a Retry-After header specifying the number of seconds the application must wait before retrying. If concurrent requests create lock contention in shared folders, Dropbox can also return an HTTP 429 status code with too_many_write_operations.
Does Fast.io support scheduled synchronization for Dropbox folders?
Yes. Fast.io Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders on a recurring schedule or on demand. Synchronization runs one-way or two-way, operating in the background rather than through continuous or real-time file monitoring. Background synchronization allows document indexing and vector generation to complete predictably without overwhelming Dropbox API limits.
Related Resources

Connect Dify agents to enterprise Dropbox files
Synchronize team Dropbox folders into persistent Fast.io workspaces with automated indexing and remote MCP retrieval. Monthly plans start with a 14-day free trial, which requires a credit card.