How to Connect Dify AI Agents to Microsoft OneDrive
Connecting Dify to Microsoft OneDrive bridges visual agent orchestration with enterprise document storage, allowing autonomous workflows to ground LLM reasoning on company files without recursive Graph API crawling. While native Dify plugins handle static file imports, multi-document agent queries trigger Microsoft Graph rate limits and token bloat. Syncing OneDrive folders into an indexed Fast.io workspace lets Dify agents query documents through remote MCP tools in a single step.

How Dify AI Agents Query Enterprise OneDrive Storage
When an autonomous Dify agent queries an unindexed Microsoft OneDrive folder via Microsoft Graph, it converts what should be an immediate factual lookup into an exhaustive chain of API requests across nested directory trees. When Dify workflows or autonomous agent nodes query raw cloud storage, they cannot search across document contents in a single step. Instead, they must recursively list folder identifiers, guess relevance from file names, download entire file binaries over HTTP, and exhaust context tokens on irrelevant pages.
Dify is an open-source platform for developing applications powered by large language models (LLMs). It integrates visual workflow orchestration, prompt engineering interfaces, agent execution runtimes, and retrieval-augmented generation (RAG) pipelines. Development teams build diverse applications in Dify, including customer support assistants, autonomous market research agents, procurement analysis pipelines, and compliance verification bots.
For enterprise engineering teams building on Dify, Microsoft OneDrive and SharePoint document libraries serve as primary corporate repositories. These directories house operational knowledge, including master service agreements, vendor contracts, technical architecture specifications, financial spreadsheets, and meeting transcripts.
Connecting Dify to Microsoft OneDrive bridges visual agent orchestration with enterprise document storage, allowing autonomous workflows to ground LLM reasoning on company files without recursive Graph API crawling. In production deployments, engineering teams implement this connection through two native pathways in the Dify Marketplace: the OneDrive Datasource plugin (langgenius/onedrive_datasource) for Knowledge datasets, and the Microsoft OneDrive Tool plugin (langgenius/onedrive) for agent execution nodes.
When configuring the Knowledge Datasource plugin, administrators register an application in the Microsoft Entra ID (formerly Azure Active Directory) portal. They generate a Client ID, create a Client Secret, record their Tenant ID, and configure delegated permissions such as Files.Read.All and Sites.Read.All. Once authorized via OAuth 2.0, users browse their OneDrive hierarchy in Dify, select specific files or folders, and initiate an ingestion task. Dify downloads the selected documents, extracts text from Word files, PowerPoint presentations, Excel workbooks, and PDFs, chunks the extracted text, and generates vector embeddings stored in an internal vector database.
When building autonomous agents in Dify using ReAct or Function Calling modes, developers attach the Microsoft OneDrive Tool plugin. This plugin provides the agent with tool definitions to list items and download file contents dynamically during workflow execution.
This direct architecture performs acceptably for small collections of static text. When an assistant summarizes an isolated onboarding memo or answers questions from a single product manual, Dify retrieves pre-computed vectors from its internal database without issue.
However, enterprise operations rarely involve isolated single files. Conducting a compliance audit, evaluating contract renewals, or reviewing multi-year financial statements requires analyzing dozens of files scattered across nested folder trees. When Dify pipelines query live OneDrive directories directly, technical bottlenecks quickly disrupt execution.
Related guides
- Can ChatGPT Access OneDrive? Workflows, Admin Limits & Fast StorageChatGPT can access OneDrive files through its cloud storage connector, but personal accounts remain unsupported while...
- How to Connect Google Gemini to Amazon S3: Cloud Storage Bridging GuideConnecting Gemini to Amazon S3 enables Google multimodal AI to analyze documents and media stored on AWS without...
- How to Connect Google Gemini to Microsoft OneDriveA Gemini OneDrive integration enables Google Gemini agents and applications to access and analyze Microsoft OneDrive...
- How to Connect Dify AI Agents to Box Cloud StorageConnecting Dify to Box allows autonomous AI agents to query enterprise documents as an active knowledge base. While...
- How to Connect LangChain to OneDrive Files for AI AgentsConnecting LangChain to Microsoft OneDrive gives AI agents access to corporate documents, but loading deep directories...
- How to Connect LangGraph Agent Workflows to OneDrive DocumentsConnecting LangGraph to OneDrive enables cyclic agent workflows and state machines to retrieve, synthesize, and ground...
More on this subject: AI Agents: General Guides (99 guides)
Why Direct Microsoft Graph Traversal Stalls Multi-Document Workflows
Autonomous AI agents evaluate cloud storage differently than human operators. A human user opens the OneDrive web interface, browses to a familiar folder, skims document titles, and selects an obvious PDF. In contrast, an autonomous Dify agent relies on programmatic tool calls to discover and inspect unfamiliar file systems. When an agent queries raw OneDrive repositories directly via Microsoft Graph, multiple architectural barriers emerge.
Opaque Folder Identifiers and Chained Directory Latency
Microsoft Graph models storage objects using unique alphanumeric item IDs rather than hierarchical POSIX file paths. Querying a folder through endpoints like /me/drive/items/{item-id}/children returns only immediate child items. If an enterprise repository organizes documents three or four levels deep, an agent must execute sequential API requests: querying the root folder, parsing returned folder IDs, issuing queries for each candidate subfolder, and repeating this sequence down the tree.
Each directory listing incurs a distinct network round trip across the public internet. If an agent must search an enterprise directory containing 200 files distributed across 15 subfolders, assembling the document index requires dozens of sequential API calls. These round trips consume minutes of execution time, causing customer-facing Dify chat interfaces and automated workflow nodes to encounter HTTP gateway timeouts.
Microsoft Graph API Rate Limits and Throttling Windows
Microsoft Graph enforces service limits to protect multi-tenant infrastructure stability. The Dify OneDrive datasource plugin documents a Microsoft Graph limit of 10,000 requests per 10 minutes per app per tenant, alongside per-user limits of 1,000 requests per 10 minutes. Furthermore, Microsoft Graph and SharePoint Online return HTTP status code 429 when application requests exceed service usage thresholds.
When an application receives an HTTP 429 response, Microsoft Graph includes a Retry-After header indicating the required pause duration before retrying the request. When Dify pipelines run bulk ingestion jobs or multiple autonomous agents query file directories concurrently, they rapidly exhaust available request quotas.
Sudden throttling backoff pauses stall agent execution, causing automated Dify pipelines to fail mid-run and exceed execution timeouts. Competitor guides often suggest writing custom webhook listeners and raw Microsoft Graph synchronization scripts. However, these custom scripts break under enterprise rate limits during batch agent analysis: incoming file modification events trigger concurrent download bursts that quickly exhaust Graph API quotas, leaving document indexes out of sync.
Context Window Bloat and Token Consumption
Direct storage connectors transfer complete file payloads rather than focused semantic excerpts. When a Dify agent tool retrieves a 40-page master service agreement or a complex quarterly spreadsheet, the full text gets injected directly into the LLM prompt context.
Injecting entire document bodies into prompt windows consumes tens of thousands of input tokens on legal disclaimers, table styling, and repetitive headers. This overhead inflates per-query inference expenses, slows model generation, and increases the likelihood of frontier models missing specific factual clauses buried in extensive text.
Storage Traversal Architecture Comparison
Evaluating direct API traversal against pre-indexed workspace retrieval reveals substantial operational differences:
Benchmarking Direct OneDrive Traversal Against Fast.io Workspaces
To eliminate the latency and rate limits of raw API queries, engineering teams deploy an intelligent two-tier storage layer. Organizations retain Microsoft OneDrive as their operational source of truth where human team members create, organize, and edit enterprise files. They then link their designated OneDrive folders to a Fast.io workspace using Cloud Sync.
Fast.io Cloud Sync links Microsoft OneDrive, Box, and Dropbox folders to an intelligent workspace. SharePoint document libraries are reached through the OneDrive connector. Synchronization runs one-way or two-way, on a schedule or on demand; Google Drive imports today with sync coming soon; never real-time. This architecture ensures that enterprise compliance policies, corporate identity, and human workflows remain grounded in Microsoft 365, while Dify agents query an optimized search surface.
The performance divergence between direct storage traversal and indexed workspace retrieval has been measured head to head. Fast.io publishes the comparison at Fast.io Benchmarks: one agent runs the same multi-document customer relationship audit against an identical corpus held in Fast.io and in each of the major cloud storage providers, and each run is scored on completion time, storage tool calls, input tokens and task cost. Fast.io completed the audit fastest and at the lowest cost of the providers measured. OneDrive is tested through its own native connector, and SharePoint carries no published figure.
This performance gain stems from Fast.io Intelligence Mode. When documents sync into a Fast.io workspace, Intelligence Mode indexes their contents using hybrid search: combining full-text keyword matching, dense semantic embeddings, and metadata values. Dify agents query the index through a remote Model Context Protocol (MCP) server, receiving precise text excerpts and document citations in a single tool call without traversing directory trees.



Connect Dify agents to enterprise OneDrive files
Synchronize OneDrive folders into persistent Fast.io workspaces with automated indexing and remote MCP retrieval. Monthly plans start with a trial of up to 30 days (credit card required); annual plans have no trial.
Connecting OneDrive to Dify via Fast.io MCP in Four Steps
Connecting Microsoft OneDrive to Dify AI agents through Fast.io follows a straightforward four-step implementation:
- Scope the target OneDrive folder
- Sync OneDrive into a Fast.io workspace
- Index the workspace with Intelligence Mode and Metadata Views
- Connect Dify to Fast.io using the remote MCP server
1. Scope the Target OneDrive Folder
Begin by identifying the specific OneDrive or SharePoint folder that contains the documents your Dify agents need to access. Rather than connecting an entire organizational root directory, scope the integration to a designated repository, such as a project archive, vendor contracts folder, or legal compliance library. Scoping folder boundaries prevents unnecessary indexing overhead, protects confidential personnel files, and keeps agent retrieval focused on relevant documentation.
2. Sync OneDrive into a Fast.io Workspace
Log into your Fast.io account and create a dedicated workspace for your project. From the workspace dashboard, configure Cloud Sync to connect to Microsoft OneDrive:
Authenticate your Microsoft 365 account through the standard OAuth authorization prompt.
Select the specific OneDrive folder or SharePoint document library scoped in Step 1.
Configure sync direction: choose one-way sync if OneDrive serves as the primary system of record, or two-way sync if you want agent-generated summaries and briefs synchronized back to Microsoft 365.
Define the synchronization schedule, selecting an hourly background refresh or manual on-demand execution. Synchronization runs on background schedules and is never real-time.
Fast.io automatically processes imported documents in the background. Word files, Excel sheets, PowerPoint decks, and PDF documents are converted into searchable text and indexed for semantic retrieval.
3. Index the Workspace with Intelligence Mode and Metadata Views
Enable Intelligence Mode on your workspace to activate automated hybrid indexing. Intelligence Mode indexes file contents across full text and vector embeddings, allowing agents to perform semantic search queries with citation tracking.
For collections containing structured business documents, such as supplier invoices, service agreements, or insurance forms, configure Metadata Views. Metadata Views turn unstructured documents into a live queryable database. Users define desired extraction fields using natural language, and Fast.io extracts typed data (Text, Integer, Decimal, Boolean, URL, JSON, Date & Time) across workspace documents without manual templates or optical character recognition rules. Agents query these structured fields via MCP to filter files by counterparties, renewal dates, or invoice totals.
4. Connect Dify to Fast.io Using the Remote MCP Server
Dify includes native support for the Model Context Protocol (MCP), enabling workflows and agent nodes to invoke external tools over Streamable HTTP and Server-Sent Events (SSE).
Fast.io hosts a remote MCP server accessible over Streamable HTTP at https://mcp.fast.io/mcp, or at https://mcp.fast.io/mcp/key when authenticating via an API key header, alongside a legacy SSE transport at https://mcp.fast.io/sse.
To register Fast.io in Dify Studio:
Navigate to Tools > MCP in your Dify dashboard.
Click Add MCP Server and select Streamable HTTP as the transport protocol.
Enter the server endpoint URL:
https://mcp.fast.io/mcp/key.In the Headers configuration, add your Fast.io API key:
{
  "Authorization": "Bearer YOUR_FASTIO_API_KEY"
}
- Save the configuration. Dify validates the connection and imports the consolidated MCP tools into your tool registry.
Once registered, attach the Fast.io MCP tools to your Dify agent node or Workflow Studio pipeline. In a ReAct or Function Calling agent, instruct the agent to query the workspace:
You have access to the Fast.io MCP toolset connected to the company OneDrive repository.
When researching customer contracts or compliance terms:
1. Use the workspace search tool to locate relevant passages.
2. Filter search queries by folder path or metadata attributes when appropriate.
3. Base all answers on returned citations, citing file names and section titles.
4. Do not attempt recursive directory crawling.
When the Dify agent executes, it issues a single search query to the remote MCP server. Fast.io returns relevant text snippets with source citations, enabling the agent to formulate accurate answers without recursive API calls or token bloat.
Operational Best Practices for Production Dify Deployments
Operating autonomous Dify agents against synchronized enterprise storage requires attention to governance, multi-agent coordination, and workspace lifecycle management. Applying structured operational patterns ensures enterprise knowledge stays secure, reliable, and auditable.
Granular Access Controls and Audit Trails
Enterprise file storage requires precise permission boundaries. Fast.io enforces granular access controls across organizational, workspace, folder, and file levels. When connecting Dify agents to a workspace, issue API keys scoped strictly to the required project workspace. Restricting agent credentials prevents automated workflows from accessing unrelated organizational folders.
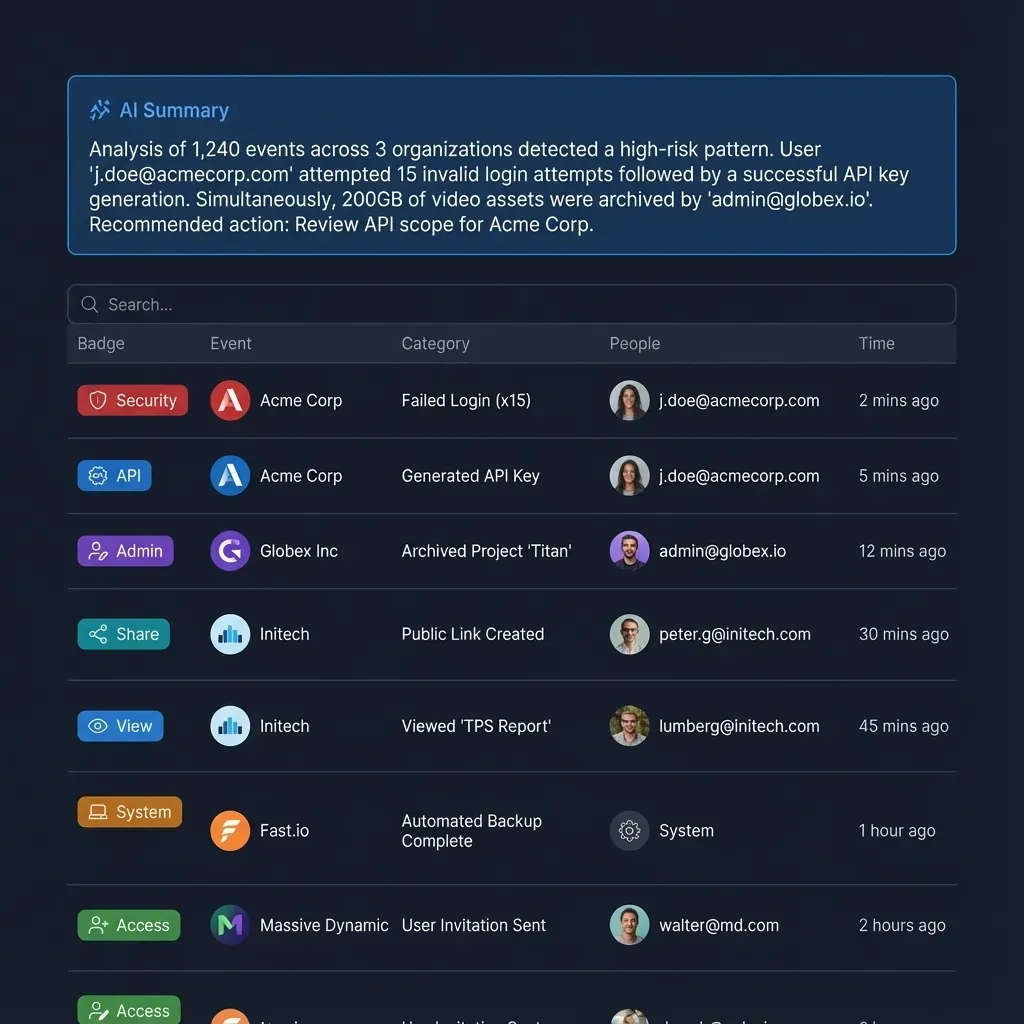
Every document read, write, and search operation is recorded in an append-only audit log. Security teams monitor the audit log to verify which files an agent inspected, track when new documents were ingested, and validate compliance with data governance policies.
Multi-Agent File Coordination and Version History
Complex enterprise workflows frequently deploy multiple specialized agents in sequence: an intake agent downloads customer documents, an extraction agent parses structured metadata, and a reporting agent drafts executive briefs.
To prevent agents from overwriting shared documents or losing historical context, Fast.io maintains complete per-file version history. When an agent updates an analysis or writes a new draft back to the workspace, Fast.io records the revision without destroying prior versions. Team members can inspect earlier revisions, compare diffs, and restore previous versions whenever needed.
Collaborative Notes for Human-Agent Handoff
When an agent completes a complex audit or multi-document synthesis, outputting the result solely into a transient chat window leaves valuable context stranded. Fast.io provides Collaborative Notes: real-time co-editing documents where human operators and AI agents collaborate within the same workspace.
A Dify agent can write its synthesized findings, executive summaries, and action items directly into a Collaborative Note. Human colleagues can review the document, highlight text, insert comments, and refine recommendations in real time, turning raw agent outputs into shared team assets.
Agent-to-Human Ownership Transfer
In consulting and client-delivery environments, development teams frequently use Dify agents to build dedicated client portals or compliance archives. An agent can establish the initial workspace structure, import designated OneDrive folders, configure Metadata Views, and index files.
Once setup is complete, Fast.io supports ownership transfer: the creator hands off primary workspace ownership to the client or department lead while retaining administrative access. This capability allows agencies to deliver turn-key agentic workspaces to clients without ongoing operational friction.
Subscription Plans and Implementation Trial
Setting up production workspaces on Fast.io is straightforward. Creating a user account is free; doing real work requires an organization on a paid subscription. Plans are structured into clear tiers: Starter at $9.99/mo, Business at $49.99/mo, and Enterprise at $199.99/mo. Monthly plans start with a trial of up to 30 days (credit card required); annual plans have no trial. Development teams can evaluate synchronized OneDrive workflows and remote MCP retrieval during the trial period before committing to production deployment.
Sources
References used to verify factual claims in this guide.
-
Microsoft Graph and SharePoint Online return HTTP status code 429 when application requests exceed service usage thresholds.
-
The Dify OneDrive datasource plugin documents a Microsoft Graph limit of 10,000 requests per 10 minutes per app per tenant.
Frequently Asked Questions
Can Dify connect to Microsoft OneDrive?
Yes. Dify connects to Microsoft OneDrive through native plugins in the Dify Marketplace or through remote Model Context Protocol (MCP) servers. The native OneDrive datasource plugin allows users to import files into Dify Knowledge datasets using Azure AD OAuth credentials. Alternatively, syncing OneDrive folders into an indexed Fast.io workspace allows Dify agents to query documents via Fast.io's remote MCP server over Streamable HTTP.
How do I add OneDrive documents to Dify knowledge base?
You can add OneDrive documents to Dify using two approaches. Through the native OneDrive datasource plugin, register an application in Microsoft Entra ID, configure OAuth credentials in Dify, and select files to ingest into a Dify Knowledge dataset. Alternatively, connect your OneDrive folder to a Fast.io workspace using Cloud Sync. Fast.io automatically indexes documents for hybrid semantic search, which Dify agent nodes can query directly using the remote MCP search tool.
What are the API rate limits when querying OneDrive with AI agents?
Microsoft Graph enforces service limits to maintain infrastructure stability. The Dify OneDrive datasource plugin notes limits of 10,000 requests per 10 minutes per app per tenant and 1,000 requests per 10 minutes per user. In addition, Microsoft Graph and SharePoint Online return HTTP status code 429 when application requests exceed usage thresholds, requiring clients to pause requests according to the Retry-After header.
What is the difference between direct OneDrive connector calls and Fast.io MCP search?
Direct OneDrive connectors download complete file binaries over HTTP and require recursive API requests to navigate nested folder trees. This approach consumes significant input tokens and risks rate-limit throttling. In contrast, Fast.io pre-indexes synchronized OneDrive documents using hybrid search. A Dify agent invokes Fast.io's remote MCP server to retrieve concise, relevant text passages and citations in a single tool call.
Does Fast.io support real-time sync with Microsoft OneDrive?
No. Fast.io Cloud Sync for Microsoft OneDrive operates on background schedules (such as hourly or daily intervals) or on demand. It does not perform real-time mirroring. This scheduled approach ensures that document indexing and vector generation complete predictably without overwhelming Microsoft Graph API quotas.
Related Resources

Connect Dify agents to enterprise OneDrive files
Synchronize OneDrive folders into persistent Fast.io workspaces with automated indexing and remote MCP retrieval. Monthly plans start with a trial of up to 30 days (credit card required); annual plans have no trial.