OpenAI Codex Context Limit: Agent Execution Caps and MCP Retrieval
The OpenAI Codex context limit bounds the prompt instructions, tool definitions, shell execution logs, and file diffs that a coding agent can hold in active memory. In the Codex CLI, OpenAI enforces a server-side cap of 272,000 tokens, which repetitive execution loops can saturate quickly. Offloading large documentation and reference files to a remote MCP server with semantic search prevents context degradation without inflating token spend.

What Is the Codex Context Limit? Model Ceilings vs. Runtime CLI Caps
In mid-2026, OpenAI reduced the Codex CLI context window to a 272,000-token cap, a roughly 27% cut from previously documented limits. The adjustment arrived server-side without a formal version bump or public announcement. Developers discovered the change when long-running coding sessions, multi-file refactoring runs, and repository audits began failing unexpectedly with context-overflow errors.
The Codex context limit is the maximum token boundary constraining the prompt, iterative command history, and file diffs that OpenAI Codex agents can process within an active coding session.
When evaluating a codex context limit, you must separate the underlying model ceiling from the product-level execution cap. Model cards for modern OpenAI reasoning and coding models publish raw input capacities reaching 128,000 tokens for GPT-4o up to higher theoretical boundaries on frontier reasoning endpoints. But an interactive agent environment like the Codex CLI operates under strict operational guardrails.
The Gap Between Raw Model Tokens and Usable Agent Capacity
The advertised context window of an LLM does not equal the workspace memory available for code edits. In the Codex CLI, the 272,000-token cap represents the absolute upper limit before the runtime refuses additional tokens or enforces aggressive compaction.
Within that allocation, the runtime consumes significant overhead before the agent executes its first shell command:
- System Prompt and Agent Instructions: The baseline prompt instructing the agent on role boundaries, tool schemas, safety constraints, and formatting rules consumes several thousand tokens.
- Tool and Schema Definitions: Every registered tool, from filesystem readers to shell runners, injects typed JSON schemas into the prompt space.
- Safety Filters and Execution Rails: Guardrails governing command execution and workspace boundaries draw from the initial budget.
- Effective Headroom: Factoring in the runtime's operational buffers, a 272,000-token cap leaves roughly 258,400 usable tokens for repository content, command output, and user instructions.
Why Provider-Specific Limits Are Configuration, Not Contracts
Many development teams treat vendor context specifications as permanent architectural guarantees. In reality, provider-specific limits are dynamic infrastructure configurations. Cloud AI providers routinely adjust runtime context windows, compaction thresholds, and tier multipliers to balance datacenter memory pressure, inference latency, and operational expense.
When prompts cross the 272,000-token threshold, inference costs often jump into higher tier multipliers. OpenAI configured the Codex CLI cap at 272,000 tokens partly to prevent autonomous subagent loops from silently crossing into higher-cost tiers during automated test iterations. Relying on an uninterrupted context window without intermediate checkpointing exposes long-running agent workflows to sudden failure whenever a provider alters server-side parameters. For teams deploying coding agents across production repositories, maintaining persistent workspaces outside the active context buffer is essential; see storage for agents for architectural patterns.
Related guides
- GitHub Copilot Token Limit: Context Windows, Chat Caps, and MCP SolutionsThe GitHub Copilot token limit restricts inline code completion to a sliding window of approximately 2,048 to 4,096...
- Copilot Prompt Limit: Caps, Truncation, and Context WorkaroundsThe Copilot prompt limit restricts inputs to 2,000 characters for anonymous users and 4,000 characters for personal...
- OpenAI Codex Context Window: Token Limits and Codebase IndexingThe OpenAI Codex context window defines the maximum number of tokens an agentic coding model can process simultaneously...
- Cursor Context Limit: Token Sliders, Request Caps, and External WorkspacesThe Cursor context limit sets token boundaries across prompts, indexing, and chat history. While frontier models...
- OpenAI Codex Token Limits: Context Windows, Request Caps, and WorkaroundsThe Codex token limit refers to the maximum number of prompt and generation tokens permitted in a single OpenAI Codex...
- How to Connect OpenAI Codex Agents to SharePoint Document LibrariesConnecting OpenAI Codex to SharePoint allows autonomous coding agents to query enterprise architecture documentation,...
More on this subject: AI Coding Assistants (86 guides)
Why Agent Execution Loops Cause Rapid Context Bloat
Treating Codex as an interactive conversational bot hides the real danger of token exhaustion. In an autonomous agent execution loop, Codex acts as an iterative operator: it inspects code, proposes patches, executes commands in the local shell, parses stdout and stderr, and decides its next move based on command exit codes.
Each step in this execution loop appends data to the session history. Because the model requires conversational continuity to evaluate whether a fix succeeded, previous steps remain inside the active context window. In complex refactoring tasks, terminal logs and multi-file diffs can consume 50,000+ tokens in fewer than five agent execution loops.
+-------------------------------------------------------------------+
|                     Agent Execution Loop                          |
|                                                                   |
|   +------------------+         +------------------------------+   |
|   | 1. Read Files    | ------> | 2. Propose Unified Diff      |   |
|   | (Source context) |         | (Code changes appended)      |   |
|   +------------------+         +------------------------------+   |
|            ^                                  |                   |
|            |                                  v                   |
|   +------------------+         +------------------------------+   |
|   | 4. Parse Errors  | <------ | 3. Execute Terminal Command  |   |
|   | (Token bloat)    |         | (Stdout/Stderr captured)     |   |
|   +------------------+         +------------------------------+   |
+-------------------------------------------------------------------+
Anatomy of Rapid Session Saturation
Four distinct data streams drive context bloat during an active coding session:
- Unfiltered Test Suites: Running a command like
npm testorpytestacross an entire repository can emit thousands of lines of output. A single stack trace containing recursive module resolutions, mock assertions, and runtime warnings frequently dumps 8,000 to 15,000 tokens into the session buffer in a single execution. - Multi-File Unified Diffs: When Codex refactors shared interfaces or updates type signatures across multiple modules, the resulting patch diff contains both modified lines and surrounding context blocks. Across ten files, a unified diff can easily add 20,000 tokens to the context buffer.
- Lockfile and Package Manifest Dumps: If an agent attempts to diagnose a dependency mismatch by reading lockfiles like
package-lock.jsonorpnpm-lock.yaml, it can instantly ingest 30,000 to 80,000 tokens of raw structure. - Recursive Directory Listings: Commands like directory walks in projects containing deep directory structures flood the context window with file paths that provide minimal structural value.
Context Rot and Attention Degradation
Token exhaustion does not merely cause hard session aborts; it causes subtle cognitive failures before reaching the 272,000-token cap. This degradation pattern is known as context rot.
As the context window fills with lengthy terminal logs and outdated diff chunks, the model's attention mechanism suffers from dilution. Critical instructions delivered in the initial prompt get buried beneath hundreds of lines of compiler errors. When this happens:
- Forgotten Architectural Constraints: The agent begins proposing code that violates patterns specified in the initial prompt, such as introducing forbidden external libraries or reverting previous architectural decisions.
- Hallucinated Dependencies: Overwhelmed by stale build logs, Codex frequently invents helper functions or package imports that do not exist, attempting to resolve errors through guesswork.
- Cyclic Debugging Loops: The agent modifies a file, runs a test, encounters an error, reverts its change, and tries the exact same modification three turns later because the original failure rolled out of immediate attention focus.
Stop Losing Codex Context to Terminal Output
Connect your autonomous coding sessions to an indexed Fast.io workspace. Search repository files over MCP instead of dumping raw text into prompt buffers. Start with a 14-day free trial.
Checklist for Preventing Codex Context Bloat
Managing the codex agent token limit requires proactive command hygiene and disciplined context allocation. Rather than letting the agent run unconstrained terminal commands, implement systematic constraints to keep active memory focused on the core engineering objective.
1. Truncate and Filter Shell Command Output
Never allow an agent to run open-ended test runners or directory scans. Wrap test invocations in filters that isolate failure lines while stripping verbose execution traces.
For JavaScript and TypeScript environments, pass quiet flags and target only failing suites:
npm test -- --bail --silent 2>&1 | head -n 25
The command above suppresses passing tests and caps the output stream to the first 25 error lines. For Python projects, configure pytest to suppress passed tests and truncate local variables in tracebacks:
pytest -q --tb=short -x
2. Scope File Inspection to Targeted Line Ranges
Autonomous agents often default to reading entire files into context, even when modifying a single function. A 1,500-line service file consumes approximately 4,000 tokens each time it is loaded into the prompt.
Instruct the agent to use targeted inspection tools:
- Inspect file structure using symbol outlines rather than raw text dumps.
- Read specific line intervals around the target edit point using range flags.
- Maintain an exclusion file such as
.codexignorecontaining build outputs, coverage summaries, minified bundles, and lockfiles.
3. Check Token Budgets and Trigger Manual Compaction
Do not wait for the runtime to hit its 272,000-token ceiling and trigger emergency truncation. Monitor session status regularly.
In the Codex CLI, run /status to view active token consumption across input prompt, conversational history, and tool outputs. When session memory approaches 150,000 tokens, review the working state:
- Commit working code changes to git before continuing.
- Run
/compactto summarize completed milestones and discard raw terminal output from passing intermediate steps. - If a major implementation milestone is complete, exit the session and start a clean Codex session focused on the next component. Review the agent onboarding guide for instructions on maintaining clean handoff state.
4. Decouple Static Reference Documents from Prompt Buffers
The most avoidable source of context bloat is loading static documentation, API references, and architectural specifications directly into agent memory. Storing internal engineering standards, third-party SDK manuals, and schema definitions in the active prompt wastes valuable working memory.
Moving static documentation to an external index and querying it on demand preserves the active context window for working code, tests, and diffs.
How Fast.io and MCP Retrieval Decouple Repository Knowledge
The architectural solution to agent context limits is decoupling working memory from reference storage. A coding agent should not hold an entire corporate codebase or complete API specifications in its prompt buffer. It needs an external retrieval layer that surfaces exact code blocks and documentation snippets when needed.
The Model Context Protocol (MCP) provides the standard open interface for connecting coding agents to external knowledge bases. Rather than attaching entire reference manuals to a session, the agent queries an MCP server to retrieve relevant fragments.
Fast.io provides an intelligent cloud workspace platform where teams and agents share organized repositories, documentation sets, and design specs. Instead of blowing past the Codex session context limit by pasting raw documentation, engineering teams store reference materials in a Fast.io workspace.
+-------------------+                   +----------------------------+
|  OpenAI Codex     |                   |  Fast.io Cloud Workspace   |
|  (Active Session) |                   |  (Intelligence Mode)       |
|                   |                   |                            |
|  Working Memory:  |   MCP Search      |  - Architectural Specs     |
|  - Active Task    | ----------------> |  - API Schemas             |
|  - Recent Diffs   | <---------------- |  - SDK Documentation       |
|  - Filtered Logs  |   Targeted Snippet|  - Legacy Repositories     |
+-------------------+                   +----------------------------+
How Intelligence Mode and Semantic Search Eliminate Bloat
When you upload technical documentation, architectural decision records, or codebase mirrors to a Fast.io workspace, enabling Intelligence Mode indexes the content automatically for hybrid search.
Fast.io's hybrid search combines full-text keyword matching, semantic vector indexing, and metadata extraction. When Codex encounters an unfamiliar internal library or needs to verify an API payload, it calls the MCP search tool:
- Targeted Query: Codex issues a semantic query for the specific endpoint or interface schema.
- Ranked Snippet Extraction: Fast.io searches the indexed workspace files and returns the exact 30-line schema definition rather than a 500-page PDF or 10,000-line markdown file.
- Context Preservation: Codex absorbs fewer than 300 tokens into its working window, leaving over 250,000 tokens available for code implementation, test verification, and debugging.
Connecting OpenAI Codex to Fast.io MCP
You can connect OpenAI Codex to Fast.io using either the plugin directory or a custom MCP connector. Both routes communicate over Streamable HTTP.
Option 1: The Fastio Plugin (Preferred)
Fastio is available in the ChatGPT plugin directory, and the same plugin connects to Codex. In the Codex CLI, install the plugin directly:
codex plugin add fast-io@openai-curated-remote
Alternatively, open /plugins in the Codex interface and select Fastio. When prompted, complete the OAuth sign-in in your browser. Review the permission screen to select Read Only or Read & Write access and specify the organizations and workspaces Codex can reach.
Option 2: Custom MCP Server Setup
If your workspace environment restricts plugin installations or if you use the Codex IDE extension, configure Fast.io as a custom MCP server:
codex mcp add fastio --url https://mcp.fast.io/mcp/operations
codex mcp login fastio
The server URL https://mcp.fast.io/mcp/operations handles operations for ChatGPT and Codex environments. Interactive clients complete authentication via OAuth in the browser. For headless agent environments, servers, or continuous integration workers where browser login is unavailable, pass your scoped API key as an HTTP header:
Authorization: Bearer <your-fastio-api-key>
For complete connection workflows and client specifications, consult the official Fast.io MCP setup documentation and the Fast.io MCP skill reference.
Live Retrieval in Action: Inspecting Schemas Without File Ingestion
Consider an autonomous task where Codex must implement a webhook receiver matching an internal enterprise event schema. Without an external index, a developer must either copy the entire event specification into the prompt or instruct Codex to read a massive markdown file from disk.
With Fast.io MCP connected, Codex executes a targeted search:
{
  "query": "payment_intent.succeeded webhook payload schema",
  "files_scope": ["specifications/webhooks/"]
}
Fast.io returns the exact TypeScript interface matching the query. Codex incorporates the 25-line interface into its active buffer, implements the controller, and runs the test suite without triggering context compaction or losing the original prompt instructions.
Managing Multi-Agent Workspaces and Persistent Context Boundaries
Modern software engineering increasingly relies on multiple agents collaborating across shared codebases. A developer might run Codex in a terminal for rapid feature development, Claude Code in another window for architectural refactoring, and automated background agents for continuous testing.
If each agent maintains isolated file storage on a local machine, context fragmentation occurs immediately. One agent modifies a file without the other's knowledge, resulting in merge collisions, duplicate token consumption, and corrupted workspace state.
Fast.io serves as the central coordination layer where humans and autonomous agents collaborate within shared, org-owned workspaces.
Advisory File Locks and Version History
When multiple agents interact with the same workspace, write coordination prevents conflicting edits. Fast.io provides advisory per-file leases through its MCP toolset:
- Acquiring a Lock: An agent acquires a lease on a target file using the
lock-acquireaction on thestorage_managetool before starting a multi-file refactoring sequence. - Heartbeating Leases: The agent maintains the lease while performing edits. If the agent crashes or exceeds its token limit, the lease expires automatically.
- Releasing Locks: Once the edits are complete, the agent calls
lock-releaseonstorage_manage. Other agents and team members can inspect active leases via thelock-statusaction on thestoragetool.
Because Fast.io locks are advisory, concurrent writes do not cause hard data loss. Every file in a workspace maintains complete per-file version history. If an agent hallucinates a change or overwrites critical logic, developers can restore previous revisions with a single click or API call.
The Detailed Activity Log
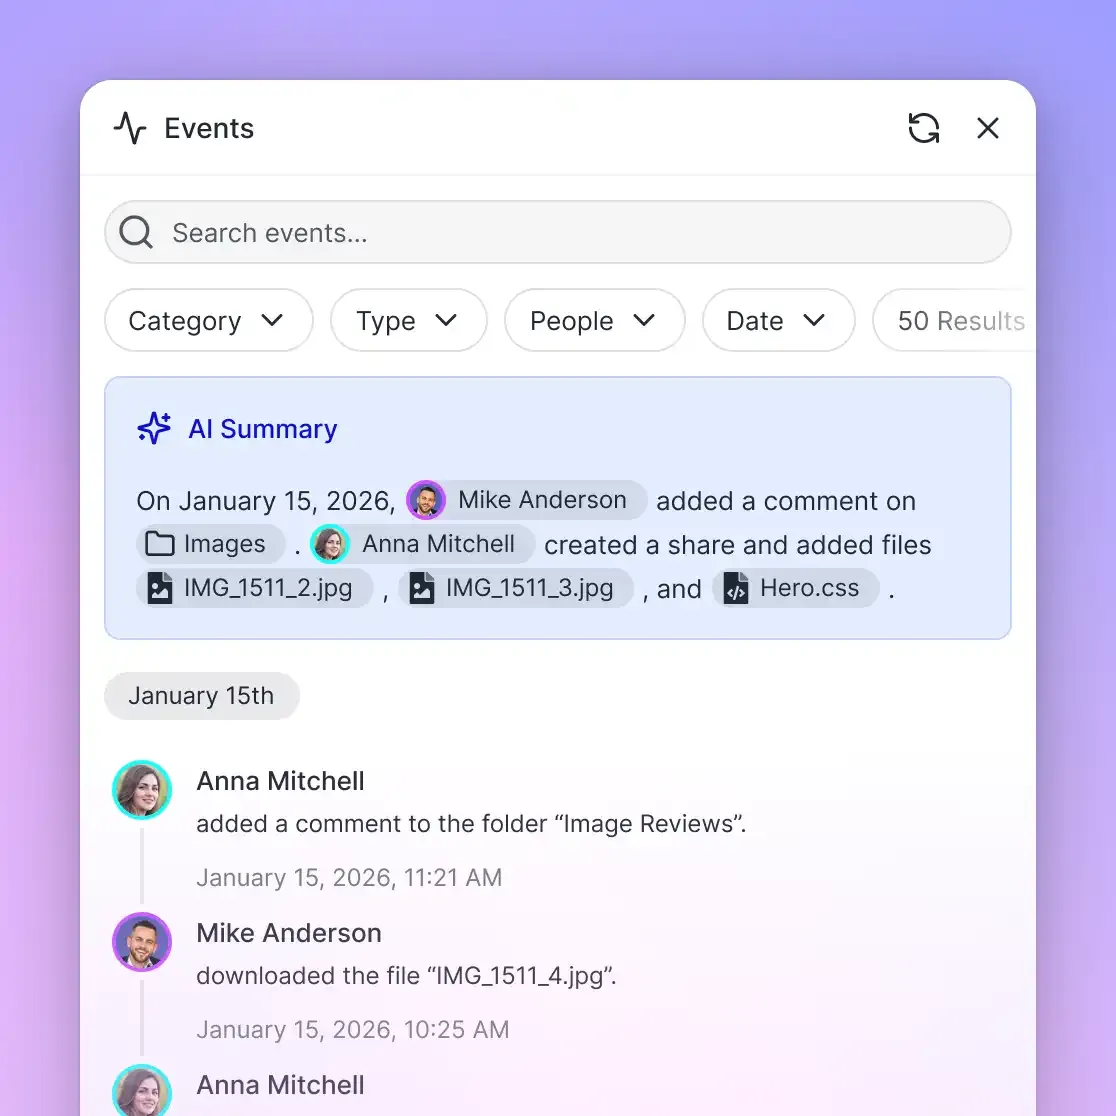
Fast.io maintains a detailed activity log of all modifications across an organization. The activity log records every file upload, edit, move, deletion, permission update, and share creation, attributing actions to specific team members or agent credentials.
Importantly, the activity log is a record of changes, not an access monitor. It does not record read-only events such as file previews, views, or downloads. For engineering teams deploying autonomous agents, this provides an auditable history of exactly which agent modified a source file, created a test fixture, or updated an environment template.
Unified Cloud Sync Across Ecosystems
Development teams rarely keep all project assets in a single directory. Specifications often live in Google Drive, design exports in Dropbox, client contracts in Box, and enterprise documentation in OneDrive for work or school.
Fast.io Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. Rather than writing brittle scripts to download files locally and feed them into agent prompts, Cloud Sync centralizes assets into an indexed workspace. Once synced, Codex queries the entire asset library via MCP.
Transparent Plans and Onboarding
Fast.io structures pricing around organizations and workspaces. Monthly plans start with a 14-day free trial that requires a credit card and ends early if trial credits run out; annual plans have no trial. Plans are Starter at $9.99/mo ($99 billed annually with 3 seats, 250 GB storage, 5 workspaces, 100,000 credits a month), Business at $49.99/mo ($499 billed annually with 10 seats, 5 TB storage, 50 workspaces, 600,000 credits a month), and Enterprise at $199.99/mo ($1,999 billed annually with 30 seats included, 25 TB storage, 200 workspaces, 3,000,000 credits a month). Maximum upload size per file is 25 GB on Starter, 50 GB on Business, and 100 GB on Enterprise. Credits meter AI work only, with overage at $10 per 100,000 credits. Storage beyond the plan is $0.015 per GB a month and extra bandwidth $0.04 per GB; see Fast.io pricing for full plan comparisons.
Engineering teams can evaluate Fast.io's remote MCP indexing and shared workspace features during the 14-day free trial, connecting Codex and other agent runtimes without upfront infrastructure commitments.
Sources
References used to verify factual claims in this guide.
-
OpenAI reduced the Codex CLI context window to a 272,000-token cap, representing a roughly 27% reduction from previously documented limits.
Frequently Asked Questions
What is the context limit for OpenAI Codex?
The OpenAI Codex CLI enforces a default server-side context limit of 272,000 tokens. While frontier foundation models publish expanded context windows in raw API specifications, the Codex runtime caps active sessions at 272,000 tokens to control latency, manage infrastructure costs, and prevent accidental transitions into higher billing tiers. After accounting for system prompts, safety rails, and tool schemas, an active session provides roughly 258,400 usable tokens.
How do autonomous coding agents manage context window limits?
Autonomous coding agents manage context limits through automated compaction, sliding window summarization, and command output truncation. When active token consumption nears the runtime threshold, the agent environment compresses earlier conversational turns and replaces detailed execution logs with concise text summaries. However, aggressive compaction can cause attention degradation, leading developers to rely on external retrieval layers such as MCP servers to store static documentation and code libraries outside the prompt buffer.
How can I prevent Codex from running out of context tokens?
To prevent Codex from exhausting its context window, filter terminal outputs using utilities like head and quiet test runner flags. Scope file reading to targeted symbol ranges instead of loading full modules. Maintain a .codexignore file to exclude minified bundles, lockfiles, and build artifacts. Monitor token consumption with the /status command, and manually run /compact after major milestones. Finally, connect external documentation and reference code via Fast.io MCP rather than loading files directly into session memory.
What happens when an OpenAI Codex session exceeds its token limit?
When a session reaches the 272,000-token cap in the Codex CLI, the runtime triggers emergency compaction, pruning early conversation turns to create space for new tokens. If the prompt and requested diff exceed the capacity even after compaction, the tool halts execution and returns a context overflow error. In direct API workflows, exceeding model limits returns an invalid_request_error HTTP 400 response.
How does MCP retrieval reduce Codex context consumption?
Model Context Protocol (MCP) retrieval reduces context consumption by replacing bulk file ingestion with precision semantic search. Instead of loading an entire repository or 500-page API manual into prompt memory, the agent queries a remote MCP server like Fast.io. Fast.io searches indexed documents and returns only the exact 20 to 50 lines relevant to the current task, consuming a few hundred tokens instead of tens of thousands.
Does Fast.io sync repository files with external cloud storage?
Yes. Fast.io Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to workspaces. Sync can be configured one-way or two-way, running on a scheduled interval or triggered on demand. This allows engineering teams to keep specifications, assets, and reference code in their primary cloud storage while giving Codex and other MCP agents indexed, searchable access.
Related Resources
Stop Losing Codex Context to Terminal Output
Connect your autonomous coding sessions to an indexed Fast.io workspace. Search repository files over MCP instead of dumping raw text into prompt buffers. Start with a 14-day free trial.