n8n File Size Limits: How to Handle Large Files and Payloads Without Crashing
The n8n file size limit is the maximum payload threshold, governed by the N8N_PAYLOAD_SIZE_MAX environment variable with a default of 16 MiB, that an n8n workflow can ingest or transfer in a single execution. When automations stream massive binary files into memory, self-hosted instances risk crashing from Node.js heap exhaustion. This guide explains how to adjust payload caps, switch storage modes, and offload heavy files to intelligent workspaces to keep automations reliable.

How the n8n File Size Limit Enforces Payload Ceilings
Every incoming webhook, package import, and HTTP trigger in a default n8n deployment is capped at 16 MiB by the N8N_PAYLOAD_SIZE_MAX environment variable. When an incoming file, API response, or multipart form upload exceeds this ceiling, the workflow halts with an HTTP 413 Payload Too Large response before execution begins.
The n8n file size limit is the maximum payload threshold, governed by the N8N_PAYLOAD_SIZE_MAX environment variable with a default of 16 MiB, that an n8n workflow can ingest or transfer in a single execution.
To troubleshoot and scale workflows effectively, automation engineers must distinguish between the different layers where file size restrictions are enforced. The default payload ceiling applies specifically to incoming HTTP network traffic arriving at n8n endpoints, including:
- Webhook Trigger Nodes. When an external service or front-end form posts files or JSON payloads directly to an n8n webhook URL, n8n parses the body using internal web server middleware. If the raw body size surpasses the configured maximum, the request is rejected immediately at the network edge.
- Webhook Test Listeners. When testing workflows inside the n8n editor canvas, the manual test webhook listener enforces the identical 16 MiB ceiling. Developers testing large sample files often receive a 413 error in their browser console or testing client without any execution log appearing in the n8n execution history.
- Package and Workflow Imports. Uploading workflow bundles or community node archives through the n8n administrative interface is subject to the same payload ceiling. Compressed archives containing embedded binary assets or extensive execution histories will trigger an upload failure if they exceed the maximum payload threshold.
- Production API Endpoints. The public n8n REST API endpoints used to trigger workflows or manage instance resources share this global incoming payload limit.
The following table summarizes the primary file size and payload thresholds across n8n subsystems:
The 16 MiB default is intentionally conservative. Because n8n runs on Node.js, parsing large incoming request bodies directly into memory buffers creates sudden spikes in resident set size. For instances running on entry-level virtual private servers with limited host memory, allowing unconstrained payload sizes causes the operating system to terminate the process under moderate traffic.
Related guides
- Claude Code File Size Limits: CLI Truncation and Large File HandlingClaude Code imposes strict operational file size limits in the terminal, truncating file reads and command outputs past...
- Copilot File Upload Limits, Formats, and Workarounds for Large FilesThe Copilot file upload limit restricts direct document attachments to 10 MB per file across standard chat interfaces,...
- How to Connect n8n Workflow Agents to SharePoint FilesAn n8n SharePoint integration links workflow automation pipelines and AI agent nodes with Microsoft SharePoint document...
- ChatGPT Max File Size: The 512 MB Upload Limit Across PlansChatGPT enforces a strict maximum file size limit of 512 MB per uploaded file across all subscription plans, alongside...
- AWS Lambda File Size Limits: Payload, Package, and Ephemeral Storage CapsAn AWS Lambda file size limit encompasses the execution constraints of AWS Lambda functions, specifically the 50MB...
- ChatGPT PDF Limit: File Size, Page Count, and Large Document WorkaroundsThe ChatGPT PDF limit enforces a 512MB file size ceiling, a 2 million token extraction threshold, and a restriction of...
More on this subject: Agent File and Document Workflows (269 guides)
Why Node.js Heap Exhaustion Crashes Heavy Automations
The most common advice shared in community forums when users encounter an HTTP 413 error is simple: raise N8N_PAYLOAD_SIZE_MAX to a higher number in the environment configuration. While this change stops the immediate 413 response from the webhook listener, it introduces a severe operational vulnerability in self-hosted deployments.
Raising the payload ceiling without modifying how n8n manages binary data in execution memory creates an in-memory bottleneck that regularly leads to container crashes.
Node.js executes JavaScript within the Google V8 engine, which allocates a private heap for runtime objects, strings, and execution scopes. On standard 64-bit platforms, Node.js historically bounds old-space memory allocation unless developers adjust heap parameters via --max-old-space-size. When an automation ingests a multi-megabyte file, that data must be managed within this constrained memory pool alongside the n8n application code, node definitions, and active execution trees.
Several factors cause memory consumption to expand rapidly beyond the initial file size:
- Data Duplication Across Nodes. Workflows are designed as linear or branching sequences of functional nodes. When an automation moves data from a Webhook node to an Edit Fields node, Code node, or HTTP Request node, JavaScript frequently duplicates object references or creates intermediate buffer copies. A single large file passed through three sequential transformation nodes can consume hundreds of megabytes of heap memory within seconds.
- Base64 Encoding Expansion. In many workflow patterns, nodes convert raw binary streams into base64 strings to manipulate data inside JSON payloads or transmit content to REST APIs. Base64 encoding expands the raw binary footprint, creating a much larger string representation in JavaScript memory that increases pressure on the garbage collector.
- Concurrent Execution Spikes. In production environments, automations rarely run in complete isolation. If an instance receives multiple concurrent incoming webhook requests each uploading a substantial document, the combined memory required for active buffers, string representations, and node execution states quickly exceeds available container limits.
- Garbage Collection Latency. The V8 garbage collector must pause execution cycles to inspect and free unreferenced heap objects. Under heavy data allocation rates, garbage collection cycles fall behind incoming memory allocations, causing heap memory to climb monotonically until the process boundary is reached.
When memory consumption hits the V8 threshold, Node.js terminates execution with a fatal error: FATAL ERROR: Reached heap limit Allocation failed - JavaScript heap out of memory.
Because n8n operates as a single Node.js process in standard single-container setups, this crash terminates the entire application. The container daemon or orchestrator detects an abrupt termination (exit code 137), tearing down the container. Every concurrent workflow execution is immediately aborted, scheduled triggers miss their execution windows, and any pending webhook calls receive connection reset errors. Increasing N8N_PAYLOAD_SIZE_MAX without offloading file storage simply shifts the failure from a predictable HTTP 413 error to an unrecoverable process crash.
How to Configure Filesystem Storage for n8n Binary Data
To prevent heavy binary payloads from exhausting the Node.js V8 heap, self-hosted n8n instances must be configured to store binary data outside of process memory. The n8n architecture provides dedicated environment variables to control binary data storage locations and execution lifecycle policies.
The primary setting governing binary data persistence is N8N_DEFAULT_BINARY_DATA_MODE. In legacy n8n installations, binary properties were retained in RAM buffers. Configuring filesystem mode instructs n8n to stream binary attachments directly to a designated local directory on disk, holding only a lightweight file descriptor in workflow memory:
version: "3.8"
services:
  n8n:
    image: docker.n8n.io/n8nio/n8n:latest
    restart: unless-stopped
    ports:
      - "5678:5678"
    environment:
      - N8N_HOST=n8n.example.com
      - N8N_PORT=5678
      - N8N_PROTOCOL=https
      - NODE_ENV=production
      - WEBHOOK_URL=https://n8n.example.com/
      - N8N_PAYLOAD_SIZE_MAX=128
      - N8N_DEFAULT_BINARY_DATA_MODE=filesystem
      - N8N_BINARY_DATA_STORAGE_PATH=/home/node/.n8n/binaryData
      - EXECUTIONS_DATA_PRUNE=true
      - EXECUTIONS_DATA_MAX_AGE=168
      - EXECUTIONS_DATA_PRUNE_MAX_COUNT=50000
      - NODE_OPTIONS=--max-old-space-size=4096
    volumes:
      - n8n_data:/home/node/.n8n
      - /opt/n8n/binary_storage:/home/node/.n8n/binaryData
volumes:
  n8n_data:
In this production configuration, four critical adjustments work together to maintain stability:
- Payload Ceiling Alignment.
N8N_PAYLOAD_SIZE_MAXis expanded to a higher value. This allows the webhook listener to accept larger document uploads, media files, and archive packages without returning HTTP 413 errors. - Filesystem Streaming. Setting
N8N_DEFAULT_BINARY_DATA_MODE=filesystemensures that incoming file payloads are streamed directly to/home/node/.n8n/binaryData. Node.js stores only metadata and file pointers on the heap, preventing memory spikes during multi-node workflows. - Automated Binary Pruning. Without pruning, processing large files on disk will rapidly consume local storage. Setting
EXECUTIONS_DATA_PRUNE=truewith an age threshold of 168 hours (7 days) and a count limit ensures that obsolete binary files and historical execution states are routinely purged from disk. - Node Heap Allocation. Specifying
NODE_OPTIONS=--max-old-space-size=4096expands the V8 heap boundary, providing sufficient breathing room for complex data transformations, JSON manipulations, and concurrent workflow executions.
Engineers must also verify their upstream reverse proxy settings. If your n8n instance sits behind Nginx, the default client_max_body_size is restrictive. Even if n8n is configured to accept larger payloads, Nginx will intercept the request and return an HTTP 413 error before the payload reaches the container. You must update your Nginx configuration block:
server {
    server_name n8n.example.com;
    client_max_body_size 128M;
    location / {
        proxy_pass http://127.0.0.1:5678;
        proxy_set_header Connection '';
        proxy_http_version 1.1;
        chunked_transfer_encoding off;
        proxy_buffering off;
        proxy_cache off;
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;
    }
}
While filesystem mode resolves local container memory exhaustion, it encounters significant friction as organizations scale. In distributed deployments running n8n in queue mode with multiple worker containers, workers running on separate hosts cannot access local disk paths without configuring shared Network File System (NFS) mounts. Alternatively, setting N8N_DEFAULT_BINARY_DATA_MODE=database forces binary files into PostgreSQL columns, leading to database bloat, write-ahead log saturation, and degraded backup performance. For production automation pipelines, passing raw multi-megabyte files through workflow nodes remains an architectural anti-pattern.


Handle Large File Workflows Without Crashing Your Automations
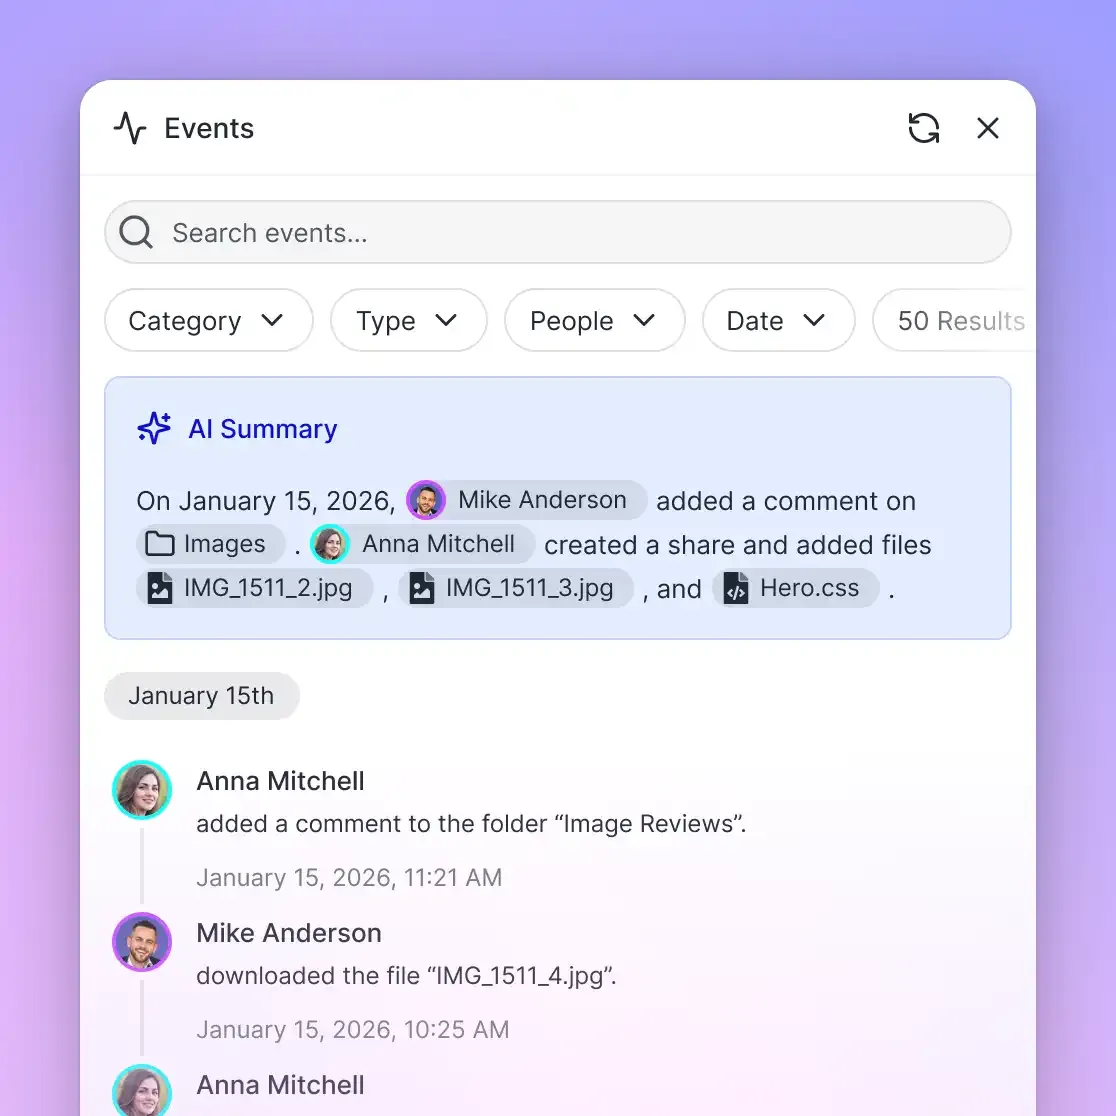
Store heavy assets in an intelligent Fast.io workspace, query indexed content remotely via MCP, and pass lightweight file references through n8n. Start your 30-day free trial today.
How to Manage Large File Workflows Using Fast.io Workspaces
The reliable design pattern for high-volume file automations is the claim-check pattern, also known as passing file references. Instead of piping multi-megabyte binary files directly through webhook requests, node branches, and API payloads, workflows store heavy assets in an intelligent cloud workspace and pass lightweight JSON references through the automation canvas.
Fast.io provides shared org-owned workspaces equipped with per-file version history, granular access controls, a detailed activity log, and native Intelligence Mode. You can populate workspaces by uploading files directly, or sync reference documents from Dropbox, Box or OneDrive. Google Drive imports today with sync coming soon, enabling teams to aggregate documents, media, and datasets into a centralized context layer.
When Intelligence Mode is enabled on a Fast.io workspace, every ingested file is automatically indexed for hybrid search, combining full-text keyword indexing with semantic vector retrieval. Workflows no longer need to download an entire technical specification or multi-page operational manual into memory to extract relevant data. Instead, the automation connects to Fast.io and retrieves only the exact paragraphs relevant to the task.
Workflows interact with Fast.io through the remote Model Context Protocol (MCP) server or the REST API. The MCP server runs at https://mcp.fast.io/mcp/tools over Streamable HTTP, with headless workflows sending an Authorization: Bearer <api key> header on the connection. Complete tool documentation is available at https://mcp.fast.io/skill.md, and integration patterns are documented on Fast.io for Agents.
In n8n, you can query a Fast.io workspace directly from an HTTP Request node or an AI Agent node using standard REST endpoints at https://api.fast.io/current/:
{
  "method": "GET",
  "url": "https://api.fast.io/current/workspace/{{ $json.workspace_id }}/storage/search/",
  "headers": {
    "Authorization": "Bearer {{ $env.FASTIO_API_KEY }}",
    "Content-Type": "application/json"
  },
  "qs": {
    "search": "Quarterly vendor compliance requirements",
    "files_scope": "{{ $json.compliance_document_id }}"
  }
}
This reference architecture delivers four operational advantages over streaming raw binary data:
- Eliminating Node.js Memory Spikes. The n8n workflow passes a lightweight JSON payload containing the workspace identifier and query string. The heavy PDF document remains safely stored and indexed in the Fast.io workspace, eliminating V8 heap pressure and container crash risks.
- Preserving Large Language Model Context Quality. In AI agent workflows, dumping entire files into an LLM context window causes attention attenuation and lost-in-the-middle degradation, where models overlook critical instructions placed between massive blocks of text. Fast.io performs semantic chunking on cloud infrastructure, returning focused text excerpts that keep prompt token counts minimal and reasoning accurate.
- Chunked Upload Ingestion. While standard HTTP requests struggle when receiving oversized files in one continuous connection, Fast.io supports chunked uploads, allowing automations, agents, and external applications to ingest large files in discrete fragments without exceeding network buffers or timeout limits.
- Team-Wide Versioning and Auditing. When an automation generates an updated document, it writes back to the workspace where per-file version history preserves every revision. If a workflow introduces an invalid modification, human operators can inspect version diffs and restore earlier states immediately.
Extracting Structured Document Data with Metadata Views
Many automated business processes involve semi-structured documents: vendor invoices, employment agreements, regulatory filings, and shipping manifests. In conventional automation designs, developers configure complex OCR pipelines or multi-step regex parsers inside n8n to extract key fields. When processing large multi-page scans, running these parsing steps inside workflow memory compounds CPU usage and increases out-of-memory risks.
To solve this operational challenge, Fast.io provides Metadata Views. Metadata Views turn unstructured documents into a live, queryable database. Users describe the fields they need extracted in natural language, and the platform automatically creates a typed schema supporting text, integer, decimal, boolean, URL, JSON, and date values.
Fast.io matches files across the workspace and populates a filterable spreadsheet view without requiring manual OCR templates or brittle extraction rules. Instead of downloading a massive scanned PDF into n8n to locate a single invoice total or contract counterparty, an n8n workflow executes a lightweight query against the Metadata View via MCP or the REST API:
{
  "tool": "fastio_query_metadata_view",
  "arguments": {
    "view_name": "Vendor_Invoices_2026",
    "filter": "status == 'Pending_Approval' && invoice_amount > 10000"
  }
}
The workflow receives clean, typed JSON attributes ready for immediate routing, database updating, or messaging dispatch. New columns can be added to an existing Metadata View at any time without reprocessing files.
Beyond automated data extraction, Fast.io provides the governance features necessary for mission-critical automation systems:
- Append-Only Audit Log. Every document upload, read operation, metadata extraction, and export action is recorded with identity attribution and precise timestamps. Teams maintain a complete, immutable audit trail of automated actions alongside human activity.
- Collaborative Notes. Human team members and autonomous agents can co-edit architecture decision records, workflow runbooks, and schema specifications within shared, real-time documents.
- Scoped Ownership Transfer. Agencies, automation consultants, and managed service providers can build client workspaces, configure Metadata Views, connect n8n workflows, and transfer organizational ownership to the client upon project completion while retaining administrative permissions.
- Real-Time Activity Monitoring. Workflows and monitoring agents can subscribe to workspace activity feeds over WebSocket connections or long-poll requests (
GET /current/activity/poll/{entity_id}), triggering downstream automations as soon as files are uploaded, modified, or extracted.
Implementing this hybrid architecture is straightforward. Every organization starts with a 30-day free trial, which requires a credit card. Plans are Starter at $29/mo, Business at $99/mo, and Enterprise at $299/mo, delivering scalable storage, Intelligence Mode indexing, and remote MCP connectivity. You can review detailed plan specifications on the pricing page.
Sources
References used to verify factual claims in this guide.
-
The default maximum payload size for n8n endpoints is 16 MiB, which can be adjusted using the N8N_PAYLOAD_SIZE_MAX environment variable.
Frequently Asked Questions
What is the default file size limit in n8n?
The default payload limit for incoming HTTP requests and webhooks in n8n is 16 MiB, controlled by the N8N_PAYLOAD_SIZE_MAX environment variable. Requests exceeding this threshold receive an immediate HTTP 413 Payload Too Large response before workflow execution begins.
How do I fix the HTTP 413 Payload Too Large error in n8n?
To resolve the 413 error in a self-hosted instance, increase the N8N_PAYLOAD_SIZE_MAX environment variable in your docker-compose.yml file and restart the n8n container. Additionally, ensure that your upstream reverse proxy, such as Nginx or Traefik, is configured with a matching upload limit like client_max_body_size.
How do I process large files in n8n without running out of memory?
To prevent out-of-memory crashes, set N8N_DEFAULT_BINARY_DATA_MODE to filesystem in your environment settings so binary files stream directly to disk rather than remaining in the Node.js V8 heap. For large-scale production pipelines, offload files to an external workspace like Fast.io and pass lightweight file identifiers or metadata references through workflow nodes.
Why does n8n crash when processing multiple large files simultaneously?
When n8n runs in default in-memory mode, passing files between nodes creates duplicate buffer copies in the V8 JavaScript heap. Under concurrent execution, multiple simultaneous uploads quickly push heap consumption past the process limit, prompting the Node.js runtime to terminate abruptly with exit code 137.
Can reverse proxies like Nginx or Cloudflare block large n8n uploads?
Yes. Reverse proxies enforce independent body size restrictions. Nginx enforces an unconfigured default body limit unless client_max_body_size is adjusted, while Cloudflare proxy tiers enforce upload ceilings on incoming HTTP requests.
How does Fast.io help n8n workflows handle large reference corpuses?
Fast.io stores files in shared cloud workspaces and automatically indexes them for hybrid keyword and semantic search using Intelligence Mode. Instead of ingesting heavy binary files into n8n memory or LLM prompts, workflows connect to Fast.io via MCP to retrieve only the specific text passages or structured metadata needed for execution.
Related Resources

Handle Large File Workflows Without Crashing Your Automations
Store heavy assets in an intelligent Fast.io workspace, query indexed content remotely via MCP, and pass lightweight file references through n8n. Start your 30-day free trial today.