Cursor Context Window: Token Limits, Long-Context Chat, and MCP Workspaces
The Cursor context window defines the token boundary allocated for project code, conversation history, and codebase embeddings during editing sessions. When conversations reach this token ceiling, reasoning quality degrades through instruction drift and hallucinated imports. This guide examines how Cursor allocates context across frontier models, how codebase indexing retrieves relevant chunks, and how connecting to remote Fast.io MCP workspaces offloads large document collections.

How the Cursor Context Window Allocates Model Memory
When an editing session in Cursor reaches its context window ceiling, the editor does not halt with a clean warning. Instead, the model silently degrades: it drops earlier architectural constraints, hallucinates file imports, and repeats failed edits because earlier tokens are evicted to accommodate newly generated logs and file contents. Every interaction with an artificial intelligence model in Cursor is bounded by this finite memory buffer.
The Cursor context window is the token boundary (typically 128k to 200k tokens depending on the chosen model) allocated for project code, chat history, and semantic codebase embeddings during editing sessions.
To understand how this boundary functions, developers must look at what competes for memory during an interactive session. The context window is not reserved exclusively for the code currently displayed on your screen. In practice, Cursor splits available token capacity across five distinct categories:
- Foundational system prompts and tool schemas. Before a user types a single character, Cursor injects instructions that define how the agent formats diffs, reasons through problems, and interacts with developer tools. Model Context Protocol (MCP) server definitions and terminal execution tools consume thousands of tokens upfront.
- Active conversation history. Every turn in chat, including user requests, intermediate thoughts, and agent explanations, remains in memory for subsequent turns. Multi-turn debugging sessions accumulate token overhead quickly.
- Explicit file attachments. Files attached via @file or @folder tags, as well as active editor tabs, are injected directly into the prompt payload. A single 1,000-line TypeScript file can consume 4,000 to 6,000 tokens.
- Codebase retrieval chunks. When Cursor searches your repository to answer a query, it extracts relevant snippets using vector embeddings and lexical search, injecting those segments into the prompt.
- Execution feedback and diagnostics. Terminal outputs, compiler stack traces, and linter errors returned during test execution are appended to the context so the model can inspect its work.
The table below outlines the default context windows and maximum context limits across frontier models available in Cursor as of September 2026:
Cursor extends context window token limits and model tokens on legacy plans through Max Mode billed at the model API rate plus 20%. On modern plans, users choose between the default context allocation and extended context modes when working with long documents or massive file sets. However, expanding the window does not automatically guarantee better reasoning, as larger contexts introduce cognitive degradation.
Why Long-Context Chat Degrades During Complex Refactors
Expanding an artificial intelligence model's context window from 128k to 200k or even 1M tokens seems like an easy fix for complex projects. Many developers assume that if an entire module fits inside the window, the model can refactor it accurately in a single pass. In production environments, this assumption regularly fails.
The primary limitation of long-context chat is attention attenuation, commonly known as the lost-in-the-middle phenomenon. Modern transformer models pay high attention to tokens positioned near the beginning of the prompt (where system instructions reside) and tokens near the end (the most recent user command). Tokens situated in the middle of a massive context window receive substantially lower attention weights. When a developer attaches thirty project files, earlier class interfaces and subtle typing constraints get buried in the middle of the payload, leading the agent to generate incompatible code.
Context degradation manifests in four distinct operational failure modes:
- Hallucinated internal imports. When module declarations are pushed outside the model's primary attention focus, the agent invents plausible-looking function names, incorrect parameter orders, or circular imports.
- Circular editing traps. During multi-file refactoring, an agent might introduce a syntax error in file A to fix file B. On the next turn, it inspects file A, notices the error, and reverts it, breaking file B again. Because the conversation history is bloated with intermediate failed attempts, the agent forgets why the initial change was made.
- Instruction drift. Strict architectural rules stated at the start of the session (such as avoiding third-party libraries or maintaining backward-compatible database migrations) get superseded by immediate compiler error logs.
- Latency and token expenditure spikes. Processing massive prompts with hundreds of thousands of input tokens on every turn introduces significant delay between user prompts and agent execution, rapidly depleting monthly credit allowances.
This dynamic explains why developers encounter friction with tools like Claude Projects, where project knowledge is bounded by Claude's context window capacity (up to 30MB per file with unlimited files, as noted in Anthropic's upload documentation), forcing users to prune reference documents manually as cumulative token volume fills available memory. When teams migrate to Cursor to manage larger codebases, they often repeat the same fundamental mistake by attaching whole folder structures into chat sessions.
To mitigate this problem during exploratory phases, Cursor includes a specialized Explore subagent. The Explore subagent operates in an isolated context window completely separate from the parent agent session. When an engineer asks a broad question about repository structure, Cursor launches this subagent using a lightweight model to execute parallel searches, inspect relevant files, and distill the findings into a concise summary. Only that distilled summary is returned to the parent conversation, preserving the primary context window for actual code changes.
How Cursor Indexes Large Codebases with Embeddings and Grep
To balance context constraints against repository scale, Cursor avoids dumping whole directories into prompts. Instead, it relies on a two-tier retrieval architecture combining lexical search with semantic embeddings.
The first retrieval tier is Instant Grep. For exact symbol lookups, function declarations, and variable references, Cursor uses an optimized lexical search engine built on top of ripgrep primitives. When an agent needs to locate all references to a specific interface or configuration key, Instant Grep executes across thousands of local files in milliseconds, returning exact lines without consuming token memory on irrelevant context.
The second tier is semantic codebase indexing. Cursor computes vector embeddings for code chunks across your repository, storing the resulting index locally or syncing it with team repositories. When a developer asks a conceptual question (such as explaining how authentication tokens are validated across API routes), Cursor performs vector similarity search to retrieve the most relevant code chunks before constructing the prompt.
While this dual-retrieval pipeline handles standard application code effectively, it encounters steep barriers in large enterprise codebases and monorepos:
- Local resource exhaustion. Indexing monorepos with hundreds of thousands of files demands significant CPU cycles, local RAM, and disk storage. On shared developer machines, background indexing can slow down IDE responsiveness.
- Asset boundary mismatches. Software engineering projects depend on non-code assets that do not belong in a Git repository. Product requirements, database schema exports, OpenAPI specifications, regulatory guidelines, and client-supplied sample data bloat repositories if committed to source control.
- Fragmented team context. In team environments, each developer's machine maintains an isolated local index. Cursor Teams subscription plans offer a Premium seat that adds 5x the Standard limits on Agent models. Yet without centralized external storage, developers on the same team end up repeatedly re-indexing identical external reference assets across separate workstations.
To solve this coordination bottleneck, engineering teams require an external storage layer that indexes non-code assets once and serves them to Cursor agents on demand through standard protocols.
Offload Cursor context to an intelligent workspace
Connect Cursor to a persistent Fast.io workspace via remote MCP to index and search large document collections with versioning and audit trails. Every organization starts with a 14-day free trial.
Connecting Cursor to Fast.io Through Remote MCP Workspaces
The sustainable path for handling large reference corpuses is moving external documentation out of local folders and into an intelligent workspace. Rather than attaching multi-megabyte files directly to chat prompts, developers store the corpus in a Fast.io workspace.
Fast.io provides shared org-owned workspaces with per-file version history, granular permissions, an append-only audit log, and built-in Intelligence Mode. You can populate a workspace by uploading files directly, or sync reference documents from Dropbox, Box or OneDrive. Google Drive imports today with sync coming soon, allowing teams to consolidate reference materials without manual downloads.
When Intelligence Mode is enabled on a workspace, files are automatically indexed for hybrid search, combining full-text keyword indexing with semantic vector retrieval. Instead of uploading entire document libraries into Cursor, the coding agent connects to Fast.io through the Model Context Protocol (MCP) and queries the indexed workspace dynamically.
Cursor connects to remote MCP servers using Streamable HTTP. To register your Fast.io workspace, create or edit .cursor/mcp.json at the root of your project directory:
{
  "mcpServers": {
    "fastio-workspace": {
      "url": "https://mcp.fast.io/mcp/key",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
The server endpoint is also accessible via legacy SSE transport at https://mcp.fast.io/sse. You can inspect complete tool definitions in the official documentation at https://mcp.fast.io/skill.md or review developer integration patterns on the Fast.io for Agents page.
When Cursor connects to Fast.io, the agent receives a consolidated MCP toolset that allows it to search workspace documents, retrieve specific file chunks, list folder structures, and read document summaries. The operational contrast between traditional file handling and MCP workspace retrieval is clear:
- Storing files locally in the repository bloats Git history and overwhelms Cursor's local vector index.
- Attaching raw PDFs or specification sheets directly to Cursor chat fills tens of thousands of tokens on the first prompt, causing rapid attention degradation.
- Commodity cloud storage providers lack native semantic indexing, forcing agents to download entire files locally before reading them.
- Fast.io indexes documents on arrival. When the agent needs information, it issues a targeted search query and receives only the relevant paragraphs accompanied by source citations.
Connecting an external MCP workspace does not alter Cursor's internal model token limit. An artificial intelligence model with a fixed context window retains that exact boundary regardless of external tooling. What changes is prompt efficiency: instead of consuming tens of thousands of tokens by pasting an entire architectural specification, the agent retrieves a concise excerpt containing the exact interface contract it needs. This keeps the active context window uncluttered, fast, and focused on writing clean code.
Structuring Complex Project Context with Metadata Views
Large software engineering initiatives frequently involve hundreds of semi-structured assets: vendor contracts, third-party API specifications, security compliance reviews, and hardware interface definitions. Standard semantic search can locate general paragraphs, but coding agents often require precise, structured data points like endpoint URLs, rate limits, schema types, and interface versions.
To solve this challenge, Fast.io provides Metadata Views. Metadata Views turn unstructured documents into a live, queryable database. Users describe the fields they want extracted in natural language, and Fast.io designs a typed schema across text, integer, decimal, boolean, URL, JSON, and date fields. The platform automatically matches documents in the workspace and populates a sortable, filterable table without requiring manual OCR templates or parsing scripts.
Because Fast.io exposes Metadata Views through its MCP server, Cursor agents can query structured records directly:
{
  "tool": "fastio_query_metadata_view",
  "arguments": {
    "view_name": "API_Endpoint_Catalog",
    "filter": "service == 'PaymentGateway' && environment == 'Production'"
  }
}
Instead of forcing Cursor to ingest a lengthy payment provider specification, the agent queries the view and receives a structured JSON object containing the exact endpoint route, authentication header format, and timeout threshold in a few compact JSON lines. Developers can add new columns to a view at any point without reprocessing files.
Beyond structured data extraction, Fast.io provides essential operational infrastructure for multi-agent and human collaboration:
- Per-file version history. Every change made by a human or an autonomous agent is preserved. If an agent writes an invalid configuration or alters a shared document unexpectedly, developers can inspect diffs and restore previous file versions immediately.
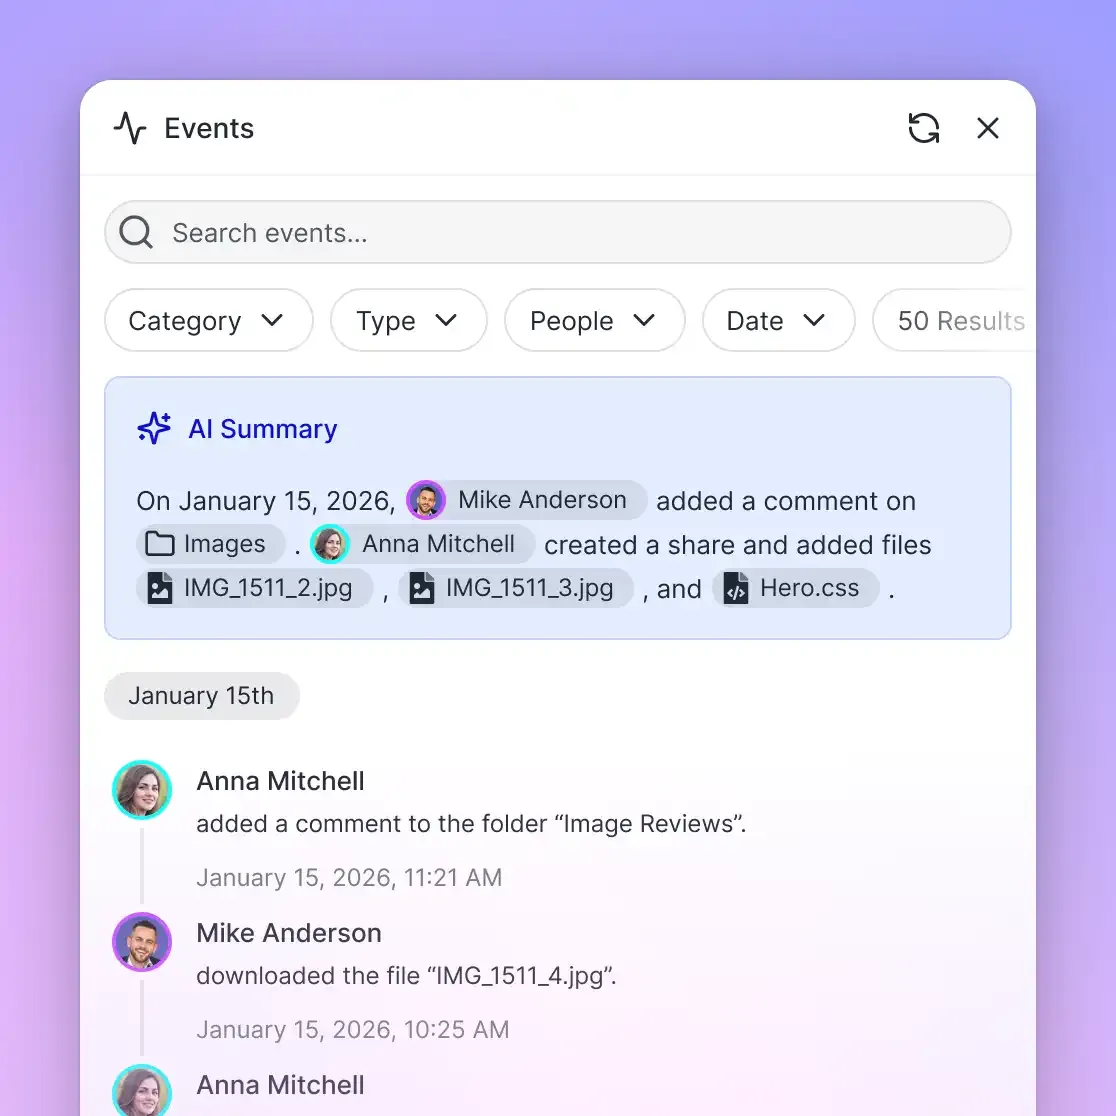
- Append-only audit log. Every read, write, search, and export operation is logged with timestamps and actor identities, maintaining clear visibility into how automated agents interact with company assets.
- Collaborative Notes. Real-time co-editing allows developers and coding agents to draft implementation plans, technical specifications, and post-mortem notes in the same shared document.
- Clean ownership transfer. Freelance developers or external consultants can build organizations and workspaces on behalf of clients, configure permissions and MCP connections, and transfer organizational ownership to the client upon project delivery while retaining administrative access.
Getting started with Fast.io is straightforward. Every organization starts with a 14-day free trial, which requires a credit card. Paid subscription plans include Starter at $29/mo, Business at $99/mo, and Growth at $299/mo, giving development teams persistent workspace capacity, centralized intelligence, and MCP connectivity for their coding agents. You can explore available plans on the pricing page.
Sources
References used to verify factual claims in this guide.
-
Cursor extends context window token limits and model tokens on legacy plans through Max Mode billed at the model API rate plus 20%. Cursor Teams subscription plans offer a Premium seat that adds 5x the Standard limits on Agent models.
Frequently Asked Questions
What is the context window in Cursor AI?
The context window in Cursor AI is the maximum number of tokens a model can process in a single interaction. It encompasses the system prompt, tool definitions, active chat history, attached project files, and retrieved codebase chunks. Default limits typically range from 128,000 to 300,000 tokens depending on the chosen model, with extended context options reaching up to 1,000,000 tokens.
How does Cursor handle codebases that exceed the context window?
Cursor does not inject an entire repository into the context window at once. Instead, it uses Instant Grep for exact symbol matching and semantic vector embeddings to search code chunks across the repository. It retrieves only the most relevant snippets for the current prompt. Additionally, the built-in Explore subagent runs in an isolated context window to investigate codebases without bloating the primary conversation.
How do you add an MCP server to Cursor for external files?
You can add an MCP server to Cursor by creating a configuration file at `.cursor/mcp.json` in your project root or at `~/.cursor/mcp.json` for global access. Define your server under the `mcpServers` object with its URL and authorization headers. For remote servers like Fast.io, configure the Streamable HTTP endpoint at `https://mcp.fast.io/mcp/key` with your Bearer API token.
What causes context window degradation in Cursor during long chats?
Context degradation occurs due to the lost-in-the-middle effect, where attention mechanisms prioritize tokens at the extreme beginning and end of the prompt while underweighting middle tokens. As multi-turn conversations accumulate verbose terminal logs, file edits, and compiler errors, earlier architectural guidelines are neglected, leading to hallucinated imports, repeated mistakes, and instruction drift.
Does connecting an MCP server increase Cursor's token limit?
No. Connecting an MCP server does not alter the underlying model's fixed token limit. Instead, it improves prompt efficiency by offloading large document collections to an external indexed workspace. The agent queries the workspace dynamically and retrieves compact, relevant excerpts with citations rather than pasting entire multi-megabyte files into chat.
How does Fast.io prevent token exhaustion in Cursor sessions?
Fast.io provides persistent workspaces equipped with Intelligence Mode and Metadata Views. Large project documents, API schemas, and specifications are automatically indexed for hybrid search upon upload. Cursor agents search and extract targeted data via MCP tool calls, keeping active token consumption minimal and preserving the context window for code generation.
Related Resources
Offload Cursor context to an intelligent workspace
Connect Cursor to a persistent Fast.io workspace via remote MCP to index and search large document collections with versioning and audit trails. Every organization starts with a 14-day free trial.