How Copilot File Search Works and How to Fix Missing Results
Copilot file search retrieves documents from OneDrive and SharePoint by combining lexical matching with semantic vector indexing through Microsoft Graph. When files go missing from search results, the issue typically stems from indexing lag, permission trimming, unsupported formats, or query scope limits. Understanding Microsoft Graph indexing mechanics and deploying indexed workspaces with remote MCP access allows AI models to locate documents reliably without hitting API throttling.

How Copilot File Search Works Across Microsoft 365
When a user asks Microsoft 365 Copilot to locate a specification, analyze a contract, or summarize a strategy deck, Copilot does not scan disk directories or crawl folder trees in real time. Instead, it relies on a background retrieval pipeline powered by Microsoft Graph and the Semantic Index for Copilot. If a document has not yet been processed by this indexing system, or if security boundaries filter it out, Copilot states that it cannot find the file, even when the document sits in the user's primary OneDrive folder.
Copilot file search is the semantic and keyword retrieval mechanism Microsoft 365 Copilot uses to discover and cite documents stored across OneDrive, SharePoint, and local user caches.
Understanding how Copilot discovers and retrieves enterprise files requires examining the interaction between traditional lexical search and modern vector grounding. Most knowledge workers assume that pointing an AI model at cloud storage functions like a local desktop search. In enterprise deployments across Microsoft OneDrive, SharePoint Online, Google Drive, Dropbox, and Box, retrieval operates under strict multi-tenant constraints, token budgets, and security trimming rules.
The Request and Grounding Lifecycle
When a prompt enters Microsoft Copilot through Word, Teams, Excel, PowerPoint, or Copilot Chat, the platform processes the query through five distinct stages:
- User Prompt Parsing and Intent Recognition: The Copilot orchestrator parses the prompt to identify whether external organizational context is required. If the prompt references a specific document, topic, or recent project, the orchestrator initiates a grounding request.
- Dual-Tiered Index Retrieval: The orchestrator queries both lexical keyword indices and the Semantic Index for Copilot in Microsoft Graph. Rather than downloading entire files, it identifies the most relevant text passages and metadata attributes.
- Real-Time Security Trimming: Before candidate search results pass to the model, Microsoft Graph verifies the identity and access permissions of the signed-in user via Microsoft Entra ID. Any file or passage for which the user lacks explicit Read permission is discarded silently.
- Context Augmentation (Meta-Prompt Construction): The orchestrator extracts relevant chunks from the retrieved documents and constructs a grounded prompt. This prompt combines the original user instructions with verified text passages and source URLs.
- LLM Synthesis and Citation Formatting: The large language model reasons over the grounded prompt and produces an answer. Citations and document links are appended to the response, referencing the exact files discovered during the retrieval phase.
The Dual-Tiered Semantic Index Architecture
The Semantic Index for Copilot is not a single database. It consists of two separate, coordinated indexing layers operating within the tenant boundary:
- Tenant-Level Index: This organization-wide index maps text-based documents stored in SharePoint Online and shared corporate repositories. It builds vector representations across document collections, allowing Copilot to identify conceptual relationships across shared projects.
- User-Level Index: This personalized index captures the individual working set of a specific user. It maps personal emails, calendar items, Teams chats, and documents stored in personal OneDrive for Business folders or files the user recently viewed, commented on, or authored.
The table below contrasts how traditional lexical search, Copilot semantic file search, and direct API traversal discover enterprise documents:
When Copilot file search functions properly, it delivers relevant citations without manual file browsing. When any step in this retrieval chain breaks, Copilot fails to locate documents that exist in cloud storage.
Related guides
- How to Fix 'Claude Upload Failed' Errors and Bypass File LimitsA Claude upload failed error occurs when files exceed 500MB per chat attachment, 30MB per project file, contain...
- Claude OneDrive Not Working: Fix Connector Sync and File Stub ErrorsClaude OneDrive connection failures occur when Microsoft Graph API throttling limits large folder indexing, tenant...
- Copilot Search SharePoint: How M365 Graph Search Works & TroubleshootingCopilot search in SharePoint uses Microsoft Graph Semantic Index to match natural language queries against indexed...
- How to Connect Copilot to OneDrive: Fix Hydration & RatesConnecting Copilot to OneDrive links AI coding assistants to Microsoft OneDrive folders, allowing models to search...
- Can Copilot Access SharePoint? Permissions, Libraries, and SetupMicrosoft Copilot can access SharePoint document libraries when users hold explicit read permissions through Microsoft...
- How to Connect Copilot to SharePoint: Copilot Studio and MCPConnecting Copilot to SharePoint links enterprise document libraries to Microsoft Copilot Studio and GitHub Copilot for...
More on this subject: GitHub Copilot (137 guides)
The Top Four Reasons Copilot Fails to Find Files
When Copilot reports missing results, users often assume the model suffered a hallucination or that the file was deleted. In enterprise environments, retrieval failures almost always stem from specific architectural boundaries within Microsoft 365. Identifying the root cause requires evaluating indexing schedules, permission inheritance, document formats, and prompt specificity.
1. Indexing Latency and Crawl Schedules
The most common cause of missing files is simple indexing delay. Copilot cannot reason over content that has not yet been processed into the semantic index. While modifications to already-indexed personal files can register quickly, newly uploaded documents to multi-user repositories require scheduled background processing.
According to Microsoft Learn documentation on Semantic indexing for Microsoft Copilot: "New documents that are added to SharePoint Online sites that are accessible, via site inheritance, by two or more users are indexed daily. When an indexed user and tenant level document is updated, the changes are immediately indexed."
Because tenant-level index jobs run on periodic cadences rather than continuous streams, a file uploaded to a shared SharePoint library thirty minutes before a meeting may remain completely invisible to Copilot search. Until the background crawler ingests the document, computes vector embeddings, and registers the metadata in Microsoft Graph, Copilot behaves as though the file does not exist.
2. Permission Trimming and Inheritance Anomalies
Copilot enforces absolute security trimming. If a user does not have direct read access to a document in SharePoint or OneDrive, the retrieval engine filters that document out before the prompt reaches the language model.
Crucially, Copilot never alerts the user that a document was hidden due to permission restrictions. To prevent information leakage regarding the existence of confidential files, the model issues a generic response stating that no matching records were found.
In enterprise tenants, permission inheritance anomalies represent a primary source of search misses:
- Broken Inheritance: When administrators or folder owners break permission inheritance on specific subfolders to restrict sensitive drafts, downstream files may lose inherited group permissions.
- Unique Item Permissions: When files are shared individually via temporary direct links, the underlying access control list (ACL) may fail to propagate to the user's primary security token immediately.
- Security Group Sync Delays: Changes made to Entra ID security groups or Microsoft 365 Groups can take several hours to replicate fully across SharePoint Online site collections.
- Sensitivity Labels and Information Protection: Files protected by Microsoft Purview sensitivity labels with strict encryption or access restrictions can block automated extraction and semantic indexing, preventing Copilot from reading their contents.
3. Unsupported File Formats and Structural Boundaries
Copilot file search supports common enterprise document formats, but strict boundary limits apply. Supported document types for semantic indexing include:
- Word documents (
.docx,.doc) - PowerPoint presentations (
.pptx) - Portable Document Format (
.pdf) - Modern SharePoint web pages (
.aspx) - OneNote notebooks (
.one)
Microsoft 365 supports substantial document sizes for PDF, PPTX, and DOCX formats during semantic indexing. However, several critical file types remain unsupported or partially indexed:
- Scanned Image-Only PDFs: PDFs that contain scanned page images without an embedded OCR text layer cannot be parsed by semantic indexing. Copilot cannot read the image pixels directly during search grounding.
- Legacy and Non-Standard Formats: Macro-enabled spreadsheets, legacy binary formats, code repositories, design files, CAD drawings, and media containers are excluded from semantic text extraction.
- Archived Repositories: Content stored in SharePoint Microsoft 365 Archive or archived mailboxes is explicitly unsupported by the semantic index.
- Shared and Delegated Mailboxes: Content located in delegated or shared mailboxes is excluded from user-level index generation.
4. Query Scope and Vector Distance Ambiguities
Large language models determine relevance through vector proximity. In a high-dimensional vector space, concepts that share semantic context cluster together. If a user prompt is overly generic, or if the enterprise repository holds hundreds of similar project updates, the semantic index may fail to return the intended file within the top retrieval slots.
RAG architectures evaluate only a bounded context budget of top-k candidate chunks. If a query such as "Find the supplier review document" returns twenty candidate chunks from older audits, the recent contract update may be truncated from the prompt context.
When queries are executed without explicit scope, Copilot searches across personal mail, Teams chats, and shared sites simultaneously. This broad scope introduces noise that displaces specific document chunks.
How to Troubleshoot and Fix Missing Copilot File Results
When Copilot file search fails to locate a file that you know exists in OneDrive or SharePoint, follow this structured diagnostic procedure to identify and resolve the issue.
Step 1: Verify Direct Web Access and Account Alignment
Before investigating indexing pipelines, confirm that the file is accessible through standard web interfaces and that your authentication context matches:
- Open a private browser window and navigate to the SharePoint or OneDrive document library containing the target file.
- Confirm that you can open and read the file natively in Office for the Web. If SharePoint prompts for administrator privileges or displays an access denied error, the issue is an access control failure rather than an AI search defect.
- Verify tenant account alignment. In enterprise environments where employees maintain multiple Microsoft identities (such as a corporate Entra ID and an external client guest account), verify that Microsoft 365 desktop apps, the OneDrive sync client, and your active Copilot session are signed in to the identical organizational account. Account mismatches prevent Microsoft Graph from associating your session with your tenant permissions.
Step 2: Test Native SharePoint Lexical Search
Isolate whether the problem lies in the underlying search crawler or in Copilot's semantic retrieval layer:
- Navigate to the top-level search bar in your SharePoint site or OneDrive web portal.
- Search for an exact, unique string from the target document, such as a distinct serial code, contract ID, or unusual header phrase. Use quotation marks around the string to force an exact lexical match.
- Evaluate the result:
- If the file appears in native search: The core SharePoint crawler has successfully indexed the document. The missing result in Copilot indicates semantic vector latency, context window truncation, or query ambiguity. Proceed to Step 4.
- If the file does not appear in native search: The document has not been indexed by Microsoft Search. The underlying crawler has either not run, encountered an ingestion error, or been blocked by site settings. Proceed to Step 3.
Step 3: Trigger a Manual Library or Site Re-Index
If a file has been uploaded for several hours and remains invisible to both native search and Copilot, request a manual crawl of the library or site.
According to Microsoft Learn documentation on crawling and reindexing: "In SharePoint, content is automatically crawled based on a defined crawl schedule." When schema modifications or indexing stalls occur, administrators can manually flag containers for re-evaluation.
To re-index a specific document library without imposing unnecessary load on the tenant:
- Open the target SharePoint document library.
- Select the Settings (gear) icon in the top right corner and choose Library settings (or More library settings).
- Under General Settings, select Advanced settings.
- Scroll down to the Reindex Document Library section and select the Reindex Document Library button.
- Confirm the prompt when requested. All files in the library will be marked for re-indexing during the next scheduled search crawl.
To re-index an entire SharePoint site (requires site owner or administrator privileges):
- On the site home page, select Settings and choose Site information, then select View all site settings.
- Under the Search heading, select Search and offline availability.
- In the Reindex site section, click Reindex site and confirm the acknowledgement warning.
Step 4: Validate Permissions and Repair Broken Inheritance
If the file is indexed but Copilot continues to omit it, check for broken permission inheritance:
- In the document library, right-click the target file (or parent folder) and select Manage access.
- In the access panel, select the three dots and choose Advanced settings to open the classic SharePoint permissions page.
- Check the ribbon notification. If it displays "This item has unique permissions," the folder or file has broken inheritance from the parent library.
- If appropriate for your governance policy, select Delete unique permissions to restore inherited access, so that tenant security groups recognized by Microsoft Graph can reach the document.
- If the file carries a Microsoft Purview sensitivity label, check whether the label restricts content extraction or programmatic access. Labels configured with user-defined permissions or offline access blocks can prevent Copilot from parsing text chunks.
Step 5: Scope Prompts Explicitly with URLs and Metadata
When searching across extensive corporate tenants, avoid open-ended prompts. Constrain Copilot's retrieval scope directly within the conversation interface:
- Reference the Direct URL: In your Copilot prompt, paste the direct SharePoint URL of the document library or folder. When you provide a specific library URL, Copilot scopes its grounding step to that exact path.
- Use Column Metadata Filters: Copilot uses SharePoint library column metadata (such as Department, Status, or Document Type) as additional ranking signals during scoped queries. For example, structure your query as: "Summarize the master services agreement in the target library URL where Status is Final and Year is 2026."
- Attach the Document Directly: Use the attachment icon in Copilot to link the specific document directly from OneDrive or SharePoint, bypassing broad vector retrieval entirely.


Solve Document Retrieval Latency with Intelligent Workspaces
Sync your OneDrive and SharePoint document libraries into indexed Fastio workspaces for sub-second hybrid search and remote MCP connectivity. Monthly plans start with a 14-day free trial, which requires a credit card.
Why Native Cloud Storage Connectors Throttle AI Retrieval
The challenges knowledge workers encounter with Copilot file search reflect a broader architectural friction across enterprise AI deployments. Most organizations maintain their operational records across a combination of Google Drive, Dropbox, Box, OneDrive, and SharePoint. When teams deploy autonomous agents, code assistants, or conversational interfaces across these repositories, relying exclusively on native cloud storage connectors introduces significant operational bottlenecks.
The Limits of Native Storage Connectors
Native connectors designed for conversational apps typically operate through shallow file pickers or synchronous API queries. While sufficient for inspecting a single file, they struggle when autonomous workflows require comprehensive retrieval across enterprise folder structures:
- Lack of Recursive Traversal: Standard conversational storage connectors do not automatically crawl nested subdirectories. If a project archive contains files organized into multiple subfolders, the assistant often fails to discover relevant documents unless each subfolder is opened manually.
- Graph API Throttling and HTTP 429 Errors: When an automated agent attempts to discover files by issuing rapid directory-listing and file-read requests across Microsoft Graph, it quickly encounters rate limits. Microsoft 365 enforces strict multi-tenant throttling thresholds. When requests exceed allowable frequencies, Microsoft Graph responds with HTTP error 429, forcing the agent to wait through exponential backoff delays.
- Context Window Exhaustion from Raw File Payloads: Native cloud storage connectors often fetch complete binary files over the wire. Loading entire multi-page PDFs or presentations into an LLM context window consumes massive token budgets and degrades reasoning performance. Effective agent retrieval requires extracting, chunking, and ranking text passages before the model processes the query.
Benchmark Measurements Across Storage Connectors
The connector comparison is published at fast.io/benchmarks and that page is the only place its numbers live. Fastio was measured the fastest and the lowest cost of the providers tested.
Connecting Indexed Workspaces to AI Agents via Remote MCP
To overcome the indexing delays and API rate limits of native cloud connectors, engineering teams increasingly adopt an intelligent workspace architecture. In this model, organizations keep their existing systems of record in Microsoft OneDrive, SharePoint, Google Drive, Box, or Dropbox, while synchronizing selected project folders into an indexed workspace.
Fastio provides a cloud workspace platform designed specifically for agentic teams. Rather than forcing teams to migrate away from existing enterprise storage, Fastio connects to existing repositories and exposes indexed content to AI agents through the Model Context Protocol (MCP).
Automated Cloud Sync and Hybrid Indexing
Fastio Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. SharePoint document libraries connect through the OneDrive connector.
This synchronization pattern delivers several operational advantages:
- Preserve Systems of Record: Your team continues collaborating in OneDrive and SharePoint. Cloud Sync copies documents into an isolated Fastio workspace without disrupting existing corporate permissions or workflows.
- Scheduled and On-Demand Sync: Sync jobs run on a user-defined schedule or trigger on demand. Because synchronization operates as an asynchronous background process, it never triggers the high-frequency API spikes that cause Microsoft Graph HTTP 429 throttling.
- Automatic Intelligence Mode: When files enter a Fastio workspace, Intelligence Mode parses and indexes every document automatically. It computes a hybrid search index combining full-text keyword matching, semantic vector embeddings, and metadata value search. Scanned PDF documents and images undergo automated OCR, making text fully queryable.
- Structured Extraction with Metadata Views: For repositories containing structured operational documents such as vendor contracts, invoices, or specifications, Metadata Views convert unstructured files into a live, queryable database. Users describe the fields they want extracted in natural language, AI designs a typed schema (Text, Integer, Decimal, Boolean, URL, JSON, Date & Time), matches files in the workspace, and populates a sortable, filterable spreadsheet. Agents can create Views, trigger extraction, and query structured fields directly via MCP.
Connecting Agents Through Remote MCP Servers
Instead of configuring complex local daemons or container bridges, Fastio provides a consolidated MCP toolset hosted remotely over Streamable HTTP. Agents connect directly using standard endpoint URLs:
https://mcp.fast.io/mcp/tools: Claude applications (claude.ai, Claude Desktop, Claude Cowork) and general personal-agent runtimes.https://mcp.fast.io/mcp/operations: ChatGPT and Codex custom server connections.https://mcp.fast.io/mcp/code: Developer environments and coding agents, including Claude Code, Cursor, VS Code, and Copilot agent mode.
To connect an autonomous agent framework to a Fastio workspace, declare the remote server endpoint in your configuration and pass a scoped API key:
{
  "mcpServers": {
    "fastio": {
      "url": "https://mcp.fast.io/mcp/tools",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
When an agent needs to retrieve information, it calls Fastio's storage tool over MCP. The workspace executes a hybrid semantic and keyword query across the pre-computed index and returns only the relevant text passages, page numbers, and file identifiers. The agent receives precise context without downloading multi-megabyte binary files or navigating nested folder trees.
Enterprise Governance and Access Control
Intelligent workspaces maintain strict administrative boundaries:
- Role-Based Permissions: Permissions are configured at the organization, workspace, and share levels through member roles. Every workspace member accesses content according to their assigned role.
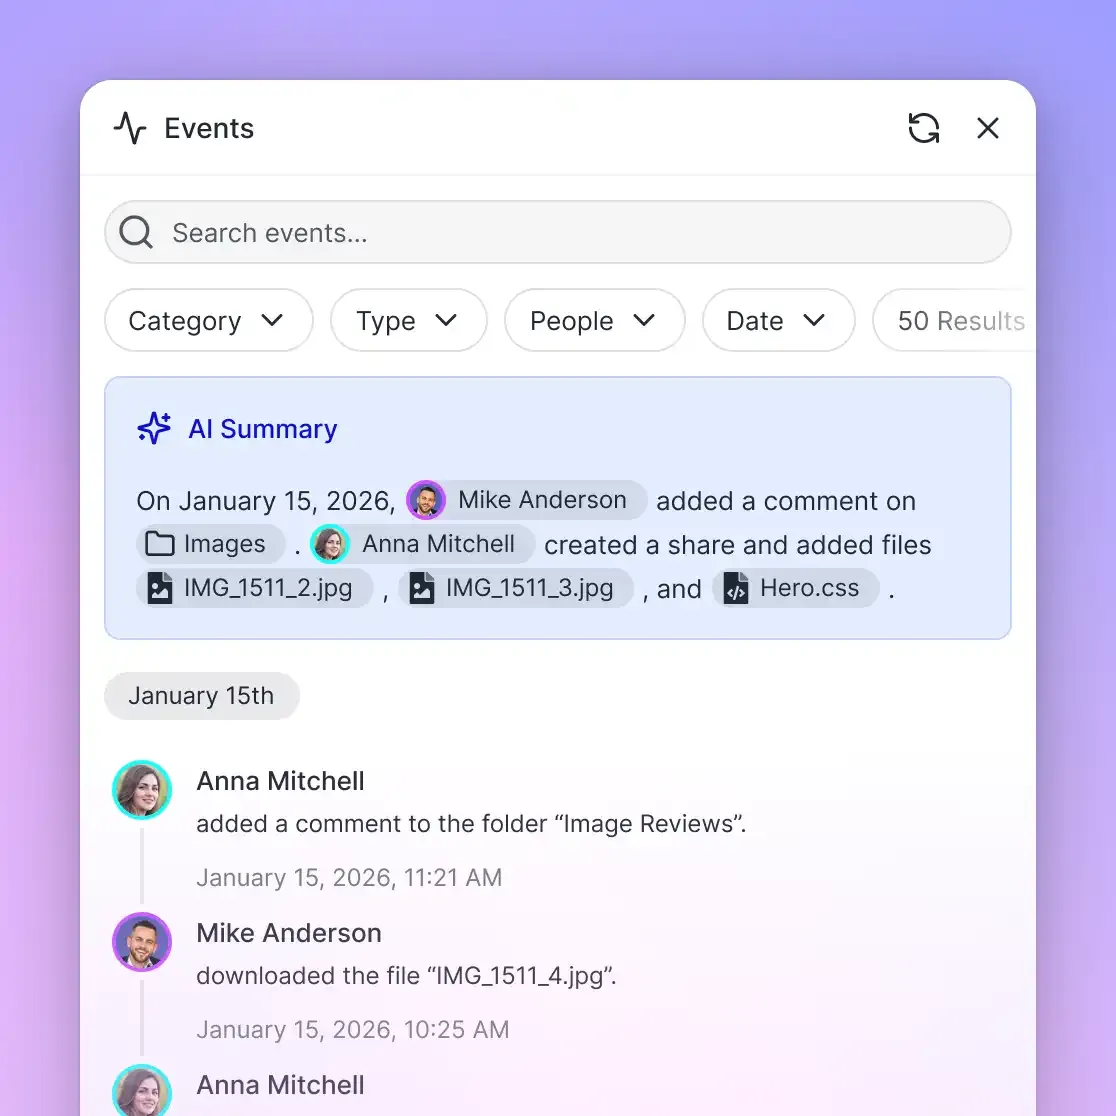
- Detailed Activity Log: Fastio maintains a detailed activity log that records changes across the organization, including uploads, edits, moves, deletions, membership updates, and share creation.
- Per-File Version History: Every document maintains complete version history, keeping concurrent agent writes or updates auditable and reversible.
Operational Best Practices for Enterprise Document Discovery
Whether using Microsoft Copilot natively or deploying autonomous agents across indexed workspaces, maintaining reliable file discovery requires active operational hygiene. Apply these organizational best practices to prevent missing search results across your enterprise repositories:
1. Maintain Clean Directory and Permission Boundaries
Avoid fragmenting SharePoint and OneDrive document libraries with item-level unique permissions. When individual documents or nested folders break inheritance, search indexers must evaluate complex access control lists for every query turn. Group related documents into dedicated document libraries or workspaces where member roles govern access uniformly.
2. Standardize Document Formats and Embedded Text Layers
Confirm that scanned contracts, paper invoices, and historical records contain embedded text layers before ingesting them into document libraries. If your organization relies on scanned PDFs, use automated OCR tools or sync repositories through Fastio workspaces where Intelligence Mode performs optical character recognition during ingestion. Standardize on modern formats (.docx, .pptx, .pdf) and avoid storing critical text inside unsupported binary containers.
3. Structure Metadata Columns for Scoped Queries
Structure SharePoint libraries and cloud workspaces with explicit metadata properties such as Department, Document Type, Fiscal Year, and Project Code. When users or agents query these repositories, include metadata parameters in the prompt. Constraining search scope reduces vector noise, prevents context window truncation, and gives the most recent document revisions precedence during retrieval.
4. Decouple Long-Term Storage from Agent Query Surfaces
For mission-critical AI workflows, do not force autonomous models to perform brute-force directory traversal across legacy enterprise file systems. Maintain your authoritative records in OneDrive or SharePoint, schedule background synchronization into an indexed workspace, and allow AI models to query pre-computed semantic indices via remote MCP. This architecture prevents API throttling, avoids indexing delays, and delivers reliable citations across all team files.
Sources
References used to verify factual claims in this guide.
-
New documents added to SharePoint Online sites accessible by two or more users are indexed daily.
-
SharePoint content is automatically crawled based on a defined crawl schedule that updates the search index.
Frequently Asked Questions
Why is Copilot not finding my files in OneDrive or SharePoint?
Copilot relies on Microsoft Graph and the Semantic Index rather than browsing directory trees in real time. If Copilot fails to find a file, the issue is typically caused by indexing delays for newly uploaded files, security trimming that hides files with broken permission inheritance, unsupported file formats like scanned image-only PDFs, or overly broad queries that dilute search relevance.
How does Microsoft Copilot search for documents?
Microsoft Copilot uses a dual-tiered retrieval process combining traditional lexical keyword search with the Semantic Index for Copilot in Microsoft Graph. When a user submits a prompt, Copilot queries both user-level and tenant-level vector indices, applies real-time Entra ID permission trimming, extracts relevant text passages, and includes those passages as grounding context in the prompt sent to the large language model.
How long does it take Copilot to index new files?
Indexing speed depends on where the file is stored. Updates to existing indexed documents are processed immediately. However, new documents added to shared SharePoint Online sites accessible by two or more users are indexed on a daily schedule. If a file was uploaded recently, it may not appear in Copilot file search results until the next background crawl completes.
Why does Copilot fail to locate files in nested subfolders?
Native conversational storage connectors often use shallow file pickers that do not recursively crawl deep folder hierarchies. Subfolders with broken permission inheritance can also silently exclude files during security trimming. To enable comprehensive search across deep folder trees, teams sync directories into an indexed workspace that builds a unified hybrid search index across all subfolders.
Can Microsoft Copilot search scanned PDF documents?
Microsoft Copilot can only search PDF files that contain a selectable, embedded text layer. Scanned PDFs that consist solely of raster images without OCR text cannot be parsed by the semantic indexing engine. To make scanned documents searchable by AI agents, files must be processed through an OCR pipeline or synced to a workspace with automated OCR text extraction.
How do indexed workspaces resolve Copilot indexing delays for AI agents?
Indexed workspaces synchronize files from OneDrive, SharePoint, Google Drive, Box, and Dropbox in the background, immediately parsing text, extracting metadata, and generating vector embeddings. AI agents query this pre-computed hybrid index via remote MCP servers, retrieving precise citations in sub-second response times without waiting for tenant crawl schedules or hitting API rate limits.
Related Resources

Solve Document Retrieval Latency with Intelligent Workspaces
Sync your OneDrive and SharePoint document libraries into indexed Fastio workspaces for sub-second hybrid search and remote MCP connectivity. Monthly plans start with a 14-day free trial, which requires a credit card.