Claude Cowork Dropbox: Native Connector Setup and Retrieval Performance
The Claude Cowork Dropbox connector allows Anthropic Claude to directly browse, search, and ingest files stored in Dropbox accounts during user conversations. While native connectors enable direct file browsing for single documents, querying large folders causes API rate limiting, high token costs, and context saturation. Syncing Dropbox folders into Fast.io workspaces lets Claude Cowork run fast hybrid searches over remote MCP without downloading complete files.

How the Native Claude Dropbox Connector Operates in Claude Cowork
Connecting Claude Cowork directly to a cloud storage folder causes an immediate retrieval bottleneck as soon as an agent queries beyond a single document: direct storage connectors force the language model to act as a raw directory browser, downloading entire files into prompt context rather than querying an indexed semantic database.
The Claude Cowork Dropbox connector allows Anthropic Claude to directly browse, search, and ingest files stored in Dropbox accounts during user conversations. Knowledge workers, product managers, and software teams maintain critical operational documents, customer research, technical specifications, and project archives across platforms like Dropbox, Google Drive, OneDrive, Box, and SharePoint. When teams deploy Claude Cowork for autonomous project synthesis, document drafting, or operational analysis, their first instinct is to link Claude directly to these existing file repositories. Claude Cowork provides a collaborative workspace where Claude works alongside users, running persistent working sessions in cloud runtimes to inspect files, draft content, and coordinate tasks.
Anthropic and Dropbox provide two primary integration paths within the Claude environment:
- The Dropbox connector for the web application (claude.ai) and the Claude desktop application
- The Dropbox plugin configured inside Claude Cowork and Claude Code environments
To configure the native connector in the Claude desktop application, open the left sidebar, navigate to the Chat, Cowork, or Code tab, and select Customize followed by Connectors. Select Add, choose Browse connectors, and find Dropbox in the integration catalog. Selecting Dropbox prompts an OAuth 2.0 authorization screen that requests specific operational permissions:
- View account information: allows Claude to verify identity and check workspace membership details.
- View files and folders: allows Claude to inspect directory trees, read file metadata, and import supported document content into conversations.
- Edit files and folders: allows Claude to save generated text files and organize folder structures upon request.
- View sharing information: allows Claude to inspect access settings on authorized folders.
- Edit sharing information: allows Claude to generate public Dropbox shared links.
- View and edit file requests: allows Claude to inspect or generate file requests to collect materials from team members or clients.
In enterprise and team environments, an administrator must enable the Dropbox connector before individual staff members can authenticate. An admin opens Organizational Settings from the profile menu in claude.ai, selects Connectors, and adds Dropbox to the allowed application list. For the Claude plugin architecture, admins can set Dropbox availability to Installed by Default, Available to Install, Required, or Not available.
Once authenticated, Claude Cowork can discover file paths, inspect metadata, generate sharing links, and write files back to designated directories. However, the native connector operates under explicit technical boundaries. According to official Dropbox documentation: "Claude-generated content can currently only be saved as text-based file types, such as .txt, .md, .html, and .py. Claude-generated content can't be saved as binary file types, such as images or PDFs." The connector also functions within an interactive, user-scoped conversational boundary. The agent does not create a durable, team-wide semantic index; every conversation thread queries the Dropbox API anew, pulling files across the network on demand.
Related guides
- How to Set Up RAG Document Retrieval in Hermes AgentHermes Agent's qmd skill provides local RAG document retrieval by combining BM25 keyword matching, vector search, and...
- How to Connect Cursor to Dropbox via MCP: Step-by-Step SetupConnecting Cursor to Dropbox via MCP allows Cursor agent mode to retrieve documents and code assets directly from cloud...
- Claude Cowork Box Connector: Connecting Team Storage & WorkspacesA Claude Cowork Box connector links Anthropic's collaborative agent workspace to enterprise Box repositories, allowing...
- Claude Cowork OneDrive Connector: File Access & BenchmarksConnecting Claude Cowork to Microsoft OneDrive allows AI agents to access enterprise files during collaborative work...
- Claude Cowork SharePoint: Connecting Document Libraries via MCPConnecting Claude Cowork to SharePoint document libraries allows AI agents to query enterprise knowledge without broad...
- How to Connect Claude Code Terminal Agent to Dropbox WorkspacesConnecting Claude Code to Dropbox via MCP enables the terminal AI coding agent to inspect, retrieve, and modify...
More on this subject: Claude and Claude Code (249 guides)
Why Direct Storage Traversal Hits Bottlenecks in Claude Cowork
While linking Claude Cowork directly to Dropbox suffices for summarizing an isolated memo or inspecting a single script, it breaks down when applied to production team workflows. Production project folders do not contain isolated text files. They contain gigabytes of nested directories, presentation decks, technical spreadsheets, legal contracts, and multimedia assets. In these real-world environments, five technical bottlenecks emerge.
Context Window Bloat and Token Inefficiency
Language models possess large context windows, but context capacity is an expensive retrieval mechanism. The native Claude Dropbox connector downloads entire files rather than extracting specific passages. When an agent queries a folder containing multiple 50-page vendor contracts or quarterly financial reviews, the connector streams the complete text of each document into the prompt.
Ingesting hundreds of pages of unindexed text consumes tens of thousands of prompt tokens on boilerplate legalese, recurring headers, tables of contents, and formatting markup. This token inflation drives up API inference expenses. Ingesting massive raw documents also degrades attention focus across the model's neural attention heads, increasing latency and elevating the chance of missed details or hallucinated figures.
Sequential Directory Walking and Network Latency
A raw cloud storage API is a hierarchical file system, not a search index. When an agent searches for specific facts across a multi-tiered directory structure, it cannot locate the target information in a single query.
To answer a question regarding a project deliverable, Claude Cowork must first execute a tool call to list the root directory, parse the returned JSON array of paths, issue another tool call to list a target subfolder, evaluate candidate file names, and then issue separate download calls for each candidate document. Executing four or five sequential network round trips before reading a single relevant sentence introduces substantial latency. What should be a five-second query becomes a multi-minute delay that disrupts user collaboration.
Dropbox API Rate Limits and HTTP 429 Errors
Autonomous agents that generate high-frequency tool calls place heavy operational load on storage APIs. Dropbox maintains platform-wide rate limits to preserve service stability across millions of concurrent users. When Claude Cowork or an automated agent loops through recursive directory listings and bulk file reads across nested folders, the burst of API requests can trigger rate limit thresholds.
When rate limits are exceeded, the Dropbox API returns an HTTP 429 response, often accompanied by a Retry-After header indicating the required backoff duration. In an active Claude Cowork session, an unhandled HTTP 429 error stops the agent execution loop in its tracks, forcing the user to wait for the backoff window to clear before resuming work.
Binary Assets and Scanned Documents
Corporate Dropbox folders contain diverse document formats, including scanned PDF agreements, architectural drawings, presentation decks, and audio-video recordings. Standard cloud storage connectors handle these files as raw byte streams.
When Claude encounters a scanned PDF that lacks an embedded optical character recognition (OCR) text layer, the native connector cannot parse the image data. The model receives an empty string or an unreadable byte stream, producing silent retrieval failures where the agent incorrectly concludes that a document contains no relevant data. Because the connector cannot write binary files back to Dropbox, agents cannot export rendered charts, compiled PDF reports, or image deliverables directly to shared client folders.
Ephemeral Sessions vs. Persistent Team Memory
The native Claude Dropbox connector binds strictly to an individual user's active session. It maintains no shared, organization-wide index and no persistent knowledge base across working groups.
When a team member uses Claude Cowork to extract data points or audit contracts in Dropbox, the retrieved context and intermediate findings remain locked within that single conversation thread. Other teammates and companion agents running in parallel cannot access the retrieved context, inspect the search index, or build upon the findings without manual copying and pasting.
Decoupling Storage from Retrieval with Fast.io Workspaces
Solving these architectural bottlenecks does not require teams to abandon Dropbox or migrate their file archives. The practical approach is decoupling long-term enterprise storage from the agentic retrieval layer. Dropbox remains the primary system of record where human teams store, share, and organize files. Fast.io serves as the persistent, intelligent workspace layer that indexes those files and exposes them to Claude Cowork through the Model Context Protocol.
Fast.io Cloud Sync establishes a direct bridge between Dropbox folders and dedicated, organization-owned Fast.io workspaces. Administrators configure one-way or two-way synchronization on a defined schedule or on demand. Cloud Sync is never continuous, live, or real-time, providing predictable background updates that respect storage boundaries. (Dropbox, Box, and OneDrive support sync today, with SharePoint libraries accessible through the OneDrive connector; Google Drive supports cloud import today with folder sync coming soon.) By synchronizing a specific project folder into Fast.io, teams create a clear boundary: Claude Cowork queries only the relevant project materials, while the rest of corporate cloud storage remains completely isolated.
Once files populate the Fast.io workspace, Intelligence Mode automatically parses and indexes incoming content for Retrieval Augmented Generation (RAG). Fast.io combines full-text keyword indexing, vector embeddings for semantic search, and metadata value filtering into a unified hybrid search engine. Rather than requiring external vector databases or complex data ingestion pipelines, the workspace processes PDFs, Word documents, spreadsheets, presentations, and code files upon arrival. When Claude Cowork asks a question, the workspace returns concise text excerpts accompanied by exact source citations.
For structured document workflows, Fast.io provides Metadata Views. Metadata Views turn unstructured documents into live, queryable databases. Team members or agents describe the target schema using natural language, and Fast.io automatically extracts typed fields, including Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time, across all matching files in the workspace. Whether extracting renewal dates and counterparty names from commercial leases, line items from invoices, or revision numbers from engineering specs, Metadata Views extracts structured information without brittle OCR templates. Claude Cowork can inspect these typed views or trigger new extractions directly through MCP.
The efficiency gains of remote indexed retrieval compared to native cloud storage connectors were evaluated in independent testing. The connector comparison is published at https://fast.io/benchmarks/ and that page is the only place its numbers live. In that published evaluation, Fastio was measured the fastest and the lowest cost of the providers tested. Every measured row represents that provider's native connector in Claude Cowork; no row represents a local stdio server, a Files-On-Demand stub, or SharePoint, and SharePoint was not measured at all. Accuracy was parity across tested providers. By offloading file parsing and hybrid search to the workspace server, agents make fewer tool calls and avoid flooding LLM context with redundant text.


Connect Dropbox to Claude Cowork with pre-indexed search
Sync Dropbox folders to a Fast.io workspace, auto-index documents for hybrid semantic retrieval, and connect Claude Cowork via remote MCP. Monthly plans start with a 30-day free trial.
Connecting Claude Cowork to Dropbox Folders via Remote MCP
Connecting Claude Cowork to Dropbox content through Fast.io involves setting up the folder sync, activating workspace intelligence, and adding Fast.io's remote Model Context Protocol endpoint to your Claude configuration.
1. Configure Cloud Sync for the Dropbox Folder
Begin by connecting the target Dropbox folder to a dedicated Fast.io workspace:
- Open your Fast.io organization dashboard and create a workspace for the project (such as
client-audit-q4orproduct-research). - Navigate to Workspace Settings and select Cloud Sync.
- Select Dropbox from the list of storage providers and complete the standard OAuth authorization prompt.
- Select the target Dropbox folder containing your project documents.
- Set the sync direction: select one-way to keep the workspace updated from Dropbox, or two-way to allow agent outputs created in Fast.io to sync back to Dropbox.
- Choose the sync schedule, such as daily, hourly, or on demand.
Files synchronize directly across cloud backends without consuming local disk space or requiring local file-system stubs.
2. Enable Intelligence Mode for Automatic Indexing
Once the files are synchronized into the workspace, enable automated semantic search:
- In the workspace navigation menu, click Settings and select Intelligence Mode.
- Toggle Intelligence Mode on. Fast.io begins indexing incoming documents immediately, generating semantic vector embeddings and full-text keyword indexes for all supported document formats.
- Check the indexing status in the workspace overview. Once complete, every document becomes queryable through hybrid search.
3. Add Fast.io Remote MCP to Claude Cowork
Fast.io provides a hosted remote Model Context Protocol server at https://mcp.fast.io/mcp/tools over Streamable HTTP.
To connect Claude Cowork or the Claude desktop application, open Customize, then Connectors; add a custom connector and paste https://mcp.fast.io/mcp/tools; select Connect and sign in to Fastio in the window that opens; in a chat, turn Fastio on from the + menu under Connectors. Sign-in shows a Review Permissions screen where you pick Read Only or Read & Write and which organizations and workspaces the connection can reach.
Because Fast.io hosts a remote MCP server, no local Node.js packages, npx commands, or local background daemon processes run on your machine. Claude Cowork connects directly to the cloud endpoint over HTTP. For complete configuration recipes, review https://mcp.fast.io/docs or read agent onboarding guidance at https://fast.io/llms.txt.
4. Querying Pre-Indexed Documents via Hybrid Search
Once connected, Claude Cowork uses Fast.io's consolidated MCP toolset to search and read documents. Rather than traversing folders sequentially or streaming whole files, Claude invokes the consolidated storage tool with the search action against GET /current/workspace/{workspace_id}/storage/search/:
{
  "name": "storage",
  "arguments": {
    "action": "search",
    "workspace_id": "ws_8f2e1b4c",
    "search": "indemnity obligations and liability caps in vendor contracts",
    "folders_scope": ["fld_contracts_2026"]
  }
}
The workspace executes a hybrid semantic search across the pre-indexed corpus, returning concise, relevant text passages with document titles, section headers, and page citations. Claude Cowork synthesizes answers from these verified excerpts, keeping token usage minimal and context windows clear.
5. Multi-Agent Coordination and Human Handoff
When multiple agents or human team members collaborate within the workspace, Fast.io provides coordination features:
- Per-File Version History: Every document modification creates a new version automatically. If an agent modifies a document or writes updated analysis, prior versions remain fully restorable through the UI or API.
- Advisory File Locks: Agents can acquire advisory leases on active files using the MCP
storage_managetool (lock-acquire,lock-status, andlock-release). Locks notify other members and agents of active editing sessions without blocking writes; concurrent updates both land safely and remain tracked in version history. - Ownership Transfer: An autonomous agent can programmatically provision an organization, configure workspaces, and set up document sync before transferring organization ownership to a human team lead. The agent retains its administrative permissions to continue operational tasks.
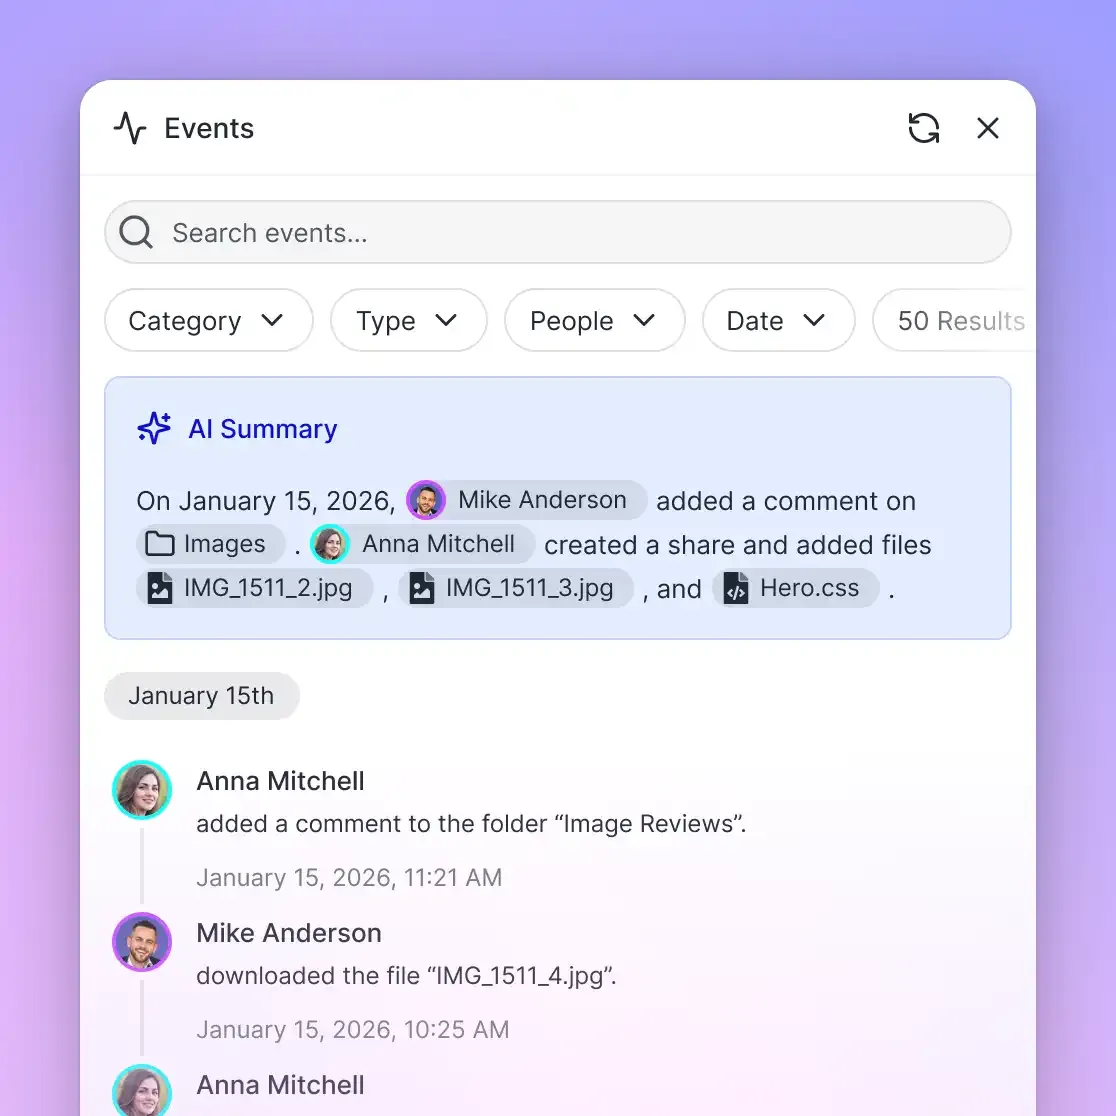
- Append-Only Audit Log: Every read, write, permission change, and sync event is logged in an immutable audit trail, providing complete forensic visibility for team administrators.
- Events Feed: External agents can monitor workspace activity by subscribing to the events feed over WebSocket or through long-poll requests (
GET /current/activity/poll/{entity_id}?wait=95&lastactivity={timestamp}).
Retrieval Performance Tradeoffs and Operational Economics
Evaluating direct Dropbox API traversal against pre-indexed workspace retrieval highlights fundamental differences in operational performance, token costs, and multi-agent coordination.
Latency and Tool Invocation Overhead
Direct API calls through native connectors require the model to act as a file explorer. When an agent searches for data across ten folders, it must issue directory listing calls, inspect metadata arrays, select candidate files, and download raw bytes across sequential tool invocations. Network round trips and prompt re-evaluations compound, resulting in multi-minute execution times.
In contrast, Fast.io offloads document parsing, OCR text extraction, and vector embedding generation to the workspace server during ingestion. Claude Cowork issues a single hybrid search call, and the Fast.io server returns ranked excerpts with citations in milliseconds. The agent answers complex queries in one or two reasoning steps rather than traversing nested directories.
Token Economy and Inference Cost
In native connector workflows, downloading raw files rapidly consumes context capacity. A single 40-page corporate PDF can consume 25,000 input tokens. When an agent inspects three documents to compare terms, context window consumption exceeds 75,000 tokens before any analytical synthesis begins.
By retrieving pre-indexed passages through Fast.io MCP, the model receives only the relevant paragraphs, typically totaling 1,000 to 2,000 tokens per query. This dramatic reduction in input tokens lowers API inference costs and preserves context window space for complex multi-turn reasoning and agent planning.
Platform Rate Limits and Reliability
Querying Dropbox directly exposes workflows to platform API quotas. Autonomous agents that execute frequent recursive scans across large directories can trigger HTTP 429 rate limit errors, stalling active tasks.
With Fast.io, Dropbox API interactions are restricted to scheduled or on-demand Cloud Sync cycles. Once files arrive in the workspace, all agent queries execute against the Fast.io hybrid search index. This architecture shields Dropbox accounts from rapid burst traffic and ensures reliable agent performance.
Transparent Workspace Pricing and Plan Structure
Organizations can evaluate persistent workspaces with straightforward subscription terms. Monthly plans start with a 30-day free trial that requires a credit card. Teams can select from three subscription tiers:
Usage beyond plan allowances follows standard metered rates:
External collaborators accessing shared files do not consume organization member seats, keeping ongoing administrative costs predictable as teams scale their agentic operations.
Sources
References used to verify factual claims in this guide.
-
The native Claude Dropbox connector only permits saving text-based files such as .txt, .md, .html, and .py back to Dropbox, and does not support saving generated binary files like images or PDFs.
Frequently Asked Questions
How do I add Dropbox files to Claude Cowork?
You can connect Dropbox files to Claude Cowork either through Anthropic's native Dropbox connector or by syncing Dropbox folders to a Fast.io workspace. The native connector connects via OAuth 2.0 under Customize > Connectors, allowing Claude to browse your personal Dropbox folders directly. The Fast.io method syncs Dropbox folders into a dedicated workspace using Cloud Sync, automatically indexes the files for hybrid semantic search, and connects to Claude Cowork via a remote MCP endpoint.
Can Claude Cowork edit files in Dropbox?
Using the native connector, Claude can save generated content back to Dropbox, but only as text-based file formats such as .txt, .md, .html, and .py. The native integration cannot save binary formats such as images or PDFs. When using Fast.io with two-way Cloud Sync, agents can create and edit documents within the workspace using full per-file version history, and updates synchronize back to Dropbox during scheduled sync cycles.
Is Claude Cowork Dropbox integration secure for confidential data?
The native Dropbox connector respects existing user permissions in Dropbox, meaning Claude can only access files the authenticated user has permission to view. However, because the connector operates across all accessible folders, it can retrieve sensitive files if queries are broad. Fast.io enhances security by allowing administrators to sync only specific, project-scoped folders into an isolated workspace, keeping unrelated corporate data invisible to the agent while logging all operations in a detailed activity log.
Why does Claude Cowork experience rate limits when searching Dropbox?
The native connector treats cloud storage as a hierarchical directory tree, requiring multiple sequential API calls to list folders and download files. When an agent recursively inspects nested folders, high-frequency requests can exceed Dropbox API rate limits, returning HTTP 429 errors. Using Fast.io avoids this bottleneck because files are indexed during background sync, allowing Claude to query the local workspace index via MCP without repeated calls to Dropbox APIs.
How does Fast.io Cloud Sync handle updates between Dropbox and workspaces?
Fast.io Cloud Sync runs one-way or two-way synchronization between Dropbox folders and Fast.io workspaces on a schedule or on demand. It is never continuous, live, or real-time. When a scheduled sync completes, newly detected files are automatically processed by Intelligence Mode, updating the hybrid search index so new content is immediately available to Claude Cowork.
What file formats can Claude Cowork search in a Dropbox workspace?
Through Fast.io Intelligence Mode, Claude Cowork can search standard office documents, PDFs, presentations, spreadsheets, and markdown files using hybrid full-text and semantic search. For structured extraction from scanned documents, forms, and receipts, Fast.io Metadata Views extracts typed data fields across PDFs and images without manual OCR rules.
Related Resources

Connect Dropbox to Claude Cowork with pre-indexed search
Sync Dropbox folders to a Fast.io workspace, auto-index documents for hybrid semantic retrieval, and connect Claude Cowork via remote MCP. Monthly plans start with a 30-day free trial.