Claude Cloud Storage: Connecting Multi-Cloud Repositories via MCP
Claude cloud storage connects cloud file systems with Anthropic Claude models using Model Context Protocol (MCP) servers and workspace sync engines. Organizations store records across fragmented providers including Dropbox, Google Drive, Box, OneDrive, and SharePoint. Connecting Claude through an intelligent Fast.io workspace avoids tool call sprawl and unreadable file errors by indexing documents on arrival for remote MCP retrieval.

The Multi-Cloud Storage Context Barrier for Claude Models
Fastio publishes a head to head comparison of agent file work across Fastio and the major cloud storage providers at Fast.io Benchmarks. The same agent runs the same multi-document audit against each connector over an identical corpus, scored on completion time, connector calls, tokens consumed, and cost. Fastio completed the audit fastest and at the lowest cost of the connectors tested.
Claude cloud storage represents the integration of cloud file systems with Anthropic's Claude models using Model Context Protocol (MCP) servers and workspace sync engines. Production engineering teams, legal departments, and corporate operations groups rarely store all their documents in a single repository. Marketing collateral and product roadmaps live in Google Drive. Financial spreadsheets and legacy vendor contracts sit in Dropbox. Corporate policies, compliance binders, and board packages reside in Box. Enterprise project deliverables and cross-departmental records fill Microsoft OneDrive and SharePoint sites.
When organizations deploy Anthropic Claude models, such as Claude Opus, Claude Sonnet, or the terminal-based Claude Code agent, they want those models to analyze cross-repository records without requiring human staff to manually locate, download, and re-upload files. An operations lead preparing a customer renewal brief needs Claude to read the original Master Services Agreement in Dropbox, inspect project work orders in OneDrive, verify billing statements in Box, and cross-reference delivery sign-offs stored in Google Drive.
Connecting Claude to disparate storage environments presents immediate architectural friction. Most public guides suggest uploading individual files directly into Claude Projects in a web browser. This manual workflow hits strict project file quotas, creates duplicate versions of sensitive corporate documents, and fails as soon as team members edit files in the source drives. Other setups attempt to configure individual local MCP connectors for each platform, requiring separate credentials, distinct API rate limits, and conflicting authentication flows. When Claude must consult five storage providers to answer one question, point-to-point connections create operational instability.
Related guides
- Claude Code Remote MCP: Connecting Cloud Storage to Terminal AgentsA Claude Code remote MCP configuration connects Anthropic terminal-based agent to cloud-hosted MCP servers using HTTP...
- Connecting CrewAI Multi-Agent Teams to Box StorageA CrewAI Box connector enables autonomous multi-agent teams to query enterprise records without loading entire...
- How to Connect Claude Desktop to Box Storage via MCPClaude Box MCP connects Anthropic Claude Desktop to enterprise Box storage using the Model Context Protocol, giving...
- How to Connect Claude Desktop to Dropbox Files via MCPClaude Dropbox MCP allows Anthropic Claude Desktop to query, search, and retrieve files stored in Dropbox accounts...
- Claude OneDrive MCP: Connect Claude to Microsoft OneDrive via Fast.ioClaude OneDrive MCP connects Anthropic Claude models to Microsoft OneDrive storage for reading, searching, and...
- Can Claude Access OneDrive? Direct Connectors vs Workspace MCPClaude can access OneDrive files through manual file uploads, local desktop sync directory access in Claude Desktop, or...
More on this subject: Claude and Claude Code (249 guides)
Why Direct Storage Connectors Fail Autonomous Agents
Point-to-point cloud connectors and local filesystem tools encounter predictable technical bottlenecks when autonomous agents attempt to process complex document collections. While native integrations exist for individual storage platforms, running agents directly against raw cloud drives introduces four distinct failure modes.
Tool Call Sprawl and Directory Traversal Overhead
Standard cloud storage APIs are designed for human navigation, organizing records into nested folders and subfolders. When an autonomous Claude agent searches for specific answers across a raw cloud drive, it cannot inspect file contents in bulk. Instead, it must discover files by traversing directory hierarchies step by step.
The agent calls folder listing tools, parses path strings, inspects filenames, and downloads candidate files one by one. In a multi-department repository containing hundreds of documents, this sequential traversal creates severe tool call sprawl. Locating five relevant contractual terms across forty files can require over a hundred connector calls. Each round trip introduces network latency, burns execution budget, and increases the likelihood of client timeouts.
Context Window Exhaustion and Prompt Dilution
When a direct storage connector reads a file, it pulls the complete document stream into Claude's prompt. If an agent needs to verify a single liability cap inside an eighty-page supplier agreement, the connector forces the model to ingest tens of thousands of tokens of standard boilerplate text.
Loading multiple complete files into Claude's context window quickly exhausts token allowances and drives up inference costs. Context dilution degrades retrieval quality: as the prompt fills with irrelevant legalese and repetitive headers, the model's ability to recall specific facts diminishes, leading to missed clauses or inaccurate summaries.
Unreadable Scanned Documents and Missing OCR
Enterprise archives contain scanned PDF contracts, image-based invoices, signed amendments, and handwritten receipts. Cloud storage APIs return raw binary files without parsing them. When an agent opens an image-only PDF through a standard storage connector, it receives an empty text layer or raw binary markers.
When this failure mode hits a scanned credit memo or a signed amendment, the underlying facts stay invisible to the agent and the audit ends up with a hole in it. Without automated text extraction and optical character recognition during ingestion, direct storage connections cannot guarantee document completeness.
API Rate Throttling and Files-on-Demand Stubs
High-frequency polling by autonomous models places heavy stress on third-party cloud APIs. Storage providers enforce strict per-minute rate limits to protect infrastructure. When an agent issues rapid bursts of file search and download requests across deep folder structures, cloud endpoints return HTTP 429 rate limit errors.
Local filesystem integrations face an even harsher failure mode: placeholder stubs. Cloud synchronization clients like Microsoft OneDrive and Dropbox conserve local disk space by using Files On-Demand features, leaving dataless placeholder stubs in local directories. When an agent running in a terminal or local desktop client attempts to read an unhydrated placeholder file, the read returns 0 bytes or blocks the filesystem thread while attempting to download the file over the network, causing unhandled I/O exceptions and halting agent execution.
Connecting Multi-Cloud Repositories via Fast.io Remote MCP
To solve the limitations of point-to-point connectors, engineering teams use a unified workspace architecture. Instead of migrating data out of established cloud repositories, organizations retain Dropbox, Google Drive, Box, and OneDrive as their official systems of record. Teams synchronize the relevant folders from each platform into a Fastio workspace. Fast.io serves as an intelligent retrieval layer, indexing documents in the cloud and exposing them to Claude through a consolidated remote Model Context Protocol endpoint.
Cloud Sync operates for Dropbox, Box, and OneDrive folders, supporting one-way or two-way synchronization on a recurring schedule or on demand. Google Drive imports today, with recurring sync coming soon. Sync operations execute on scheduled intervals rather than real-time file streams, protecting source storage quotas while keeping workspace indexes up to date.
Setting up a multi-cloud Claude integration follows five practical steps:
- Step 1: Create a Fast.io organization and workspace. Creating an account is free; active workspaces run within an organization on a paid subscription. Monthly plans start with a trial of up to 30 days (credit card required); annual plans have no trial. Paid subscription tiers on Fast.io pricing include Starter, Business, and Enterprise options.
- Step 2: Connect external storage repositories. Navigate to Cloud Import in the Fast.io interface. Authorize your storage accounts using OAuth for Google Drive, Dropbox, Box, and Microsoft OneDrive. Select the specific project folders you want to make accessible to Claude. Fast.io mirrors the folder hierarchy into your workspace without altering source files.
- Step 3: Enable Intelligence Mode. In workspace settings, confirm that Intelligence Mode is active. Fast.io parses incoming files on arrival, extracting text layers from PDFs, Word documents, spreadsheets, presentations, and scanned records, building semantic embeddings and full-text indexes.
- Step 4: Configure Claude Desktop or Claude Code. The Fast.io MCP server is remote, hosted over Streamable HTTP at
https://mcp.fast.io/mcp/toolsfor Claude Desktop andhttps://mcp.fast.io/mcp/codefor Claude Code. It is not an npm package and requires no local node daemon.
For Claude Desktop, open Customize, then Connectors, add a custom connector, and paste https://mcp.fast.io/mcp/tools. Select Connect, sign in to Fast.io in the window that opens, and turn Fast.io on in a chat from the + menu under Connectors.
For developers running Claude Code CLI in terminal environments, register the remote server directly with the command line interface:
claude mcp add --transport http fastio https://mcp.fast.io/mcp/code
Then run /mcp inside Claude Code to sign in.
- Step 5: Query cross-cloud files with citations. Launch Claude Desktop or Claude Code. Claude automatically discovers the consolidated MCP toolset. You can now prompt Claude to search, cross-reference, and summarize records across all connected cloud repositories within a single conversational turn.


Unify Cloud Repositories for Claude via Remote MCP
Connect Claude to indexed Google Drive, Dropbox, Box, and OneDrive folders with hybrid search, metadata extraction, and multi-agent coordination. Starts with a 30-day free trial.
Performance Analysis: Why Indexed Search Eliminates Tool Call Sprawl
The architectural contrast between raw cloud storage APIs and an intelligent workspace centers on how retrieval is executed. In a raw connector setup, retrieval is client-driven: Claude acts as the search engine, inspecting directories and downloading entire byte streams. In an intelligent workspace, retrieval is index-driven: Fast.io preprocesses documents upon arrival, allowing Claude to execute targeted search queries that return exact excerpts with page citations.
The operational impact of this difference is documented in Fast.io Benchmarks, which runs the same agent on the same multi-document audit against Fastio, Dropbox, Box, Google Drive, and OneDrive over an identical corpus. Fastio finished the audit fastest and at the lowest cost of the connectors tested.
Hybrid Search Across Cloud Repositories
Fast.io combines exact full-text keyword matching with semantic vector retrieval. When Claude needs to answer a prompt regarding payment defaults or contract renewal schedules, it does not download forty separate documents. It issues a single search query through the consolidated MCP toolset.
The workspace searches across file titles, metadata, and extracted body text, returning matching passages alongside exact document names and page numbers. Claude receives the factual context necessary to answer the prompt in one turn, avoiding round-trip latency and preserving token budgets.
Structured Extraction with Metadata Views
Standard search is ideal for narrative questions, but finance and legal operations often require structured tables across hundreds of cloud documents. Fast.io provides Metadata Views, turning unstructured files into queryable relational grids.
Teams define the fields they need extracted in natural language, such as contract counterparty, effective date, governing law, renewal notice period, and total contract value. AI constructs a typed schema using seven supported field types: Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time. Fast.io scans matching documents across your connected Google Drive, Dropbox, Box, and OneDrive folders (Google Drive imports today with sync coming soon), populating the grid without requiring rigid OCR templates or manual data entry.
New columns can be added at any time without reprocessing existing files. Autonomous Claude agents can query Metadata Views through the MCP server, filtering documents by structured attributes before opening specific files.
Comprehensive Processing for Scanned Media
Unlike direct storage connectors that pass unparsed binary files, Fast.io automatically extracts text from scanned pages, PDFs, and image files during ingestion. The extracted text layers are indexed alongside native digital documents, ensuring that legacy scanned credit memos, handwritten delivery notes, and counter-signed contract amendments remain fully visible to Claude during compliance checks.
Multi-Agent Coordination and Governance for Cloud Records
Modern enterprise AI deployments rarely feature a single user interacting with Claude in isolation. Organizations deploy multiple autonomous agents across teams: Claude Code in terminal environments refactoring codebases, Cursor generating application logic, and custom agents processing customer tickets or reconciling vendor accounts.
When multiple AI agents and human teammates interact with files sourced from multi-cloud repositories, uncoordinated access can cause version collisions, untracked changes, and unauthorized data exposure. Fast.io provides an integrated governance and collaboration framework:
- Per-File Version History. Every file in a Fast.io workspace maintains complete version history. If an autonomous Claude agent overwrites an existing document or generates an inaccurate revision, previous file versions remain accessible. Human operators can inspect changes and restore prior versions at any time.
- Granular Permission Controls. Access controls can be enforced across organizations, workspaces, folders, and individual files. Developers can generate API keys scoped strictly to an individual project folder, preventing agents from accessing sensitive legal records or personnel files located in adjacent directories.
- Collaborative Notes. Fast.io Notes provides real-time co-editing with live multiplayer cursors for human teammates and AI agents. Claude can write research briefs, draft executive summaries, and record audit observations directly inside a collaborative note where team members can review the output live. Notes are indexed alongside files for workspace grounding.
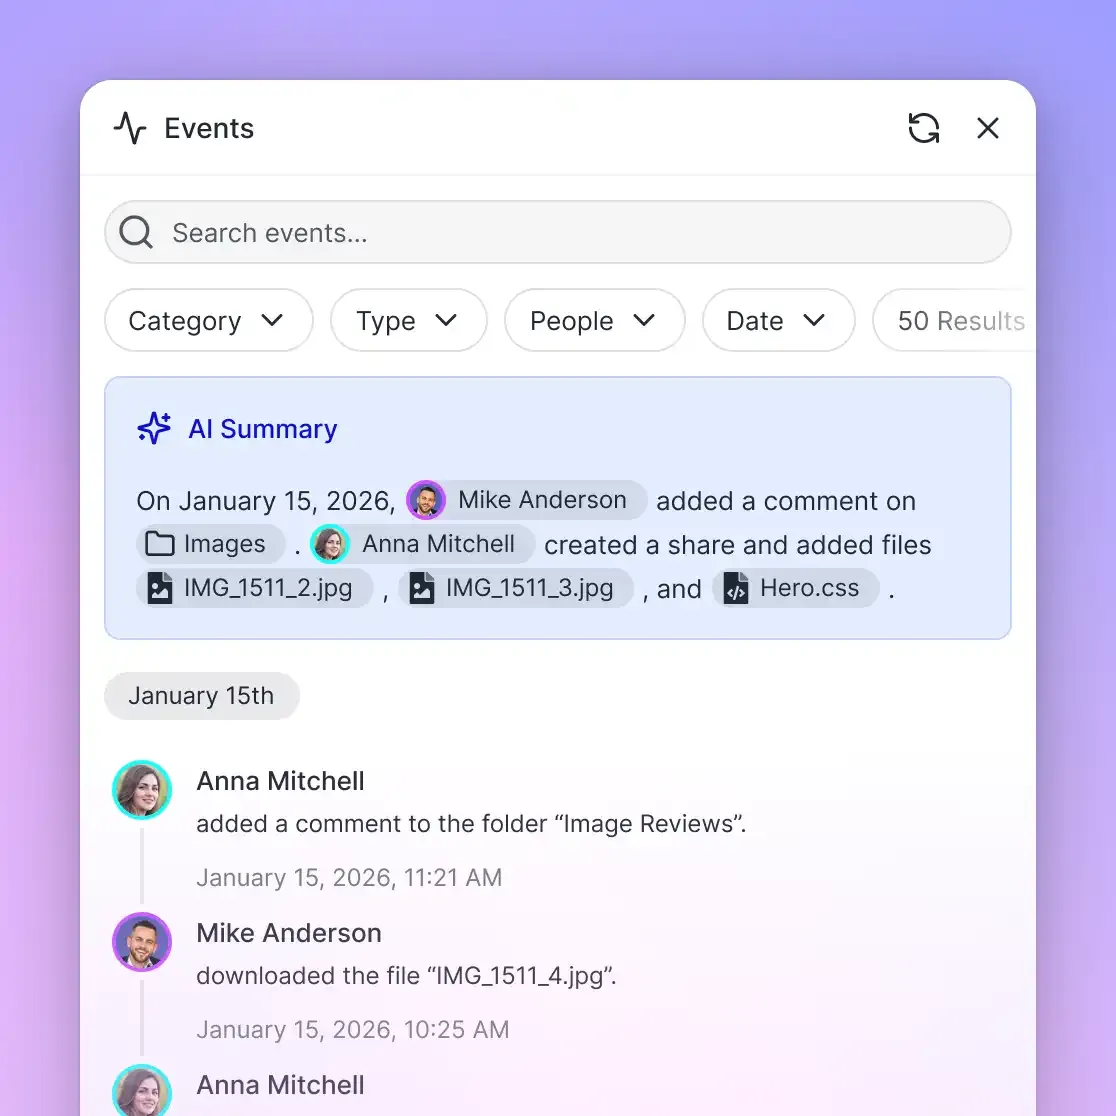
- Activity Log. Every file creation, read operation, edit, metadata update, and download is recorded in a detailed activity log. Security officers and engineering leads can review a record showing which agent accessed specific cloud documents and what operations were performed.
- Ownership Transfer. Developers or external consultants can create an organization, configure multi-cloud sync folders, establish Metadata Views, and test Claude agent workflows under an agent account. Once the implementation is verified, ownership of the entire organization can be transferred to the client or business stakeholder through a secure claim link while the creator retains administrative access.
Step-by-Step Implementation: Building a Cross-Cloud Audit with Claude Code
To demonstrate the practical mechanics of Claude cloud storage, consider an enterprise customer audit workflow. An operations team maintains customer contracts in Google Drive, historical invoices in Dropbox, and service agreements in OneDrive. The team needs an automated Claude Code agent to audit the entire relationship, calculate billing totals, verify renewal notice periods, and flag discrepancies.
1. Ingesting Multi-Cloud Folders into the Workspace
The team connects the customer's Google Drive, Dropbox, and OneDrive folders to Fast.io using Cloud Import. Google Drive imports files immediately (with recurring sync coming soon), while Dropbox and OneDrive folders maintain scheduled two-way sync. The files are organized into a single workspace:
/Customer-AcmeCorp/
├── contracts/          (synced from Dropbox)
│   ├── MSA_2024.pdf
│   └── Amendment_1.pdf
├── billing/            (synced from OneDrive)
│   ├── INV-1041.pdf
│   ├── INV-1088.pdf
│   └── CreditMemo_Scan.pdf
└── statements-of-work/ (imported from Google Drive)
    ├── SOW_Phase1.pdf
    └── SOW_Phase2.pdf
2. Querying the Unified Workspace from the Terminal
With the Fast.io remote MCP server registered in Claude Code, the developer opens a terminal session and prompts the agent:
Audit all documents in the Customer-AcmeCorp workspace. Identify the governing law,
calculate total invoiced amounts versus approved SOW values, verify whether any credit
memos exist, and report the required termination notice window.
3. Execution via the Consolidated MCP Toolset
Instead of issuing dozens of sequential directory listing requests across three cloud accounts, Claude Code calls the Fastio search tool to run keyword and semantic search across the workspace documents.
Fast.io evaluates the query against its vector embeddings and text indexes. The search endpoint returns relevant passages with exact file names, page numbers, and extracted dollar amounts.
4. Review and Verified Output
Claude Code parses the returned snippets and compiles a structured reconciliation brief. Because Fast.io performed automated text extraction during ingestion, the agent successfully reads the scanned credit memo that would have caused read errors in raw connectors. Claude outputs the verified brief with exact document citations, drafts a summary in a Collaborative Note, and logs the execution in the activity log.
Sources
References used to verify factual claims in this guide.
-
Anthropic introduced the Model Context Protocol as an open standard to connect AI assistants to external content repositories and data systems.
Frequently Asked Questions
How do I connect Claude to external cloud storage?
You can connect Claude to external cloud storage using Model Context Protocol (MCP) servers. For local single-provider setups, you can configure desktop MCP servers for Google Drive or Dropbox. For multi-cloud environments across Dropbox, Box, and OneDrive (alongside Google Drive import, with sync coming soon), you can connect folders into an intelligent Fast.io workspace and link Claude Desktop or Claude Code to the Fast.io remote MCP endpoints at `https://mcp.fast.io/mcp/tools` (Claude Desktop) and `https://mcp.fast.io/mcp/code` (Claude Code).
Can Claude Code read documents from cloud drives?
Claude Code can read cloud documents when configured with an MCP server supporting Streamable HTTP. By running `claude mcp add --transport http fastio https://mcp.fast.io/mcp/code` and signing in with `/mcp`, Claude Code gains access to a consolidated MCP toolset that queries indexed files across synced cloud repositories directly from the terminal.
What is the fastest way to search cloud files with Claude?
The fastest way to search cloud files with Claude is through an indexed workspace using hybrid search. Fastio publishes a head to head comparison of agent file work at https://fast.io/benchmarks/, where the same multi-document audit is run against each major storage connector over an identical corpus, and Fastio completed it fastest and at the lowest cost.
How does Fast.io handle scanned PDFs and image files from cloud drives?
Fast.io automatically extracts text layers and performs optical character recognition during file ingestion. Scanned invoices, signed PDF amendments, and image files are converted into searchable text and indexed alongside digital documents, preventing the unreadable file errors common in raw cloud storage connectors.
What is the difference between local filesystem MCP servers and remote cloud storage MCP servers?
Local filesystem MCP servers point directly to a directory on your machine, but cloud sync clients often leave 0-byte Files-on-Demand placeholder stubs that return empty files or crash agent threads. Remote cloud storage MCP servers connect to cloud-hosted workspaces that index files centrally, eliminating local storage bottlenecks and supporting headless server environments.
Related Resources

Unify Cloud Repositories for Claude via Remote MCP
Connect Claude to indexed Google Drive, Dropbox, Box, and OneDrive folders with hybrid search, metadata extraction, and multi-agent coordination. Starts with a 30-day free trial.