OneDrive Indexing for AI Agents: Efficient Document Search & Retrieval
Autonomous AI agents attempting to read OneDrive files locally can hit read failures when Files On-Demand placeholders cannot be downloaded in the agent's environment. Implementing OneDrive indexing for AI agents bridges this gap by syncing OneDrive and SharePoint directories directly into indexed cloud workspaces. Through remote Model Context Protocol (MCP) endpoints, agents search document excerpts semantically rather than downloading bulk directories or failing on cloud stubs.

The Cloud-Only Stub Dilemma: Why AI Agents Fail on OneDrive Files On-Demand
When an autonomous AI agent inspects a locally mounted OneDrive folder to read reference specifications, it can come back with an error or nothing usable instead of documentation. Under Microsoft Windows Files On-Demand, cloud-backed documents appear in directory listings with their reported file sizes, but online-only files exist on disk as NTFS reparse points that take up no local space. Opening one triggers a download through the OneDrive sync client. For an agent running where that client is not available (a headless container, a service account, or a cloud execution environment), the read fails, and an agent that treats the failure as an empty file can produce silent execution failures or context hallucinations.
Relying on a desktop-mounted OneDrive Files On-Demand folder as an AI index pipeline breaks down when online-only files cannot be hydrated in the agent's runtime. OneDrive indexing for AI agents provides automated parsing and indexing of Microsoft OneDrive directories so autonomous coding and research agents can retrieve specific document excerpts via MCP. Without automated indexing, engineering teams typically attempt to point agents directly at synchronized desktop folders or raw storage buckets. When desktop sync clients manage those directories, the underlying operating system virtualizes file storage to conserve local disk space.
On Windows systems, Microsoft implements Files On-Demand through the Cloud Files Filter Driver (cldflt.sys). When Files on Demand is enabled in OneDrive, all synced files and folders are implemented as reparse points. These filesystem objects carry specific metadata attributes, including FILE_ATTRIBUTE_RECALL_ON_DATA_ACCESS and FILE_ATTRIBUTE_RECALL_ON_OPEN. When an application such as Microsoft Word opens a placeholder in a signed-in session with OneDrive running, the operating system pauses the read, the sync client downloads the file payload from cloud servers, and execution returns to the application.
Autonomous agents often run outside that session. Headless continuous integration workers, scheduled tasks under service accounts, containerized research processes, and Linux sandboxes have no OneDrive client to hydrate the file. When a Python script or Node.js agent reads an online-only placeholder there, the call fails with a cloud file error instead of returning the document. Damaged placeholders produce reparse point errors such as 0x80071129 ("The tag present in the reparse point buffer is invalid"), which Microsoft documents for OneDrive-synced files. If the agent's tooling swallows the error and carries on, the agent proceeds as if the file is blank, producing false assumptions, inaccurate code generation, or abrupt execution termination.
How Failed Placeholder Reads Cause Agent Context Poisoning
The technical failure mode of cloud placeholders extends beyond simple permission errors. When an agent scans a directory using standard POSIX or Win32 file enumeration APIs, the file metadata reports the full cloud logical size. An agent planning a retrieval workflow reads the directory table, calculates token budgets based on the reported file sizes, and schedules retrieval passes.
When the agent then opens the file, hydration fails or times out. Many agent tools catch read errors and return an empty result rather than stopping, so the agent concludes that the document exists but contains no text.
This behavior poisons the agent's reasoning loop. Instead of requesting administrative intervention or flagging a missing asset, the model assumes the file was intentionally left blank. In software development workflows, an agent attempting to parse an interface definition file might generate duplicate, conflicting classes because the canonical contract appeared empty. In research operations, an agent summarizing technical policy documents misses critical compliance clauses entirely while reporting full job completion.
The Limitation of Local Sync Workarounds
Teams often attempt to solve this problem by disabling Files On-Demand entirely, forcing the local OneDrive client to maintain full offline copies of every directory. While this guarantees hydrated disk blocks, it creates three severe operational bottlenecks for modern development teams:
- Disk exhaustion on developer machines: Engineering repositories, architectural diagrams, and company documentation archives easily exceed available local storage on developer laptops and cloud virtual workstations.
- Sync latency and local lock contention: Local OneDrive desktop sync clients operate on desktop polling intervals. When multiple team members or automated agents modify files simultaneously, desktop clients produce conflicting copies, renaming files with workstation suffixes that break hardcoded agent paths.
- Total failure in headless environments: Production AI agents operate on Linux cloud containers, Kubernetes clusters, and serverless sandboxes where native Microsoft OneDrive sync clients cannot run. Linux FUSE mounts such as
onedriverorrclonewith on-demand caching add daemon dependencies and cache state that can misbehave under concurrent multi-agent read patterns.
Related guides
- How to Search OneDrive with ChatGPT: Efficient Cloud File AccessSearching OneDrive with ChatGPT enables ChatGPT to inspect and retrieve specific information from OneDrive files using...
- ChatGPT OneDrive Plugin: Fast File Retrieval Without Graph API DelaysA ChatGPT OneDrive plugin allows OpenAI models to query and summarize Word documents, Excel spreadsheets, and PDFs...
- OneDrive AI Search: Semantic Search and Agent Access for OneDriveOneDrive AI search enables users and autonomous agents to locate documents and extract precise answers from OneDrive...
- Can ChatGPT Access OneDrive? Workflows, Admin Limits & Fast StorageChatGPT can access OneDrive files through its cloud storage connector, but personal accounts remain unsupported while...
- How to Connect LangChain to OneDrive Files for AI AgentsConnecting LangChain to Microsoft OneDrive gives AI agents access to corporate documents, but loading deep directories...
- How to Connect LangGraph Agent Workflows to OneDrive DocumentsConnecting LangGraph to OneDrive enables cyclic agent workflows and state machines to retrieve, synthesize, and ground...
More on this subject: AI Agents: General Guides (190 guides)
Comparing Architectures for Indexing OneDrive Files for AI Agents
Connecting AI agents to enterprise documentation stored in OneDrive requires balancing retrieval speed, computational overhead, and operational reliability. Today, engineering organizations choose between three primary architectures: local filesystem synchronization, direct integration with the Microsoft Graph API, and cloud workspace indexing via Fastio.
Local sync clients rely on desktop operating system drivers that break down in automated pipelines. Direct Microsoft Graph API integrations eliminate local filesystem stubs by querying Microsoft 365 cloud endpoints directly. However, Microsoft Graph introduces significant integration friction. Developers must configure complex Microsoft Entra ID app registrations, negotiate broad tenant-wide permissions (Files.Read.All or Sites.Read.All), and handle aggressive HTTP 429 rate limits when agents run bulk indexing passes.
Furthermore, Microsoft Graph's standard search returns matching files and short hit highlights rather than passages chunked for language model context windows. An agent querying Graph for a specific deployment configuration often downloads entire multi-megabyte PDF manuals to read them, burning model token budgets on irrelevant context.
Fastio offers a clean alternative: Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. When teams sync OneDrive for AI agent workflows using Cloud Sync, the engine operates server-to-server directly through cloud storage APIs, eliminating local filesystem stubs, disk hydration failures, and machine dependencies. SharePoint document libraries connect through the OneDrive connector, pulling organization knowledge into shared workspaces without client-side sync daemons.
Once files arrive in a Fastio workspace with Intelligence Mode enabled, documents are indexed automatically for hybrid search, combining full-text indexing, vector semantic search, and metadata-value filtering. For structured extraction, Metadata Views turn documents into queryable tables by extracting typed schema fields without manual OCR rules. Autonomous agents connect through remote Model Context Protocol (MCP) endpoints, querying targeted excerpts and structured fields over Streamable HTTP instead of downloading bulk files.
In connector comparisons published at fast.io/benchmarks/, Fastio was measured the fastest and lowest cost of the providers tested. Serving indexed semantic excerpts directly from Fastio workspaces prevents cloud stub read failures and keeps context consumption focused.
Architectural Comparison Matrix
The table below contrasts the mechanical differences between local sync clients, direct Microsoft Graph API calls, and Fastio cloud workspace indexing:
Four Steps to Connect AI Agents to Indexed OneDrive Workspaces
Transitioning from brittle local file mounts to an indexed cloud workspace requires four straightforward setup phases. This workflow connects your existing Microsoft OneDrive or SharePoint document libraries to Fastio, enables automatic semantic indexing, and exposes the corpus to your AI agents via remote MCP endpoints.
Step 1: Connect OneDrive via Cloud Sync
Begin by creating a dedicated workspace inside your Fastio organization. Rather than migrating your organization away from Microsoft 365, Cloud Sync links your existing cloud storage into Fastio:
- In the target workspace, open Cloud Sync.
- Choose Microsoft OneDrive as the external provider.
- Authorize the connection using your Microsoft 365 administrative or user credentials through OAuth.
- Select the specific OneDrive folder or SharePoint document library to synchronize.
- Configure sync parameters: choose one-way sync (OneDrive to Fastio) to protect source archives from agent modifications, or two-way sync if agents need to write reports back to Microsoft 365. Set the sync frequency to execute on a predictable schedule or trigger sync runs on demand.
Because Cloud Sync runs entirely cloud-to-cloud, file transfers execute between data center backbones. Documents arrive in Fastio fully populated, completely bypassing the local NTFS filter driver and eliminating dehydrated placeholder stubs.
Step 2: Enable Intelligence Mode and Configure Metadata Views
After configuring Cloud Sync, turn on Intelligence Mode in the workspace settings. Intelligence Mode then indexes incoming documents automatically, extracting text, generating vector embeddings, and building a unified hybrid index:
- Full-text search indexes exact keyword tokens, part numbers, variable names, and error strings.
- Semantic search indexes conceptual relationships, allowing agents to find relevant sections even when queries use different phrasing than the source text.
- Metadata search filters on field values extracted by Metadata Views, such as a contract date or an amount.
If your OneDrive directory contains structured operational documents such as invoices, service contracts, or system architecture manifests, configure Metadata Views. Metadata Views allow teams to describe target data fields in natural language. Fastio automatically designs a typed schema (such as Text, Integer, Boolean, URL, JSON, and Date) and extracts structured values across PDFs, Word documents, and spreadsheets into a queryable table. Agents can query these structured columns directly via MCP without running expensive text parsing routines on raw documents.
Step 3: Connect Your AI Agent to the Remote Fastio MCP Server
Fastio provides remote Model Context Protocol servers operating over Streamable HTTP. Connecting your agent requires no local Python packages, no custom daemon bridges, and no complex Entra ID app registrations.
Choose the appropriate MCP endpoint based on the agent client you run:
- Coding agents (Claude Code, Cursor, Cline, Devin, GitHub Copilot): use
https://mcp.fast.io/mcp/code - General conversational agents (Claude apps, OpenClaw, Hermes Agent): use
https://mcp.fast.io/mcp/tools - Automated scripts and backend pipelines: use
/mcp/codefor search and execution tools, or/mcp/toolsfor named storage tools
For IDE coding agents like Cursor, add the remote endpoint to your configuration file (~/.cursor/mcp.json or .cursor/mcp.json in your project root):
{
  "mcpServers": {
    "fast-io": {
      "url": "https://mcp.fast.io/mcp/code"
    }
  }
}
For terminal environments using Claude Code, add the connection via the CLI:
claude mcp add --transport http fast-io https://mcp.fast.io/mcp/code
Then run /mcp inside Claude Code to complete authentication. When running personal desktop agents, authentication completes securely via OAuth in your browser. For automated background services, sandboxes, or headless server agents, pass a scoped API key on the connection using the standard header Authorization: Bearer <api_key>. Complete setup documentation and endpoint parameters are maintained at mcp.fast.io/docs.
Step 4: Execute Semantic Excerpt Retrieval via MCP
Once connected, the agent interacts with your indexed OneDrive repository using native MCP tool calls. When a coding agent needs architectural context, it calls the search tool on the /mcp/code endpoint instead of downloading entire files.
An agent query executes as a standard JSON-RPC tool invocation:
{
  "jsonrpc": "2.0",
  "method": "tools/call",
  "params": {
    "name": "search",
    "arguments": {
      "query": "authentication token refresh flow and timeout settings",
      "workspace_id": "1234567890123456789"
    }
  },
  "id": 1
}
The Fastio MCP server executes a hybrid search against the workspace index and returns only the matching paragraphs, source file names, section headings, and citation references. The agent receives precise context in a small fraction of the tokens it would spend loading a complete PDF specification.


Index OneDrive Files for Your AI Agents Without Stub Failures
Connect your OneDrive and SharePoint folders to an intelligent Fastio workspace. Enable semantic retrieval across your documentation via remote MCP with a 14-day free trial.
Operational Patterns: Concurrency, Access Scopes, and Multi-Agent Collaboration
Production AI deployments rarely involve a single agent reading static files. Multiple autonomous agents, automated CI pipelines, and human engineers frequently collaborate across the same documentation repository. Maintaining data integrity requires explicit synchronization policies, clear access boundaries, and dependable change auditing.
Cloud Sync operates on a defined schedule or on demand. When team members edit documents in Microsoft 365, Fastio pulls updated files during scheduled sync windows. When an agent needs immediate verification of an external change before starting a critical operation, it can trigger an on-demand sync pass via the Fastio API.
To keep external consumers and autonomous agents synchronized without polling overhead, Fastio provides a workspace events feed. Agents subscribe to workspace activity over a persistent WebSocket connection or HTTP long-poll. When a synchronized OneDrive document updates, the events feed emits a notification containing the modified file identifier, allowing agents to invalidate local caches or trigger downstream reasoning passes.
Advisory File Locks and Per-File Version History
When multiple agents or humans write to the same workspace, write collisions can corrupt project assets. Fastio implements advisory file locks to coordinate multi-agent operations across workspace files.
An agent preparing to update an architectural specification or write an automated summary acquires an advisory lease through the MCP storage_manage tool using the lock-acquire action. The lock status is visible to other members through lock-status on the storage tool. The lease expires unless it is renewed, and the agent releases it with lock-release when the job finishes.
Advisory locks help agents avoid accidental overlap while preserving accessibility: concurrent writes are not blocked, and Fastio records every change in per-file version history. If an agent produces an invalid modification, human operators can inspect historical versions and restore prior revisions through the workspace interface or API.
Granular Role-Based Access Controls
Enterprise security teams often hesitate to expose corporate OneDrive folders to autonomous agents due to over-permissioning risks. Connecting an agent directly to Microsoft Graph with the application permission Files.Read.All grants that agent potential read visibility across every user drive in the tenant.
Fastio enforces role-based access permissions at the organization, workspace, and share levels. Permissions are never applied at the individual folder or file level, ensuring clear, predictable boundaries.
To establish secure containment:
- Create dedicated workspaces for specific functional areas (such as engineering specifications, marketing assets, or customer support documentation).
- Sync only the relevant OneDrive folders or SharePoint libraries to each target workspace.
- Assign agents scoped credentials restricted to the designated workspace. An agent working on frontend implementation cannot read executive financial spreadsheets stored in a separate workspace.
- When sharing specific agent outputs or research folders with external clients or partner agencies, generate a branded share (Send, Receive, or Exchange) that provides scoped link access with optional download restrictions and expiration dates, without exposing the underlying workspace or OneDrive repository.
Auditing Multi-Agent Workflows with the Detailed Activity Log
Enterprise governance requires complete visibility into how autonomous agents interact with corporate knowledge. Fastio maintains a detailed activity log that records modifications across every workspace and organization.
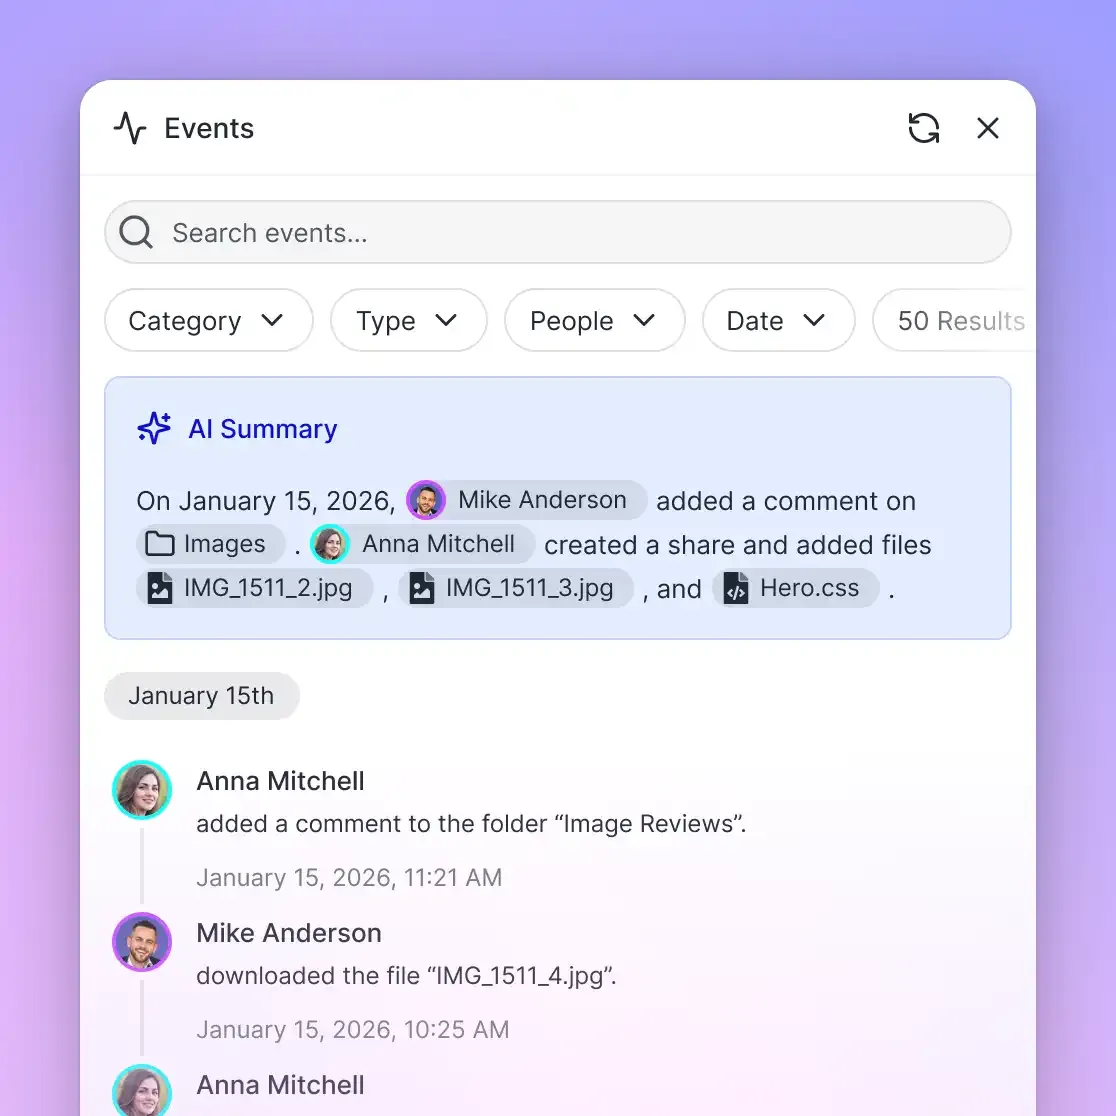
The detailed activity log captures structural and content changes: file uploads, document edits, file moves, deletions, membership updates, and share creation events. Each entry identifies the actor, distinguishing between human collaborators and specific automated agent credentials. The activity log tracks change events rather than read-only file views or downloads, giving operations teams a clean record of file modifications without clutter.
Troubleshooting OneDrive Indexing for Autonomous AI Agents
Deploying automated indexing pipelines across enterprise storage environments occasionally surfaces edge cases. Understanding common error states prevents downtime and ensures consistent retrieval quality.
Resolving Corrupt Reparse Points and Local Dehydration Errors
If developers run local agents against workstation OneDrive mounts and encounter error 0x80071129, Microsoft attributes it to damaged reparse points on synced files.
To repair the local filesystem:
- Open an Administrator Command Prompt on Windows and run
chkdsk C: /R /F(substituting the affected volume) to repair the damaged reparse points. - If errors persist, reset the desktop sync client by running
%localappdata%\Microsoft\OneDrive\onedrive.exe /reset. - For production workflows, eliminate workstation dependencies completely by migrating the retrieval path to Fastio Cloud Sync, running server-to-server synchronization directly into an indexed workspace.
Mitigating Microsoft Graph API Throttling
When agents query Microsoft Graph directly during large-scale indexing passes, Graph can respond with HTTP 429 Too Many Requests and a Retry-After header. Graph applies per-tenant and per-app request limits that multi-agent workloads can quickly reach.
Offloading document indexing to Fastio Cloud Sync resolves this bottleneck. Fastio runs server-to-server synchronization on defined schedules or on demand, and indexes the synced content in the workspace. Agent queries hit the Fastio MCP endpoint over Streamable HTTP, drawing from indexed vector and keyword stores without consuming Microsoft Graph rate limits.
Handling Large Documents and Context Ceilings
Enterprise documentation often includes dense technical manuals, regulatory guidelines, and system logs spanning hundreds of pages. If an agent attempts to ingest a 100-page system specification directly into prompt memory, it risks exceeding model context limits or triggering HTTP 413 Payload Too Large errors.
Fastio Intelligence Mode segments large documents during ingestion. When an agent queries the repository via MCP search, the server evaluates chunk relevance and returns compact excerpts with source citations.
For structured extractions across massive file sets, configure Metadata Views to extract key metrics (such as SLA commitments, endpoint URLs, and software dependencies) into structured columns. The agent queries the structured view to find exact values without scanning thousands of pages of unstructured text.
Connecting SharePoint Document Libraries
Many organizations store team knowledge in Microsoft SharePoint or OneDrive for Business rather than personal OneDrive drives. In Fastio, SharePoint document libraries synchronize directly through the OneDrive Cloud Sync connector.
Indexing OneDrive for Business this way allows teams to index corporate SharePoint libraries and business drives without exposing broad tenant credentials to autonomous agents. When setting up Cloud Sync, authenticate using an account with appropriate SharePoint site permissions, then select the target SharePoint library. Syncing it brings corporate policies, engineering documentation, and shared project assets into the Fastio workspace, making team knowledge searchable for your autonomous agents while preserving your existing Microsoft 365 storage hierarchy.
Sources
References used to verify factual claims in this guide.
-
When Files on Demand is enabled in OneDrive, all synced files and folders are implemented as reparse points.
Frequently Asked Questions
How do AI agents access and index OneDrive files?
AI agents can access OneDrive files through local filesystem mounts, direct Microsoft Graph API integrations, or cloud workspace indexing platforms like Fastio. Local filesystem mounts frequently fail because OneDrive Files On-Demand leaves online-only placeholders that cannot be downloaded in headless environments. Fastio solves this by using Cloud Sync to connect OneDrive and SharePoint folders server-to-server on a schedule or on demand. Once synchronized, Fastio Intelligence Mode indexes documents for hybrid search, allowing agents to retrieve semantic excerpts via remote Model Context Protocol (MCP) endpoints.
What happens when an AI agent tries to read a OneDrive cloud-only stub?
An online-only OneDrive Files On-Demand file is a placeholder (an NTFS reparse point on Windows) that takes up no local space until the OneDrive client downloads it. In headless scripts, Docker containers, service accounts, or other sessions where the OneDrive client is not running, that download cannot happen and the read fails. If the agent's tooling treats the failure as an empty file, the agent assumes the file is blank, resulting in context poisoning and hallucinations.
How does Fastio Cloud Sync index OneDrive for AI agents?
Fastio Cloud Sync connects directly to Microsoft OneDrive and SharePoint document libraries via cloud APIs, transferring files server-to-server without local disk stubs or desktop sync clients. Sync runs one-way or two-way, on a schedule or on demand. Once files land in the Fastio workspace, Intelligence Mode parses and auto-indexes documents for hybrid search (combining full-text, vector semantic, and metadata-value retrieval). Agents then query specific document excerpts over Streamable HTTP using Fastio remote MCP endpoints.
Can AI agents index SharePoint document libraries through OneDrive?
Yes. Fastio Cloud Sync connects to Microsoft SharePoint document libraries directly through the OneDrive connector. By authenticating with Microsoft 365 credentials that have access to the target SharePoint sites, administrators can select corporate document libraries and sync them into a Fastio workspace. The synchronized SharePoint documents are automatically indexed by Intelligence Mode and made queryable to AI agents via MCP.
What permissions and plans support OneDrive indexing in Fastio?
Connecting OneDrive requires an authorized Microsoft 365 account with read permissions to the target folder or SharePoint document library. Within Fastio, permissions are managed per organization, workspace, and share. Monthly plans start with a 14-day free trial that requires a credit card, providing full access to Cloud Sync, Intelligence Mode, and remote MCP endpoints. See the [pricing](/pricing/) page for plan options.
Related Resources

Index OneDrive Files for Your AI Agents Without Stub Failures
Connect your OneDrive and SharePoint folders to an intelligent Fastio workspace. Enable semantic retrieval across your documentation via remote MCP with a 14-day free trial.