OneDrive Agent: Connecting AI Agents to OneDrive File Storage
An OneDrive agent connects autonomous AI models to cloud file storage, allowing systems like Claude and Cursor to inspect, query, and update documents across Microsoft 365. While local filesystem sync triggers hydration errors and direct API calls hit throttling limits, connecting an agent to an indexed workspace via remote Model Context Protocol (MCP) provides targeted semantic search without pulling entire directory trees.

The Architecture of a OneDrive Agent
When an autonomous AI agent attempts to read files from a local OneDrive directory, it frequently crashes into zero-byte placeholder stubs, triggers unexpected bulk cloud downloads, or consumes millions of context tokens traversing raw folder trees. An OneDrive agent is an AI agent equipped to read, analyze, and update files located across personal or business OneDrive storage directories. Building reliable OneDrive agentic workflows on top of Microsoft 365 requires understanding how models interact with enterprise storage systems and where standard file synchronization primitives fall short.
Configuring a dedicated OneDrive AI agent allows engineering teams to delegate complex document analysis tasks to models like Claude Code, Cursor, Cline, or custom orchestration frameworks. An engineering team might deploy an agent to audit architectural compliance across dozens of design specifications, parse vendor invoices, or generate customer status reports based on spreadsheets scattered across multiple project folders. To perform these tasks, the agent must inspect file hierarchies, retrieve relevant passages, and extract key variables without exceeding token budgets or tripping infrastructure limits.
Microsoft introduced native Agents in OneDrive for Microsoft 365 Copilot users on the web. These built-in assistants allow knowledge workers to ground Copilot in specific folders or document sets directly within the browser. However, these web assistants operate within the closed Microsoft 365 Copilot interface. They cannot serve as open Model Context Protocol (MCP) endpoints for external coding assistants, custom multi-agent frameworks, or local terminal agents.
When developers connect AI agent to OneDrive storage, they typically pursue two architectural paths:
- Local filesystem integration. The agent runs locally on a workstation or virtual machine where the OneDrive desktop sync client is installed. The agent navigates the local OneDrive directory as standard filesystem paths.
- Direct cloud API integration. The agent uses Microsoft Graph REST endpoints to authenticate through Microsoft Entra ID, query folder hierarchies, and download file content into application memory over HTTP.
Both approaches present severe operational bottlenecks when scaled to multi-document workflows, large binary formats, or concurrent multi-agent systems. Dedicated storage for agents solves these bottlenecks by decoupling the physical cloud archive from the real-time retrieval layer.
Related guides
- OneDrive WebDAV: Connecting Legacy Clients, Workarounds, and Modern AlternativesOneDrive WebDAV was a legacy method for mounting OneDrive as a network location using a CID-based WebDAV URL, which...
- How to Mount OneDrive with Rclone: VFS Cache, Throttling, and Agent StorageMounting Microsoft OneDrive through Rclone exposes cloud files as a local filesystem via FUSE, but standard mount...
- How to Mount OneDrive on Windows with Rclone and WinFspRclone mount OneDrive on Windows uses the WinFsp user-mode file system proxy to expose remote Microsoft OneDrive...
- Can ChatGPT Access OneDrive? Workflows, Admin Limits & Fast StorageChatGPT can access OneDrive files through its cloud storage connector, but personal accounts remain unsupported while...
- ChatGPT OneDrive Plugin: Fast File Retrieval Without Graph API DelaysA ChatGPT OneDrive plugin allows OpenAI models to query and summarize Word documents, Excel spreadsheets, and PDFs...
- ChatGPT OneDrive Not Working: How to Fix Connection and Sync FailuresWhen ChatGPT OneDrive integration is not working, connection failures typically stem from expired authentication,...
More on this subject: AI Agents: General Guides (190 guides)
Why AI Agents Fail on OneDrive Files-On-Demand Stubs
Deploying autonomous agents against raw OneDrive storage reveals two recurring failure modes: operating system hydration failures caused by Files-On-Demand stubs, and API throttling triggered by recursive Microsoft Graph calls.
The Local Reparse Point Trap: Zero-Byte Stubs
OneDrive manages local disk capacity through Files-On-Demand. To prevent downloading entire cloud document libraries onto local drives, the operating system creates cloud-only placeholder stubs. On Windows NTFS filesystems, these files are designated with the FILE_ATTRIBUTE_REPARSE_POINT attribute and marked as sparse files. On macOS, the sync engine uses File Provider placeholder items.
These placeholder stubs appear in directory listings with their nominal file sizes and extension names, but their physical on-disk content is zero bytes until the operating system hydrates them by downloading the payload from Microsoft servers.
When a human user double-clicks a document in File Explorer, the operating system triggers a hydration request and displays a progress bar while the file downloads. In contrast, when an autonomous AI agent, a Python script, or a command-line utility executes a standard read operation (such as open(), cat, or Node.js fs.readFile()) inside an automated subshell, the process frequently fails:
- Access Denied and Hydration Timeouts. Non-interactive subshells and automated runtimes often lack the interactive context required to trigger operating system hydration hooks. The read call fails immediately with operating system errors like
PermissionErroror Windows Error 395 (ERROR_CLOUD_FILE_UNSUCCESSFUL), causing the agent to perceive the file as corrupt or missing. - Local Disk Saturation. If an agent attempts to inspect an entire directory by iterating through files or invoking recursive search utilities, it inadvertently triggers the sequential hydration of every document in the folder. A routine audit can suddenly force hundreds of gigabytes of PDFs, spreadsheets, and presentations onto the local drive, filling local disk storage and freezing background operations.
- Context Window Overflows. When an agent succeeds in reading hydrated local files, it typically reads raw binary or plain-text documents directly into its context window. Ingesting raw multi-megabyte files rapidly exhausts token limits, inflating inference costs and displacing earlier reasoning instructions.
Microsoft Graph API Rate Limits and Traversal Overhead
To avoid local filesystem issues, developers often connect agents directly to cloud storage using Microsoft Graph API connectors. While this bypasses local disk stubs, it introduces severe networking and rate-limiting constraints.
Microsoft Graph enforces strict request throttling to preserve service availability across multi-tenant environments. For SharePoint Online and OneDrive operations, Microsoft Graph limits delegated requests to prevent resource monopolization. When an agent exceeds these thresholds, the API rejects subsequent calls with HTTP status code 429 Too Many Requests:
HTTP/1.1 429 Too Many Requests
Retry-After: 30
Content-Type: application/json

{
  "error": {
    "code": "TooManyRequests",
    "message": "Please retry again later."
  }
}
When an autonomous agent must answer a specific business question across a 200-file OneDrive library, direct API access requires recursive directory crawling. The agent must call /v1.0/me/drive/root/children to enumerate root folders, navigate subdirectories through repeated GET requests, inspect metadata, download binary streams, and perform client-side text extraction.
This traversal pattern triggers multiple round-trip API calls before the agent reads a single line of relevant text. Under multi-agent workloads, where several models query the same document library simultaneously, the application rapidly hits per-user throttling thresholds, forcing exponential backoffs that delay execution.
Comparing Multi-Document Audit Performance Across Storage Layers
The operational difference between direct cloud storage traversal and indexed workspace search is measurable rather than rhetorical. Fast.io publishes a head to head benchmark of agent file work that runs one agent through the same multi-document audit over an identical corpus held in Fast.io and in each of the major cloud storage providers, OneDrive included, recording completion time, tool calls, token consumption and cost per task. Fastio completed the audit fastest and at the lowest cost of the storage layers tested.
The mechanism is the one this page has been describing. Instead of making dozens of repetitive API requests to discover files and downloading entire binary blobs into context, an agent connected to an indexed workspace queries pre-processed embeddings and text chunks directly, which sidesteps hydration errors entirely and keeps prompt context small.


Connect AI Agents to Your Enterprise OneDrive Files
Synchronize OneDrive folders into an intelligent workspace, query pre-indexed documents over remote MCP, and eliminate local hydration errors. Monthly plans start with a trial of up to 14 days (credit card required); annual plans have no trial.
The Fast.io Architecture: Cloud Sync, Intelligence Mode, and Metadata Views
The most effective architecture for connecting AI agents to OneDrive separates persistent long-term document storage from the runtime retrieval layer. Rather than replacing existing corporate file repositories, teams maintain OneDrive as their primary document management system while synchronizing target folders into an intelligent workspace.
Fastio Cloud Sync keeps Google Drive, OneDrive, Box, and Dropbox folders synchronized with an intelligent workspace. The synchronization operates one-way or two-way, on a recurring schedule or on demand; never real-time.
By syncing target folders into Fast.io, corporate governance, retention policies, and administrative ownership remain intact inside Microsoft 365, while AI agents interact with an optimized retrieval substrate.
Automatic Processing in Intelligence Mode
Once documents synchronize into a Fast.io workspace, workspace Intelligence processes them automatically. The platform extracts text from PDFs, spreadsheets, Word documents, presentations, and scanned pages, generating a hybrid search index that combines exact full-text keyword matching with semantic vector retrieval.
When an agent needs information to complete a task, it queries the workspace index through remote MCP tools rather than pulling raw files across the network. The workspace returns relevant text passages, document metadata, and citations, eliminating client-side document chunking and vector database management.
Structured Extraction with Metadata Views
Many enterprise agent workflows require structured tabular data rather than unstructured text snippets. For instance, a contract audit agent might need counterparty names, effective dates, renewal terms, and governing law across hundreds of vendor agreements.
Fast.io Metadata Views turn unstructured documents into a live, queryable database. Users describe target fields in plain English, and the system designs a typed schema across seven field types: Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time.
The workspace matches documents, extracts the specified fields without manual OCR rules, and presents the results in a filterable grid. Autonomous agents can query Metadata Views programmatically through MCP tools, retrieving exact structured values without processing raw document pages.
How to Connect Claude and Cursor to OneDrive Storage via MCP
Configuring a high-performance OneDrive MCP agent takes four practical steps:
- Synchronize the target OneDrive folder to a Fast.io workspace using Cloud Sync.
- For headless scripts, create an API key in Fast.io under Settings > Devices & Agents > API Keys (Claude Code and Cursor sign in with OAuth instead).
- Configure your agent runtime with the remote Model Context Protocol endpoint.
- Execute targeted semantic searches and structured metadata queries from your agent tools.
The Fast.io Model Context Protocol server is a remote endpoint hosted over Streamable HTTP at https://mcp.fast.io/mcp/code for coding agents like Claude Code and Cursor, and at https://mcp.fast.io/mcp/tools for general MCP clients. Interactive clients sign in with OAuth in the browser and carry no API key in their configuration. Sign-in shows a Review Permissions screen where you pick Read Only or Read & Write and which organizations and workspaces the connection can reach. Complete integration parameters and tool definitions are available in the Fast.io documentation. It requires no local server installations, runtime daemons, or package dependencies.
Claude Code Configuration
To connect Claude Code to your synchronized OneDrive workspace, update the project's .mcp.json file with the remote Fast.io MCP endpoint, then run /mcp inside Claude Code to sign in:
{
  "mcpServers": {
    "fastio": {
      "type": "http",
      "url": "https://mcp.fast.io/mcp/code"
    }
  }
}
Once loaded, Claude gains access to a consolidated MCP toolset that includes workspace exploration, semantic search, and file retrieval tools.
Cursor IDE Configuration
In Cursor, configure ~/.cursor/mcp.json (or .cursor/mcp.json in a project) with { "mcpServers": { "fastio": { "url": "https://mcp.fast.io/mcp/code" } } }. Sign in to Fastio in the browser when prompted.
Cursor's background agent can now reference your synchronized OneDrive files during code generation and debugging sessions without indexing local zero-byte placeholder stubs.
Custom Multi-Agent Integration in Python
Custom multi-agent frameworks built with LangChain, CrewAI, or AutoGen can connect directly to the remote MCP server using standard protocol libraries like @modelcontextprotocol/sdk or standard HTTP client requests.
The following Python example illustrates how an autonomous agent queries an indexed OneDrive workspace using semantic search:
import os
import requests

FASTIO_API_KEY = os.environ.get("FASTIO_API_KEY")
WORKSPACE_ID = "ws_88f92a10b4c7"
search_query = "vendor indemnity clauses under New York law"

endpoint_url = f"https://api.fast.io/current/workspace/{WORKSPACE_ID}/storage/search/"
request_headers = {
    "Authorization": f"Bearer {FASTIO_API_KEY}",
    "Content-Type": "application/json"
}
query_parameters = {
    "search": search_query,
    "limit": 5
}

response = requests.get(endpoint_url, headers=request_headers, params=query_parameters, timeout=30)
response.raise_for_status()
search_payload = response.json()

for match in search_payload.get("files", {}).values():
    print("File: " + str(match.get("name")) + " (Score: " + str(match.get("relevance_score")) + ")")
    print("Passage: " + str(match.get("content_snippet")))
Because the query runs against the pre-indexed cloud workspace, the agent retrieves relevant snippets and document IDs in a single HTTP round trip, bypassing local disk hydration and Graph API throttling.
Operational Best Practices for Enterprise Multi-Agent Workflows
Deploying autonomous agents against enterprise file storage requires clear operating boundaries to ensure governance, auditability, and collaboration between human operators and artificial agents.
Workspace Isolation and Granular Permissions
Production deployments should never expose an entire company OneDrive account to a single AI agent. Fast.io enforces granular permissions across organizations, workspaces, folders, and individual files.
Teams should map specific OneDrive directories to dedicated, isolated workspaces based on business function. A legal research agent should be restricted to the legal agreements workspace, while a financial analytics agent accesses only billing and invoice folders. Scoping credentials at the workspace boundary prevents unintentional data exposure across agent teams.
Preventing Overwrites with Version History
When multiple autonomous agents operate within the same storage substrate, concurrent modifications risk overwriting critical files. Traditional cloud drives rely on last-write-wins synchronization, which can silently destroy intermediate reasoning outputs or analysis logs.
Fast.io maintains per-file version history on every document in a workspace. When an agent updates a document, adds supplementary notes, or overwrites an existing deliverable, the platform preserves prior revisions. Human team members and other agents can inspect earlier iterations, diff changes, or restore previous versions if an agent produces inaccurate output.
Complete Traceability with Activity Logs
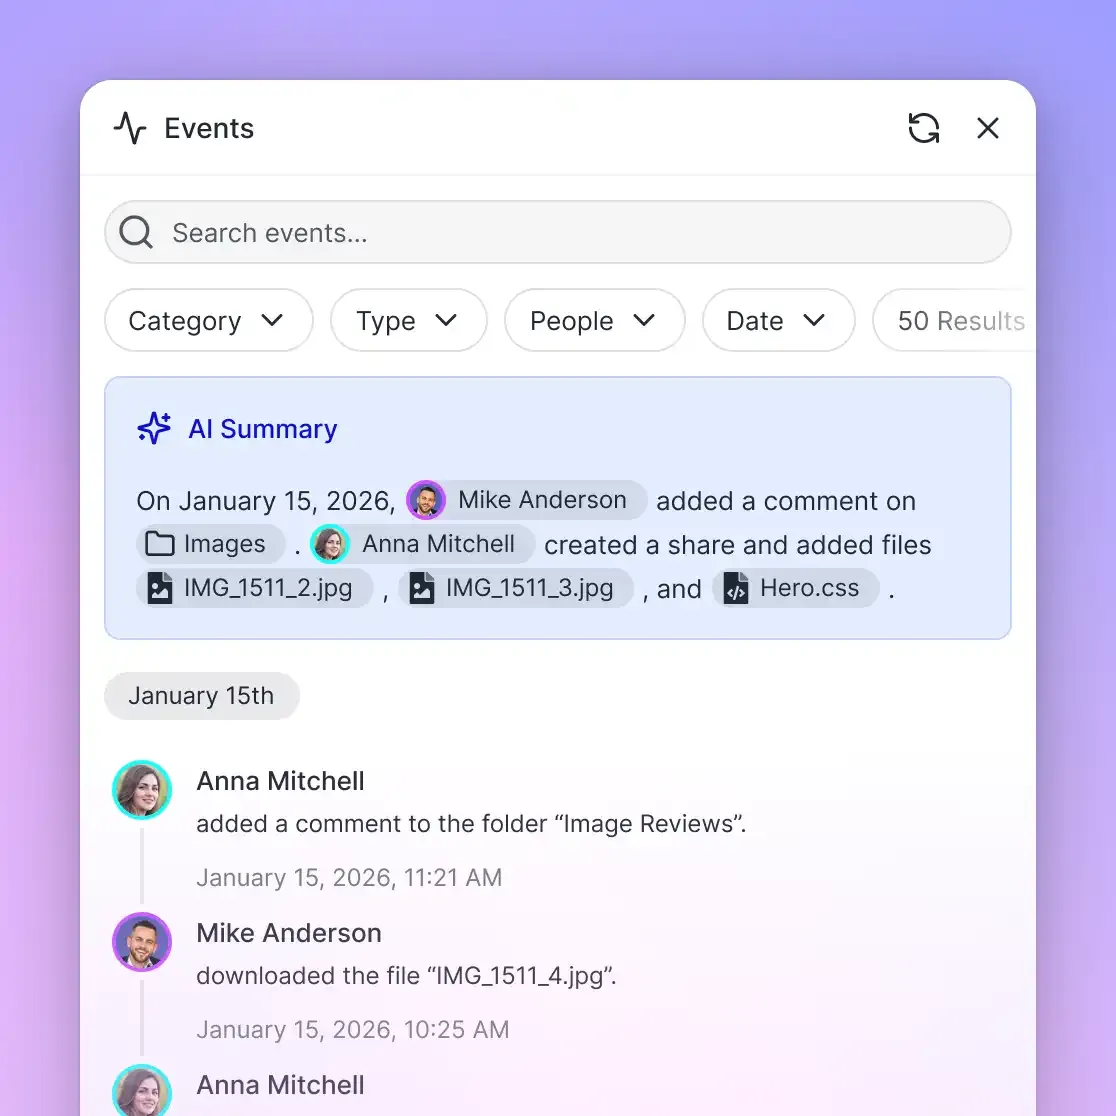
Enterprise compliance requires complete visibility into how automated systems interact with corporate knowledge. Fast.io records workspace operations in a detailed activity log of actions by people and agents, retained according to your plan.
Every file read, search query, metadata extraction, and document modification is logged with timestamps, actor credentials, and file identifiers. IT administrators can inspect exactly which documents an agent accessed during a specific task, providing transparent governance that meets corporate accountability standards.
Human-in-the-Loop Ownership Transfer
AI agents frequently initialize workspaces, aggregate research files, and generate structured deliverables for human colleagues or external clients.
Fast.io supports clean ownership transfer: an autonomous agent can generate a workspace, populate it with synthesized client deliverables, and transfer administrative ownership to a human team member while retaining administrative or read-only access. Reviewing Fast.io pricing shows how teams can start exploring these capabilities with an organization subscription. The human owner assumes billing and security management, while the agent continues performing background queries through scoped credentials.
Sources
References used to verify factual claims in this guide.
-
Microsoft Graph returns HTTP 429 status codes to throttle client applications when request rates exceed service limits.
-
SharePoint Online and OneDrive throttle delegated user requests that exceed 10 requests per second per user.
Frequently Asked Questions
Can AI agents read OneDrive files without downloading them locally?
Yes. By syncing OneDrive folders to an intelligent cloud workspace like Fast.io, AI agents query the pre-indexed workspace via remote Model Context Protocol (MCP) tools. The workspace indexes document text and embeddings on arrival, allowing models like Claude or Cursor to perform semantic search and retrieve specific passages with citations without downloading raw binary files to a local disk.
Why do AI agents fail on OneDrive Files-On-Demand stubs?
OneDrive Files-On-Demand uses operating system reparse points and sparse file placeholders that allocate zero physical bytes on local storage until hydrated. When automated scripts or command-line agents attempt standard read operations without interactive user prompts, the operating system often blocks the read or returns an access error, leaving the agent with an empty file or a failed task.
How do you connect Claude or Cursor to OneDrive via MCP?
You connect Claude or Cursor by synchronizing your target OneDrive folder to a Fast.io workspace and configuring your client's MCP configuration with the remote endpoint at `https://mcp.fast.io/mcp/code` for coding agents like Claude Code and Cursor (or `https://mcp.fast.io/mcp/tools` for Claude desktop and web apps). Interactive clients sign in with OAuth in the browser and carry no API key in their configuration. Setup steps are detailed in the [Fast.io documentation](https://mcp.fast.io/docs). The agent can then use a consolidated MCP toolset to search, inspect, and extract information from your OneDrive files.
What is the difference between Microsoft's built-in Agents in OneDrive and an external OneDrive agent?
Microsoft's native Agents in OneDrive operate strictly inside Microsoft 365 Copilot on the web, requiring Microsoft 365 Copilot licensing and browser-based user interaction. External OneDrive agents run inside developer environments like Cursor, Claude Code, or custom Python orchestration frameworks, connecting through remote MCP to perform programmatic document retrieval and multi-agent coordination.
How do Microsoft Graph API rate limits affect autonomous agents querying OneDrive?
Microsoft Graph limits delegated SharePoint Online and OneDrive search requests to 10 requests per second per user. When an autonomous agent performs recursive directory crawling or parallel file downloads across deep folder trees, it frequently exceeds these thresholds and receives HTTP 429 Too Many Requests responses, stalling multi-agent workflows.
How can an AI agent extract structured data from OneDrive spreadsheets and PDF documents?
Agents can use Fast.io Metadata Views to convert unstructured files into live, queryable databases. Users define fields in plain language, and the system populates typed columns across Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time without manual OCR templates. Agents query these structured records directly over MCP without parsing raw files.
Related Resources

Connect AI Agents to Your Enterprise OneDrive Files
Synchronize OneDrive folders into an intelligent workspace, query pre-indexed documents over remote MCP, and eliminate local hydration errors. Monthly plans start with a trial of up to 14 days (credit card required); annual plans have no trial.