How to Connect Langflow Workflows to Google Drive
Connecting Langflow to Google Drive lets visual AI pipelines query cloud documents dynamically, replacing brittle single-file loaders with an indexed workspace queried via MCP. While direct API connectors trigger directory crawls and rate limits on large folders, importing Google Drive into Fast.io enables hybrid search across hundreds of files in a single tool call.

How Langflow Connects Google Drive Workflows to Enterprise Cloud Repositories
Point-to-point file ingestion in visual AI builders breaks down as soon as project knowledge expands beyond a handful of static documents. When visual language pipelines in Langflow attempt to read directly from unindexed Google Drive directories, execution slows to a crawl. The visual canvas model excels at orchestrating prompt templates, foundation models, and vector stores into interactive graphs, but raw cloud storage was engineered for human folder navigation rather than rapid machine retrieval. Instead of executing a targeted semantic lookup, an agent pointed at raw cloud storage must recursively query folder structures, guess relevance from arbitrary filenames, download entire file payloads across the network, and flood model context windows with unparsed boilerplate.
Langflow has gained widespread adoption among Python developers, enterprise software engineers, and automation teams building agentic applications. Through its modular component graph, teams construct sophisticated pipelines that combine conversational interfaces, multi-agent collaboration loops, and retrieval-augmented generation. Within enterprise environments, Google Drive serves as the central repository for critical institutional knowledge, housing vendor agreements, technical specifications, financial projections, customer interview transcripts, and compliance policies.
Connecting Langflow to Google Drive enables visual AI pipelines to retrieve live folder contents with semantic citations while avoiding Google Drive API rate limiting and token exhaustion. Standard community approaches attempt to bridge this gap by writing custom Python components or employing basic document loaders from LangChain. Developers generate service account credentials in Google Cloud, configure OAuth consent screens, paste folder IDs into component fields, and attempt to embed entire directories into an external vector database.
Once authenticated, standard document loaders pull supported Google Workspace files such as Google Docs, Google Sheets, and Google Slides, as well as Microsoft Office documents and PDF files. The flow splits the extracted text into chunks, computes vector embeddings, and commits those embeddings to a standalone vector store.
This point-to-point ingestion works adequately for small proof-of-concept projects containing five or six static files. A single customer support FAQ or an internal handbook can be ingested once into memory without stressing infrastructure. However, production deployments demand continuous access to dynamic archives distributed across complex folder trees. Attempting to query raw Google Drive folders directly from an autonomous visual flow introduces crippling latency, API throttling, and prohibitive token costs.
Related guides
- How to Connect Google Drive to AnythingLLM for Agentic RAGConnecting Google Drive to AnythingLLM provides local and team LLMs with direct access to cloud documents for grounding...
- How to Connect Microsoft AutoGen Agents to Google DriveAn AutoGen Google Drive connector registers retrieval functions with AutoGen agents so multi-agent group chats can...
- How to Connect Dify AI Agents to Google DriveConnecting Dify to Google Drive allows agentic workflows and LLM apps to query Google Drive files as a persistent...
- How to Connect Flowise AI Agents to Google DriveConnecting Flowise to Google Drive lets low-code AI workflows query cloud documents dynamically, replacing brittle...
- Can ChatGPT Access Google Drive? Permissions, Limits & WorkaroundsChatGPT can access Google Drive files through its native integration, but only by retrieving individual user-selected...
- ChatGPT Google Drive Connector: Native Connected Apps vs. Fast.ioA ChatGPT Google Drive connector links OpenAI models to cloud document repositories, enabling conversational search,...
More on this subject: Agent Integrations and APIs (133 guides)
Why Direct API Traversal Stalls Complex Langflow Agent Pipelines
Autonomous AI agents evaluate storage repositories through programmatic queries rather than visual inspection. While a human analyst navigates folder hierarchies, opens documents in multiple tabs, and scans section headings for key terms, an agent operating on a Langflow canvas relies on discrete tool executions. When an agent queries Google Drive directly, the underlying storage architecture creates severe operational friction.
Non-Hierarchical ID Structure and Compounding Request Latency
Google Drive does not operate as a traditional POSIX filesystem or a cloud bucket with hierarchical prefix keys. Instead, every file and folder exists as an independent entity assigned a unique alphanumeric ID, with folder hierarchies represented through relational parent-child arrays. To locate files located within nested subdirectories, an agent must make repetitive files.list API calls, querying child folder IDs sequentially and parsing metadata arrays.
Every directory hop introduces a full network round trip. In enterprise shared drives where documents are organized across department and project subfolders, an agent may need dozens of sequential API round trips simply to discover candidate documents. For interactive Langflow flows and real-time customer assistants, these multi-second discovery phases degrade responsiveness and cause front-end requests to time out.
Strict Quota Enforcement and Flow Interruption
Google Drive protects its infrastructure by enforcing strict API consumption caps. Under Google Cloud's quota model, projects are governed by limits such as 325,000 quota units per minute per user per project and 1,000,000 quota units per minute per project.
Exceeding these thresholds immediately halts execution. Under Google Cloud's quota model, exceeding project limits triggers a 403 user rate limit error or an HTTP 429 rate limit exceeded response. When multiple agent instances execute parallel lookups or when a batch data ingestion flow attempts to index a large folder, the flow quickly exhausts allowable quota units.
When throttling occurs, the Google Drive API requires applications to implement exponential backoff pauses. In production Langflow deployments, sudden rate-limit delays freeze flow execution, break WebSocket event loops, and exceed downstream API gateway timeouts. Published community guides focus on embedding individual files via standard LangChain Google Drive loaders, failing on nested folder traversal, permission hierarchies, and multi-document queries. As developers broaden folder scopes to capture enterprise archives, API rate limits routinely disrupt agent runs midway through document ingestion.
Prompt Bloat and Context Window Exhaustion
Direct cloud storage loaders are built for bulk file transfer rather than precision semantic retrieval. When a native component retrieves a document, it pulls the complete text body and injects it directly into prompt context.
Dumping whole files into an LLM prompt consumes tens of thousands of tokens on document headers, legal disclosures, formatting markup, and irrelevant sections. Frontier foundation models charge per input token, and model reasoning degrades as prompt windows fill with noise. Expecting an agent to extract a single clause from dozens of unindexed 50-page PDFs leads to inflated inference costs and increases the likelihood of model hallucinations.
The contrast between direct storage polling and workspace-indexed retrieval highlights key operational differences:
Retrieval Precision: Direct loaders download entire file payloads, whereas indexed workspaces return specific paragraph chunks matching the query.
Network Overhead: Recursive directory traversal requires dozens of individual API requests to identify files, while indexed search resolves queries in a single tool call.
Token Economy: Direct ingestion floods prompt context with full file text, whereas indexed retrieval extracts only relevant text passages alongside page-level citations.
Rate Limit Resilience: Frequent folder polling quickly triggers Google Drive API throttling, whereas querying an indexed workspace keeps runtime traffic off third-party storage APIs.
Index Maintenance: Native loaders require full workflow re-runs to re-chunk and re-embed edited files, whereas intelligent workspaces update indexes automatically upon file arrival.
Raw Drive Connectors Against Indexed Agent Workspaces
To eliminate the performance penalties and rate limits of raw API traversal, modern architectures decouple permanent storage from runtime agent retrieval. Instead of migrating enterprise archives away from Google Drive or maintaining an independent vector database cluster, teams retain Google Drive as their authoritative system of record. They connect their Google Drive directories to Fast.io, creating an intelligent workspace that indexes document contents automatically for AI agents.
Fast.io supports one-time cloud import for Google Drive today, with two-way folder sync coming soon; synchronization is never real-time, operating on reliable background schedules. This ensures that organizational permissions, compliance controls, and human workflows remain anchored in Google Drive, while Langflow agents query a dedicated, high-speed retrieval layer.
The difference between raw storage traversal and indexed workspace retrieval has been measured rather than asserted. Fast.io publishes a head to head benchmark of agent file work in which one agent runs the same corporate audit, reading legal agreements, statements of work, invoices and credit memos to build a complete customer profile, over an identical corpus held in Fast.io and in each of the major cloud storage providers, Google Drive included. The run records completion time, tool calls, token consumption and cost per task. Fast.io completed the audit fastest and at the lowest cost of the storage layers tested.
That speed advantage is driven by workspace intelligence. When documents land in a Fast.io workspace, Intelligence Mode indexes their contents using hybrid search. Hybrid search blends full-text keyword matching, semantic vector embeddings, and structured metadata filters. Instead of downloading whole files sequentially to locate terms, Langflow agents query the workspace index through a remote Model Context Protocol (MCP) server. Fast.io returns exact text chunks with page-level citations, allowing the model to answer accurately with lower token overhead and reduced storage query latency.



Connect Google Drive to Langflow with Indexed Workspaces
Import your Google Drive folders into an intelligent workspace, query indexed files through Fast.io MCP, and eliminate API rate limits. Starts with a 14-day free trial.
How to Connect Fast.io MCP to Langflow in Three Steps
Integrating Google Drive content into Langflow pipelines via Fast.io requires three straightforward steps:
- Ingest Google Drive folders into a dedicated Fast.io workspace
- Activate Intelligence Mode and extract structured data using Metadata Views
- Connect the remote Fast.io MCP endpoint to Langflow via the MCP Tools component
1. Ingest Google Drive Folders into a Dedicated Workspace
Start by isolating the project folders in Google Drive that contain relevant reference files. Rather than importing an entire organization drive, organize documents into targeted folders, such as an enterprise customer archive, vendor contracts repository, or technical product documentation directory.
Log into the Fast.io console, navigate to your organization, and create a new workspace. Initiate a cloud import from Google Drive:
Authorize access to your Google account through the secure OAuth authentication dialog.
Select the specific Google Drive folder containing your documents.
Confirm the server-to-server cloud import.
Fast.io executes the import directly across cloud infrastructure, transferring data without consuming local network bandwidth or local machine storage. Existing folder hierarchies, document names, and nested structures are preserved intact. While Fast.io supports one-time cloud import for Google Drive today, two-way folder sync is coming soon on the product roadmap; file updates on Google Drive do not reflect in real time.
2. Activate Intelligence Mode and Configure Metadata Views
Once files arrive in the workspace, confirm that Intelligence Mode is active. Fast.io automatically processes uploaded PDFs, spreadsheets, Word documents, presentations, scanned pages, and text files. Intelligence Mode parses the text, calculates semantic embeddings, and creates a unified keyword index for hybrid search.
When dealing with structured records such as vendor invoices, client agreements, or purchase orders, configure Metadata Views. Metadata Views turn unstructured document repositories into a typed, interactive database. You specify the target fields in plain English, such as supplier name, contract effective date, renewal notice period, or payment total. Fast.io matches the relevant documents and extracts structured values across Text, Integer, Decimal, Boolean, Date & Time, and JSON fields without requiring manual regex scripts or brittle parsing rules. Langflow agents can query these structured columns directly over MCP.
3. Connect Fast.io MCP to Langflow Using the MCP Tools Component
Langflow provides native client support for the Model Context Protocol over streamable HTTP. Fast.io hosts a remote MCP server over Streamable HTTP at https://mcp.fast.io/mcp and https://mcp.fast.io/mcp/key when authenticating via an API key header, alongside a legacy SSE transport at https://mcp.fast.io/sse. You can review the architecture on the storage for agents page.
To connect the Fast.io MCP server to your Langflow flow:
In Langflow, open Settings, select MCP Servers, and click Add MCP Server (or open the MCP sidebar in the flow canvas and click Add MCP Server).
Select the streamable HTTP transport type, name the server (for example,
fastio-storage), and enter the server endpoint configuration:
{
  "mcpServers": {
    "fastio-storage": {
      "url": "https://mcp.fast.io/mcp/key",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Open your Langflow canvas and locate the MCP Tools component in the MCP category sidebar.
Drag the MCP Tools component onto the canvas and select your registered
fastio-storageserver in the component configuration.Connect the output port of the MCP Tools component to the
toolsinput of your Agent component (such as an Agent, Tool Calling Agent, or Custom Agent).
Generate your API key in the Fast.io web console under Developer Settings. Keys inherit granular workspace permissions, ensuring that Langflow agents access only authorized workspaces.
When the flow runs, Langflow connects to Fast.io and registers its consolidated MCP toolset. The agent receives actions to search the workspace index, retrieve page-level citations, inspect folder trees, and extract specific document passages. Instead of downloading whole files or requesting raw Google Drive file IDs, the Langflow agent calls Fast.io search actions dynamically during conversation execution.
Developers building automation workflows using command-line tools can use the official package @vividengine/fastio-cli. If your system integrates directly with REST endpoints, the base path is https://api.fast.io/current/. To track newly imported files and team modifications, agents can poll the realtime activity feed via GET /current/activity/poll/{entity_id} or connect to the WebSocket events stream, enabling responsive coordination without repetitive storage polling.
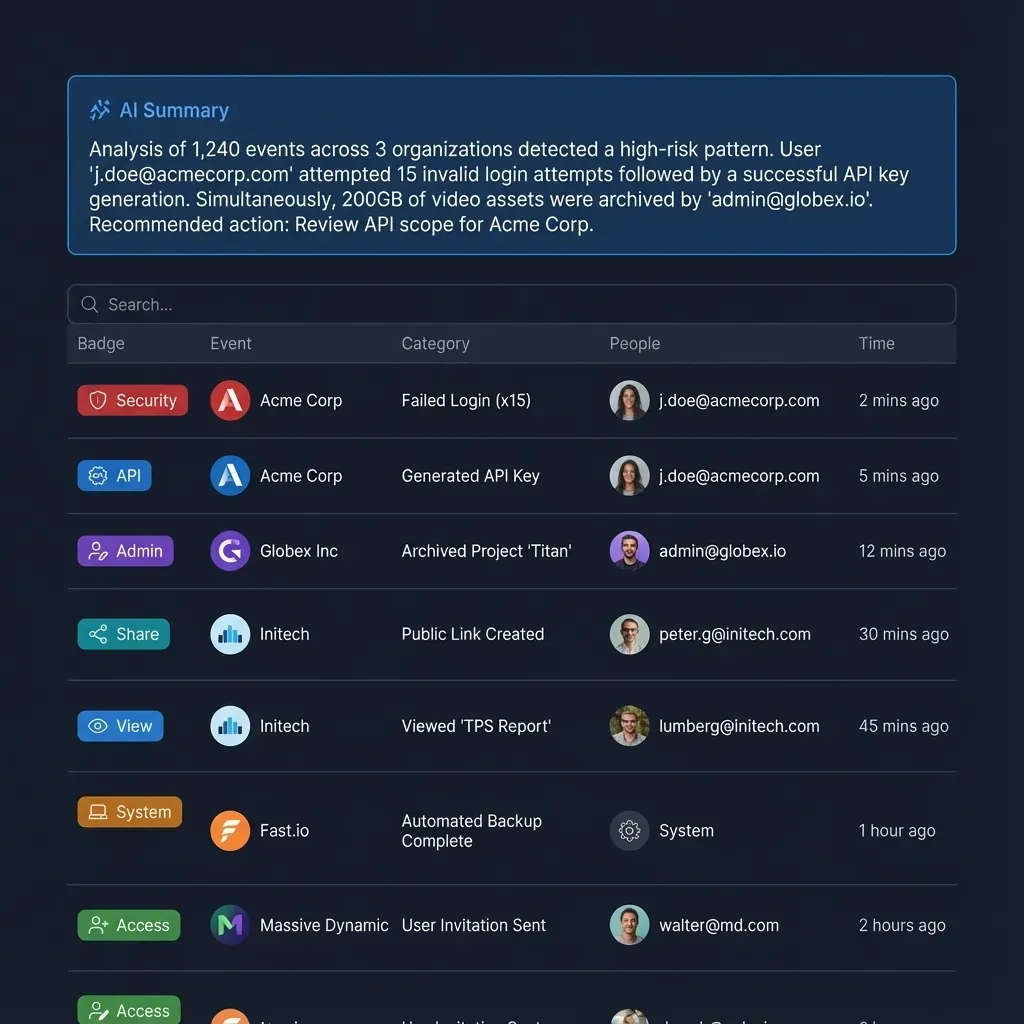
Operational Governance, Role Isolation, and Human Oversight
Operating autonomous Langflow pipelines against enterprise file repositories requires strict oversight, deterministic permissions, and complete visibility into model behavior. When visual agents interact with company archives, organizations must ensure models cannot access unauthorized HR files, cite obsolete agreement versions, or corrupt shared deliverables. Fast.io wraps imported Google Drive data in an enterprise governance layer tailored for human-agent workflows.
Append-Only Activity Logs for Tool Invocations
Every search query, document retrieval, and metadata lookup executed by a Langflow agent is permanently captured in an append-only audit log. Each event records the model credential, requested resource, operation type, and millisecond-accurate timestamp. Security teams and engineering leaders can trace precisely which prompts referenced sensitive client records or examine how an agent arrived at a specific factual citation during automated review workflows.
Hierarchical Access Scoping Across Teams and Agents
Fast.io applies granular permission controls at the organization, workspace, folder, and individual file tier. Developers can provision an API credential for a Langflow flow that restricts its scope strictly to read-only access within a single imported directory, such as /procurement/active-rfps. This architectural boundary ensures an autonomous agent cannot roam into restricted corporate shares or expose confidential records across organizational boundaries.
Per-File Versioning and Co-Editing Workspaces
When automated agents and human colleagues interact with identical files, uncoordinated edits create the risk of data loss. Fast.io maintains comprehensive, per-file version history across all stored documents. If an agent outputs an erroneous summary or updates a working draft incorrectly, team members can inspect previous iterations and restore verified revisions instantly. Collaborative Notes offer a shared canvas where agents and human specialists can draft, annotate, and refine project documentation concurrently with full attribution.
Handoff Workflows and Administrative Ownership Transfer
Fast.io enables direct ownership transfer from autonomous agents to human stakeholders. A Langflow agent can programmatically initialize an organization, configure workspaces, import Google Drive document hierarchies, and generate schema-driven Metadata Views. Once the workspace structure is established, the agent generates a claim link to transfer organizational ownership to a human administrator. The human sponsor assumes billing and governance oversight, while the agent retains the necessary API credentials to perform ongoing semantic search and structured data extraction.
Predictable Plan Tiers and Workspace Onboarding
Adopting Fast.io is simple for development teams. Creating an account is free; doing real work requires an organization on a paid subscription. Plans are structured into clear tiers: Starter at $9.99/mo, Business at $49.99/mo, and Enterprise at $199.99/mo. Every organization starts with a 14-day free trial, which requires a credit card.
Team seats and storage allocations are bundled directly into each subscription, alongside a monthly credit allowance that meters AI operations. Learn more about agentic storage patterns on the storage for agents page and examine plan details on the pricing page. By pairing Google Drive storage with Fast.io's intelligent workspace layer, teams provide their Langflow agents with rapid, accurate, and fully governed access to enterprise documents.
Sources
References used to verify factual claims in this guide.
-
Exceeding Google Drive API usage quotas results in a 403 user rate limit error or an HTTP 429 rate limit exceeded response.
-
Langflow connects to external Model Context Protocol servers using the MCP Tools component to expose remote server functions to agents.
Frequently Asked Questions
How do I connect Langflow to Google Drive?
You can connect Langflow to Google Drive either through custom Python components using Google Cloud OAuth2 credentials or by connecting an indexed Fast.io workspace via the MCP Tools component. Direct scripts download files into Langflow for local chunking and vector storage, which works for small static collections. For production agents querying larger archives, importing Google Drive folders into Fast.io and querying them through the remote MCP server provides faster hybrid search without hitting Google API quotas.
Can Langflow search files in Google Drive?
Langflow can search files in Google Drive once documents are processed through an ingestion loader, split into text chunks, and embedded into a vector store. However, native loaders perform static ingestion and cannot dynamically query Google Drive in real time without directory crawling. Connecting Langflow agents to Fast.io via MCP enables real-time hybrid search (combining exact keyword matching and semantic retrieval) directly across indexed Google Drive files with source citations in a single tool call.
How do I set up an MCP connector for Google Drive in Langflow?
To set up an MCP connector for Google Drive in Langflow, import your Google Drive folder into a Fast.io workspace. Next, open Langflow Settings, select MCP Servers, and add a remote streamable HTTP server pointing to `https://mcp.fast.io/mcp/key` with your Fast.io API key in the Authorization Bearer header. Finally, drag the MCP Tools component onto your canvas, select the Fast.io server, and connect it to your Agent component's tools input.
How do I avoid Google Drive API rate limits in Langflow?
You avoid Google Drive API rate limits in Langflow by decoupling file storage from runtime agent queries. Direct API traversal triggers HTTP 403 or 429 errors when agents frequently inspect folders or batch-load files. By importing Google Drive folders into Fast.io once, documents are indexed on arrival. Langflow agents then query the Fast.io MCP server over Streamable HTTP, keeping query traffic off Google Drive APIs and eliminating rate-limit throttling during agent runs.
What file formats can Langflow query through an imported Fast.io workspace?
Fast.io supports Google Docs, Google Sheets, Google Slides, Microsoft Word, Excel, PowerPoint, PDF files, plain text documents, scanned pages, handwritten notes, and images. Fast.io automatically extracts content and structured data through Intelligence Mode and Metadata Views without requiring separate parsing scripts or third-party OCR tools.
Can Fast.io sync Google Drive folders automatically or is it import only today?
Fast.io supports server-to-server cloud import for Google Drive today, copying folder hierarchies and file contents directly into an intelligent workspace without using local bandwidth. Two-way folder synchronization for Google Drive is coming soon on the product roadmap; synchronization operates on background schedules and is never real-time.
Related Resources

Connect Google Drive to Langflow with Indexed Workspaces
Import your Google Drive folders into an intelligent workspace, query indexed files through Fast.io MCP, and eliminate API rate limits. Starts with a 14-day free trial.