Why Claude Google Drive Is Slow and How to Fix It
Teams querying cloud folders frequently find Claude Google Drive connectors slow due to recursive directory crawling and dynamic document exports during prompt execution. While standard advice recommends reconnecting accounts, resolving persistent latency requires decoupling cloud storage from conversational retrieval. Fast.io synchronizes Google Drive folders into an intelligent workspace, allowing Claude to execute fast hybrid searches over remote MCP without pulling entire files.

Why Claude Google Drive Runs Slowly During Document Retrieval
Connecting an AI agent directly to a personal or enterprise cloud drive turns prompt evaluation into an unpredictable sequence of network round trips. When Claude queries a native Google Drive connector, the assistant does not possess an internal, pre-computed map of your workspace files. Instead, the model acts as an ad-hoc web crawler, issuing serial HTTP requests across the Google Drive API to inspect folder hierarchies, parse file trees, and download complete document payloads before writing an initial response.
Claude Google Drive queries run slowly when the connector attempts to transfer complete document bodies over the Google Drive API rather than querying pre-indexed document chunks.
When an operator asks a question touching multiple files, five compounding factors degrade performance:
- Unindexed Directory Traversal: Google Drive exposes a hierarchical graph of folders rather than a search-optimized vector index. The connector queries parent directories and subfolders in linear succession over the network.
- Dynamic Workspace Document Export Delays: Native cloud assets like Google Docs, Google Sheets, and Google Slides do not exist as static byte streams on Google's file systems. The Drive backend must convert them on the fly into text or PDF formats before transmission.
- Monolithic Payload Transmission: Rather than pulling specific clauses or rows, the connector transmits complete document files over the internet into prompt memory.
- Google Drive API Quota Throttling: Rapid bursts of folder listing and export calls consume project quota units, causing the Drive API to return rate limit errors that stall execution.
- Context Window Saturation: Stuffing raw document text into Claude's prompt context inflates token processing durations and delays time-to-first-token output.
To resolve this bottleneck, teams must modernize their retrieval architecture:
- Synchronize Google Drive folders into a dedicated workspace using scheduled background transfers.
- Enable automated workspace intelligence to index documents into a hybrid search catalog combining full-text keywords, semantic embeddings, and metadata attributes.
- Point Claude to the indexed workspace through a remote Model Context Protocol endpoint, querying targeted document chunks instead of pulling whole folders over the Google Drive API.
Competitors suggest clearing browser cookies or reconnecting Google OAuth without addressing the architectural bottleneck of full-file context loading. While refreshing an expired authorization token solves broken credential handshakes, it does nothing for operational latency. The slowdown stems from synchronous file transfers over remote REST endpoints during active prompt generation. In Claude Cowork sessions, this delay frequently breaches client tool execution limits, terminating the task with an unhandled timeout error.
Related guides
- How to Connect Devin AI to Google DriveConnecting Devin AI to Google Drive allows the autonomous engineer to parse and edit your organization's documentation...
- How to Connect Claude Code to Google DriveConnecting Claude Code to Google Drive links Anthropic's command-line coding agent to Google Workspace documents,...
- Why Claude Dropbox Is Slow: Causes and Architecture FixesWhen querying cloud folders, teams often find Claude Dropbox slow due to unindexed directory scans and full-file...
- Why Claude OneDrive Is Slow and How to Accelerate ItWhen accessing Microsoft 365 files, teams often find Claude OneDrive slow due to sequential Microsoft Graph directory...
- Claude Code Google Drive MCP: Connecting Terminal Agents to DriveClaude Code Google Drive MCP connects Anthropic's command-line agent to Google Drive files through the Model Context...
- How to Connect Claude to Google Drive: A Complete GuideGetting your Google Drive files into Claude's context is more annoying than it should be. This guide covers the main...
More on this subject: Claude and Claude Code (289 guides)
How Google Drive API Architecture Causes Latency Cascades in Claude Cowork
Diagnosing connector latency requires tracing what happens across network boundaries when an operator submits a prompt in Claude Cowork or Claude Desktop. The model cannot read files from disk directly; it must rely on tool definitions that call Google Drive REST endpoints on your behalf.
The Directory Enumeration Bottleneck
When an agent searches for information within a designated project space, it begins by querying folder metadata via the files.list endpoint in the Google Drive API v3. In Google Drive, items do not have conventional UNIX paths; files reference their parent container identifiers using a query string such as 'root' in parents and trashed = false.
In team settings, business documents reside within nested organizational hierarchies, such as departmental records, quarterly budgets, or signed vendor agreements. Because Claude cannot determine ahead of time which nested directory stores the needed text, it must inspect the root, parse child folder IDs, and issue secondary files.list calls for every subordinate directory.
When a directory contains dozens or hundreds of files, the Google Drive API paginates results according to the pageSize setting. The connector must evaluate the nextPageToken property and issue repeated requests to fetch the complete directory manifest. Each API exchange incurs HTTPS establishment, TLS handshakes, payload decryption, and JSON deserialization overhead. In a repository with three or four folder tiers, Claude can burn 20 to 45 seconds assembling file names before inspecting a single sentence.
Dynamic Workspace Document Export Delays
Once candidate files are discovered, the connector must retrieve readable text. For standard binary files like PDFs or plain text uploads, the connector calls files.get with the query parameter alt=media.
For native Google Workspace documents, such as Google Docs (application/vnd.google-apps.document), Google Sheets (application/vnd.google-apps.spreadsheet), and Google Slides (application/vnd.google-apps.presentation), the storage architecture introduces another layer of latency. Google Drive does not store static files for these formats. The connector must invoke the files.export endpoint, passing a target export MIME type such as text/plain, text/csv, or application/pdf.
Google's servers must convert the document format dynamically before returning the byte stream. For a 50-page technical manual or a multi-tab financial spreadsheet, server-side document rendering adds several seconds per file. If Claude identifies five candidate documents to resolve a prompt, export conversions alone introduce compounding network wait times.
API Quotas, HTTP 403 Errors, and Client Timeouts
High-frequency API interactions trigger platform defenses. Google Drive monitors request frequency and enforces rate limits measured in quota units per minute per project and per user per project to protect service stability.
When Claude Cowork executes rapid bursts of directory listings and file downloads, the transaction volume can exceed permitted request thresholds. When quotas are exceeded, the API returns an error response. As documented in the Google Drive API specifications, "If you exceed a quota, you'll receive a 403: User rate limit exceeded HTTP status code response. Additional rate limit checks on the Drive backend might also generate a 429: Rate limit exceeded response."
Google guidelines dictate that client applications must back off using exponential retries with randomized jitter. While background ETL pipelines can pause execution for 30 or 60 seconds, an interactive session in Claude Cowork cannot tolerate long pauses. If the connector exceeds the client interface's tool execution threshold, Claude aborts the tool call, displaying a connection failure or empty retrieval error.
Decoupling Google Drive Storage from Conversational Retrieval
Solving connector latency does not require abandoning Google Drive or migrating your team to unfamiliar collaboration software. Google Drive remains a capable platform for human authoring, real-time document drafting, and internal file sharing. The solution is an architectural separation: retain Google Drive as your team's authoring system of record, while introducing an intelligent workspace layer that handles indexing and semantic retrieval for AI agents.
Fast.io implements this decoupled architecture through Cloud Sync. Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. Scheduled non-real-time Cloud Sync offloads API load from active agent sessions. Because synchronization executes as an asynchronous cloud task, background transfers never compete with conversational queries for Google Drive API quota. Fast.io synchronizes files in scheduled batches or on demand and is never continuous, live, or real-time.
Pre-Computed Indexing with Intelligence Mode
As soon as Google Drive assets synchronize into a Fast.io workspace, Intelligence Mode processes the files in the background. The platform extracts text structures, identifies tabular data, and constructs a pre-computed hybrid search index across three distinct retrieval methods:
- Lexical Keyword Search: Locates exact code snippets, SKU identifiers, personnel names, and precise contract terms.
- Semantic Vector Embeddings: Resolves natural language concepts and conceptual inquiries, even when user prompts do not match the exact wording of the original document.
- Metadata Attribute Filtering: Narrows searches by file type, modification dates, custom properties, and workspace tags.
Because indexing occurs before an agent conversation begins, Claude never wastes prompt cycles traversing folders or executing text extraction.
Single-Call Retrieval over Streamable HTTP
Rather than communicating directly with Google Drive REST endpoints, Claude connects to the Fast.io Model Context Protocol server over Streamable HTTP at https://mcp.fast.io/mcp/tools. Streamable HTTP communicates across standard HTTPS ports, bypassing the configuration headaches of local process managers or socket bridges.
When Claude needs information from your Google Drive files, the agent issues a single call to the consolidated storage tool with action: "search". Fast.io searches the pre-indexed chunks and returns relevant passages, structured tables, and verifiable source citations in a single response payload.
In benchmark testing published at Fast.io Benchmarks, Fastio was measured the fastest and the lowest cost of the providers tested. The evaluation measured native cloud storage connectors in Claude Cowork across multi-document retrieval tasks against identical document collections. Accuracy across tested providers showed parity.
Speed up Claude Google Drive search with pre-indexed workspaces
Connect Google Drive folders to Fast.io Cloud Sync, search indexed files over remote MCP, and eliminate recursive API timeouts. Monthly plans start with a 14-day free trial, which requires a credit card.
Connecting Claude to Pre-Indexed Google Drive Files via Fast.io MCP
Configuring Fast.io to serve indexed Google Drive content to Claude takes only a few minutes. This workflow preserves your team's existing Google Drive folder structure while eliminating retrieval latency.
Step 1: Select Target Google Drive Folders
Identify the Google Drive directories that house reference documentation, customer specifications, research archives, or standard operating procedures. Grouping files into dedicated directories, such as /Shared Drives/Engineering/Specifications or /Company/Handbooks, simplifies workspace boundary management.
Step 2: Establish Fast.io Cloud Sync
In Fast.io, create an organization workspace and configure synchronization:
- Open workspace settings, select Cloud Sync, and choose Google Drive.
- Authenticate through the Google OAuth prompt to grant access to the chosen directories.
- Designate the specific folder mapped in Step 1.
- Select your synchronization mode: pick one-way sync for a read-only search corpus, or two-way sync if you want Claude to write finished summaries or generated reports back to Google Drive.
- Configure your sync frequency to update on a defined schedule or refresh on demand. Fast.io syncs in scheduled batches and is never continuous, live, or real-time.
Step 3: Verify Workspace Indexing
Once files copy into the workspace, confirm that Intelligence Mode has processed your documents. Fast.io automatically indexes Word files, Google Docs exports, PDF documents, presentations, and spreadsheets. You can test search precision directly in the Fast.io web console by submitting a sample inquiry and confirming that relevant passages and source links appear immediately.
Step 4: Configure the Claude Connector
Link Claude to your Fast.io workspace using the native connector interface:
Claude (web, desktop, mobile): open Customize, then Connectors; add a custom connector and paste https://mcp.fast.io/mcp/tools; select Connect and sign in to Fastio in the window that opens; in a chat, turn Fastio on from the + menu under Connectors.
During the browser authentication handshake, Fast.io presents a Review Permissions screen. Specify whether Claude receives Read Only or Read & Write permissions, and choose which organization workspaces the connector can reach.
Step 5: Execute High-Speed Searches in Claude Cowork
With the connector configured, open Claude Cowork or Claude Desktop and enter a prompt:
Search the engineering workspace for our 2026 data pipeline architecture specifications.
Summarize the failover mechanisms and cite the exact source documents.
Claude dispatches a single call to the storage tool with action: "search". The Fast.io workspace evaluates the query against pre-computed indices and delivers targeted text segments into prompt context, completing the request in seconds without traversing directory trees or triggering Drive API quotas.
Structured Extraction, Access Controls, and Multi-Agent Workspaces
Deploying Fast.io alongside Google Drive provides capabilities designed specifically for autonomous agents and cross-functional teams. Beyond eliminating query latency, workspaces introduce structured document extraction, team governance, and multi-agent coordination.
Structured Data Extraction with Metadata Views
Business operations often require structured database records rather than narrative summaries. Fast.io offers Metadata Views to convert unstructured files into relational databases.
Users describe the fields they need in plain English, such as agreement renewal dates, customer names, billing amounts, or project milestones. Fast.io builds a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time formats. Without manual OCR setup or rigid templates, the system extracts requested attributes from PDFs, images, spreadsheets, and presentations into a structured grid.
Agents interact with Metadata Views over the remote MCP connection. Claude can query specific columns to filter agreements expiring in thirty days or aggregate expenses across quarterly sheets without scanning full document bodies.
Multi-Agent Coordination and Governance
When autonomous agents share workspaces with colleagues, uncoordinated writes can cause document collisions. Fast.io provides coordination primitives built for multi-agent workflows:
- Role-Based Access Controls: Permissions are configured per organization, workspace, and share through member roles. Every workspace member accesses workspace contents according to their assigned role, preventing accidental access leakage.
- Per-File Version History: Every document modification creates a distinct version in file history. Teams can inspect earlier iterations and restore previous files if an agent produces unintended changes.
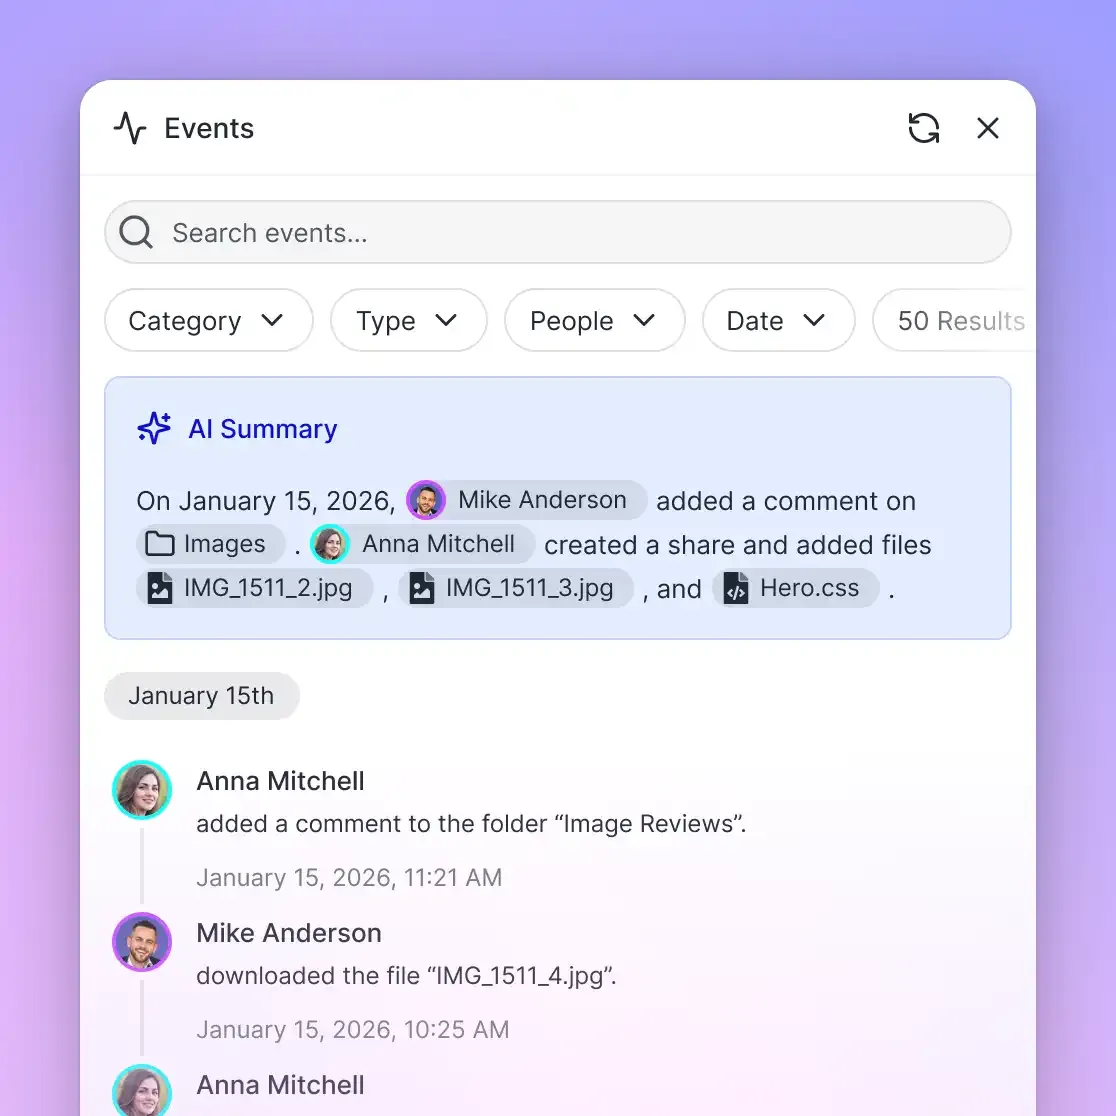
- Detailed Activity Log: Fast.io records a detailed activity log of all organizational changes, tracking file uploads, edits, moves, deletions, and permission adjustments. The log captures modifications from people and AI agents alike, providing operational accountability.
- Advisory File Leases: Agents can coordinate concurrent edits using advisory file locks. An agent acquires a lock using
action: "lock-acquire"on thestorage_managetool, checks lock status withaction: "lock-status"on thestoragetool, and releases the lock withaction: "lock-release"onstorage_manage. Leases expire unless heartbeated by the holder. Concurrent writes land safely, and version history preserves each version. - Collaborative Notes: Team members and AI agents can maintain Notes beside project files. Notes support version-checked saves rather than real-time co-editing, allowing human operators and automated agents to record research findings and handoff instructions in shared workspace context.
Plan Options and Organization Setup
Every Fast.io organization runs on a paid subscription. Monthly plans start with a 14-day free trial, which requires a credit card. Teams choose from three subscription tiers:
Organizations can add extra member seats on Enterprise plans ($1 a month each, up to 200). Credit overage is $10 per 100,000 credits. Credits meter artificial intelligence operations only. Additional storage beyond the plan is $0.015 per GB a month and extra bandwidth is $0.04 per GB.
Sources
References used to verify factual claims in this guide.
-
If you exceed a quota, you'll receive a 403: User rate limit exceeded HTTP status code response. Additional rate limit checks on the Drive backend might also generate a 429: Rate limit exceeded response.
Frequently Asked Questions
Why is Claude taking so long to read my Google Drive files?
Claude takes so long to read Google Drive files because the native connector treats cloud storage as an unindexed file system. When you ask a question, Claude must issue sequential API calls to inspect folder hierarchies, list directories, and download complete files into prompt memory before generating an answer. Each API round trip introduces network transfer delays and token processing overhead.
How do I make Claude search Google Drive faster?
To make Claude search Google Drive faster, decouple file storage from real-time agent retrieval. Instead of letting Claude crawl remote Google Drive APIs during an active prompt, use Fast.io Cloud Sync to replicate target folders into an organization workspace. Fast.io pre-indexes the files with Intelligence Mode, allowing Claude to retrieve targeted passages in a single MCP tool call without triggering client timeout limits.
Does Claude pull entire files from Google Drive?
Yes. When using the native Google Drive connector, Claude downloads complete document payloads over the Google Drive API into its prompt context. Because raw cloud storage lacks pre-computed chunking and vector indices, Claude must ingest entire files to search for specific answers.
How do I fix Claude Google Drive timeout errors?
To fix Claude Google Drive timeouts, replace live API folder traversals with pre-indexed workspace search. Replicating files into a Fast.io workspace enables single-call semantic queries over remote MCP, preventing recursive directory scanning and API rate limits from exceeding client timeout thresholds.
Does disconnecting and reconnecting Google Drive fix connector latency?
Disconnecting and reconnecting Google Drive only resolves expired OAuth token handshakes. It does not fix persistent search latency or timeout errors. Latency is caused by recursive directory crawling and full-file downloads over the Google Drive API during inference, which requires an indexed retrieval architecture to resolve.
Can Claude save generated files back to Google Drive through Fast.io?
Yes. When Fast.io Cloud Sync is configured for two-way synchronization, files created or edited by Claude in the Fast.io workspace synchronize back to the connected Google Drive folder on your scheduled sync cadence. Fast.io maintains per-file version history so you can review changes.
Does Fast.io Cloud Sync require running a local desktop application?
No. Fast.io Cloud Sync runs entirely in cloud infrastructure through server-to-server OAuth connections. You do not need to install desktop sync daemons, configure local folder watchers, or keep your computer awake for files to synchronize and index.
Related Resources
Speed up Claude Google Drive search with pre-indexed workspaces
Connect Google Drive folders to Fast.io Cloud Sync, search indexed files over remote MCP, and eliminate recursive API timeouts. Monthly plans start with a 14-day free trial, which requires a credit card.