Claude Code Token Limit: Output Caps, Compaction, and Workspace Architecture
The Claude Code token limit defines the boundaries on input context, per-turn output generation, and rolling session usage during CLI workflows. Although models like Claude 3.7 Sonnet support a 200,000-token context window and 64,000 thinking output tokens, repetitive tool outputs rapidly consume capacity. Effective engineers combine auto-compaction, selective file targeting, and external workspace retrieval to maintain coding velocity.

What Limits Apply to Claude Code Sessions?
In Anthropic's documented architecture for Claude Code, terminal coding sessions do not operate under a single monolithic token ceiling. Instead, developers encounter three distinct constraints: an input context window of 200,000 tokens, a per-turn output generation cap of up to 64,000 tokens in thinking mode, and rolling session usage limits that reset on 5-hour and weekly intervals. Understanding the interaction between these three tiers prevents truncated code, failed bash executions, and surprise mid-day lockouts.
The Claude Code token limit refers to the constraints on input prompt tokens, maximum output tokens per turn, and sliding context compaction thresholds enforced during Claude Code CLI sessions.
In general Claude usage, Anthropic's documentation on file uploads documents that a single chat accepts up to 20 files at up to 500MB each, while a project accepts files up to 30MB each with no fixed file-count cap, provided the total content fits within Claude's context window. Claude Code applies an identical principle in the terminal environment: there is no arbitrary limit on how many files exist in your local git repository, but every file read by the agent enters active context and draws down the session's token capacity.
The first dimension is the model input context window. Claude 3.7 Sonnet, Claude 3.5 Sonnet, and Claude Opus operate on a standard 200,000-token context window. This 200,000-token space serves as the total working memory for the session. It must accommodate the system prompt, environment details, project instructions from CLAUDE.md, all tool definitions, previous turn history, files read from disk, bash execution output, and the model's response. Select enterprise plan configurations offer expanded 500,000 or 1,000,000 token windows on specialized model variants, but the default CLI experience anchors to 200,000 tokens.
The second dimension is the output token cap. For standard response completions without extended thinking, Claude models enforce an output ceiling of 8,192 tokens per turn. When working with Claude 3.7 Sonnet in extended thinking mode, the model reaches a generation ceiling of 64,000 output tokens per turn. Crucially, thinking tokens count directly as output tokens for both billing calculations and per-turn generation ceilings. If an architectural plan requires 40,000 tokens of internal reasoning, only 24,000 tokens remain for visible code generation within that 64,000-token turn.
The third dimension is the account-level usage window. How developers authenticate their CLI session determines how consumption is governed:
- Claude Pro: Provides baseline access subject to a rolling 5-hour session quota and a separate weekly limit. Usage is shared across claude.ai, Claude Desktop, and Claude Code.
- Claude Max tiers: Deliver expanded session capacity within each 5-hour window, backed by higher weekly allowances.
- Team and Enterprise seats: Organizations draw from pooled seat allowances. Enterprise administrators can configure spend caps and enable usage credits for overage.
- Claude Console API and Cloud Providers: Developers using an API key through Anthropic Console, Amazon Bedrock, Google Cloud Vertex AI, or Microsoft Foundry pay per token without artificial session pauses. Spend is tracked with the
/costcommand and capped using the--max-budget-usdCLI flag.
The table below compares limits across Claude Code deployment tiers:
Context Windows Versus Output Generation Ceilings
A frequent mistake among engineers is conflating the 200,000-token context window with Claude Code's output capacity. A model with 200,000 tokens of context cannot output 200,000 tokens of source code in one pass. The context window governs what the model can read, while the 8,192-token standard cap or 64,000-token thinking ceiling governs what it can write.
When an agent attempts to rewrite a large legacy codebase in a single prompt, it frequently hits the output ceiling mid-generation. The API returns a stop reason of max_tokens, leaving partial files, broken syntax, and unclosed functions on disk. Managing this boundary requires structuring work into modular increments, asking Claude Code to plan changes across individual files rather than requesting full-repository rewrites in one command.
Related guides
- Claude Context Limit: Token Windows, Memory Saturation, and Workspace SearchClaude context limit is the 200,000-token operational boundary that caps the cumulative volume of conversation history,...
- Claude CSV File Limit: Token Caps, File Limits, and Data WorkaroundsThe Claude CSV file limit allows uploads up to 30MB in Projects or 500MB in individual chats, but tabular datasets are...
- Claude Prompt Limit: Maximum Input Length, Character Caps, and WorkaroundsClaude prompt limits define the volume of text and context a model processes in a single turn. Anthropic bounds...
- Managing Claude Code Daily Limits: Spend Caps, Quotas, and Unattended WorkflowsAutonomous coding agents can rapidly exhaust token quotas and project context when executing unbounded multi-turn loops...
- Claude Code Message Limit: Quotas, Compaction, and Large-Context WorkaroundsClaude Code message limits define the maximum prompt token size and message frequency allowed in a CLI session before...
- Claude Code Session Limit Reached: Causes, Compaction, and WorkaroundsClaude Code session limits occur when cumulative terminal output, command history, and file reads saturate the agent...
More on this subject: Claude and Claude Code (278 guides)
Why Interactive Coding Loops Consume Tokens Rapidly
The reason developers burn through token limits by mid-afternoon lies in the mechanics of the agentic terminal loop. When interacting with a simple web chat, each question can be answered in isolation. In Claude Code, however, every interaction forms part of a continuous state machine.
Each turn sent to the Claude API packages three distinct components:
- Conversation history: Every prior user prompt, assistant response, thinking block, and tool invocation recorded in the session.
- Project context: The contents of
CLAUDE.md, directory listings, and the full text of every file read into context during the task. - The current prompt: The latest instruction or tool result.
Consider a typical debugging workflow. A developer asks Claude Code to resolve an edge case in an API handler. Claude Code lists the project structure, reads four related TypeScript files totaling 1,200 lines, runs a test suite that outputs 800 lines of console logs, inspects a package configuration, and proposes a fix. At this stage, the session context has grown to 45,000 tokens. When the developer types a simple two-word response like "run tests", Claude Code does not send two words to the API. It sends all 45,000 tokens of accumulated history alongside the two words.
Enterprise Claude Code deployments reflect this cumulative consumption pattern. According to the official Claude Code cost documentation, across enterprise deployments, the average cost is around $13 per developer per active day and $150-250 per developer per month, with costs remaining below $30 per active day for 90% of users.
Prompt caching mitigates part of the financial impact. The Anthropic API automatically caches static prefixes, such as system instructions and immutable blocks of conversation history. When a prompt cache hits, input tokens are billed at a discounted cache-read rate. However, caching does not expand the physical 200,000-token context window. A 160,000-token history still consumes most of the model's memory space, leaving little room for reasoning and new file reads.
Cache invalidation occurs frequently during active development. Editing a file, changing environment variables, modifying tool definitions, or pausing work longer than the cache time-to-live forces a full cache rebuild. On pay-as-you-go API keys, the cache time-to-live is five minutes by default. A developer who steps away for coffee returns to a session that must reload and re-index its entire context on the next message.
Context Multiplication in Multi-Agent Teams
The token consumption curve steepens dramatically when using multi-agent features. Claude Code includes experimental support for agent teams (CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1), which allows a primary coordinator to spawn independent subagents for parallel tasks like research, testing, and implementation.
Each spawned teammate operates with its own dedicated context window and execution loop. Teammates independently ingest CLAUDE.md, load tool definitions, read project files, and maintain distinct message histories.
Anthropic documentation notes that agent teams consume substantially more tokens than standard sessions when teammates run in plan mode, because each teammate maintains its own context window and runs as a separate Claude instance.
Without strict context boundaries, spawning three parallel agents to inspect a bug can consume hundreds of thousands of tokens within minutes. Managing agent teams requires strict scoping: assign teammates tightly defined tasks, enforce concise return payloads, and terminate idle subagents immediately upon task completion.
How Context Compaction and Memory Pruning Function
To prevent long-running terminal sessions from crashing against the 200,000-token ceiling, Claude Code employs an automated mechanism known as context compaction. Compaction balances the need for historical context against the physical constraints of the model window.
When conversation history approaches the total context window capacity, Claude Code triggers auto-compaction. During this process, the CLI passes the accumulated conversation to Claude with instructions to generate a concise summary. The compaction engine drops verbose tool execution results, clears raw test outputs, removes intermediate file contents, and distills the session down to essential facts:
- Files that were inspected, created, or modified.
- Critical architectural decisions agreed upon by the developer and agent.
- Unresolved errors, remaining tasks, and explicit instructions for next steps.
Once generated, this summary replaces the lengthy conversation history in active memory. The total context size drops from near capacity back down to a manageable baseline, typically between 15,000 and 30,000 tokens. This reduction frees up space for subsequent code reads and diff generation.
Developers can also trigger compaction manually at any time using the /compact command. Running manual compaction is advisable before pivoting to a complex implementation step, so that the model operates with clean, focused context. You can pass explicit instructions to guide what the summary preserves:
/compact focus on modified auth endpoints, database schema changes, and failing unit tests
You can also establish persistent compaction rules in your repository's root CLAUDE.md file. Adding a dedicated section guarantees that every automated or manual compaction pass preserves domain-critical context:
### Compact instructions

When compacting conversation history:
- Always retain modified file paths and exported function signatures.
- Keep track of mock configurations used during test runs.
- Discard raw terminal stdout from passing test suites.
The Operational Difference Between /compact and /clear
Understanding when to use /compact versus /clear is the foundation of terminal token hygiene.
The /compact command summarizes existing history to free up context while maintaining narrative continuity. However, compacting a 150,000-token session is itself a significant operation: the model must read all 150,000 tokens to author the summary. While it preserves context, it costs both processing time and token expenditure.
In contrast, the /clear command completely wipes conversation history from memory, resetting the session token count to zero. It retains your project memory (CLAUDE.md), loaded skills, and repository files on disk, but drops all previous chat exchanges.
The operational rule is straightforward: use /compact when continuing an ongoing task that requires prior decisions, and use /clear when beginning an unrelated task. If you finish fixing a CSS layout bug and plan to start working on database migrations, running /compact wastes tokens preserving irrelevant front-end details. Run /clear instead to give Claude Code a fresh, unpolluted workspace.
Inspecting Context Consumption with Built-In CLI Commands
Claude Code provides several diagnostic commands to monitor context growth in real time:
/context: Displays a visual breakdown of active tokens, illustrating how much space is consumed by system prompts,CLAUDE.md, configured MCP tools, custom skills, and conversation turns./usage: Shows detailed API token counts, session durations, prompt cache hit ratios, and estimated dollar costs. Pressdorwto toggle between daily and weekly metrics./cost: Reports real-time token expenditure for the active session, especially useful for developers authenticating with direct API keys.- Terminal Spinner Counter: During code generation, the terminal spinner displays an active token counter indicating how many tokens the current turn has produced so far.
Monitoring these tools regularly helps identify misbehaving commands, oversized prompt files, or runaway subagents before they exhaust plan quotas.


Extend Claude Code Beyond Local Context Limits
Connect Claude Code to a shared Fastio workspace over MCP. Index large project documentation, preserve version history, and retrieve context on demand without filling your active context window. Monthly plans start with a 14-day free trial that requires a credit card.
Five Practical Context Optimization Habits for Developers
Adopting disciplined context hygiene dramatically extends your daily coding capacity in Claude Code. Applying five practical habits prevents runaway token inflation and improves generation accuracy:
1. Clear Between Unrelated Tasks
Every prior message in a session is resent on every subsequent turn. A session that wanders through three distinct features pays the token cost of all three on every message. When a task is complete, run /clear before starting the next one. If you might need to revisit the conversation later, use /rename to give the session a meaningful title before clearing, then return to it later using claude --resume.
2. Point to File Paths Instead of Pasting Code
Pasting large code blocks, stack traces, or configuration files into the terminal embeds that full text into conversation history permanently. When you paste 500 lines of code, you pay for those 500 lines on every subsequent turn. Instead, reference the file path directly in your prompt:
Look at the validateToken function in src/auth/jwt.ts and add expiration checks
Claude Code will open the file, read only the relevant function, and leave the rest out of permanent context. Avoid using the @ file prefix unless strictly necessary, as @ forces the entire file and its dependency context into memory.
3. Maintain a Lean CLAUDE.md File
The project instruction file CLAUDE.md is prepended to every single prompt. While prompt caching reduces the financial cost of re-reading this file, it still occupies permanent context window space on every turn. Follow the two-strikes rule: only add a rule to CLAUDE.md after Claude makes the same mistake twice. Aim to keep CLAUDE.md concise, maintaining within 200 lines. Move workflow-specific documentation into on-demand skills that load only when explicitly invoked.
4. Filter Terminal Output with PreToolUse Hooks
Verbose terminal commands are major sources of token bloat. Running npm test across a full test suite can print thousands of lines of passing output into context. Claude Code supports custom hooks that preprocess commands before the model sees them. A PreToolUse hook can rewrite test commands to pipe stdout through filters, returning only failing assertions and errors:
{
  "hooks": {
    "PreToolUse": [
      {
        "matcher": "Bash",
        "hooks": [
          {
            "type": "command",
            "command": "~/.claude/hooks/filter-test-output.sh"
          }
        ]
      }
    ]
  }
}
Filtering test outputs reduces terminal output from 20,000 tokens down to 200 tokens, preserving context for code generation.
5. Match the Model to the Task Complexity
Using Claude Opus for routine tasks like renaming variables or writing boilerplate drains usage allowances rapidly. Use /model to select the right tool for the job:
- Claude 3.7 Sonnet: The optimal default for standard development, bug fixing, test writing, and refactoring.
- Claude Opus: Reserved for complex architecture planning, deep algorithmic debugging, or wide cross-cutting changes. Use the
/model opusplanmode to let Opus author the initial plan and Sonnet execute the code. - Claude Haiku: Ideal for fast, low-cost subagent tasks, commit message generation, and simple regex creation.
Managing Extended Thinking Token Budgets
Extended thinking enhances Claude's code generation quality, but it can quickly consume your token budget if misconfigured. In Claude 3.7 Sonnet, extended thinking is metered as output tokens.
For straightforward coding tasks, lower the thinking effort using the /effort command, or cap the maximum thinking tokens in your environment:
export MAX_THINKING_TOKENS=8000
Setting an 8,000-token thinking ceiling prevents the model from spending tens of thousands of tokens overthinking simple refactoring tasks, preserving both your budget and your per-turn output buffer.
Scaling Beyond Token Limits: The External Workspace Architecture
Even with aggressive compaction and disciplined prompting, development teams eventually hit an architectural wall: large codebases and project knowledge repositories simply do not fit inside a 200,000-token context window.
When engineering teams build complex systems, they must manage extensive documentation: OpenAPI specifications, architectural decision records, security policies, database migration histories, and external API manuals. Dumping these assets into local project files forces Claude Code to scan hundreds of thousands of tokens, triggering constant auto-compaction and degrading reasoning accuracy.
Traditional workarounds carry significant trade-offs:
- Local git repository storage: Adding large documentation sets, PDFs, and API dumps directly to git bloats repository size and requires constant file grep searches that pollute active context.
- Generic cloud drives (Google Drive, Dropbox, Box): Standard consumer storage tools sync files to local machines, but they lack agent-native retrieval interfaces, meaning agents still have to ingest whole files locally.
- Raw cloud buckets (Amazon S3): Object storage stores arbitrary files, but it provides no built-in semantic search, no versioned document chat, and no native Model Context Protocol integration.
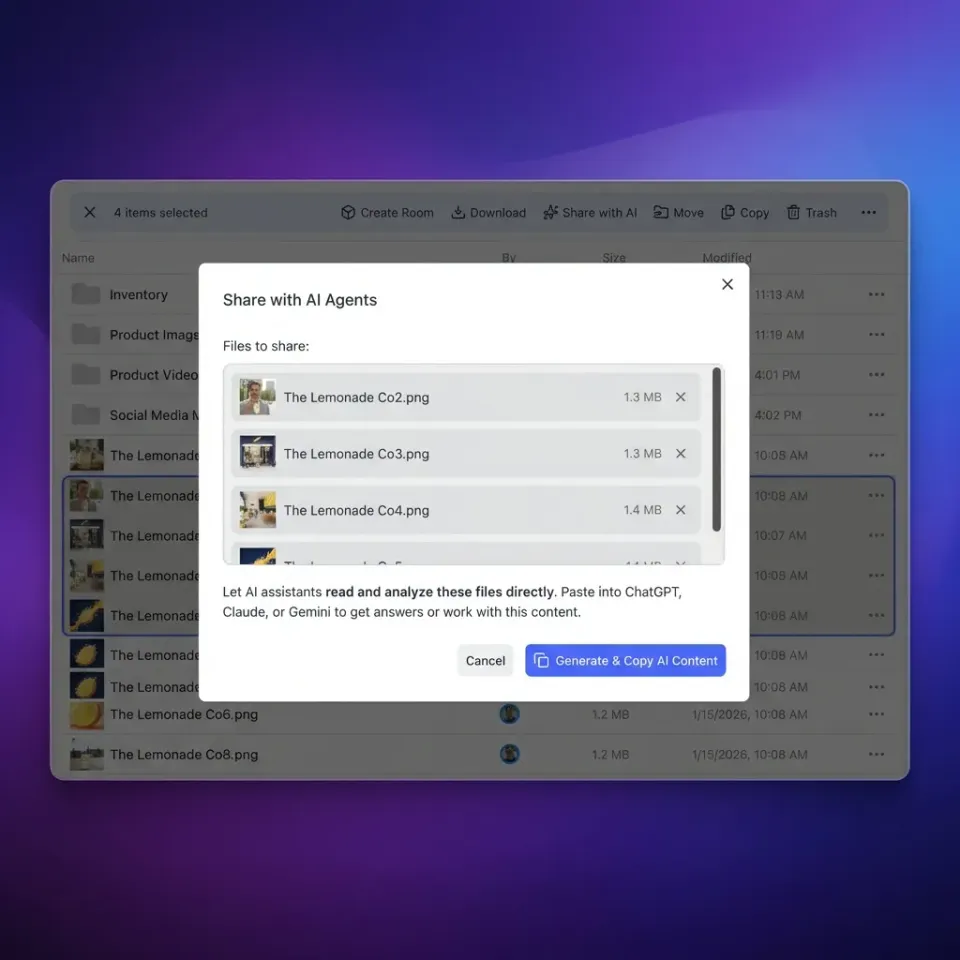
The modern solution is an external workspace architecture that separates working code from persistent project knowledge. Instead of pushing reference corpora into the local repository or active terminal context, teams place project documentation into a shared Fastio workspace.
Fastio provides intelligent cloud workspaces built for agentic teams. When documents, specifications, or datasets are added to a Fastio workspace, Intelligence Mode automatically indexes the files for hybrid search, combining full-text indexing, semantic search, and metadata matching without requiring a separate vector database.
Claude Code connects directly to Fastio storage for agents using the official Model Context Protocol (MCP) server over Streamable HTTP, documented in the Fastio setup docs:
claude mcp add --transport http fast-io https://mcp.fast.io/mcp/code
Once connected, running /mcp inside Claude Code initiates an OAuth sign-in flow where developers authenticate and grant access to designated workspaces.
Through this connection, Claude Code interacts with the workspace via targeted MCP actions. Instead of reading a 500-page API manual into its 200,000-token context window, Claude Code executes semantic search queries against the Fastio workspace. The platform retrieves only the exact paragraphs, function definitions, or endpoint specifications needed for the current prompt. The rest of the corpus stays in the cloud workspace, keeping Claude Code's terminal context pristine and preventing premature compaction.
Multi-Agent Coordination and Persistent Version History
In team environments where multiple agents and human engineers collaborate, external workspaces provide critical coordination safeguards:
- Per-file version history: Every file saved to a Fastio workspace retains complete version history. If an automated coding agent introduces an erroneous change or overwrites a colleague's work, prior versions can be restored instantly through the web interface or MCP tools.
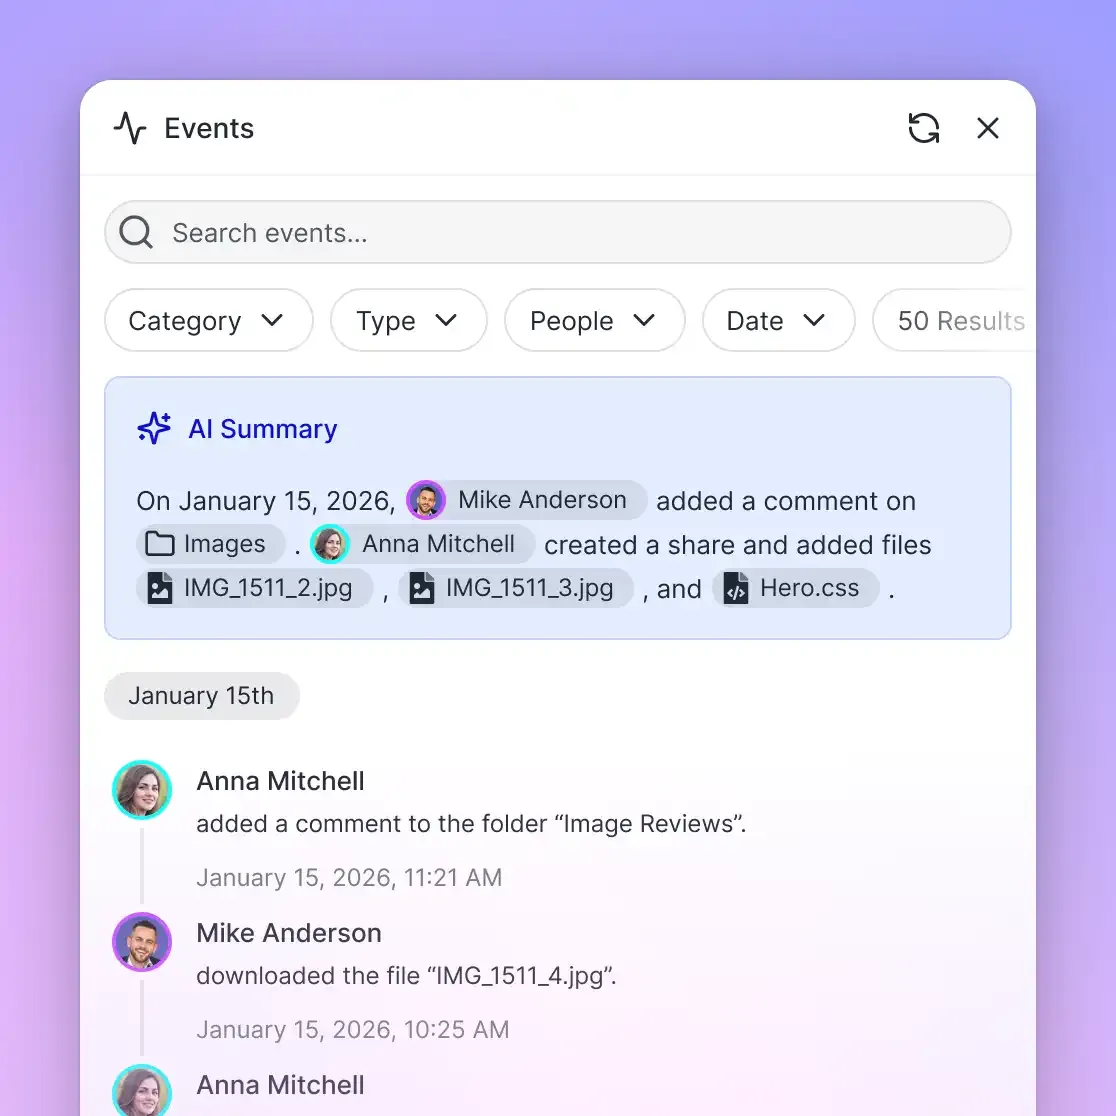
- Detailed activity log: A detailed activity log records changes made by people and agents: uploads, edits, moves, and deletions, alongside membership and permission changes and share creation. While the log deliberately avoids tracking read-only events like views or downloads, it records who changed what and when.
- Workspace and share permissions: Access controls are configured per organization, workspace, and branded share via member roles, eliminating the administrative fragility of folder-level permission setups.
- Multi-cloud sync: Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders to a workspace, operating one-way or two-way on a schedule or on demand. Teams can aggregate documentation from existing enterprise drives into an indexed agent workspace without manual file transfers.
Onboarding details and tier breakdowns are documented on Fastio pricing, designed to align with team scale:
Monthly plans start with a 14-day free trial that requires a credit card. Credits meter AI work only, and overage is $10 per 100,000 credits. By decoupling project context from terminal memory, development teams maximize Claude Code's performance while keeping token spend under control.
Sources
References used to verify factual claims in this guide.
-
Across enterprise deployments, the average cost is around $13 per developer per active day and $150-250 per developer per month, with costs remaining below $30 per active day for 90% of users.
-
Anthropic documents that Claude chat accepts up to 20 files at 500MB each, while Claude Projects supports files up to 30MB each with no fixed file-count cap as long as content fits within the context window.
Frequently Asked Questions
What is the token limit for Claude Code?
Claude Code operates with a 200,000-token input context window on standard models including Claude 3.7 Sonnet, Claude 3.5 Sonnet, and Claude Opus. Its per-turn output generation limit is 8,192 tokens for standard responses, reaching 64,000 tokens when using extended thinking on Claude 3.7 Sonnet. On subscription plans (Pro and Max), usage is further governed by rolling 5-hour session limits and weekly quotas.
How does Claude Code handle long conversations when tokens run out?
When a conversation approaches the context window limit, Claude Code initiates auto-compaction. It summarizes previous turns, drops verbose tool execution logs and raw file dumps, and replaces the detailed history with an executive summary. Developers can also trigger this process manually using /compact or reset context completely using /clear.
How can I reduce token usage in Claude Code?
You can reduce token usage by running /clear between unrelated tasks, pointing Claude Code to specific file paths instead of pasting raw code, keeping CLAUDE.md concise and within 200 lines, filtering bash tool output with PreToolUse hooks, and matching models to task complexity with /model opusplan or Haiku subagents.
What is the difference between /compact and /clear in Claude Code?
The /compact command summarizes previous conversation history to free up context while preserving key decisions, modified files, and pending tasks. The /clear command completely wipes conversation history, resetting active context to zero tokens while leaving project memory (CLAUDE.md) and repository files intact on disk.
Does extended thinking count against the Claude Code token limit?
Yes. Thinking tokens are billed as output tokens and count toward per-turn generation limits. On Claude 3.7 Sonnet, thinking tokens and visible response tokens share a combined 64,000-token output ceiling per turn. You can limit thinking token consumption by lowering the effort level with /effort or setting the MAX_THINKING_TOKENS environment variable.
How do Claude Code usage limits differ between Claude Pro, Max, and API billing?
Claude Pro provides baseline 5-hour session and weekly limits. Claude Max tiers offer expanded session capacity within rolling windows. In contrast, Claude Console API and cloud provider accounts have no session caps and are billed per token based on actual consumption.
Related Resources

Extend Claude Code Beyond Local Context Limits
Connect Claude Code to a shared Fastio workspace over MCP. Index large project documentation, preserve version history, and retrieve context on demand without filling your active context window. Monthly plans start with a 14-day free trial that requires a credit card.