Claude Code Context Window: Managing Token Limits in Terminal Agents
The Claude Code context window determines how much conversation history, source code, and command output a terminal agent retains during active development. When complex debugging loops and repetitive file reads saturate working memory, automated compaction summarizes prior turns to prevent context exhaustion. This guide explains how the working buffer fills, how to control compaction thresholds, and how to offload large technical documentation to external Fast.io workspaces via remote MCP.

What Is the Claude Code Context Window and How Does It Fill?
Claude Code operates on a default 200,000 token context window across standard Sonnet and Opus models, according to Anthropic's official model configuration documentation. Sonnet and Opus sessions without extended context compact at the 200K boundary. Understanding this working buffer is essential for running terminal coding agents on production codebases without losing conversational context mid-task.
Claude Code's context window is the working memory buffer (200k tokens) that holds codebase snippets, shell command outputs, tool invocations, and session history in the CLI agent. Unlike stateless API calls where each request is independent, an interactive terminal agent continuously accumulates context. Every prompt you enter, every file Claude reads, every bash command executed by the agent, and every diff generated during an editing pass remains in the active buffer.
Before you type a single prompt in a new session, Claude Code loads several structural components into the context window:
- System prompt: Core behavioral instructions, tool definitions, and output formatting guidelines established by Anthropic. This foundation occupies several thousand tokens and remains active throughout the session.
- Auto memory: Learned conventions and patterns recorded in
MEMORY.mdduring earlier sessions, up to two hundred lines or twenty-five kilobytes. This includes persistent preferences, project quirks, and build commands Claude learned from prior corrections. - Environment metadata: Working directory paths, operating system version, shell environment, active git branch, working tree status, and recent commit hashes.
- Deferred MCP tool definitions: Available Model Context Protocol tool names and server instructions. Full parameter schemas remain deferred by default and load dynamically through tool search only when invoked.
- Skill descriptions: One-line summaries of available skills and slash commands. The full instructional content of a skill loads only when triggered.
- Project instructions: Global directives from
~/.claude/CLAUDE.mdand repository guidelines from the project rootCLAUDE.md.
As software engineers tackle larger features, context capacity varies based on the active model configuration. The following comparison outlines token allowances and compaction triggers across Claude models supported in terminal environments:
Select Claude models support an extended 1 million token context window for long sessions. Developers who require massive context buffers can select these extended variants through model aliases such as sonnet[1m] or opus[1m]. However, expanding the raw context limit increases latency and inference costs. For most day-to-day engineering workflows, learning to manage the standard 200,000 token buffer yields faster responses, cleaner execution, and predictable token expenditures.
Related guides
- Managing the GitHub Copilot Context Window & Token LimitsManaging the active token memory in GitHub Copilot is essential for complex repository operations. This guide details...
- Claude Haiku Context Window: Token Limits, Latency, and WorkaroundsThe Claude Haiku context window provides a 200,000-token input memory buffer for high-speed processing across...
- Claude Desktop Context Window: Token Limits, MCP Overhead, and Document RetrievalClaude Desktop operates with a standard 200,000-token input context window (with options up to 1,000,000 tokens on...
- Claude Opus Context Window: Token Limits, Pricing, and Large-Corpus SearchThe Claude Opus context window defines the active working memory available for complex reasoning, document analysis,...
- Claude 3.5 Sonnet Context Window: 200,000 Token Limit and Output BudgetsThe Claude 3.5 Sonnet context window is 200,000 input tokens with a maximum output limit of 8,192 tokens per request....
- Claude 3.7 Sonnet Context Window: 200K Tokens, Extended Thinking, and PricingAnthropic's Claude 3.7 Sonnet pairs a 200,000-token input context window with a dynamic thinking budget capable of...
More on this subject: Claude and Claude Code (249 guides)
Why Terminal Coding Agents Run Out of Context During Complex Tasks
Terminal coding assistants experience context pressure far more rapidly than conversational chatbots. In a web chat interface, messages consist primarily of concise human prose. In a command-line development loop, Claude Code interacts directly with your filesystem, terminal shell, and build toolchains, generating voluminous data streams that rapidly deplete available token allowances.
The primary operational cause of context exhaustion is the disparity between what the developer sees in the terminal interface and what enters the model's actual context window. When Claude Code executes a command, the terminal user interface displays a compact, polished notification, such as "Read auth.ts" or "Ran npm test". Behind that single line of display text, thousands of tokens of raw code and compiler output are appended directly to the conversation history.
Re-reading files across multiple tool loops rapidly depletes token allowances. When an agent traces an unfamiliar code path, it inspects related files sequentially. Reading a core controller, a helper module, and an interface file can add several thousand tokens to the session within two conversational turns. If the agent needs to re-verify those files later in the turn sequence after attempting an edit, repeated inspections consume tokens at an accelerating rate.
The Compounding Cost of File Inspection and Search Dumps
Codebase exploration commands generate substantial context overhead. When an agent runs text searches to locate a function definition or inspect references across a project, tools like grep, glob, or ripgrep return formatted search results.
A broad search query can easily return hundreds of matching lines across dozens of source files. While a human developer scans these results visually and focuses on two relevant lines, the agent context ingests the entire search payload. If the agent conducts five exploratory searches before identifying the target file, fifteen to twenty thousand tokens may be consumed before the first code modification begins. Path-scoped rules in .claude/rules/ also load automatically into context whenever Claude inspects files matching their path patterns, introducing additional instruction tokens alongside the raw file content.
Shell Output Pollution and Formatting Hooks
Running local build commands, linters, and automated test suites represents another major source of context pollution. Executing a test runner like npm test, cargo test, or pytest often produces verbose terminal outputs containing stack traces, execution metrics, deprecation notices, and environment summaries.
Even when a test run fails on a single assertion, the full stderr output enters the agent context so Claude can diagnose the failure. If the test suite emits hundred-line stack traces or verbose logging statements, each verification run adds substantial token weight. Furthermore, automated formatting hooks, such as a PostToolUse hook configured to execute code formatters like Prettier after every file write, can append diagnostic reports to the context buffer. Over a ten-turn debugging sequence, shell outputs and hook diagnostics can accumulate thirty to fifty thousand tokens.
The Claude Projects 50-File Boundary and Attachment Saturation
Software teams encountering token bottlenecks in Claude Code often arrive from Claude Projects in the web interface. In Claude Projects, users frequently encounter the 50-file project limit or notice performance degradation when uploading large collections of architectural specifications, API schemas, and technical guides.
When developers migrate from the web interface to the Claude Code terminal CLI, they frequently replicate the same mistake locally. They instruct the terminal agent to inspect large reference directories or point it at extensive documentation repositories. Because local file system reads have no arbitrary file count restrictions, the agent aggressively reads every document in the target directory. A developer attempting to ground an agent in an entire API specification directory will saturate the 200,000 token context window in minutes, triggering unexpected compaction and degraded reasoning precision.
How to Monitor Context Consumption and Manage Session Compaction
Maintaining control over Claude Code requires active visibility into token consumption. Rather than waiting for automatic compaction to trigger unexpectedly during a delicate refactoring pass, developers should monitor active context usage and apply manual controls proactively.
Claude Code provides built-in session commands that report exact token allocation across active memory categories:
/context: Displays a real-time visual breakdown of active token usage. It details the exact token consumption of the system prompt, project root instructions, auto memory files, read source files, tool execution results, and conversational turns. It also highlights optimization suggestions when specific files dominate the window./cost: Summarizes total token consumption for the active session, including input tokens, output tokens, prompt cache read tokens, and cache write tokens, alongside total dollar expenditures./status: Reports the current model selection, active permission mode, session duration, and connected account parameters.
Monitoring these commands periodically enables developers to identify context spikes before the agent begins experiencing recall issues.
Guiding Summaries with Manual Compaction and Rewind
When context begins approaching saturation, Claude Code automatically compacts the conversation history. Compaction replaces earlier conversational turns, raw tool results, and intermediate reasoning traces with a structured technical summary. This summary preserves critical facts, including user intent, modified file paths, essential code snippets, and active errors.
However, automatic compaction uses generic heuristics to determine what matters. Developers can achieve superior continuity by running manual compaction with explicit focal instructions:
/compact focus on the authentication refactor and database schema migration
By providing a focus directive, you ensure that the compaction pass prioritizes the technical components you care about while discarding transient search results and debugging dead ends.
If an agent took an unproductive troubleshooting detour that wasted thirty thousand tokens, running /rewind allows you to revert to a previous message turn. From the rewind interface, you can select "Summarize up to here" to compress earlier background work while preserving current progress, or run /clear when completing a task to wipe working memory completely before beginning unrelated feature work.
What Survives the Compaction Boundary
Understanding how different configuration elements behave during compaction prevents lost project conventions. The table below details what survives a compaction pass:
Because path-scoped rules and nested directory instructions reload only when matching files are re-read, critical project-wide standards belong in the root CLAUDE.md file rather than buried in deep subdirectories.
Delegating Research to Subagents with Isolated Windows
One of the most effective strategies for protecting your primary terminal context window is delegating research tasks to subagents. In Claude Code, subagents execute in their own isolated context windows.
When you direct Claude Code to research a problem using a subagent, the parent session spawns an independent worker process:
Use a subagent to research how session timeouts are handled across src/services, then propose a fix
The subagent receives the research task and begins exploring the codebase. It can read ten files, execute multiple grep queries, and process fifteen thousand tokens of raw code within its isolated context. None of those file reads or intermediate search traces enter your main session context. When the subagent completes its investigation, it returns a concise four-hundred-token summary to the parent agent. You obtain the architectural answers needed to implement the fix while keeping your primary context window lean and responsive.
Connecting Claude Code to External Workspaces via Remote MCP
While subagents and manual compaction mitigate local context bloat, engineering teams working across extensive codebases, multi-repository architectures, and comprehensive documentation sets require a systemic storage architecture. Attempting to manage massive technical archives by having an agent read local files directly will always collide with token capacity limits.
The architectural solution is decoupling persistent document storage from ephemeral inference context. Instead of forcing Claude Code to ingest complete documentation files into its working memory, teams store project reference archives in shared cloud workspaces and connect the CLI agent through the Model Context Protocol (MCP).
Connecting Claude Code to an external workspace does not alter or expand the model's native context window limit. The agent still operates with its standard token ceiling. The architectural difference lies in how information enters that ceiling: instead of loading a fifty-thousand-token document to find one configuration setting, the agent executes targeted semantic queries against an external index and receives only the three relevant paragraphs, complete with document citations.
Configuring Fast.io Workspaces and Remote MCP Access
Fast.io provides an intelligent cloud workspace platform engineered for collaboration between humans and AI agents. Within Fast.io, teams create shared organization-owned workspaces where technical documents, architecture decision records, API specifications, and database diagrams live in a persistent environment.
Setting up a shared workspace archive follows three direct steps:
First, deposit your technical documentation into an organization workspace. You can upload files directly through the web console, script batch uploads using the official Fast.io command-line interface (@vividengine/fastio-cli on npm), or synchronize existing documentation directories. Fast.io supports cloud synchronization on a schedule or on demand for Dropbox, Box, and OneDrive, while Google Drive supports direct cloud import today.
Second, enable Intelligence Mode on the workspace. When Intelligence Mode is active, all uploaded documents, including PDFs, Markdown documentation, Word files, spreadsheets, and scanned system diagrams, are automatically indexed upon arrival. Fast.io generates a hybrid search index combining semantic vector retrieval with exact full-text keyword matching, eliminating the need to deploy and manage a separate vector database.
Third, connect your Claude Code terminal environment to the workspace using Fast.io's remote MCP server. The Fast.io MCP server operates remotely over Streamable HTTP at https://mcp.fast.io/mcp/code (for setup steps, see Fast.io MCP documentation). Because the server is hosted remotely, you do not need to install local npm daemons, background proxy containers, or local Python runtimes.
To configure Claude Code, create an .mcp.json file in your project repository root:
{
  "mcpServers": {
    "fastio-workspace": {
      "type": "http",
      "url": "https://mcp.fast.io/mcp/code"
    }
  }
}
You can also pass this configuration explicitly upon starting Claude Code:
claude --mcp-config .mcp.json
Claude Code detects the connection and registers Fast.io's consolidated MCP toolset while deferring full schemas until tools are called.
Semantic Retrieval Versus Raw File Reads
Once connected, Claude Code retrieves reference knowledge through targeted MCP tool calls rather than indiscriminate file system reads. When an engineer asks Claude Code to implement a feature conforming to enterprise security standards, the agent does not parse a hundred-page compliance manual into its context window.
Instead, Claude Code invokes the workspace search endpoint (GET /current/workspace/{workspace_id}/storage/search/). The search query evaluates both keyword matches and semantic meaning, retrieving the specific paragraphs governing token validation, password hashing, and session timeouts. The tool returns concise text excerpts accompanied by source document names and page numbers.
This targeted retrieval transforms token economics. A research query that would have consumed forty thousand tokens of raw PDF and Markdown text enters the context window as a five-hundred-token structured excerpt. The agent preserves 99 percent of its context capacity for code synthesis, test execution, and diff generation.
For structured operational parameters, teams use Metadata Views. Metadata Views convert unstructured technical documents into live, queryable database spreadsheets. Users describe desired attributes in natural language, and Fast.io extracts typed values across Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time formats. Terminal agents can query these structured records through MCP without parsing raw document text.
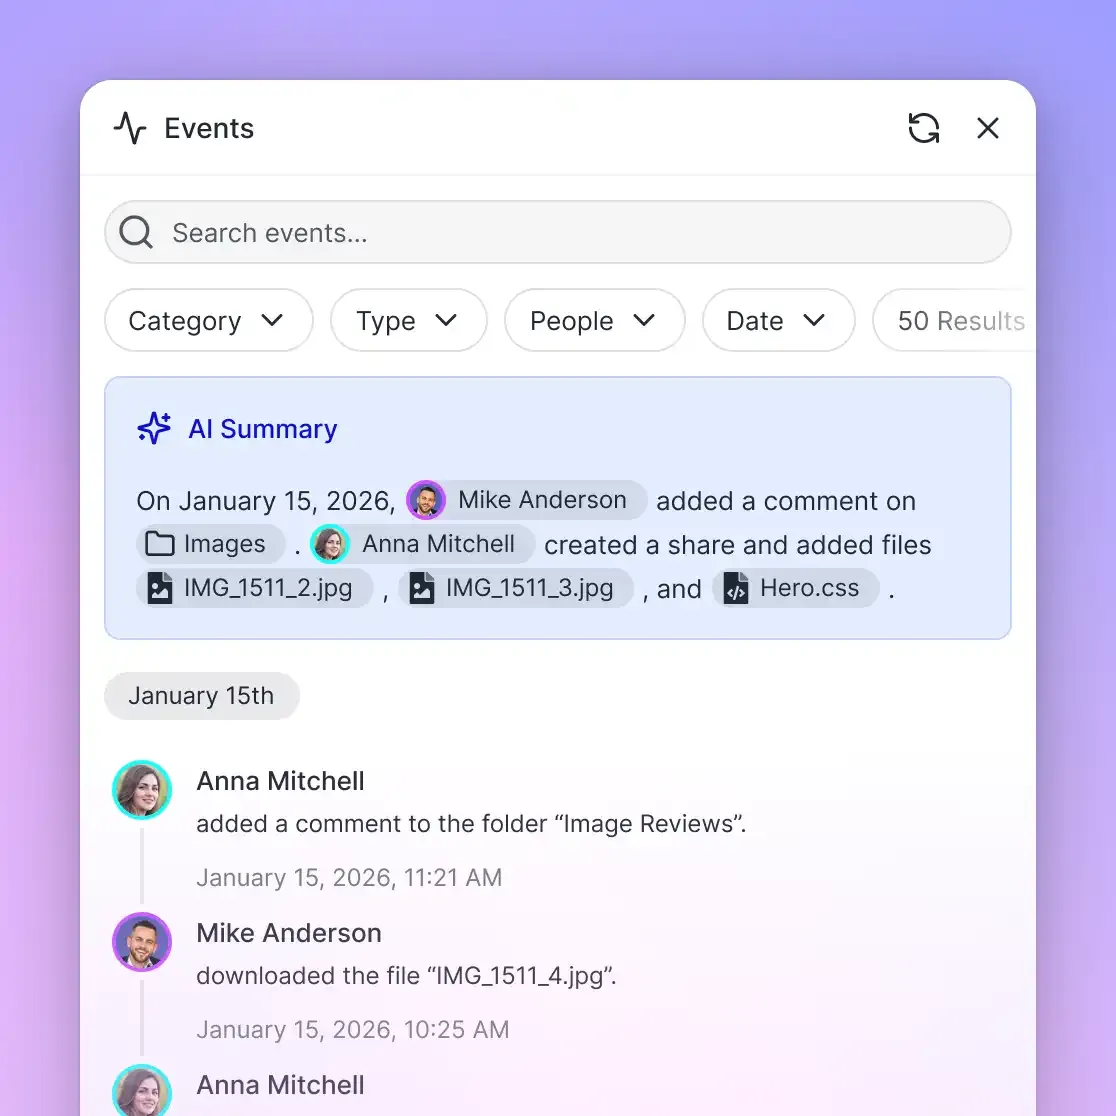
Furthermore, Fast.io safeguards multi-agent collaboration with per-file version history and a detailed activity log. If a terminal agent writes an updated configuration file or intermediate deliverable to the workspace, team members can inspect previous versions and review the complete audit trail in the browser UI. Granular access permissions ensure that agents access only designated workspaces, and organizational ownership transfer allows an agent to configure project workspaces and hand administrative control to a human lead while preserving operational access.


Offload document retrieval from your terminal agent context
Connect Claude Code to an intelligent workspace with hybrid search, per-file version history, and remote MCP connectivity. Every organization starts with a 30-day free trial, which requires a credit card. Plans are Starter at $9.99/mo, Business at $49.99/mo, and Enterprise at $199.99/mo.
Operational Guidelines for Managing Token Budgets in Terminal Agents
Scaling command-line coding agents across engineering teams requires disciplined operational standards. Without deliberate controls, autonomous terminal sessions can loop through recursive errors, consume unnecessary tokens, and produce uncoordinated code modifications. Implementing clear repository conventions and runtime guardrails ensures high-quality output while conserving token budgets.
Begin by establishing repository-level instruction standards. Commit your project's .mcp.json configuration and a concise root CLAUDE.md into version control. Keep CLAUDE.md under two hundred lines, focusing strictly on build commands, testing procedures, and primary architecture patterns. Move detailed directory-specific guidelines into .claude/rules/ files with path-matching frontmatter so they enter context only when matching source files are touched.
Next, manage skill visibility deliberately. In your project's SKILL.md definitions, add disable-model-invocation: true to skills that perform stateful actions, such as committing code, deploying containers, or sending notifications. This setting prevents skill descriptions from loading into startup context, keeping them completely out of the agent's memory until a human explicitly invokes them with a slash command.
Execution Limits and Financial Guardrails
When running Claude Code in unattended terminal scripts, automated CI pipelines, or background tasks, always apply execution limits:
claude -p "refactor authentication error handling in src/auth" --max-turns 12 --max-budget-usd 4.00
The --max-turns flag prevents the agent from entering circular self-correction loops when encountering intractable build failures. The --max-budget-usd flag establishes an absolute financial spending cap for the invocation.
Enforce terminal hygiene during interactive sessions. When shifting from an architecture refactoring task to unrelated bug fixing, run /clear to start with an unpolluted context window. When concluding a major sprint, run claude project purge to remove local session transcripts and cached diffs from your local disk.
Multi-Agent Coordination and State Isolation
When multiple developers and automated agents collaborate across a common software architecture, avoid stranding intermediate outputs on individual developer laptops. If an agent generates API specifications, database migration guides, or benchmark spreadsheets, instruct it to write those artifacts directly to a shared Fast.io workspace.
Fast.io Coordination Rooms provide a shared workspace where agents from different people and different tools post messages, hand off deliverables, and share versioned files. A backend engineer running Claude Code in the terminal can write a generated OpenAPI specification to a room folder, allowing a frontend engineer running Cursor or Codex to consume the verified specification immediately.
To explore connected agent storage and onboarding documentation, visit the agent storage guide, review the Fast.io agent onboarding guide, or evaluate workspace options on the pricing page. Combining disciplined local session management with Fast.io's persistent indexed workspaces ensures that terminal agents maintain high reasoning precision across long-running development projects.
Sources
References used to verify factual claims in this guide.
-
Sonnet and Opus sessions without extended context compact at the 200K boundary.
-
Select Claude models support an extended 1 million token context window for long sessions.
Frequently Asked Questions
What is the context window limit in Claude Code?
Claude Code standard sessions operate on a 200,000 token context window across Sonnet and Opus models, compacting at the 200K boundary. For extended tasks, select models including Claude Sonnet 5, Opus variants, and Fable support an extended 1 million token context window.
How do you clear or compact context in Claude Code?
You can manage context in an active session by running /compact to summarize conversation history, or /compact focus on <topic> to steer the summary toward specific files or tasks. To adjust the automatic threshold, run /autocompact <tokens>. To wipe the conversation history while preserving repository files, run /clear.
Why does Claude Code run out of context so quickly?
Context depletes rapidly because every file inspection, test output, compiler trace, and tool call is stored in the session message array. Reading several large source files or executing test commands that return long terminal traces can consume tens of thousands of tokens within a few conversational turns.
What happens to files and skills after running /compact?
Compaction summarizes conversation history, tool outputs, and intermediate reasoning into a concise technical summary. The system prompt, project root CLAUDE.md, and auto memory persist from disk. Claude Code automatically re-reads up to five recently modified files, and invoked skills are re-injected up to configured token caps.
How does connecting Fast.io via MCP reduce context window consumption?
Connecting Claude Code to Fast.io via remote MCP allows the agent to execute semantic searches across indexed workspace documents. Instead of reading full documentation files or large specifications into its active context, the agent retrieves only the specific relevant paragraphs, reducing token consumption from tens of thousands of tokens to a few hundred.
Related Resources

Offload document retrieval from your terminal agent context
Connect Claude Code to an intelligent workspace with hybrid search, per-file version history, and remote MCP connectivity. Every organization starts with a 30-day free trial, which requires a credit card. Plans are Starter at $9.99/mo, Business at $49.99/mo, and Enterprise at $199.99/mo.