ChatGPT Google Drive Plugin: Connecting Drive Files Without Context Bloat
Connecting Google Drive directly to ChatGPT often floods the prompt context window with raw text, causing token exhaustion and forgotten conversation turns. A ChatGPT Google Drive plugin enables ChatGPT conversations to query documents, spreadsheets, and presentations stored in Google Drive via targeted semantic retrieval. By syncing Drive folders into an indexed workspace, teams query specific excerpts through remote Model Context Protocol tools without saturating context limits.

Why Direct Google Drive Ingestion Bloats ChatGPT Prompts
When a language model reads a file from cloud storage, it does not skim like a human; it translates the entire document payload into input tokens that fill the prompt's active context window. In a typical chat session, uploading or referencing a large PDF or an extensive spreadsheet immediately consumes tens of thousands of tokens before you ask your first analytical question.
A ChatGPT Google Drive plugin enables ChatGPT conversations to query documents, spreadsheets, and presentations stored in Google Drive via targeted semantic retrieval. Most guides overlook token usage costs and context saturation caused by reading full files instead of using pre-indexed semantic excerpts. When users attach large files directly to a chat, they trigger an architectural mismatch between raw document storage and the finite memory of transformer models.
How Context Saturation Degrades Model Performance
Modern language models support context windows reaching hundreds of thousands of tokens, but larger context windows do not make massive context dumps cost-effective or reliable. In practice, dumping raw files into prompt context causes several immediate problems:
- Attention Degradation: Research into transformer attention patterns consistently demonstrates that retrieval accuracy drops when relevant facts are buried inside massive contexts. Key clauses, numeric tables, or critical caveats located in the middle of long documents get overlooked.
- Conversational Amnesia: Every file dumped into a chat session consumes token headroom that would otherwise preserve conversational history. As your discussion continues and reaches token limits, earlier conversation turns, system instructions, and user constraints get truncated.
- Compounding Latency and Cost: Processing tens of thousands of document tokens on every single prompt turn slows down model generation. Each subsequent follow-up question reprocesses the entire conversation history, multiplying latency and quickly exhausting usage allocations.
Native file pulls stream full documents into prompt context, quickly consuming context windows. Rather than forcing ChatGPT to ingest entire documents on every prompt, effective agent architectures decouple cloud storage from prompt context. Pre-indexing documents in an external retrieval layer allows the model to pull only the specific sentences, tables, or sections necessary to answer each query.
Related guides
- ChatGPT Google Drive Sync: How to Connect, Index & Query Drive FilesChatGPT Google Drive sync connects OpenAI models to cloud document folders for fast semantic search and contextual...
- How to Connect Google Drive to ChatGPT: Setup and Agent WorkspacesConnecting Google Drive to ChatGPT allows the model to access, read, and reason about files stored in your cloud...
- Can ChatGPT Access Google Drive? Permissions, Limits & WorkaroundsChatGPT can access Google Drive files through its native integration, but only by retrieving individual user-selected...
- ChatGPT Google Drive Connector: Native Connected Apps vs. Fast.ioA ChatGPT Google Drive connector links OpenAI models to cloud document repositories, enabling conversational search,...
- ChatGPT Google Drive Not Working: Troubleshooting Guide & FixesWhen ChatGPT Google Drive is not working, expired OAuth tokens, unindexed binary formats, or API rate limits during...
- Building a LangGraph Google Drive Storage Connector Without State BloatPassing raw Google Drive files into LangGraph state channels causes serialization bottlenecks, token inflation, and...
More on this subject: Agent Integrations and APIs (191 guides)
How to Connect Google Drive to ChatGPT Directly
Before looking at indexed architectures, it is helpful to understand how OpenAI's native Google Drive connector functions and where its boundaries lie. OpenAI provides an integrated Google Drive app that lets ChatGPT access files directly from your cloud drive.
Setting Up the Native ChatGPT Google Drive Connector
Connecting Google Drive directly to ChatGPT follows a standard OAuth workflow:
- Log in to ChatGPT in your browser and open your user account settings.
- Select the Connected Apps or Connectors section in the settings menu.
- Locate Google Drive in the directory of available cloud services and select Connect.
- Sign in with the Google account that contains the project documents you want to reference.
- Review the requested OAuth permissions and grant ChatGPT access to read files in your drive.
- Return to your chat prompt and reference documents by selecting the attachment menu or mentioning
@Google Drive.
Once connected, you can ask ChatGPT to summarize a selected Google Doc, analyze a specific spreadsheet, or draft responses based on presentation slides. For occasional ad-hoc questions on single files, this workflow is straightforward.
Operational Breakdowns in Production Workflows
While the native connector works for individual files, teams running recurring workflows encounter four persistent operational limitations:
- Manual File Selection: The native connector cannot autonomously index or search across deep, nested folder hierarchies. A user must know which file holds the answer and attach it explicitly. If a question spans ten distinct reports spread across multiple subfolders, manually locating and attaching each file is tedious.
- Ephemeral Authentication Drops: Native OAuth connections in chat interfaces frequently time out. When an authentication session drops, users must stop work, open settings, and re-authenticate before continuing. For automated agent workflows, these session drops halt execution entirely.
- API Rate Limits and Quotas: The Google Drive API enforces per-user and per-project request limits. According to official Google Drive API limits, Google Drive API limits are measured in quota units representing resource usage and return user rate limit errors when exceeded. When automated processes send rapid search queries, download requests, or folder scans, Google Drive throttles the connection, returning rate limit errors that disrupt the conversation.
- Stateless Token Consumption: Closing a conversation thread discards the document state. Starting a new chat to continue the analysis requires pulling the same documents from Google Drive again, re-spending the token budget from scratch.
How to Bridge Google Drive Folders to Fast.io via Cloud Sync
To eliminate context bloat and API rate limits, teams use Fast.io as an intelligent bridge between Google Drive and ChatGPT. Fast.io is a cloud workspace platform for agentic teams. Instead of abandoning Google Drive, you keep your existing file organization in Google Drive, Dropbox, Box, or OneDrive.
Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand, never continuous, live or real-time; SharePoint libraries through the OneDrive connector.
Server-to-Server Ingestion Without Local Overhead
Importing folders from Google Drive into Fast.io runs backend-to-backend through Google OAuth. The platform pulls files directly between cloud servers:
- Zero Local Bandwidth: Syncing large project archives does not consume your local internet connection or fill up local disk space.
- Preserved Folder Hierarchies: Complete folder trees, nested directories, and original filenames replicate directly into your org-owned Fast.io shared workspaces.
- Format Normalization: Fast.io processes PDFs, Word documents, spreadsheets, presentations, and text files into standard formats ready for indexing.
Scheduled and On-Demand Synchronization
Because Cloud Sync is designed for predictable, production-grade operations, synchronization runs on a schedule or on demand rather than continuous live polling. Teams can configure sync intervals (such as hourly or daily) or trigger an immediate sync when new assets land in Drive.
This scheduled approach protects your team from Google Drive API quota exhaustion. All intensive search operations, semantic parsing, and AI queries run against the indexed Fast.io workspace rather than hitting the live Google Drive API. Fast.io serves as an intelligent buffer layer that keeps files permanently organized, cached, and available for AI processing.


Query Google Drive in ChatGPT Without Context Saturation
Sync your Drive folders into an intelligent Fast.io workspace and connect ChatGPT via remote MCP. Keep prompts lean with targeted semantic search on a 14-day trial.
How to Connect ChatGPT to Fast.io via Remote Plugin and MCP
Once your Google Drive files are synced into a Fast.io workspace, you can connect ChatGPT using the Model Context Protocol (MCP). The Model Context Protocol provides an open standard for connecting AI models to external tools and data stores.
Fast.io hosts a remote MCP server over Streamable HTTP. It does not require installing local background daemons, running bridge processes, or maintaining complex desktop configurations.
Step-by-Step: Connecting Google Drive to ChatGPT Without Context Bloat
Connecting Google Drive folders to ChatGPT with targeted semantic retrieval requires four steps:
- Sync Drive folders to Fast.io: In your Fast.io organization, configure Cloud Sync to connect your Google Drive folder to a shared workspace on a schedule or on demand.
- Enable Intelligence Mode: Turn on Intelligence Mode on the workspace to automatically generate vector embeddings and index incoming files for hybrid search.
- Install the Fastio plugin in ChatGPT: Open the ChatGPT plugin directory at chatgpt.com/plugins, locate Fastio, select Install plugin, and complete OAuth authorization.
- Query documents in chat: Mention
@Fastioin any ChatGPT conversation to retrieve concise, citation-backed excerpts without saturating prompt context limits.
Installing the Fastio Plugin in ChatGPT (Preferred)
Fast.io is listed in the ChatGPT plugin directory. Connecting ChatGPT takes a few clicks:
- Open the plugin directory at chatgpt.com/plugins.
- Find Fastio in the directory.
- Select Install plugin.
- Sign in to Fastio when prompted.
- In your chat conversation, mention
@Fastioto query your workspace documents.
Connecting ChatGPT via a Custom MCP Server (Alternative)
If your team uses an enterprise ChatGPT workspace where third-party plugins are managed, or if you prefer a direct developer connection, you can connect via a custom MCP server:
- In ChatGPT Settings, open Security and login and turn on Developer mode (availability depends on your workspace's administrative policy).
- Go to chatgpt.com/plugins and select the plus button to add a new server.
- Name the connection
Fastio. - Enter
https://mcp.fast.io/mcp/operationsas the MCP server URL. - Create the connection and complete the OAuth sign-in flow in the browser window that opens.
During OAuth sign-in, you review permissions on screen, selecting Read Only or Read & Write, and specifying exactly which organizations and workspaces the connection can reach. To disconnect later, remove the connector in ChatGPT, then in Fastio open Settings, select Devices & Agents, navigate to Connected Devices, and select Revoke.
Standardized MCP Client Routing
Fast.io serves dedicated MCP endpoints tailored to different client architectures:
- ChatGPT and Codex Custom Servers: Connect to
https://mcp.fast.io/mcp/operations. - Claude Apps and General MCP Clients: Connect to
https://mcp.fast.io/mcp/tools. - Coding Agents (Claude Code, Cursor, VS Code, Cline): Connect to
https://mcp.fast.io/mcp/code.
Consult the setup guide at https://mcp.fast.io/docs for step-by-step instructions across platforms, and review https://mcp.fast.io/skill.md for tool definitions and parameter specifications.
How Semantic Retrieval and Metadata Views Eliminate Context Saturation
Connecting ChatGPT to an indexed Fast.io workspace changes how files are presented to the model. Fast.io Intelligence Mode indexes Google Drive files upon sync for sub-second excerpt retrieval. Instead of reading an entire document into the prompt, ChatGPT queries Fast.io for targeted information.
Sub-Second Semantic Retrieval in Action
When Intelligence Mode is enabled on a workspace, Fast.io automatically generates vector embeddings and extracts text from incoming files. It creates a hybrid search index combining full-text keyword matching, semantic meaning search, and metadata value filtering.
Consider a practical example. A team stores a comprehensive vendor compliance handbook in Google Drive. A user asks ChatGPT:
"What are the notification deadlines if a data incident occurs under our vendor terms?"
In a native direct-file integration, the chat app attempts to ingest the entire document, consuming tens of thousands of tokens in prompt overhead.
With the Fast.io plugin:
- ChatGPT receives the user prompt and issues a semantic search call to Fast.io over MCP.
- Fast.io searches the indexed workspace and identifies the exact two paragraphs in the handbook governing security incident notices.
- Fast.io returns those specific excerpts along with the document title and page citation.
- ChatGPT answers the question accurately using a focused excerpt of a few hundred tokens.
The prompt context remains lean and uncluttered, leaving almost the entire context window available for follow-up questions and complex reasoning.
Structured Document Extraction With Metadata Views
While Intelligence Mode handles conversational search and RAG, teams often need to turn unstructured files into organized tabular records. For this purpose, Fast.io provides Metadata Views.
Metadata Views turn documents into a live, queryable database. Users describe the fields they want extracted in natural language. AI designs a typed schema (Text, Integer, Decimal, Boolean, URL, JSON, Date & Time), matches files in the workspace, and populates a sortable, filterable spreadsheet grid.
This extraction works across PDFs, images, Word documents, spreadsheets, presentations, and scanned pages without rigid templates or manual OCR rules. Agents and ChatGPT can query these structured Metadata Views via MCP, retrieving specific fields like contract values, effective dates, or invoice totals without scanning raw document text.
The connector comparison is published at Fast.io Benchmarks and that page is the only place its numbers live.
How Multi-Agent Teams Govern Synced Drive Workspaces
A major advantage of centralizing cloud files in Fast.io is establishing a shared, neutral workspace for human teams and multiple AI agents. Rather than siloing files inside individual chat sessions, Fast.io creates an organization-owned space where ChatGPT, Claude Code, Cursor, Codex, and OpenClaw can collaborate.
Concurrency and Per-File Version History
When autonomous agents read and write files simultaneously, file collisions can occur if storage is unmanaged. Fast.io solves concurrency with automatic per-file version history.
Every edit, overwrite, or agent update creates a distinct version in the file's history. If an agent produces an unexpected change or misinterprets data, team members can review the change history and restore any prior version with a single click.
For active write coordination, Fast.io provides file locks. A file lock is an advisory per-file lease in workspace or share storage, acquired through MCP actions (lock-acquire and lock-release on storage_manage, lock-status on storage). A lock expires unless it is heartbeated by the holder. It informs other agents and teammates who is working on a file without blocking concurrent writes, and version history preserves every version that lands.
Role-Based Permissions and Change Auditing
Fast.io permissions are configured at the organization, workspace, and share levels through member roles; every workspace member reaches the workspace contents according to their role. When you need to give someone access to only a single folder or a specific set of files, you create a branded share (Send, Receive, or Exchange) that provides scoped access without granting visibility into the broader workspace.
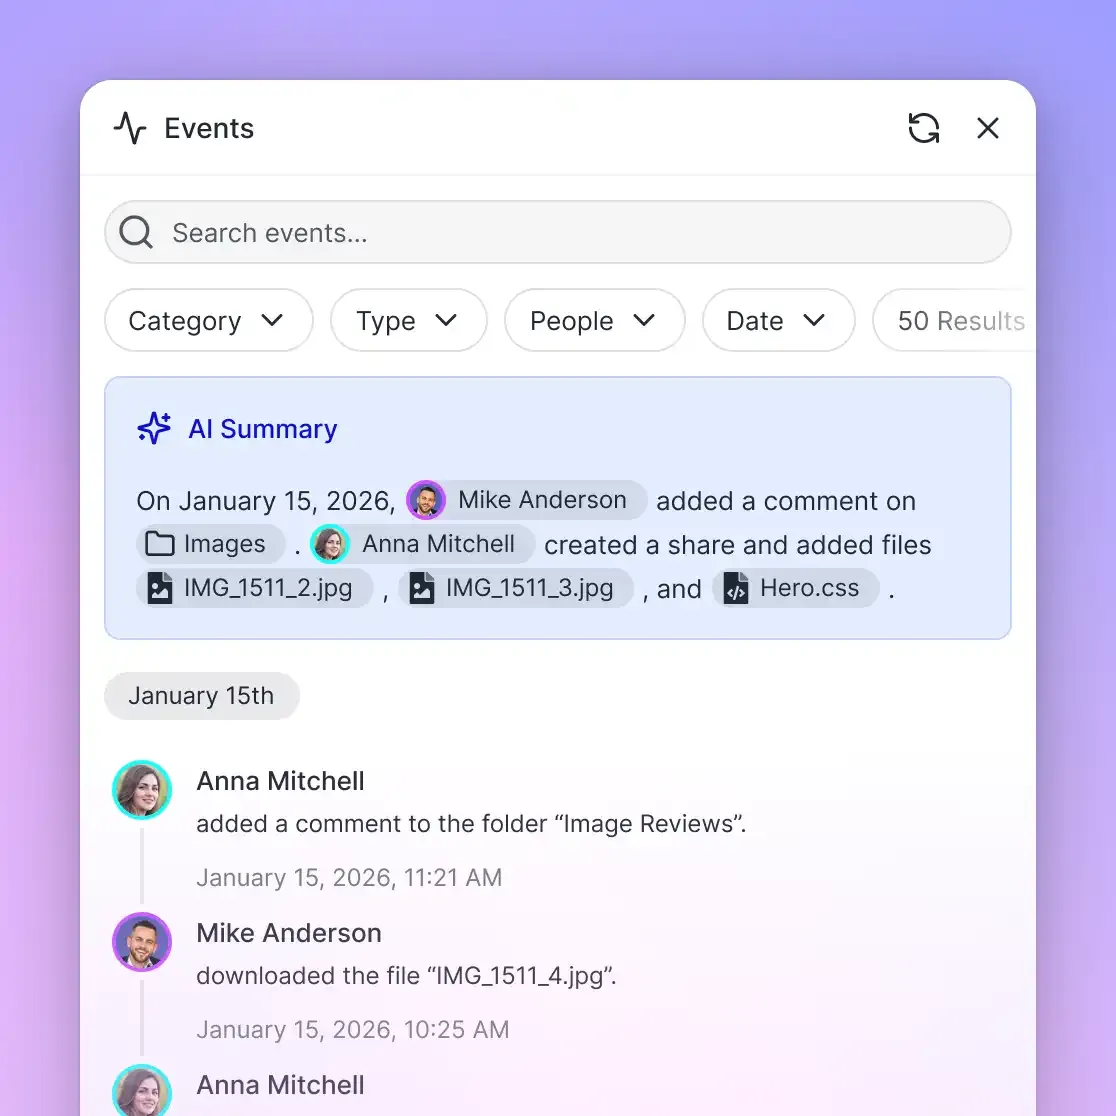
Workspace modifications are tracked in a detailed activity log of changes. The activity log records file uploads, edits, moves, deletions, membership updates, role changes, and share creations. This record provides administrators with full visibility into which human or agent modified project files and when changes occurred.
Transparent Pricing and Team Plans
Fast.io operates on predictable subscription tiers designed for teams and agentic workloads. Monthly plans start with a 14-day free trial, which requires a credit card. Plan tiers include:
Credits meter AI operations such as semantic indexing and metadata extraction, while storage, bandwidth, and seats are included with each plan. Check the Fast.io pricing page for complete plan specifications.
Sources
References used to verify factual claims in this guide.
-
Google Drive API limits are measured in quota units representing resource usage and return user rate limit errors when exceeded.
Frequently Asked Questions
Does ChatGPT have a Google Drive plugin?
Yes. ChatGPT provides a native Google Drive connector in its connected apps directory, and Fast.io provides a remote ChatGPT plugin that connects Google Drive folders via Model Context Protocol. While the native connector attaches individual files directly to prompts, the Fast.io plugin queries indexed workspace files using targeted semantic retrieval, preventing context window saturation.
How do I link Google Drive to ChatGPT?
To link Google Drive directly, open ChatGPT Settings, select Connected Apps, find Google Drive, and sign in with Google OAuth. To link Google Drive without context bloat across large folders, sync your Drive folders into a Fast.io workspace using Cloud Sync, install the Fastio plugin from chatgpt.com/plugins, and reference your workspace using @Fastio in any chat prompt.
Why does ChatGPT run out of memory when reading Google Drive files?
ChatGPT runs out of memory or forgets earlier conversation turns because native file integrations stream entire document bodies into the prompt context window. When files contain dozens of pages or thousands of spreadsheet rows, raw text quickly exhausts available context tokens. Using an indexed semantic retrieval plugin passes only relevant excerpts to the prompt, keeping token usage minimal.
Does Fast.io sync with Google Drive?
Yes. Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. Files sync server-to-server, preserving folder hierarchies and document formatting without requiring local downloads or consuming local disk space.
How does remote MCP prevent prompt context bloat?
The Model Context Protocol connects ChatGPT to Fast.io's remote server at `https://mcp.fast.io/mcp/operations`. Instead of injecting an entire document into the prompt, ChatGPT sends a targeted search query. Fast.io performs hybrid semantic search and returns only the most relevant excerpts with page citations, keeping context consumption under a few hundred tokens.
Can multiple AI agents access the same synced Google Drive files?
Yes. Fast.io workspaces serve as a shared neutral ground where ChatGPT, Claude Code, Cursor, Codex, and other agents collaborate. Every agent accesses the same indexed files through client-specific MCP endpoints, with per-file version history tracking every modification and preventing file collisions.
Related Resources

Query Google Drive in ChatGPT Without Context Saturation
Sync your Drive folders into an intelligent Fast.io workspace and connect ChatGPT via remote MCP. Keep prompts lean with targeted semantic search on a 14-day trial.