AWS Bedrock Context Window: Token Limits, Model Capacities, and Memory Architecture
The AWS Bedrock context window defines the maximum sequence of input and output tokens a hosted foundation model evaluates in a single session. While standard Claude models support 200,000 tokens and preview models reach 1,000,000 tokens, sending massive files directly into API calls inflates latency and costs. Decoupling file storage through external indexing lets models query concise excerpts dynamically.

Understanding AWS Bedrock Context Window Limits Across Foundation Models
The AWS Bedrock context window is the maximum sequence length of input and output tokens that a hosted foundation model can evaluate within a single invocation session. In Amazon Bedrock, model context windows vary across foundation model providers, ranging from 8,000 tokens on legacy architectures to 200,000 tokens on Anthropic Claude 3.5 Sonnet, with preview configurations expanding to 1,000,000 tokens on Claude Sonnet 4. While an expanded context window accommodates extensive instructions and conversation history, repeatedly loading multi-megabyte files into raw Bedrock API invocations multiplies token consumption and drives up operational expenses.
Engineers deploying generative AI applications often assume that a large context window eliminates the need for external data architecture. In practice, the context window defines an ephemeral compute canvas, not a persistent storage repository. Every token submitted in a prompt must be processed by the model's self-attention mechanism during the prefill phase, consuming GPU compute and drawing down account-level throughput allowances. Understanding the exact context limits across Bedrock foundation models is the foundation for architecting cost-effective and responsive agent workflows.
The table above illustrates the variance in token capacities across major model families supported on Amazon Bedrock. While models like Claude Sonnet 4 offer up to 1,000,000 tokens in preview, standard production deployments operate predominantly within 128,000 to 200,000 token boundaries. Aligning your application architecture with these boundaries ensures consistent throughput across AWS regions.
Input Tokens versus Output Limits in Bedrock API Invocations
A common misconception among developers using Amazon Bedrock is treating the context window as a uniform ceiling for both input prompts and generated responses. In the Bedrock runtime data plane, foundation models enforce separate limits for input tokens and output tokens.
The input token limit represents the maximum sequence of tokens supplied in the prompt payload, including system prompts, chat history, document text, and tool definitions. In contrast, the maximum output tokens parameter controls the length of the generated completion. For example, Claude 3.5 Sonnet supports an input context window of 200,000 tokens but caps standard output generation at 8,192 tokens. Attempting to set the max_tokens request parameter above the model's supported output ceiling results in an immediate validation error from the Bedrock API.
Furthermore, Amazon Bedrock enforces an upfront token reservation mechanic during API invocations. When an application initiates a call to InvokeModel or Converse, Bedrock evaluates regional Tokens Per Minute (TPM) limits by temporarily reserving quota capacity equal to the input prompt length plus the requested max_tokens parameter. If a client application submits a prompt of 150,000 tokens and leaves max_tokens set to a high default ceiling, Bedrock reserves that entire combined quantity against your account quota for the duration of the request. If multiple worker threads execute in parallel, this reservation behavior can trigger unexpected throttling exceptions even when the model ultimately generates only a brief response.
Context Limits Across Regional Endpoints and Inference Profiles
Amazon Bedrock distributes foundation model capacity across AWS regions using regional endpoints and cross-region inference profiles. Context window limits remain consistent across deployment methods, but throughput quotas and feature availability vary significantly.
Regional endpoints process requests within a specific AWS data center, such as us-east-1 (N. Virginia) or us-west-2 (Oregon). In single-region deployments, your application shares token buckets and request quotas exclusively with other workloads in that specific region. When regional demand surges, on-demand invocations may experience higher latency or capacity constraints.
To mitigate regional capacity bottlenecks, Amazon Bedrock provides cross-region inference profiles. Cross-region routing dynamically distributes incoming inference traffic across multiple AWS regions within a geographic zone, such as across Virginia, Ohio, and Oregon. While cross-region inference profiles improve availability and reduce throttling for standard 200,000-token Claude invocations, extended context configurations like the 1,000,000-token Claude Sonnet preview are initially restricted to specific regional clusters where specialized GPU infrastructure is deployed. System architects must verify regional availability in the Amazon Bedrock console before designing production pipelines that depend on extended context models.
Related guides
- GPT-4o Context Window: Token Limits, Architecture, and MCP SearchThe GPT-4o context window is 128,000 tokens, supporting up to 16,384 completion tokens per API request. While 128,000...
- Gemini 2.0 Flash Context Window: 1M Architecture and RAG Best PracticesThe Gemini 2.0 Flash context window spans 1,048,576 input tokens and an 8,192-token output ceiling. While ingesting...
- Groq Context Window: LPU Token Limits, Model Capacities, and Workspace IndexingGroq context windows specify the maximum total tokens that Language Processing Units can process in a single inference...
- Google Gemini Context Window: Token Limits, Architecture, and Handling Large FilesThe Google Gemini context window spans 1,048,576 input tokens and 65,536 output tokens on current Gemini 3 models such...
- Grok Context Window: Token Limits, Architecture, and Large File HandlingThe Grok context window spans from 256,000 tokens on grok-build-0.1 up to 1,000,000 tokens on Grok 4.3 and the Grok...
- Qwen Context Window: Model Specifications, Memory Limits, and MCP RetrievalThe Qwen context window is the total sequence capacity of tokens that Alibaba's Qwen models can ingest and generate in...
More on this subject: Agent Memory and Storage (209 guides)
How Context Window Size Impacts Amazon Bedrock Pricing and Latency
Expanding the prompt context to ingest complete documents, technical specifications, or codebase repositories directly affects operational expenditure and runtime latency. While frontier models are technically capable of evaluating hundreds of thousands of tokens, the economic and computational cost scales with prompt size.
In Amazon Bedrock, model billing is calculated per 1,000 tokens (or per 1,000,000 tokens) processed. For standard model invocations, input tokens and output tokens carry distinct price points. When prompts exceed standard thresholds, cloud providers apply tiered pricing structures to account for the heavy memory footprints required to hold attention states in GPU memory. Passing multi-megabyte payloads in raw Bedrock API invocations rapidly multiplies infrastructure costs, particularly when autonomous agents execute multi-turn iterative loops where the same background context is re-submitted on every turn.
Beyond direct financial costs, large context payloads impose substantial latency overhead. Understanding the relationship between context length, Time-To-First-Token (TTFT), and attention accuracy is critical for building responsive applications.
Pricing Tiers for Extended Context Windows
Amazon Bedrock applies differential pricing tiers based on model family, token volume, and context thresholds. Standard Claude Sonnet invocations within the baseline 200,000-token window are priced at standard base rates for input and output. However, for expanded context models supporting 1,000,000 tokens, AWS introduces tiered pricing once prompt size crosses the 200,000-token boundary.
When an invocation exceeds 200,000 tokens in the Claude Sonnet expanded preview, input tokens above that threshold incur approximately twice the standard token price, and output tokens carry an elevated pricing rate for long-context generation. For an autonomous agent that submits an 800,000-token repository analysis across ten conversational turns, the cumulative cost accumulates rapidly:
- Base Input Costs: The first 200,000 tokens of each invocation are billed at standard rates across all turns.
- Extended Tier Ingestion: The remaining 600,000 input tokens in each call are billed at the doubled extended rate.
- Multi-Turn Compounding: Over ten turns of agent reasoning, the agent re-submits the static 800,000-token payload repeatedly, resulting in 8,000,000 billable input tokens for a single analytical task.
Without architectural intervention, continuous long-context prompting turns manageable background research tasks into major cost centers. Decoupling static document archives from active prompt memory avoids this compounding cost penalty.
Latency and Prefill Compute Overhead in Large Prompts
In transformer-based architectures, inference execution consists of two distinct phases: prompt prefill and token generation. During the prefill phase, the model processes the entire input sequence simultaneously, constructing key-value (KV) caches across all attention layers. The computational complexity of self-attention scales quadratically with sequence length unless optimized with sparse or linear attention variants.
When an application sends a 180,000-token document payload to Amazon Bedrock, the service must ingest and compute attention across that entire corpus before generating a single output token. This produces a measurable increase in Time-To-First-Token (TTFT). For interactive user-facing chat applications, a TTFT of twelve to twenty seconds creates a sluggish and unresponsive user experience.
In addition to latency overhead, researchers have documented the phenomenon known as attention dilution or the 'lost in the middle' effect. Even when a foundation model demonstrates high retrieval accuracy on synthetic needle-in-a-haystack benchmarks, real-world analytical accuracy degrades when critical constraints or conflicting facts are embedded in hundreds of pages of unindexed text. Foundation models exhibit stronger recall for facts placed at the very beginning or end of the context window, while subtle details located in the central third of a massive prompt are more easily overlooked.
The Context Stuffing Trap: Why Massive In-Prompt Payloads Fail
Documented Claude mechanics, outlined in Anthropic's help page on uploading files to Claude, state that a standard chat accepts up to 20 files at up to 500MB each, while a project accepts files up to 30MB each, and its file count is unlimited, but the total content must fit within Claude's context window. Claude Projects enforces no fixed file-count cap, meaning that the true operational ceiling of any project or agent session is determined strictly by how quickly attached documents consume the model context window.
When development teams migrate from consumer AI interfaces to programmatic infrastructure on AWS Bedrock, they frequently attempt to replicate this file attachment pattern by stuffing entire documents directly into the API request payload. However, Amazon Bedrock provides no native file system abstraction or persistent document store in raw runtime calls. Every attached file must be converted to text or serialized into JSON payloads sent over HTTP.
Attempting to pass complete manuals, legal binders, or codebase repositories directly into Bedrock API prompts creates severe operational bottlenecks that disrupt production deployments.
Upfront Token Reservations and ThrottlingException Failures
Amazon Bedrock enforces regional service quotas measured in Requests Per Minute (RPM) and Tokens Per Minute (TPM) across foundation models. These quotas protect cloud infrastructure and ensure fair resource distribution across AWS accounts.
When an application adopts a context stuffing pattern, it rapidly exhausts regional TPM allocations. Consider an internal enterprise assistant deployed for twenty team members. If five users simultaneously ask questions that require analyzing a 100,000-token compliance manual, those five concurrent requests transmit 500,000 input tokens within a few seconds. If the account's regional TPM quota for that model family is set to 250,000 tokens per minute, Bedrock immediately denies excess calls with an HTTP 429 status code and a ThrottlingException.
Because Bedrock implements the upfront token reservation mechanic, the problem compounds when worker threads specify generous max_tokens ceilings. The service locks the combined input and output capacity upfront, rejecting subsequent requests from unrelated services sharing the same AWS account in that region. Handling this failure mode with client-side retries and exponential backoff helps smooth transient spikes, but it cannot resolve the underlying architectural defect of transmitting oversized payloads across an inference channel.
Attention Dilution and Loss of Reasoning Headroom
Beyond quota exhaustion and API throttling, context stuffing introduces cognitive degradation in autonomous AI agents. An agent operating within a saturated context window suffers from reduced reasoning headroom and context fragmentation.
When reference knowledge consumes 170,000 tokens of a 200,000-token context window, the agent is left with only 30,000 tokens to manage system prompts, tool schemas, multi-turn dialogue, tool execution responses, and final generation. If the agent needs to call external APIs, parse structured outputs, or engage in multi-step problem solving, the cumulative conversation state quickly collides with the 200,000-token hard ceiling.
When an agent hits the context boundary mid-task, execution terminates abruptly with a ValidationException or context truncation error. In multi-agent systems where one agent hands off intermediate artifacts to another, stuffing unparsed files into conversational state ensures that downstream workers receive noisy, unfiltered text rather than precise, actionable facts. Keeping prompt contexts compact and focused is essential for maintaining reasoning precision across multi-step tasks.
Scale Agent Memory Without Exhausting Bedrock Context Windows
Store large document archives in persistent Fast.io workspaces. Index files automatically and let your agents retrieve targeted context over remote MCP instead of burning expensive tokens on raw file payloads. Every organization starts with a 14-day free trial, which requires a credit card.
Decoupling File Storage from Context Windows Using External Workspaces
When enterprise documentation, customer archives, or codebases exceed what can safely and economically live inside a foundation model's context window, engineering teams must decouple document storage from the inference layer. Rather than forcing models to carry complete reference libraries inside active prompt memory, modern architectures implement an external storage and indexing tier that supplies relevant excerpts on demand.
Engineering teams typically evaluate several approaches for managing large file collections:
- Local Filesystem Storage: Storing files on local disk is simple for single-developer prototypes, but it fails in production. Local files cannot be accessed by distributed agents running across cloud containers, Lambda functions, or developer machines, and local environments lack unified search and versioning.
- Amazon S3: Object storage provides virtually unlimited durability and scale. However, S3 is a raw storage layer. To make S3 documents useful to Bedrock models, engineering teams must build and maintain custom text extraction pipelines, chunking services, vector embedding generation, and vector databases like OpenSearch Serverless, adding substantial operational maintenance.
- Traditional Cloud Drives: Synchronized consumer drives like Google Drive, Box, Dropbox, and OneDrive excel at human file sharing, but their APIs are optimized for desktop synchronization rather than high-concurrency agent tool calls. Passing heavy API traffic through standard consumer sync connectors frequently triggers strict third-party rate limits.
Fast.io provides a purpose-built workspace platform designed specifically for agentic teams and human collaborators. Rather than forcing agents to carry entire file libraries within their prompt context, Fast.io workspaces serve as a persistent, organized environment where documents are stored, indexed, and queried dynamically.
With Fast.io Intelligence Mode enabled on a workspace, incoming documents, including PDFs, office files, presentations, spreadsheets, code files, scanned pages, and images, are automatically parsed and indexed for hybrid search. Fast.io hybrid search combines semantic vector understanding with exact full-text keyword matching and structured metadata values. Files become instantly searchable without requiring developers to configure an external vector database or write embedding ingestion scripts.
AI assistants and Bedrock-powered agents connect to Fast.io workspaces through a remote Model Context Protocol (MCP) server hosted at https://mcp.fast.io/mcp (accessible through the Fast.io MCP server, or https://mcp.fast.io/mcp/key for persistent Bearer token authentication). Instead of attaching 50 files to an API prompt, the agent uses MCP search tools to locate exact, relevant passages across indexed workspace documents, pulling only 2,000 to 4,000 tokens of precise context into the active Bedrock prompt.
This decoupled architecture preserves over 190,000 tokens of Bedrock's context window for multi-turn problem solving, code generation, and extended reasoning. In addition, Fast.io workspaces provide per-file version history, granular access permissions across organizations and folders, an append-only audit log, and direct ownership transfer so agents can prepare complete workspaces and hand administrative control to human colleagues.
Every organization starts with a 14-day free trial, which requires a credit card, detailed on the Fast.io pricing page. Fast.io subscriptions are organized into three tiers:
Architecting a Tiered Memory Hierarchy for Bedrock Agents
A resilient agent architecture separates memory into three functional tiers:
- Ephemeral Working Memory: The immediate Bedrock prompt context, reserved for current task instructions, active user dialogue, tool parameter schemas, and current reasoning traces. This layer remains lean, typically between 4,000 and 15,000 tokens.
- Dynamic Short-Term Memory: Cached conversational summaries and active scratchpads stored in Collaborative Notes or temporary session state, tracking progress across multi-turn agent iterations.
- Persistent Long-Term Memory: The indexed workspace corpus in Fast.io, housing complete historical documents, technical manuals, policy guidelines, and data assets.
Under this tiered architecture, the Bedrock foundation model never ingests raw documentation wholesale. When a user asks a complex question, the model evaluates its working memory, formulates a targeted search query, and queries the long-term memory layer via MCP. The external workspace returns structured, citation-backed snippets that populate the model's working memory with only the facts needed for that specific generation step.
Implementing Fast.io Workspace Indexing with Remote MCP
Integrating Fast.io workspace indexing with Amazon Bedrock requires no complex data pipeline engineering. When documents arrive in a workspace, Fast.io's Intelligence engine handles document parsing, optical character recognition (OCR) on scanned pages, chunking, and embedding generation automatically in the background.
For structured extraction workflows, Fast.io provides Metadata Views. Metadata Views turn unstructured documents into live, queryable databases by extracting typed fields such as contract dates, counterparties, totals, and policy numbers based on natural language instructions. Agents can query both unstructured semantic content and structured metadata fields through the consolidated MCP toolset.
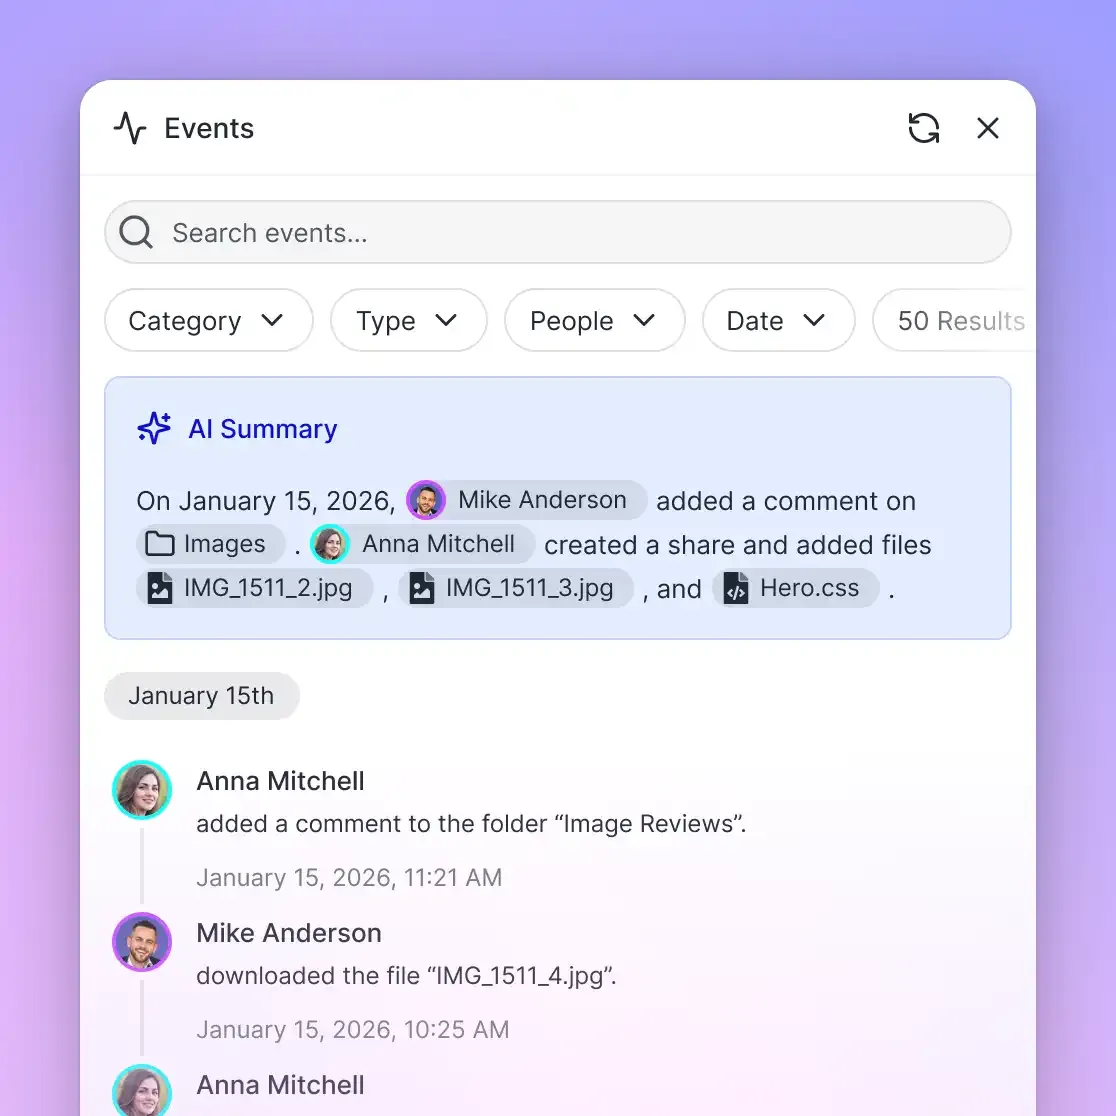
When team members update files or add new reference materials, Fast.io maintains per-file version history and updates the search index automatically. Autonomous agents reading from the workspace always retrieve current information, while human team members can inspect the append-only audit log to verify which files the agent accessed and modified during execution.
Step-by-Step Implementation: Querying Indexed Files with Bedrock and MCP
Implementing external workspace retrieval with Amazon Bedrock involves connecting your agent application to the remote Fast.io MCP server, exposing workspace search tools to the Bedrock Converse API, and executing an agentic retrieval loop.
The Model Context Protocol establishes a standard interface for models to discover and execute external tools. By configuring your agent runtime to connect to https://mcp.fast.io/mcp/key, the agent receives tool schemas for searching workspaces, fetching file metadata, and reading specific document passages.
When an end-user submits a question that requires domain knowledge, Bedrock evaluates the incoming prompt against the available tool definitions. Rather than answering from outdated parametric weights or complaining about missing context, the model generates a structured tool call requesting relevant document excerpts from Fast.io.
Configuring Bedrock Tool Calling with Remote MCP Endpoints
To connect an autonomous agent or application runner to Fast.io workspaces, developers configure the remote MCP endpoint in their client configuration.
The following JSON configuration establishes a connection to Fast.io using Bearer token authentication:
{
  "mcpServers": {
    "fastio": {
      "url": "https://mcp.fast.io/mcp/key",
      "headers": {
        "Authorization": "Bearer YOUR_FASTIO_API_KEY"
      }
    }
  }
}
Once authenticated, your agent framework discovers the consolidated Fast.io storage tool, which takes an action parameter selecting the operation to run, including search for hybrid retrieval, list for folder enumeration and details for file metadata. The agent registers that tool with Amazon Bedrock using the converse API.
The following Python script demonstrates how to configure the AWS SDK to invoke Amazon Bedrock Claude 3.5 Sonnet with a Fast.io workspace search tool:
import json
import boto3
import requests

# initialize bedrock runtime client
bedrock = boto3.client("bedrock-runtime", region_name="us-east-1")
model_id = "anthropic.claude-3-5-sonnet-20241022-v2:0"

# define tool specification for bedrock converse API
tools = [
    {
        "toolSpec": {
            "name": "storage",
            "description": "Search indexed documents in a Fast.io workspace for relevant passages.",
            "inputSchema": {
                "json": {
                    "type": "object",
                    "properties": {
                        "action": {
                            "type": "string",
                            "description": "Storage action to run, such as search, list or details."
                        },
                        "query": {
                            "type": "string",
                            "description": "Semantic search query or keyword phrase."
                        }
                    },
                    "required": ["action", "query"]
                }
            }
        }
    }
]

messages = [
    {
        "role": "user",
        "content": [{"text": "What are our enterprise data retention requirements for financial audit logs?"}]
    }
]

# dispatch initial converse request
response = bedrock.converse(
    modelId=model_id,
    messages=messages,
    inferenceConfig={"maxTokens": 2048, "temperature": 0.2},
    toolConfig={"tools": tools}
)

output_message = response["output"]["message"]
messages.append(output_message)

# inspect if model requested a tool execution
stop_reason = response["stopReason"]
if stop_reason == "tool_use":
    for content_block in output_message["content"]:
        if "toolUse" in content_block:
            tool_use = content_block["toolUse"]
            tool_name = tool_use["name"]
            tool_input = tool_use["input"]
            tool_use_id = tool_use["toolUseId"]
            # call remote fast.io MCP search endpoint
            mcp_response = requests.post(
                "https://mcp.fast.io/mcp/key",
                headers={"Authorization": "Bearer YOUR_FASTIO_API_KEY"},
                json={
                    "jsonrpc": "2.0",
                    "id": 1,
                    "method": "tools/call",
                    "params": {
                        "name": "storage",
                        "arguments": {"action": "search", "query": tool_input["query"]}
                    }
                }
            ).json()
            # format tool result back to bedrock
            tool_result = mcp_response.get("result", {}).get("content", [{}])[0].get("text", "No documents found.")
            messages.append({
                "role": "user",
                "content": [
                    {
                        "toolResult": {
                            "toolUseId": tool_use_id,
                            "content": [{"text": tool_result}]
                        }
                    }
                ]
            })
    # complete conversation with grounded context
    final_response = bedrock.converse(
        modelId=model_id,
        messages=messages,
        inferenceConfig={"maxTokens": 2048, "temperature": 0.2}
    )
    final_text = final_response["output"]["message"]["content"][0]["text"]
    print("Grounded Response:", final_text)
In this implementation, the prompt context remains minimal during the initial request. When the model determines that it requires specific organizational knowledge, it executes the search tool against Fast.io, ingesting only the concise excerpt needed to answer the question accurately.
Operational Best Practices for High-Throughput Invocations
To maintain high availability and predictable costs across high-volume Bedrock deployments, engineering teams should follow several operational best practices:
- Calibrate Output Token Ceilings: Avoid leaving
max_tokensset to maximum ceilings like 64,000 on routine conversational tasks. Settingmax_tokensto realistic limits, such as 2,048 or 4,096 tokens, prevents Bedrock's upfront token reservation mechanic from locking excessive regional quota capacity. - Implement Exponential Backoff with Jitter: When operating near regional service quota limits, wrap Bedrock invocations in retry logic using randomized jitter. Decorrelated jitter spreads retry requests across time, preventing worker threads from synchronizing into thundering herds.
- Use Prompt Caching for Invariant Context: For static system prompts, detailed tool schemas, and core guidelines, enable prompt caching on supported Bedrock models. Caching static prompt prefixes reduces latency and cuts input token costs on subsequent invocations.
- Use Structured Metadata Filtering: When querying external workspaces, combine semantic search queries with metadata filters to narrow search scopes to specific document types, folders, or creation dates. Narrowing search parameters ensures the highest retrieval precision and minimizes irrelevant context tokens.
Sources
References used to verify factual claims in this guide.
-
Anthropic's Claude Sonnet context window in Amazon Bedrock expanded from 200,000 to 1 million tokens, representing a 5x expansion in public preview.
-
In Claude Projects, individual file count is unlimited, but total content must fit within Claude's context window.
Frequently Asked Questions
What is the context window for Claude on AWS Bedrock?
Anthropic Claude 3.5 Sonnet on AWS Bedrock supports a 200,000-token context window for input prompts with an 8,192-token output limit. In addition, Anthropic Claude Sonnet 4 offers an expanded context window of 1,000,000 tokens in public preview in selected AWS regions such as US West (Oregon) and US East (N. Virginia).
How do I increase the context length in Amazon Bedrock?
You cannot alter the hard architectural context window of a specific foundation model version. To evaluate longer token sequences, select a model version designed for extended context, such as Claude Sonnet 4 with 1,000,000-token preview support or Amazon Nova Pro with 300,000 tokens, or request quota adjustments in the AWS Service Quotas console for throughput velocity.
How does context window affect AWS Bedrock pricing?
Amazon Bedrock charges per token for prompt input and completion output. When using extended context models like Claude Sonnet with prompts exceeding 200,000 tokens, AWS applies tiered pricing where input tokens above 200,000 incur approximately twice the standard price and output tokens carry an elevated pricing rate.
What is the difference between max_tokens and context window in Bedrock?
The context window represents the total cumulative sequence of input and output tokens that a model can evaluate in one invocation session. In contrast, the max_tokens parameter specifies the maximum number of new tokens the model is permitted to generate in its response, which is capped by the model's documented output limit.
What causes ThrottlingException when using large context windows in Bedrock?
ThrottlingException occurs when an application exceeds regional Requests Per Minute (RPM) or Tokens Per Minute (TPM) service quotas. Because Bedrock reserves quota capacity upfront equal to input tokens plus the max_tokens parameter, large prompt payloads quickly deplete regional token velocity buckets.
How can AI agents access large document collections without exceeding Bedrock token limits?
Rather than stuffing raw files directly into API prompts, teams store document archives in an external workspace like Fast.io with Intelligence Mode enabled. Models connect via remote Model Context Protocol (MCP) tools to search indexed files dynamically, retrieving only the concise passages required to answer the query.
Related Resources
Scale Agent Memory Without Exhausting Bedrock Context Windows
Store large document archives in persistent Fast.io workspaces. Index files automatically and let your agents retrieve targeted context over remote MCP instead of burning expensive tokens on raw file payloads. Every organization starts with a 14-day free trial, which requires a credit card.