Connecting Semantic Kernel to Google Drive: Setup and Best Practices
A Semantic Kernel Google Drive connector bridges enterprise AI agents with cloud files stored across My Drive and Google Workspace shared drives. Teams can choose between implementing custom native API plugins or routing storage through persistent Fastio workspaces with built-in semantic search and remote MCP connectivity. This guide walks through authentication lifecycles, shared drive query traps, and practical indexing patterns for production agent deployments.

How to Configure a Semantic Kernel Google Drive Connector: Core Architecture
Connecting an autonomous AI agent to enterprise document repositories introduces an operational challenge that traditional cloud storage APIs were never built to solve. When a Semantic Kernel agent connects directly to the Google Drive REST API, developers immediately encounter three friction points: rigid sixty-minute OAuth token expiration windows, silent query failures across Google Workspace Shared Drives, and prompt context inflation caused by downloading raw binary files for simple factual lookups.
Cross-cloud agent architectures frequently require Microsoft-hosted agents to retrieve documents from Google Drive repositories. In enterprise software environments, development teams frequently deploy Microsoft-based agent stacks built on Semantic Kernel while organizational knowledge, spreadsheets, and project documentation reside in Google Drive and Google Workspace shared drives. Bridging these systems requires a dependable integration pattern.
A Semantic Kernel Google Drive connector is a tool plugin that allows Semantic Kernel AI agents to search and retrieve files stored in Google Drive and Google Workspace shared drives. Semantic Kernel plugins encapsulate APIs and native functions into collections that AI models can invoke through function calling. When an agent processes a user request, the language model inspects the plugin metadata, determines which native function to invoke, and formats the arguments. Semantic Kernel marshals the call, executes the operation against the storage provider, and feeds the resulting context back into the conversation loop.
Developers addressing this integration typically choose between two architectural patterns:
- The direct native plugin pattern, where the developer writes custom C# or Python functions wrapping the Google Drive API v3 and handles authentication, paging, and parsing manually.
- The workspace coordination pattern, where Google Drive folders sync to a persistent Fastio workspace and the agent interacts with indexed documents through a remote Model Context Protocol (MCP) server.
Both patterns enable agents to read and search files, but they place very different maintenance burdens on the engineering team.
Related guides
- How to Connect Google Drive to ChatGPT: Setup and Agent WorkspacesConnecting Google Drive to ChatGPT allows the model to access, read, and reason about files stored in your cloud...
- How to Connect Microsoft AutoGen Agents to Google DriveAn AutoGen Google Drive connector registers retrieval functions with AutoGen agents so multi-agent group chats can...
- ChatGPT Google Drive Connector: Native Connected Apps vs. Fast.ioA ChatGPT Google Drive connector links OpenAI models to cloud document repositories, enabling conversational search,...
- ChatGPT Google Drive Plugin: Connecting Drive Files Without Context BloatConnecting Google Drive directly to ChatGPT often floods the prompt context window with raw text, causing token...
- Gemini Google Drive Extension: Workspace Setup vs. Dedicated MCP StorageThe Gemini Google Drive extension is a built-in Google Workspace integration that allows Google Gemini to reference and...
- Google Drive Semantic Search: How to Search Drive Documents by MeaningGoogle Drive semantic search is the capability to search across documents, spreadsheets, and presentations in Google...
More on this subject: Agent Integrations and APIs (192 guides)
How to Build Native Google Drive Plugins: OAuth, Scopes, and Shared Drives
The traditional route for connecting Semantic Kernel to Google Drive involves creating a custom native plugin class that calls the Google Drive API v3. In this approach, developers expose specific methods, such as searching files, reading file contents, and downloading exports, to the kernel using function annotations.
In C#, a native plugin wraps a Google Drive client service and exposes methods decorated with the KernelFunction and Description attributes. The LLM relies on these descriptions to select the right tool during planning.
using System;
using System.ComponentModel;
using System.Linq;
using Google.Apis.Drive.v3;
using Microsoft.SemanticKernel;

public class GoogleDrivePlugin
{
    private readonly DriveService _driveService;
    public GoogleDrivePlugin(DriveService driveService)
    {
        _driveService = driveService;
    }
    //
    [KernelFunction, Description("Searches Google Drive files matching a metadata query.")]
    public async Task<string> SearchFilesAsync(
        [Description("Query string for filtering files, such as name contains 'spec'")] string query)
    {
        var request = _driveService.Files.List();
        request.Q = query;
        request.Fields = "nextPageToken, files(id, name, mimeType, modifiedTime)";
        request.SupportsAllDrives = true;
        request.IncludeItemsFromAllDrives = true;
        request.Corpora = "allDrives";
        request.PageSize = 25;
        var response = await request.ExecuteAsync();
        if (response.Files == null || response.Files.Count == 0)
        {
            return "No matching files found in Google Drive.";
        }
        return string.Join(Environment.NewLine, response.Files.Select(f => $"{f.Name} (ID: {f.Id}, Type: {f.MimeType})"));
    }
}
While registering this plugin into the kernel builder is straightforward, production implementations routinely stumble across three subtle API traps:
1. OAuth Token Lifecycle and Background Refresh
Google OAuth access tokens expire after one hour. In interactive client applications, an expired token triggers a browser redirect or refresh prompt. In unattended background agents, worker services, or scheduled jobs, an expired token causes sudden HTTP 401 errors that abort the agent run.
To prevent outages, the plugin initialization pipeline must configure offline access by requesting the offline access type. The application must securely store the refresh token, catch authorization exceptions, and automatically exchange the refresh token for a fresh access token before making storage calls. Relying on short-lived user tokens without an automated token refresh loop is the primary cause of failure in custom agent storage connectors.
2. Google Workspace Shared Drive Query Scoping
By default, Google Drive API files.list calls search exclusively within the authenticated user's personal My Drive. When an organization stores documentation in Google Workspace Shared Drives (formerly Team Drives), standard API queries return empty results even when the agent account has full manager permissions.
To search Shared Drives, three distinct query parameters must be explicitly set on every request:
SupportsAllDrives = true: Signals to the API that the calling application supports shared drive organizational structures.IncludeItemsFromAllDrives = true: Instructs the search engine to include items residing inside shared drives in the returned list.Corpora = "allDrives": Expands the query scope across all shared drives the credential can access, alongside personal storage. Alternatively, targeting a specific shared drive requires settingCorpora = "drive"and supplying the correspondingDriveId.
Omitting any of these parameters produces silent retrieval failures, causing the agent to hallucinate that requested documents do not exist.
3. Incomplete Search Flags and Rate Limiting
When querying broad corporate corpora, the Google Drive API may return incompleteSearch: true in the response body if evaluation takes too long across massive shared directories. Custom plugins must inspect this flag and page through results using nextPageToken. Furthermore, Google Drive enforces per-user and per-project request quotas. When an agent recursively traverses deep directory trees to find nested assets, it rapidly depletes API quota limits.
Why Direct Document Retrieval Bottlenecks Agent Workflows
Finding a file by name is only the first step in an agent workflow. The primary reason developers connect Semantic Kernel to Google Drive is to allow the agent to read document contents and answer user questions. This is where direct API plugins encounter severe performance and architectural limits.
Substring Matching Versus Semantic Search
The Google Drive API search query parameter q supports basic metadata filtering and raw full-text substring matching. It does not perform semantic search, conceptual indexing, or vector similarity scoring.
If a user asks an agent, "What are our compliance obligations under the vendor security policy?", a direct Google Drive plugin cannot locate the relevant paragraph by concept. It can only search for exact words like "compliance" or "obligations" across filenames and body text. If the document uses terms like "regulatory standards" or "mandatory controls", the native search misses the file entirely.
The Payload Problem
When a direct plugin does locate a document, it must retrieve the content. Google Drive stores files in proprietary cloud formats (Google Docs, Sheets, Slides) or binary files (PDFs, Microsoft Office documents). To make this content readable to an LLM, the plugin must:
- Call
files.exportfor proprietary Google Workspace files orfiles.getwith media download for binary files. - Download the entire file payload over HTTP into agent memory.
- Parse raw PDF streams, extract text from presentation slides, or convert tabular spreadsheets into text strings.
- Pass the extracted text into the agent prompt context.
This workflow creates severe context window bloat. Injecting a sixty-page vendor agreement or a dense corporate financial model into an agent context window consumes dozens of tokens, slows response latency, and drastically increases LLM inference costs. More critically, flooding the prompt with raw text degrades model reasoning, causing the agent to miss critical details buried in irrelevant sections.
The Self-Hosted RAG Burden
To solve context bloat with a direct plugin, engineering teams are forced to build a full Retrieval-Augmented Generation (RAG) pipeline beside their Semantic Kernel host. This requires deploying and managing a vector database, writing document chunking workers, calculating text embeddings, and implementing custom synchronization logic to re-embed files whenever someone edits a Google Doc.
For most organizations, maintaining a secondary data pipeline just to make Google Drive files searchable by agents introduces unnecessary operational overhead.


Connect Semantic Kernel to Unified Workspace Storage
Give your Semantic Kernel agents persistent file storage, automatic semantic indexing, and remote MCP connectivity with a 14-day free trial on monthly plans (credit card required).
When to Use Workspace Architecture: Fastio Cloud Sync and Remote MCP
A more dependable approach decouples the storage repository from the agent retrieval engine. Instead of forcing Semantic Kernel to act as a custom Google Drive sync client and document parser, teams can maintain Google Drive as their primary human interface while syncing relevant project folders into a Fastio workspace.
Scheduled Folder Synchronization
Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. When configuring Cloud Sync for Google Drive, organizational folders sync into an isolated Fastio workspace at designated intervals. The integration handles OAuth authentication, Google Workspace Shared Drive permissions, and incremental file transfers automatically, without consuming agent execution cycles or custom token refresh scripts.
Built-In Intelligence and Hybrid Search
When files arrive in the workspace, Fastio Intelligence Mode automatically indexes documents for hybrid search, combining full-text keyword indexing, semantic vector search, and search-by-metadata-value without requiring external vector databases or embedding pipelines.
For structured document extraction, Fastio provides Metadata Views. Metadata Views turn unstructured documents into live, queryable tables. Users or agents describe the fields they want extracted in natural language, and the system designs a typed schema (Text, Integer, Decimal, Boolean, URL, JSON, Date & Time), matches workspace files, and extracts structured data from PDFs, scanned pages, spreadsheets, and presentations. Agents can query these structured views directly via MCP to retrieve precise data fields without loading full documents.
Connecting Semantic Kernel via Streamable HTTP MCP
Semantic Kernel agents connect to Fastio through the Model Context Protocol (MCP) using Streamable HTTP. Fastio hosts a remote MCP server, eliminating the need to install local daemon processes or custom API wrappers.
For general agent clients and application backends calling named tools, the connection endpoint is https://mcp.fast.io/mcp/tools. Coding agents connect through https://mcp.fast.io/mcp/code. Agents authenticate by providing a scoped workspace API key as a Bearer token in the connection header: Authorization: Bearer <FASTIO_API_KEY>. For detailed client configuration steps, consult the Fastio MCP documentation or the storage for agents guide.
Once connected, the agent calls the storage tool using the search action. Because files are pre-indexed by Intelligence Mode, the search action returns precise semantic excerpts backed by document citations. The agent receives only the paragraphs necessary to answer the question, preserving context window budget and improving response accuracy.
Measured Connector Performance
In third-party testing documented in the published connector benchmarks, Fastio was measured the fastest and the lowest cost of the providers tested. By shifting document parsing, vector indexing, and synchronization to the workspace layer, agents avoid downloading full files over rate-limited storage APIs.
Workspace Capacity and Plans
Fastio provides predictable capacity for team and agent workflows. Storage and member seats are bundled into monthly plans:
Monthly plans start with a 14-day free trial, which requires a credit card. Credits meter AI search and document extraction, while storage and seats come included with each subscription.
What Production Deployments Require: Permissions, Concurrency, and Audit Logs
Moving a Semantic Kernel storage connector from a local proof-of-concept into enterprise production requires strict controls around access scoping, multi-agent concurrency, and compliance visibility.
Enforce Scoped Workspace Boundaries
A common security flaw in custom Google Drive integrations is assigning the agent a broad service account with domain-wide delegation. If that credential leaks or if the agent falls victim to prompt injection, the agent can traverse sensitive directories across the entire organization.
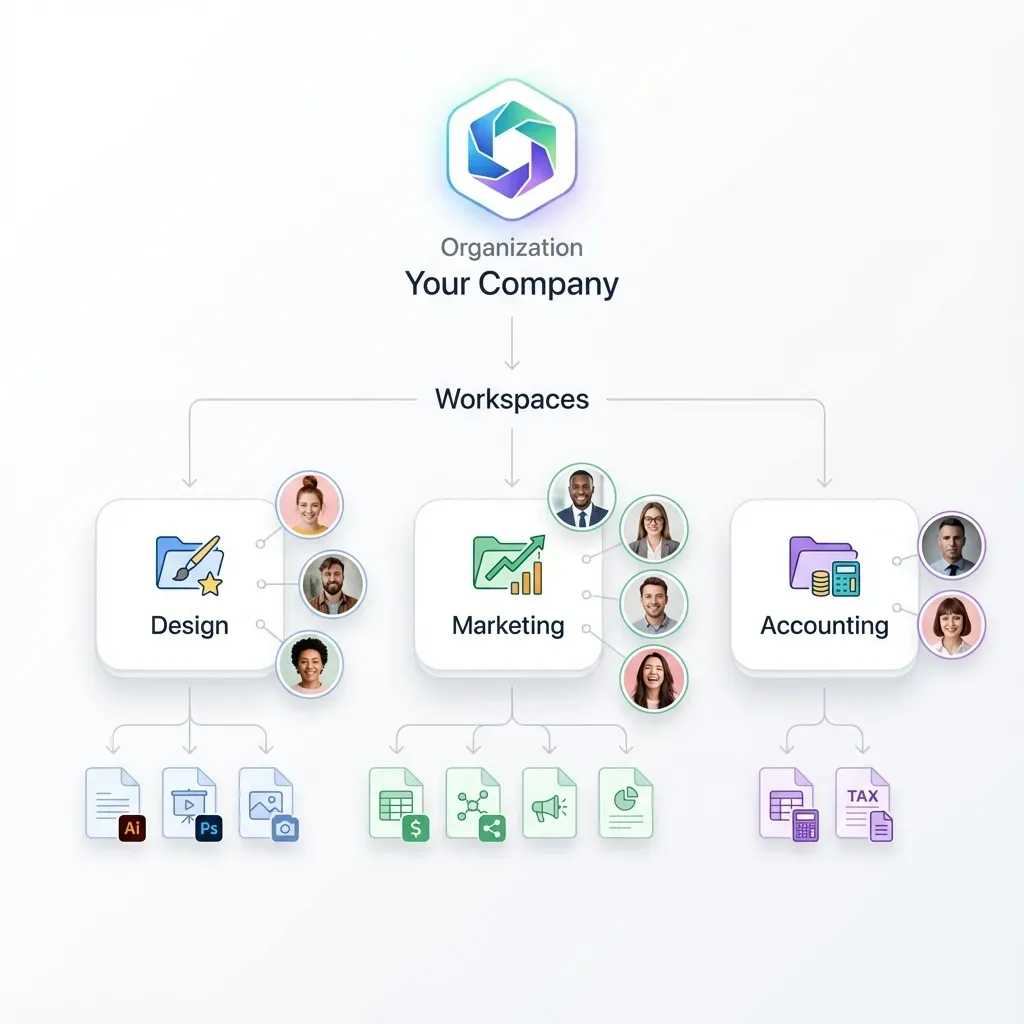
Fastio permissions are set per organization, workspace, and share through member roles. There are no folder-level or file-level permissions; every workspace member reaches the whole workspace according to their role. To isolate an agent, create a dedicated workspace containing only the specific project assets the agent requires, and sync only relevant Google Drive folders into that workspace. This sandboxes the agent, ensuring it cannot access or exfiltrate unrelated organizational data.
Concurrency and Per-File Version History
When multiple Semantic Kernel agents or human team members collaborate on the same file repository, race conditions occur. Two agents attempting to update a shared project log or analysis document simultaneously can cause silent overwrites.
Fastio protects concurrent workflows through per-file version history and advisory file locks. Agents acquire, heartbeat, and release advisory file leases through MCP actions (lock-acquire and lock-release on the storage_manage tool, and lock-status on the storage tool). If a lock expires or if concurrent writes occur, version history retains every iteration, allowing teams to review changes or restore prior copies without data loss.
Activity Tracking and Ownership Transfer
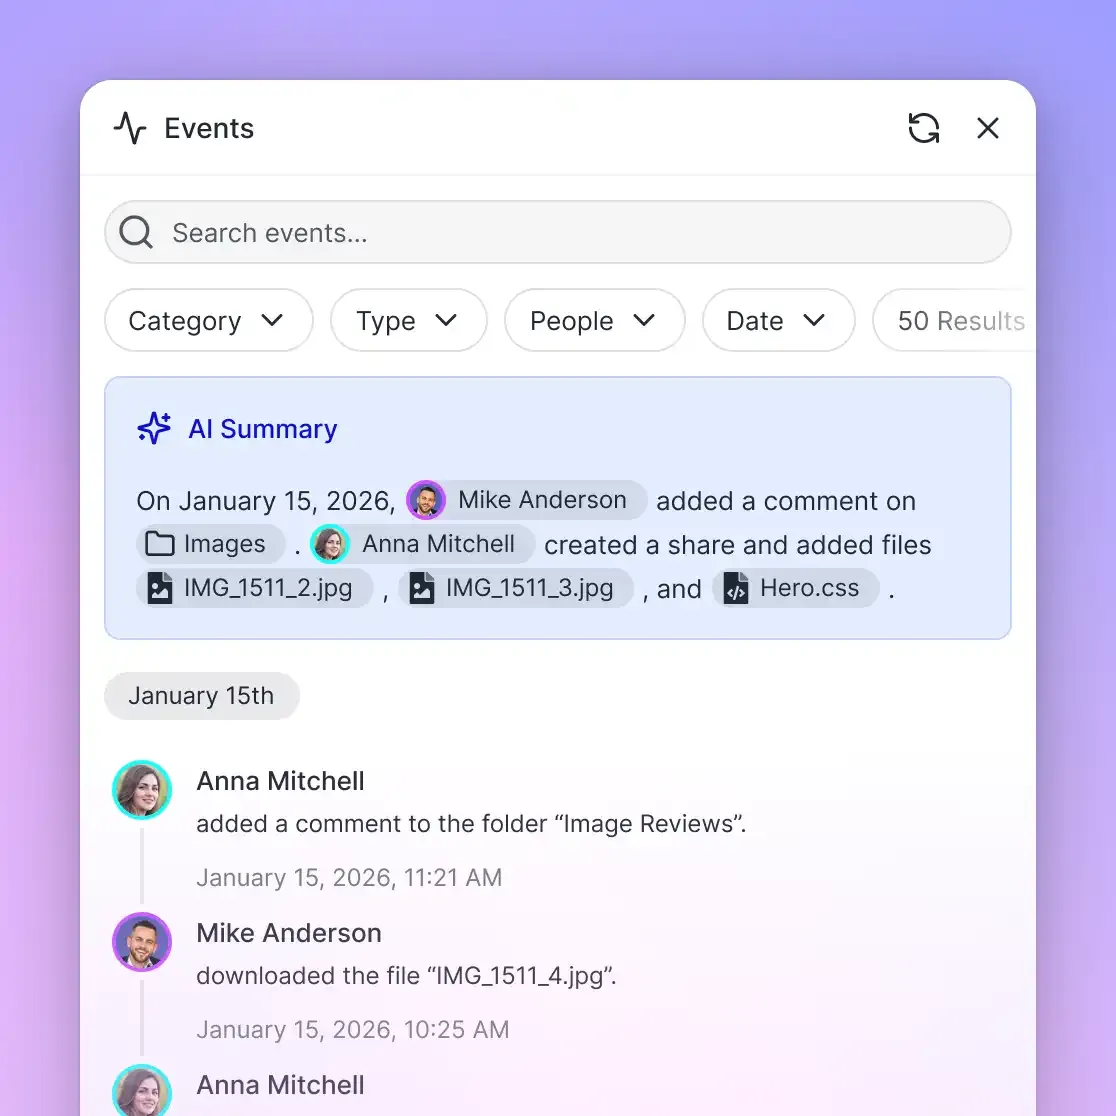
Enterprise security teams require visibility into agent modifications. Fastio maintains a detailed activity log of changes across the organization, recording file uploads, edits, moves, deletions, membership adjustments, and share creation by humans and agents alike. The activity log records modifications rather than read-only file views or downloads, providing a clean audit trail of workspace state changes.
Additionally, Fastio supports ownership transfer from agent to human. An agent can be programmed to initialize an organization, construct workspaces, sync Google Drive folders, and build Metadata Views, then transfer organization ownership to a human administrator while retaining administrative access for ongoing maintenance.
Choosing the Right Architecture
Use a direct native Google Drive plugin when building lightweight personal assistants that only need to look up simple file metadata in a user's own My Drive. When building enterprise agents that must search complex documentation across Google Workspace Shared Drives, answer detailed questions using semantic retrieval, or coordinate concurrent updates safely, routing storage through Fastio workspaces and the remote MCP server provides a more secure, scalable, and cost-effective foundation.
Sources
References used to verify factual claims in this guide.
-
Semantic Kernel plugins encapsulate APIs and native functions into collections that AI models can invoke through function calling.
Frequently Asked Questions
Can Semantic Kernel connect to Google Drive?
Yes. Semantic Kernel can connect to Google Drive through custom native API plugins wrapping the Google Drive API v3, or by using Cloud Sync to mirror Google Drive folders into a Fastio workspace accessible via a remote Model Context Protocol (MCP) server.
How do I build a Google Drive plugin for Semantic Kernel?
To build a native plugin, create a class with methods decorated with the KernelFunction and Description attributes, configure Google OAuth credentials with offline access to support token refresh, set supportsAllDrives and includeItemsFromAllDrives to true for shared drive access, and register the plugin with your kernel builder.
How do you securely share Google Drive files with enterprise AI agents?
Secure agent access by avoiding domain-wide service account delegation, isolating files into dedicated workspaces, scoping credentials to read-only roles when write access is unnecessary, and relying on advisory file locks and detailed activity logs to maintain auditable change records.
What causes Google Drive API searches to return empty results in Shared Drives?
Google Drive API files.list queries search only personal My Drive folders by default. Searching Google Workspace Shared Drives requires explicitly setting supportsAllDrives=true, includeItemsFromAllDrives=true, and setting corpora='allDrives' or specifying a driveId.
How does Fastio Cloud Sync differ from direct Google Drive API calls?
Direct API calls query Google Drive in real time and require the agent to download and parse full binary files. Fastio Cloud Sync syncs folders into a workspace on a schedule or on demand, where Intelligence Mode automatically pre-indexes documents for fast semantic search and structured metadata extraction via MCP.
Does Fast.io sync with Google Drive?
Yes. Cloud Sync connects Google Drive, Dropbox, Box and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand, allowing teams to preserve existing storage while giving AI agents unified MCP access.
Related Resources

Connect Semantic Kernel to Unified Workspace Storage
Give your Semantic Kernel agents persistent file storage, automatic semantic indexing, and remote MCP connectivity with a 14-day free trial on monthly plans (credit card required).