Grok Daily Limit: Reset Times, Quotas, and Managing Document Queries
Grok daily limit rules define how many prompts, image generations, and document analyses an account can complete before hitting a cooldown or reset. While free accounts face daily query caps and rolling 2-hour rate limits, paid subscriptions draw from a weekly compute pool. Offloading document corpora to an intelligent workspace preserves query quotas while maintaining deep contextual search.

How Grok Daily Limit Quotas Work: Free Tier Caps Versus Compute Pools
Free Grok users get roughly 20 messages per day, which refresh at midnight UTC, while official xAI documentation limits individual file attachments to 150 MB. For users analyzing multi-page documents, this message allotment frequently exhausts within minutes.
The Grok daily limit is the maximum number of queries, image generations, or document analyses an account can perform within a 24-hour cycle before access is restricted until reset.
Many online guides confuse the 2-hour rolling message limit with the 24-hour daily quota. In practice, xAI enforces two distinct gating mechanisms on free accounts:
- The 2-Hour Rolling Rate Limit: A short-term buffer designed to mitigate rapid-fire prompt submission and server cluster congestion. During periods of peak demand, a free account can encounter a temporary cooldown after sending roughly 10 messages within any 2-hour window. This pause prevents traffic spikes and automated scraping from degrading system availability.
- The 24-Hour Daily Quota: The cumulative daily ceiling that caps total interactions across the calendar day at approximately 20 messages. Once an account reaches this 24-hour ceiling, the interface blocks all new prompts until the scheduled daily reset.
Paid Compute Pools
Paid plans operate on a shared weekly compute pool rather than rigid, separate daily quotas for individual capabilities such as Chat, Voice, Imagine, or Build. This model applies across SuperGrok accounts and subscription tiers such as Plus, Premium, Super, and Ultra.
Under this compute pool model, different tasks draw down varying amounts of compute:
- Standard text chat messages consume minimal compute units.
- Deep reasoning queries using Think Mode, high-resolution image generations, and video processing draw down compute much faster.
- Multi-page document attachments force the model to evaluate thousands of context tokens on every follow-up question, rapidly depleting the account allowance.
Understanding how compute costs scale prevents unexpected lockouts during critical projects.
Related guides
- Perplexity Message Limit: Pro Search Quotas, Daily Caps, and WorkaroundsThe Perplexity message limit restricts Pro Search queries across Free and Pro tiers, while API endpoints enforce...
- ChatGPT Deep Research Limits: Plan Quotas, Reset Rules, and Workspace SolutionsChatGPT Deep Research limits restrict autonomous research tasks through plan-based quotas, rolling 30-day reset cycles,...
- ChatGPT Team Message Limits: Workspace Quotas, Resets, and Capacity PlanningThe ChatGPT Team message limit provides individual quotas within a shared organizational workspace, typically granting...
- DeepSeek Message Limit: Web Chat Quotas, Rate Limits, and WorkaroundsThe DeepSeek message limit is the dynamic ceiling on consecutive chat turns and daily queries enforced across DeepSeek...
- Perplexity Token Limits: Document Size, Query Caps, and Large Corpus WorkaroundsThe Perplexity token limit defines the maximum token capacity Perplexity can parse from attached documents (typically...
- Google Gemini Daily Limit: Free vs Advanced Quotas & API Reset TimesThe Gemini daily limit governs request velocity and compute allowances across Google consumer apps and developer APIs....
More on this subject: AI Agents: General Guides (190 guides)
When Does the Grok Limit Reset: Rolling Windows and Cooldown Cycles
Knowing exactly when a Grok limit resets allows teams to schedule heavy research and analysis sessions effectively. Reset behaviors differ between free accounts and paid subscription tiers.
Global Reset Clocks: Free Tier Midnight UTC Synchronization
For free accounts, the daily quota refreshes at 00:00 UTC (midnight Coordinated Universal Time). Because UTC does not observe daylight saving time, the local reset hour changes when regional clocks shift.
In North America, 00:00 UTC corresponds to:
- 5:00 PM PDT (or 4:00 PM PST) for users on the West Coast.
- 8:00 PM EDT (or 7:00 PM EST) for users on the East Coast.
In Europe and the United Kingdom, the daily quota clears during the early morning:
- 1:00 AM BST (or 12:00 AM GMT) in London.
- 2:00 AM CEST (or 1:00 AM CET) in Berlin and Paris.
In the Asia-Pacific region, resets occur during the working day:
- 9:00 AM JST in Tokyo.
- 11:00 AM AEDT in Sydney.
Free users planning intensive query sessions can schedule work immediately following their local UTC conversion time to access their full 24-hour allotment.
Paid Tier Weekly Refresh Cycles
For paid accounts on SuperGrok or The X Subscription, usage limits do not reset at midnight UTC. Instead, the usage pool refreshes on a rolling weekly schedule tied directly to the date and time of account activation or billing renewal.
Users can check their current quota status by opening Settings and selecting the Usage tab on web or mobile, or by checking the account dashboard at grok.com/dashboard. The dashboard displays:
- A progress bar showing the total percentage of the weekly pool consumed.
- A percentage breakdown categorized by product area (Chat, Voice, Imagine, Build, and API).
- The exact calendar date and timestamp for the next weekly reset.
- Any active Extra Usage Credits balance.
Rate Limiting Versus Quota Lockouts
Distinguishing between a rate limit and a quota lockout is straightforward:
- HTTP 429 (Too Many Requests): Occurs when messages are submitted too rapidly, exceeding limits such as one prompt per second on the free tier. Pausing for 10 to 30 seconds clears this error.
- Rolling 2-Hour Cooldown Banner: Displays a message indicating that capacity has been reached for the current window. This block clears automatically after the 2-hour window elapses.
- Daily or Weekly Quota Lockout: Displays an explicit notification that your account has reached its daily or weekly limit. On the free tier, queries pause until midnight UTC. On paid tiers, paid features pause until the weekly reset date, though users retain access to free-tier Chat and Voice allowances, which operate on their own independent schedules.
Grok Tier Comparison: Quotas, Resets, and File Support
The following table compares message limits, reset behaviors, and file handling rules across Grok subscription tiers:
For accounts on paid tiers, xAI does not publish a fixed, static message count. Because different tasks demand different compute levels, lightweight queries allow hundreds of interactions, whereas document analysis and media generation draw down the pool much faster.
Why Document Attachments Accelerate Grok Daily Limit Exhaustion
Grok limits individual document, image, code, and audio file attachments to 150 MB per file.
As documented in official xAI guidelines, users can attach up to approximately 100 files at once on the web application, up to 20 files on Android, and multiple files on iOS. Grok accepts common document formats including PDF, DOCX, TXT, CSV, XLSX, PPTX, HTML, XML, JSON, Markdown, LaTeX, and standard code files (.py, .cpp, .java).
The Hidden Penalty: Context Re-Ingestion
While Grok allows large document attachments, loading raw files directly into chat threads introduces an architectural penalty: context window re-ingestion.
In a standard chat interface, every follow-up question re-submits the entire conversation history, including all attached document text, back into the model context window.
Consider a practical example where a researcher analyzes a 90-page regulatory report:
- Turn 1: The user uploads the 90-page document and asks for an executive summary. Grok ingests the full document text (roughly 45,000 tokens) and generates the summary.
- Turn 2: The user asks a follow-up question regarding section four compliance dates. Grok re-evaluates the prompt, the previous summary, and the entire 90-page document text.
- Turn 3: The user asks about financial penalty clauses. Grok re-evaluates the prompt history, prior answers, and the entire document text a third time.
- Turn 5: By the fifth turn, the session has re-evaluated the full document text multiple times, processing hundreds of thousands of cumulative context tokens across repeated passes over identical source material.
How Document Queries Exhaust Daily Quotas
This repetitive context processing directly drives quota exhaustion:
- Free Tier Lockouts: Because free tier limits account for both message counts and backend compute overhead, submitting token-heavy prompts triggers the 2-hour burst limit rapidly. A user can find their account paused after just 4 or 5 document queries, well before reaching their nominal 20-message daily ceiling.
- Paid Tier Compute Drain: On SuperGrok or The X Subscription, heavy context evaluations accelerate weekly usage pool consumption. Running extended document research sessions early in the week can consume a substantial majority of the weekly compute allowance in a single afternoon.
- Information Truncation on Large Files: For long PDFs exceeding 100 pages, xAI documentation notes that Grok focuses on text and key visuals, advising users to reference specific pages directly. When a large document exceeds optimal context limits, the model must compress or summarize sections, increasing the risk of missing critical details in tables, financial columns, or contractual conditions.


Query Large Document Libraries Without Exhausting Grok Quotas
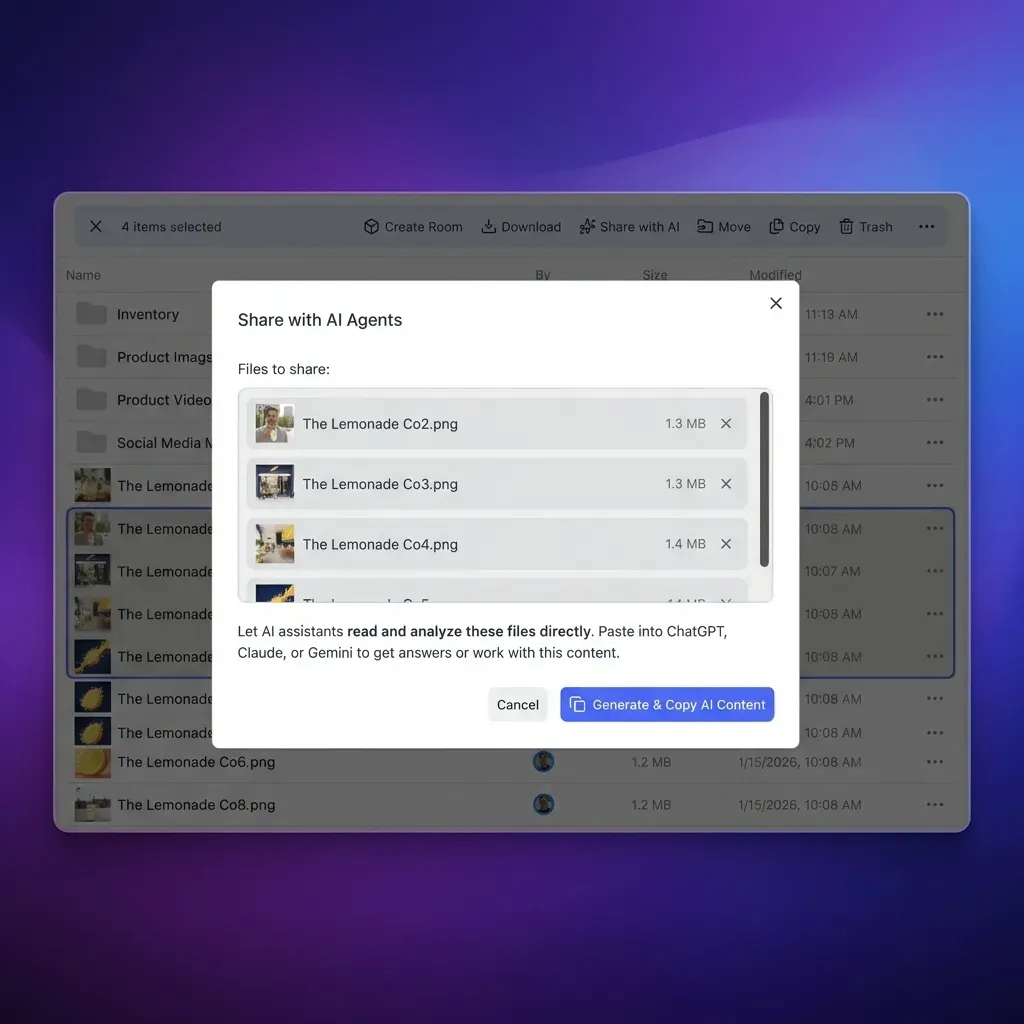
Connect your AI assistants to persistent Fastio workspaces through the remote MCP server to search indexed documents without re-uploading files. Monthly plans start with a 14-day free trial that requires a credit card.
How to Query Large Document Sets Without Exhausting Grok Limits
Relying on direct file attachments for enterprise document analysis creates friction, burns message allowances, and forces repetitive uploads. Teams managing hundreds of research papers, legal briefs, technical specifications, or customer agreements need an architectural approach that separates persistent document storage from model inference.
Comparing Document Storage and Retrieval Architectures
Organizations evaluating how to process large document collections with AI models typically choose among four distinct architectures:
Direct Chat Attachment:
- Mechanism: Uploading raw PDF, DOCX, or CSV files directly into the web chat prompt window.
- Limitations: Burns daily message quotas and weekly compute pools rapidly. Files are not persisted across chats, and context windows compress large documents.
- Best For: One-off checks on short, single-page memos.
Custom Local Scripting and Client-Side Chunking:
- Mechanism: Writing local Python scripts with libraries like pypdf or LangChain to chunk files and pass snippets to an API.
- Limitations: Requires ongoing script maintenance, local machine compute, and manual credential management. Cannot be shared easily with non-technical team members.
- Best For: Solo software engineers building local command-line prototypes.
Commodity Cloud Storage (Google Drive, Dropbox, Box, S3):
- Mechanism: Storing documents in traditional cloud folders or object storage buckets.
- Limitations: Files remain passive storage blobs. These systems lack native semantic indexing for agent search, requiring teams to construct external vector database pipelines and synchronization jobs.
- Best For: Cold data archiving and static file backups.
Intelligent Cloud Workspaces with Built-in RAG (Fastio):
- Mechanism: Documents live in shared, organization-owned workspaces where Intelligence Mode parses and indexes files automatically upon arrival.
- Advantages: Provides hybrid search (combining full-text lexical search, semantic search, and metadata value filtering). An assistant or agent connects over the Model Context Protocol (MCP) and retrieves only the specific, relevant text excerpts needed to answer a query.
- Best For: Teams and AI workflows querying large, multi-document corpora without burning model context windows or daily quotas.
How Fastio Preserves Grok and Agent Query Quotas
In an intelligent workspace, files are indexed automatically upon arrival. Instead of uploading a heavy document bundle into Grok and forcing the model to evaluate tens of thousands of tokens on every question, your workflow changes:
- Centralized Ingestion: Documents are uploaded directly to a workspace or synchronized from Google Drive, Dropbox, Box, or OneDrive. Cloud Sync connects folders one-way or two-way, on a schedule or on demand.
- Automatic Indexing: Intelligence Mode indexes document text, headings, and tables for semantic and full-text retrieval without requiring an external vector database.
- Targeted Excerpt Retrieval via MCP: When an assistant or coding agent needs information, it connects to Fastio through the remote MCP server over Streamable HTTP. The agent queries workspace search and receives only the precise two or three relevant paragraphs along with exact document citations.
- Minimal Token Footprint: The agent passes only the retrieved paragraphs into Grok or your chosen model prompt. Because the input prompt contains only 500 tokens instead of massive file contexts, the query consumes minimal compute, leaving your daily message caps and weekly compute pools intact.
Structured Extraction with Metadata Views
When teams need structured facts extracted from hundreds of files (such as policy numbers, contract dates, invoice totals, or counterparty names), querying a chat interface document by document burns hundreds of queries.
Fastio Metadata Views turn document libraries into queryable, structured databases. Users describe desired fields in natural language, and the system extracts typed values (Date, Decimal, Text, Boolean, URL, JSON) into a sortable spreadsheet without requiring OCR templates or repetitive conversational prompts.
Learn more about structured extraction capabilities on the Fastio Metadata Views product page.
Fastio Workspace Plans and Pricing
Fastio plans start with a 14-day free trial on monthly subscriptions, which requires a credit card.
The plans provide predictable capacity for team and agent workflows:
Explore all plan options on the Fastio pricing page.
Connecting Agents to Fastio via the Model Context Protocol
Fastio provides a remote MCP server over Streamable HTTP. To integrate Fastio with your development environment or coding agents (such as Grok CLI, Grok Build, Cursor, Claude Code, Cline, or VS Code), configure the coding endpoint:
- Coding Agents Endpoint:
https://mcp.fast.io/mcp/code - General AI Applications and Assistants:
https://mcp.fast.io/mcp/tools
For complete setup guides across supported clients, review the official documentation at https://mcp.fast.io/docs.
Operational Best Practices to Preserve Grok Query Allowances
Adopting disciplined operational habits extends the productivity of both free accounts and paid compute tiers. Follow these five practical rules when structuring Grok research workflows:
1. Consolidate Sequential Prompts into Multi-Part Queries
Avoid asking separate, single-line questions in a chat thread. Asking "What is the contract term?", followed by "Who is the indemnified party?", followed by "What is the liability cap?" consumes three distinct messages from your daily free quota or evaluates heavy context three times on paid tiers.
Instead, group related requirements into a single structured prompt:
Analyze the attached agreement and provide:
1. Effective date and termination conditions
2. Complete list of indemnified parties
3. Maximum aggregate liability cap under Section 12
4. Governing law jurisdiction
Format the response as a bulleted checklist with exact section references.
This single prompt extracts all required facts while burning only one query from your allocation.
2. Pre-Filter and Extract Key Passages Before Querying
Do not upload massive document bundles when your inquiry concerns only a single financial table or technical specification appendix. Extract the specific pages or relevant text sections before initiating the chat session. This practice avoids hitting Grok 100-page compression thresholds and prevents unnecessary token consumption.
3. Separate Document Indexing from Model Synthesis
Use an external intelligent workspace like Fastio to store, version, and index reference files. Let the workspace handle full-text and semantic search, and feed Grok only the retrieved text snippets. Reserving Grok for high-value reasoning, summarization, and synthesis rather than raw document ingestion dramatically extends your available queries.
4. Monitor Consumption Trends in Account Settings
If you subscribe to SuperGrok or The X Subscription, make a habit of checking the Usage section in Settings mid-week. The dashboard shows whether high-compute activities like video generation or heavy coding tasks are depleting your weekly pool prematurely. If you anticipate heavy document analysis later in the week, you can pace media generation accordingly or enable auto top-up credits.
5. Align Intensive Work with the 00:00 UTC Reset
For free-tier accounts conducting research sprints, schedule intensive work immediately following the 00:00 UTC reset hour (5:00 PM PDT or 8:00 PM EDT in North America). Starting a research batch right after the reset ensures that you have access to your full 24-hour query quota and gives you ample time before encountering rolling rate limit windows.
Sources
References used to verify factual claims in this guide.
-
Free Grok users get roughly 20 messages per day, which refresh at midnight UTC.
-
Grok limits individual document, image, code, and audio file attachments to 150 MB per file, with web sessions accepting up to approximately 100 attached files and Android up to 20 files.
Frequently Asked Questions
What is the daily limit for Grok?
On the free tier, Grok allows approximately 20 messages per day alongside rolling 2-hour rate limits that throttle rapid prompt bursts. On paid subscriptions, such as SuperGrok and The X Subscription tiers, paid plans operate on a flexible weekly compute pool that resets on an account-specific billing schedule.
When does Grok daily limit reset?
Grok daily limits on free accounts reset at 00:00 UTC (midnight Coordinated Universal Time). In North America, this corresponds to 5:00 PM PDT (8:00 PM EDT). Paid accounts reset on a rolling weekly schedule visible in account settings under Settings Usage tab.
How many messages can you send to Grok in a day?
Free users can send roughly 20 messages per day, subject to a rolling limit of approximately 10 messages per 2 hours during high-demand periods. Paid tiers have no fixed daily message cap; instead, users draw from a shared weekly compute pool where standard chat messages consume minimal compute units.
What is the difference between Grok 2-hour limit and 24-hour limit?
The 2-hour limit is a rolling rate limiter designed to prevent automated spam and server congestion, temporarily pausing prompts if too many are sent within two hours. The 24-hour limit is the overall daily ceiling (about 20 queries for free accounts) that resets at 00:00 UTC.
What happens when you reach your Grok usage limit?
When free users reach their daily limit, access pauses until 00:00 UTC. When paid users exhaust their weekly compute pool, paid features pause until the weekly reset, but users retain access to free-tier Chat and Voice or can purchase Extra Usage Credits.
What are Grok file upload and document size limits?
Grok documentation limits individual file attachments to 150 MB per file across documents, images, code, and audio, allowing web sessions to attach roughly 100 files and Android devices up to 20 files.
How does document analysis consume Grok quota?
Uploading large documents forces the model to re-evaluate the full document context on every subsequent question in that chat thread. This heavy token processing quickly triggers 2-hour burst limits on free accounts and accelerates compute pool drain on paid subscriptions.
How can you query large document sets without exhausting Grok limits?
Store documents in an external intelligent workspace like Fastio, where files are indexed automatically. Connect an AI assistant or coding agent via MCP to search for relevant excerpts, passing only small, precise passages into model prompts rather than re-evaluating whole files.
Related Resources

Query Large Document Libraries Without Exhausting Grok Quotas
Connect your AI assistants to persistent Fastio workspaces through the remote MCP server to search indexed documents without re-uploading files. Monthly plans start with a 14-day free trial that requires a credit card.