How to Sync SharePoint to MCP: Enterprise Agent Document Access
Syncing SharePoint to MCP bridges enterprise Microsoft 365 document libraries with autonomous AI agents by synchronizing files into an indexed remote workspace that exposes targeted search tools over the Model Context Protocol. Rather than writing custom Graph API scripts that trigger rate limits and require tenant-wide credentials, teams establish scheduled folder synchronization to give agents fast retrieval and strict permission boundaries.

The Enterprise Barrier Between SharePoint and AI Agents
Pointing an autonomous AI agent directly at an enterprise SharePoint document library over the Microsoft Graph API causes immediate friction: recursive folder crawls quickly trigger HTTP 429 throttling, while tenant-wide app registrations create security and credential maintenance hurdles. The solution is not to grant broader Graph permissions, but to synchronize the document library into an indexed workspace where the agent searches pre-processed files over the Model Context Protocol.
Syncing SharePoint to MCP bridges enterprise Microsoft 365 document libraries with autonomous AI agents by synchronizing files into an indexed remote workspace that exposes targeted search tools over the Model Context Protocol. Establishing a dependable sharepoint mcp sync workflow allows technical teams to query architecture records, internal policies, and technical specifications directly from AI development environments.
Enterprise organizations store their most valuable operational knowledge inside Microsoft 365. Architecture decision records, standard operating procedures, technical specifications, and legal guidelines reside across SharePoint document libraries. For human employees, SharePoint provides familiar folder trees, metadata columns, and co-authoring tools.
When engineering teams attempt to connect sharepoint files to mcp clients or desktop assistants (such as Claude, Cursor, Devin, or ChatGPT), the interaction model breaks down. Autonomous agents need targeted context. They do not operate efficiently when traversing deeply nested folder trees, downloading multi-megabyte binary documents, or handling interactive browser-based authentication challenges.
Direct scripts that query SharePoint via raw API calls force the AI model to act as a crawler. The agent must inspect directories, parse file types, download binary streams, and manage pagination. This unindexed traversal consumes massive token allowances, introduces significant latency, and frequently triggers tenant-wide API throttling.
Decoupling source storage from the agent execution layer resolves this tension. By synchronizing SharePoint document libraries into a dedicated, indexed workspace, organizations maintain their existing governance in Microsoft 365 while giving AI agents fast, structured access through standard MCP endpoints.
Related guides
- How to Connect Gemini to SharePoint via MCPConnecting Gemini to SharePoint via MCP bridges Google AI ecosystem to Microsoft enterprise storage through standard...
- Microsoft 365 MCP Server: Connecting Agents to OneDrive and SharePointA Microsoft 365 MCP server connects AI coding assistants to OneDrive and SharePoint repositories via the Model Context...
- OneDrive MCP Integration: Graph API Limitations and Remote Workspace SyncDeploying an onedrive mcp integration reveals severe operational constraints across local sync folders and direct Graph...
- How to Sync Dropbox to MCP for AI Agents and Automated PipelinesSyncing Dropbox to MCP gives AI agents fast, searchable access to team files without downloading entire directory...
- How to Sync Google Drive to MCP for AI Agent WorkspacesSyncing Google Drive to MCP allows AI agents to access Google Drive files through a standardized protocol by mirroring...
- How to Sync OneDrive to MCP for AI Coding and Workflow AgentsSyncing OneDrive to MCP allows AI agents to access Microsoft OneDrive files through a standardized protocol by...
More on this subject: MCP and Model Context Protocol (244 guides)
Why Direct Microsoft Graph API Crawls Break Agent Runtimes
Many initial experiments with SharePoint and MCP involve running a standalone Python server or writing custom scripts against the Microsoft Graph API. While this approach appears functional in small development sandboxes, it fails under enterprise production workloads due to fundamental constraints in authentication, rate limiting, and context management.
Tenant-Wide Permissions and Credential Sprawl
Connecting an agent directly to Microsoft Graph requires creating an application registration in Microsoft Entra ID. Standard tutorials frequently direct developers to request high-privilege application permissions, such as Sites.Read.All or Files.Read.All.
In enterprise environments, security teams routinely deny these requests. A tenant-wide application permission grants the client access to every site collection and document library across the entire organization. Granting such broad privileges to an AI assistant or a local developer workstation violates the principle of least privilege.
Managing client secrets or private certificates on local machines creates ongoing operational risks. When developers run headless agents, automated CI/CD jobs, or scheduled background tasks, interactive authentication prompts fail completely. If token refresh tokens expire or conditional access policies enforce interactive web re-authentication checks, the agent crashes mid-execution.
Microsoft Graph Rate Limits and HTTP 429 Throttling
SharePoint Online operates on multi-tenant cloud infrastructure protected by aggressive request rate limits. When an autonomous agent attempts to locate relevant documents, it typically performs recursive directory scans, parallel metadata queries, and rapid content fetches. This pattern quickly exhausts Microsoft Graph request quotas.
When an AI agent repeatedly queries Microsoft Graph without backoff, the service responds with HTTP status code 429 to signal rate throttling. Official Microsoft Learn guidance instructs developers: "When you implement error handling, use the HTTP error code 429 to detect throttling." Along with the 429 code, the response includes a Retry-After header specifying how many seconds the client must wait before sending another request.
For an interactive coding session in Cursor or a multi-step reasoning task in Claude, receiving a Retry-After delay breaks the workflow. The developer sits idle while the agent waits, or the client connection times out entirely.
Context Window Exhaustion from Raw Document Ingestion
Direct Graph API scripts typically download entire files and inject the raw text directly into the agent's prompt context. Ingesting full documents introduces two severe problems:
- Token Exhaustion: Ingesting complete, dense architecture manuals or multi-megabyte spreadsheets consumes tens of thousands of tokens per query, increasing inference costs and filling context limits.
- Context Dilution: When a model receives dozens of pages of surrounding boilerplate to answer a single question about an API header or database field, the relevant details get obscured. This dilution increases the frequency of hallucinations and inaccurate code generation.
Rather than forcing the AI model to handle file parsing and bulk data transfer, teams need an architecture that pre-indexes documents and exposes semantic search tools.
Architecture: Sync SharePoint to MCP via Scoped Workspaces
Decoupling enterprise document storage from agent retrieval creates a reliable, high-performance bridge between Microsoft 365 and autonomous AI tooling. When planning a production sharepoint model context protocol integration, SharePoint remains the system of record for human staff, while an indexed workspace is the retrieval layer for AI models.
Scoped Ingestion Through Cloud Sync
Instead of granting an AI agent high-level credentials to crawl SharePoint directly, the organization uses Fastio Cloud Sync to ingest specific document libraries into a dedicated Fastio workspace.
Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive folders to a workspace, one-way or two-way, on a schedule or on demand. Because SharePoint document libraries are accessible through the OneDrive connector in Fastio, teams select only the specific site libraries or project folders required for the agent's task. Cloud Sync runs on a schedule or on demand, never continuous, live, or real-time.
Syncing SharePoint libraries through the OneDrive connector eliminates interactive Entra ID re-authentication prompts in headless agent runs. The synchronization connection is authenticated once at the organization or workspace level using delegated credentials. Background agents and automated pipelines interact with Fastio using scoped API keys, completely isolated from Microsoft 365 authentication flows.
Strict Workspace Isolation
In Fastio, permissions are set per organization, workspace, and share through member roles. Every workspace member reaches the whole workspace according to their role.
By assigning an AI agent to a specific workspace containing only the synchronized SharePoint libraries, teams create an impenetrable security boundary. The agent has no programmatic path to discover or access other SharePoint sites, HR repositories, or executive communication channels. If a team needs to provide external contractors with a subset of files, they can place those files in a dedicated share without exposing the underlying SharePoint infrastructure.
Intelligent Retrieval and Benchmark Performance
Once files synchronize into the Fastio workspace, Intelligence Mode automatically indexes document contents for hybrid search, combining full-text, semantic, and metadata-based retrieval.
When an agent needs information, it does not download complete documents or scan folder paths. Instead, the agent calls Fastio MCP search tools. The search engine returns exact, relevant text excerpts with source document citations. The model context window receives dense, high-signal information while consuming minimal tokens.
In third-party testing evaluating cloud storage connectors in Claude Cowork, published in the connector benchmark report, Fastio was measured the fastest and the lowest cost of the providers tested. Note that SharePoint was not measured in that evaluation, and the benchmark tested cloud connectors rather than local stdio servers or Files-On-Demand stubs.


Connect Your SharePoint Libraries to AI Agents
Sync enterprise documents to an indexed Fastio workspace and give your agents hybrid search over the Model Context Protocol. Starts with a 14-day free trial.
Step-by-Step Implementation: Connecting SharePoint to Fastio MCP
Setting up a synchronized SharePoint-to-MCP pipeline requires five clear steps, transitioning enterprise files from Microsoft 365 into an agent-ready MCP environment. To sync sharepoint document library to mcp workspaces effectively, follow this sequence:
1. Authenticate the OneDrive Connector in Fastio
Log in to your Fastio organization dashboard and create a new workspace dedicated to your project or team documentation. Open workspace settings and select Cloud Sync. Choose OneDrive as your synchronization provider.
Sign in with your Microsoft 365 corporate account. The connector requests delegated permissions to access the files and libraries your account already has permission to read. This eliminates the need for tenant-wide Entra ID administrative consent.
2. Select the Target SharePoint Document Library
Within the Cloud Sync configuration interface, browse your available storage locations. The OneDrive connector displays both your personal OneDrive folders and the SharePoint document libraries associated with the Microsoft 365 groups and team sites you belong to.
Locate the target SharePoint document library. Select the specific folder tree containing the technical documentation, specifications, or reference manuals required by your agents.
3. Configure Synchronization Schedule and Direction
Select your preferred synchronization mode:
- One-Way Sync: Ingests updates from SharePoint into Fastio. Recommended for read-only agent contexts where agents consume reference documentation.
- Two-Way Sync: Ingests updates from SharePoint into Fastio and uploads agent-generated artifacts from Fastio back to the SharePoint library.
Set the synchronization frequency. Choose an automated schedule, such as every hour or once daily, or configure the sync to run on demand. Remember that Cloud Sync runs on a schedule or on demand, never continuous, live, or real-time.
4. Enable Intelligence Mode for Document Indexing
Navigate to workspace settings and toggle on Intelligence Mode. Once enabled, Fastio automatically processes incoming PDF, DOCX, XLSX, Markdown, and text files.
The indexing engine extracts text, computes vector embeddings, and builds a hybrid search index. This process happens entirely in the cloud workspace, requiring zero compute resources on developer machines.
5. Connect AI Agents to the Remote MCP Endpoint
Fastio provides a hosted MCP server over Streamable HTTP. To connect your AI tools, configure the client using the appropriate endpoint:
- Claude Apps (Web, Desktop, Mobile): Open Customize, then Connectors. Add a custom connector and paste
https://mcp.fast.io/mcp/tools. Select Connect and complete OAuth sign-in. In any chat, enable Fastio from the Connectors menu. - Cursor: Add the server to
.cursor/mcp.jsonin your project or global configuration:
{
  "mcpServers": {
    "fast-io": {
      "url": "https://mcp.fast.io/mcp/code"
    }
  }
}
- Claude Code: Run the CLI command:
claude mcp add --transport http fast-io https://mcp.fast.io/mcp/code
- Headless Agents and CI/CD Pipelines: For autonomous frameworks running in containers or servers, connect to
https://mcp.fast.io/mcp/toolsorhttps://mcp.fast.io/mcp/codesending your API key as an HTTP header:
POST /mcp/tools HTTP/1.1
Host: mcp.fast.io
Authorization: Bearer your-fastio-api-key
Content-Type: application/json
Accept: application/json, text/event-stream
For complete client instructions and parameter options, refer to the Fastio MCP setup guide and the agent documentation. For agent onboarding protocols, consult agent onboarding instructions.
Agent Interaction Patterns: Search, Retrieval, and Metadata Extraction
Once the SharePoint library is synchronized and indexed, AI agents interact with documents through structured tool calls over MCP rather than raw file downloads.
Executing Targeted Hybrid Search
On the https://mcp.fast.io/mcp/tools surface, agents use the consolidated storage tool with the search action to query workspace content. For coding agents on https://mcp.fast.io/mcp/code, models use the specialized search tool.
When an agent needs information regarding enterprise procedures or technical specifications, it submits a natural language search query. The platform evaluates full-text keywords and semantic embeddings simultaneously, returning exact text snippets with file identifiers and relevance scores.
A typical tool call payload from an agent appears as follows:
{
  "name": "storage",
  "arguments": {
    "action": "search",
    "query": "microservices authentication and token refresh policy",
    "workspace_id": "wks_dev_docs_892"
  }
}
The response provides the exact paragraphs addressing authentication policies, complete with source file references. The agent reads the necessary facts in hundreds of tokens, rather than downloading a fifty-page specification document.
Handling Two-Way Synchronization and Advisory File Leases
In workflows where agents generate output files (such as updated architecture diagrams, code audit summaries, or draft specifications) that must sync back to SharePoint, teams configure two-way synchronization.
To coordinate concurrent agent operations, Fastio provides advisory per-file leases via MCP actions. Agents call lock-acquire and lock-release on the storage_manage tool (or check status via lock-status on the storage tool).
An agent acquires an advisory lease before editing a document:
{
  "name": "storage_manage",
  "arguments": {
    "action": "lock-acquire",
    "file_id": "file_arch_summary_104"
  }
}
An advisory lock informs other agents and human team members that a file is actively being updated. It does not grant exclusive write rights or prevent overwrites: concurrent writes both land, and Fastio's per-file version history preserves every version. Once the agent finishes writing, it calls lock-release.
On /mcp/code, agents execute writes through the execute_manage tool, while read operations stay on execute. On /mcp/tools, all modifications (uploads, moves, deletions) use storage_manage, keeping write operations strictly separated from read actions.
Structured Extraction with Metadata Views
Many enterprise SharePoint libraries contain structured or semi-structured assets: vendor contracts, invoices, compliance attestations, and security questionnaire responses. Searching for specific data points across hundreds of documents using standard text search can be time-consuming.
Fastio provides Metadata Views to turn documents into a live, queryable database. Users and agents describe the required fields in natural language, and the system creates a typed schema supporting Text, Integer, Decimal, Boolean, URL, JSON, and Date & Time fields.
The extraction engine extracts structured values across PDFs, Word documents, spreadsheets, and scanned pages without requiring manual OCR template configuration. Agents can query these structured views over MCP to retrieve table rows, filter by date ranges, or analyze contract terms across the entire library instantly.
Governance, Activity Logging, and Operational Best Practices
Operating enterprise AI agents against corporate documentation requires strict administrative oversight and clear visibility into document changes.
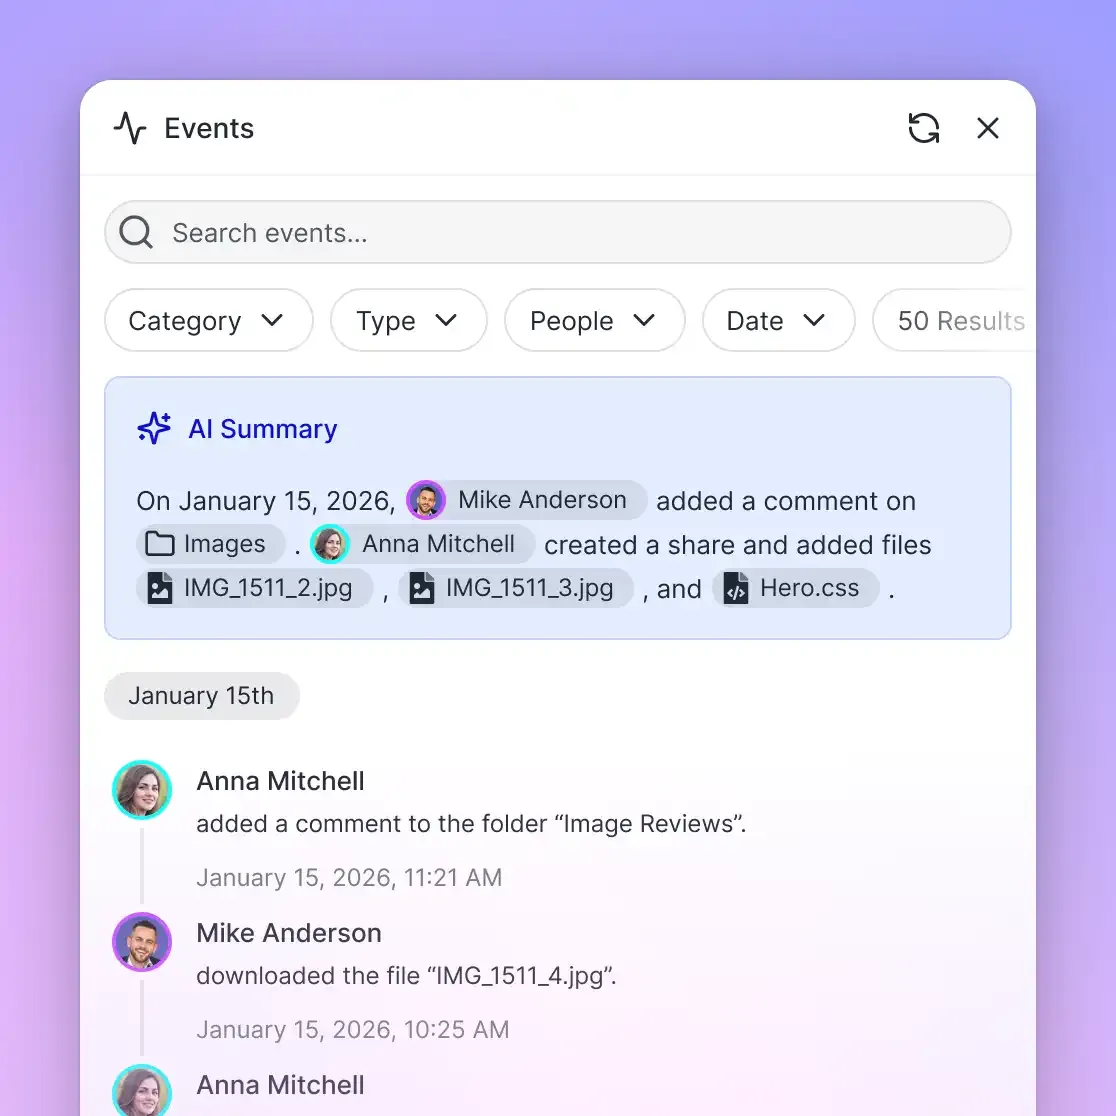
Auditing Agent Modifications with the Detailed Activity Log
Security and compliance teams must track actions taken by automated tools. Fastio maintains a detailed activity log that records what changed in an organization and who changed it, covering people and agents alike.
The detailed activity log records:
- File uploads, edits, moves, and deletions
- Membership and permission modifications
- Share creation
The activity log does not record read-only events such as views, downloads, opens, or previews. When an agent updates a technical specification or removes an obsolete asset, the change appears in the log with the agent's identity, timestamp, and target file details, maintaining a clean audit trail.
Version History and Conflict Recovery
When multiple agents or human engineers collaborate within the same workspace, race conditions can occur. Fastio maintains complete per-file version history.
Every save or update creates a distinct version snapshot. If an agent produces an incorrect draft or overwrites essential documentation, team members can review earlier revisions and restore prior versions with a single click. When paired with advisory file locks, version history allows engineering teams to deploy multi-agent pipelines with full confidence that prior work remains protected.
Scoped Client Delivery via Branded Shares
Often, teams need to distribute agent-generated reports or synchronized SharePoint documentation to outside partners, auditors, or clients who do not have Microsoft 365 accounts.
Rather than configuring guest access in Azure Entra ID, teams can generate branded Fastio shares directly from the workspace. Shares can be configured as Send (delivery), Receive (document collection), or Exchange (bidirectional collaboration). Administrators can set expiration dates and disable file downloads. Guests access files via secure links without consuming an organization user seat.
Subscription Plans and Implementation Economics
Organizations can deploy Fastio workspaces on paid monthly or annual subscriptions. Monthly plans start with a 14-day free trial, which requires a credit card.
On the Enterprise plan, extra seats are $1 a month each, up to 200 seats. Credits meter AI operations such as indexing and semantic retrieval, with credit overages billed at $10 per 100,000 credits. Storage beyond the plan is $0.015 per GB a month, and extra bandwidth is $0.04 per GB.
By establishing a scheduled sync bridge from SharePoint to an indexed Fastio workspace, enterprise teams solve the core challenges of Graph API throttling, credential management, and context dilution, giving autonomous agents fast and governed document access.
Sources
References used to verify factual claims in this guide.
-
When an AI agent repeatedly queries Microsoft Graph without backoff, the service responds with HTTP status code 429 to signal rate throttling.
Frequently Asked Questions
How do I sync SharePoint document libraries to an MCP server?
To sync a SharePoint document library to an MCP server, connect Microsoft OneDrive within Fastio Cloud Sync and select your target SharePoint library. Configure synchronization to run one-way or two-way on a schedule or on demand. Once files synchronize into the workspace, enable Intelligence Mode to index the documents. Then connect your MCP client (such as Claude, Cursor, or an autonomous agent) to the remote Fastio MCP endpoint over Streamable HTTP to query the indexed library.
Can Claude or Cursor search SharePoint via MCP?
Yes. By syncing your SharePoint library to a Fastio workspace, Claude and Cursor can search your documents using the Model Context Protocol. In Claude, add a custom connector pointing to `https://mcp.fast.io/mcp/tools` and complete OAuth sign-in. In Cursor, configure `.cursor/mcp.json` with `https://mcp.fast.io/mcp/code`. The assistants can then execute semantic and keyword searches against your indexed enterprise documents directly from the chat interface or editor.
How do you avoid Microsoft Graph API rate limits when connecting agents to SharePoint?
Direct agent scripts that crawl SharePoint over Microsoft Graph frequently encounter HTTP 429 throttling due to recursive folder queries and bulk file downloads. Syncing documents to a Fastio workspace shifts data ingestion to scheduled cloud-to-cloud background transfers. Because agents query Fastio's pre-indexed hybrid search over MCP rather than making live Graph API requests, Graph rate limits are eliminated during active agent reasoning sessions.
Does Fastio Cloud Sync update files in real time?
Fastio Cloud Sync connects Google Drive, Dropbox, Box, and OneDrive (including SharePoint document libraries via the OneDrive connector) on a schedule or on demand. It is never continuous, live, or real-time. Changes made in SharePoint reflect in your Fastio workspace based on your configured sync frequency or whenever an on-demand sync is triggered.
What permissions are required to connect SharePoint to Fastio MCP?
Connecting SharePoint through the OneDrive connector uses delegated credentials for the specific libraries your Microsoft 365 account has permission to access. This avoids granting broad tenant-wide permissions like `Sites.Read.All` in Azure Entra ID. Within Fastio, permissions are governed at the organization, workspace, and share levels through member roles.
Related Resources

Connect Your SharePoint Libraries to AI Agents
Sync enterprise documents to an indexed Fastio workspace and give your agents hybrid search over the Model Context Protocol. Starts with a 14-day free trial.