Metadata Filtering for RAG Permissions: Mechanics, Latency, and Limits
Metadata filtering for RAG permissions attaches security attributes to vector embeddings to prevent unauthorized document retrieval. While tag-based filtering restricts context, naive pre-filtering fragments HNSW graphs and post-filtering discards relevant candidates. Setting permissions at the container level avoids per-chunk filters and keeps each query inside the containers the asker belongs to.

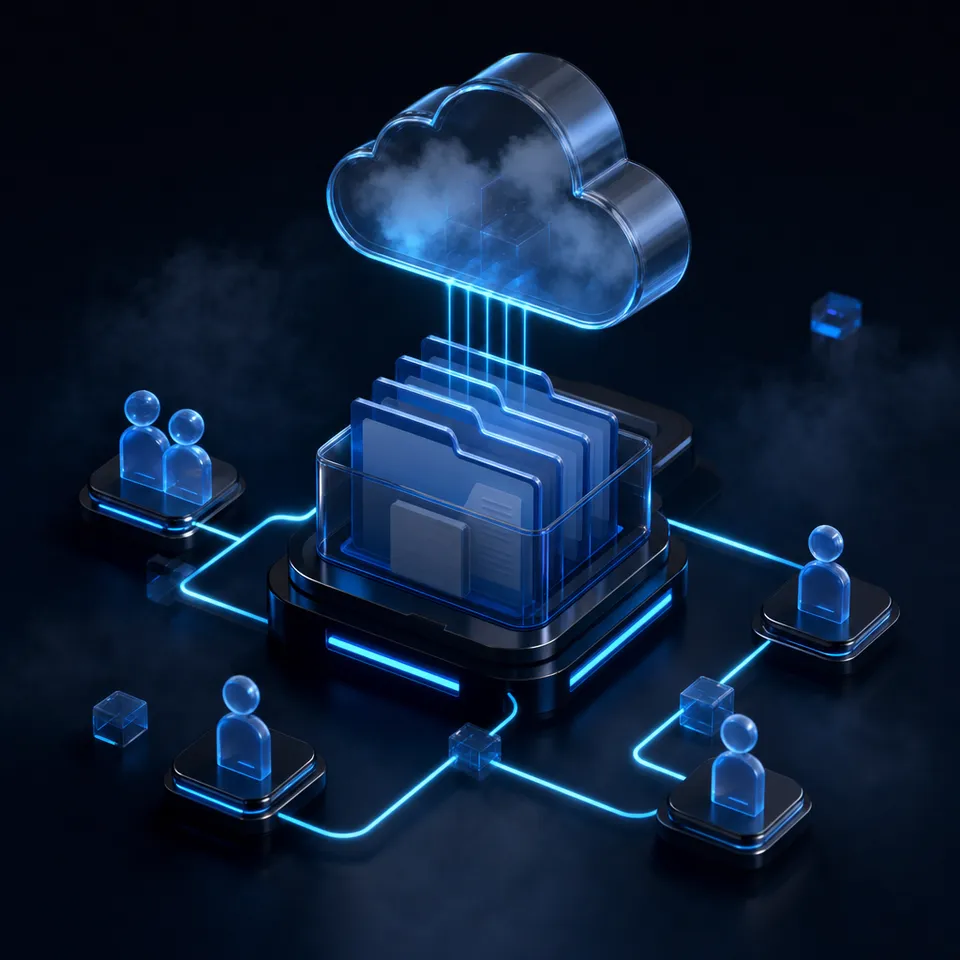
How Metadata Filtering for RAG Permissions Works in Vector Databases
In one Qdrant benchmark, a single two-keyword filter returned 39.7% recall with ACORN off while every other filter stayed above 90%, which shows how a narrow filter can quietly break approximate search. Permission tags are filters too: vector indexes organize data by geometric proximity, while access control lists divide it by administrative privilege.
Metadata filtering for RAG permissions is the technique of attaching security attributes (such as user IDs, role tags, or workspace tokens) to vector embeddings and querying them to restrict semantic retrieval to authorized text chunks. In a retrieval-augmented generation (RAG) architecture, text extracted from files, manuals, emails, and database records is divided into chunks and passed through an embedding model. To enforce enterprise security rules, engineers store discrete metadata attributes alongside each high-dimensional vector. These attributes include tenant identifiers, document identifiers, project codes, departmental classifications, and access control lists (ACLs).
Consider a typical vector chunk record stored in a modern vector database:
{
  "id": "chunk_8841a",
  "vector": [0.0142, -0.0521, 0.0893, 0.0034],
  "payload": {
    "document_id": "doc_contract_q3",
    "workspace_id": "ws_finance_corp",
    "allowed_principals": ["user_alice", "group_executives", "group_finance_lead"],
    "classification": "confidential",
    "text": "The Q3 operating margin targets require board sign-off before vendor execution..."
  }
}
When an employee or autonomous agent submits a prompt, the application converts the query into a dense embedding. Before returning results to the large language model, the system must confirm that the requester possesses authorization to view the underlying sources. Without strict boundaries, the search engine surfaces passages from confidential files to individuals who lack read access. The language model then incorporates those unauthorized passages into its synthesis, generating accurate summaries of materials the user was never permitted to inspect.
Enforcing authorization in vector search differs from standard relational database filtering. Relational databases evaluate scalar filters using B-tree indices, hash indices, or bitmap scans over structured columns. Vector search, by contrast, relies on approximate nearest neighbor (ANN) index structures such as Hierarchical Navigable Small World (HNSW) graphs or Inverted File with Product Quantization (IVF-PQ). These graph and clustering structures are built entirely around geometric distance in high-dimensional space. Introducing administrative metadata filters into this geometric traversal creates severe architectural trade-offs between retrieval speed, result accuracy, and permission synchronization.
Modern vector engines attempt to bridge this divide through two primary mechanisms: single-stage pre-filtering during graph traversal and post-filtering after candidate selection. Both strategies introduce practical constraints that become apparent as corpora expand into millions of chunks. Fastio Workspaces take a different approach: permissions are set per workspace and share rather than per file, and Fastio AI search answers only from the workspaces and shares the asker belongs to.
Related guides
- RBAC in RAG: Mapping Enterprise Roles to Context RetrievalRole-based access control for retrieval-augmented generation (RBAC RAG) restricts context retrieval to authorized...
- How to Choose the Best Vector Database for AI Agents (2026)Vector databases serve as the long-term semantic memory for AI agents, allowing them to recall context across sessions...
- Top 7 Vector Database Alternatives for AI Agents (2026)Vector databases serve as the long-term memory for AI agents, storing semantic embeddings that allow models to retrieve...
- Gemini 1.5 Pro Context Window: 2M Limits, Latency, and Workspace RAGThe Gemini 1.5 Pro context window offers 2,097,152 tokens of input capacity, processing audio, video, and text in a...
- Do SharePoint Permissions Carry Over to RAG? Access Control in Vector SearchSharePoint document library permissions do not carry over to vector embeddings during standard RAG ingestion. When...
- Multi-Tenant RAG Permissions: Isolating Context Across Teams and AgentsMulti-tenant RAG permissions are the data partitioning boundaries and access enforcement mechanisms that prevent an AI...
More on this subject: Agent Memory and Storage (338 guides)
What Causes Retrieval Latency in Pre-Filtering and Post-Filtering
Engineers implementing permission-aware retrieval typically choose between pre-filtering and post-filtering. Each approach handles access control tags differently during the vector search lifecycle, and each introduces distinct performance penalties.
Pre-Filtering and Graph Disconnection
In pre-filtering, the vector database applies the metadata filter before or during approximate nearest neighbor search. In naive implementations, the engine identifies all vectors matching the user's permission tags and constructs an ad-hoc search space. In modern single-stage filterable HNSW implementations, the engine traverses the global graph but evaluates the metadata payload at each visited node. If a node does not match the requester's allowed identifiers, the algorithm ignores it and continues searching for neighboring nodes.
This approach protects security boundaries because unauthorized chunks never enter candidate consideration. However, single-stage pre-filtering frequently triggers HNSW graph fragmentation. HNSW graphs rely on long-range highway edges to navigate quickly across vector space before zooming in on localized clusters. When a restrictive metadata filter hides a substantial portion of the dataset, it removes the bridge nodes that connect different regions of the graph.
The search beam encounters dead ends where all outward edges point to filtered nodes. The algorithm terminates traversal prematurely, unable to hop across the graph to find relevant nodes that match the filter criteria. Restrictive metadata pre-filtering can cause nearest-neighbor recall to drop by over half due to this graph isolation. Specialized algorithms such as ACORN attempt to mitigate this by exploring secondary neighborhood connections, but doing so increases the number of distance calculations and lengthens query execution time. When selectivity is high and only a small fraction of the corpus matches the user filter, pre-filtering engines often abandon graph traversal entirely and fall back to brute-force linear scans.
Post-Filtering and Candidate Exhaustion
Post-filtering takes the opposite path. The vector database performs standard approximate nearest neighbor search across the entire index to retrieve a broad candidate pool. The application layer or database engine then iterates through those candidates, inspecting their metadata attributes and discarding any record the user is not permitted to see.
Post-filtering preserves HNSW graph integrity because traversal operates over the complete, unpartitioned index without dead ends. However, post-filtering introduces a fatal reliability issue known as candidate exhaustion. If the semantic query strongly matches documents that belong to a restricted classification (such as an executive compensation review or an unannounced acquisition), the top returned results will consist almost entirely of unauthorized records.
After the security filter discards those unauthorized candidates, the remaining pool may contain only one or two valid chunks, or none at all. The retrieval step starves the language model of necessary context, causing the agent to hallucinate or report that no relevant information exists.
To prevent candidate exhaustion, developers often increase the initial retrieval window, fetching hundreds of candidates in hopes that enough permitted records survive the filter. This practice multiplies memory consumption, increases network payload size, and introduces latency during re-ranking stages. Furthermore, post-filtering carries a subtle security exposure: if an application component fails during the post-retrieval filtering step, raw vector matches containing sensitive text fragments can leak into logs, re-rankers, or context windows.
Enforce RAG Permissions with Workspace Retrieval Boundaries
Fastio provides intelligent workspaces with built-in semantic search and automatic indexing for AI agents and teams. Connect your agents through the remote MCP server and keep permission boundaries at the workspace level. Start a 14-day free trial on any monthly plan.
Why Chunk-Level Access Control Creates an Operational Bottleneck
Many tutorials propose a simple design: attach user and group access lists directly to the metadata payload of every text chunk. In a static prototype with a few hundred files, this strategy appears straightforward. In production systems handling dynamic corporate data, chunk-level access control creates severe operational overhead.
Permission Synchronization Drift
Corporate permissions are dynamic. Employees join projects, change departments, take leaves of absence, and depart organizations. Shared folder access lists and team memberships update continuously in directory services and identity providers.
When access control lists sit embedded inside millions of chunk metadata payloads, every permission change requires a massive synchronization cycle. If an administrative group loses access to a project folder containing two hundred lengthy documents, the ingestion system must locate every chunk generated from those documents (often tens of thousands of individual records) and update their payload metadata.
Because vector databases are distributed systems, updating payloads across multiple shards takes time. During this propagation window, the index suffers from permission synchronization drift: revoked users can still retrieve sensitive passages, while newly authorized users encounter search failures because their user identifiers have not yet propagated to historical chunk payloads.
Write Lock Contention and Index Degradation
Vector databases are engineered for batch ingestion and high-concurrency read queries. Their underlying index formats (such as compressed inverted lists, product quantization codebooks, and graph link layers) are computationally expensive to mutate in real time.
When background workers execute bulk payload updates to reflect group membership changes, they trigger write lock contention on active index segments. Updating metadata fields invalidates internal caching layers and forces the database engine to update secondary payload indices.
Under heavy write load, read queries can slow down, and agent workflows that wait on retrieval may time out. In extreme cases, frequent metadata mutations fragment the vector storage files, necessitating periodic index rebuilds and compaction cycles that consume significant compute capacity.
Multi-Tenant Index Bloat
Storing comprehensive access control lists on individual chunks also inflates index size. When a document is accessible to hundreds of distinct users, dozens of distribution groups, and multiple project teams, the JSON payload of each chunk can exceed the byte size of the raw text and vector embedding combined.
Because payload indices must remain in memory or high-speed storage to support fast query filtering, this bloat directly increases operational infrastructure costs. Engineering teams find themselves provisioning higher-tier database clusters not to hold more knowledge, but to store redundant permission strings replicated across millions of segmented chunks.
How to Compare Permission Models: Pre-Filtering, Post-Filtering, and Container Partitioning
To balance retrieval speed, search recall, and operational stability, engineering teams evaluate three primary architectural patterns for permission-aware retrieval.
The Container Partitioning Alternative
As a general design pattern, container partitioning replaces chunk-level metadata tagging with structural isolation. Instead of placing documents from all teams, clients, and classifications into a single shared vector index and relying on runtime boolean filters, data is partitioned into discrete collections, indexes, or workspaces.
In a containerized retrieval model, an agent or user queries only the specific containers where they hold active membership, so the search runs over documents they are already allowed to see. How a given product stores its index behind that boundary varies.
This structural boundary solves the fundamental trade-offs of metadata filtering:
- Full Graph Continuity: Because every vector in the target container is accessible to the requester, the search engine applies zero metadata filters during traversal. The HNSW graph remains complete and unbroken, preserving search recall without dead ends.
- Consistent latency: Without per-query permission filters, search latency does not grow with the number of access rules.
- Simpler Permission Updates: Granting or revoking access to a corpus means updating a single membership record at the container level. No background jobs need to rewrite millions of chunk payloads.
- Contained Mistakes: Because each query runs only against the containers the requester belongs to, a flawed query parameter does not widen the search to containers outside that membership.
Steps to Implement Permission-Aware Retrieval with Workspace Boundaries
Building production retrieval systems for AI agents requires separating storage, indexing, and access boundaries into clear administrative units. Rather than building fragile custom synchronization pipelines that push directory group lists into vector payloads, teams use container-based workspace platforms.
Fastio applies the container idea at the permission level: permissions are set per organization, workspace and share by member role, and search and Intelligence answer only from the workspaces and shares the asker belongs to. Workspaces do not support folder-level or file-level access control lists; every member of a workspace accesses all files within that workspace according to their assigned role (owner, admin, member, guest, or view).
When material must be restricted to specific individuals or automated agents, that material lives in its own dedicated workspace or share, with the workspace's join setting restricted, since by default any organization member can join. This approach establishes a clean retrieval boundary: Fastio Search and Intelligence Mode (which handles automated document indexing, semantic search, and summary generation with file citations) answer strictly from the workspaces and shares the asking person or agent belongs to. An agent querying a share retrieves context exclusively from that share's files.
Connecting Autonomous Agents via MCP
AI agents connect to Fastio workspaces through the remote Model Context Protocol (MCP) server or the REST API. The MCP server operates over Streamable HTTP at standard client endpoints:
- For Claude applications and general MCP runtimes:
https://mcp.fast.io/mcp/tools - For coding agents (such as Claude Code, Cursor, or Cline):
https://mcp.fast.io/mcp/code - For custom ChatGPT and Codex configurations:
https://mcp.fast.io/mcp/operations
Interactive clients authenticate using OAuth in the browser, where the person signing in picks Read Only or Read & Write permissions and selects the specific organizations and workspaces the connection reaches. Headless agents use API keys that act with their creator's permissions, narrowed by the key's scopes.
Because the boundary is enforced at the workspace level, an agent executing semantic search through the MCP search tool cannot retrieve passages outside its permitted workspace scope. Because access follows workspace membership, there are no per-chunk permission tags to keep in sync when people join or leave.
For example, a coding agent on /mcp/code calls the search tool:
{
  "method": "tools/call",
  "params": {
    "name": "search",
    "arguments": {
      "query": "operating margin forecasts and budget allocations",
      "workspace_id": "<workspace ID>"
    }
  }
}
Ingestion Boundaries and External Sync
Enterprise knowledge often originates in external cloud repositories. Fastio Cloud Sync connects folders from Google Drive, Dropbox, Box, and OneDrive into designated workspaces. Sync runs one-way or two-way, on a schedule or on demand.
Crucially, source drive permissions do not carry over during synchronization. Synced files immediately inherit the permissions of the destination Fastio workspace. This design prevents security confusion: what an agent or user can retrieve is determined entirely by their Fastio workspace membership, rather than by complex, opaque permission trees defined in upstream storage systems.
For teams requiring structured extraction alongside semantic retrieval, Fastio provides Metadata Views. Metadata Views turn unstructured documents into typed tables (extracting dates, counterparties, contract totals, and custom attributes) without manual OCR rules. Agents can inspect structured metadata records and perform semantic searches within the same workspace boundary.
To audit administrative changes, Fastio maintains a detailed activity log. The activity log records modifications, including file uploads, edits, moves, deletions, membership adjustments, role updates, and share creations. Read-only interactions such as file views and downloads are not logged, keeping the record focused on governance and structural changes.
By aligning retrieval boundaries with workspace membership, teams avoid maintaining per-chunk permission tags and give agents permission-aware context. Teams exploring agent integration can review the Fastio MCP documentation or inspect Fastio storage for agents to evaluate workspace-level retrieval architectures.
Sources
References used to verify factual claims in this guide.
-
In one Qdrant benchmark, a single two-keyword filter returned 39.7% recall with ACORN off while every other filter stayed above 90%.
Frequently Asked Questions
How does metadata filtering work in vector search?
Metadata filtering in vector search pairs high-dimensional embeddings with structured key-value attributes (such as user IDs, document tags, or department codes). During search, the vector database evaluates these metadata fields alongside vector similarity scores, either filtering candidates before traversing the index graph (pre-filtering) or pruning unauthorized results after vector retrieval (post-filtering).
What is the difference between pre-filtering and post-filtering for RAG permissions?
Pre-filtering evaluates access control metadata before or during index graph traversal, ensuring that unauthorized chunks never enter the candidate set but risking HNSW graph fragmentation and recall degradation. Post-filtering performs standard nearest-neighbor search first and discards unauthorized results afterward, preserving graph structure but risking candidate exhaustion where all returned chunks are filtered out.
Why does metadata filtering slow down vector search?
Metadata filtering introduces computational overhead by requiring the search engine to evaluate boolean conditions on visited nodes. In pre-filtering, restrictive filters isolate regions of HNSW graphs, forcing algorithms to explore extended neighborhoods or fall back to brute-force linear scans. In post-filtering, systems must over-fetch large candidate pools to ensure permitted documents remain after pruning.
How do you update permissions in a vector database without re-indexing?
Updating chunk-level permissions without re-indexing typically requires vector databases to support in-place payload mutations on existing point IDs. However, frequent payload updates create write lock contention and secondary index churn. The most efficient way to manage permissions without re-indexing is container partitioning, where access is controlled at the workspace or collection boundary rather than on individual chunks.
How does container partitioning simplify permission-aware RAG?
Container partitioning divides document collections into discrete workspaces or indexes matching organizational access boundaries. Because all documents in a container share identical access rules, the vector search engine runs without runtime metadata filters, preserving full graph recall, keeping latency predictable, and letting permission updates happen once at the container boundary.
Related Resources
Enforce RAG Permissions with Workspace Retrieval Boundaries
Fastio provides intelligent workspaces with built-in semantic search and automatic indexing for AI agents and teams. Connect your agents through the remote MCP server and keep permission boundaries at the workspace level. Start a 14-day free trial on any monthly plan.